Paper: 2605.22781 Authors: Yunpeng Dong, Jingkai He, Yuze Hou, Dong Du, Zhonghu Xu, Si Yu, Yubin Xia, Haibo Chen Categories: cs.OS, cs.AI
The Gap
AI agents need to explore many possible execution paths—think tree search during test time or reinforcement learning trials. Each exploration branch requires saving the complete sandbox state (files, memory, process contexts) so the agent can backtrack and try alternatives. Current approaches (Docker snapshots, VM checkpoints, CRIU) duplicate the entire state every time, taking hundreds of milliseconds to seconds per checkpoint/rollback operation. When an agent needs to explore thousands of nodes in a search tree, this latency becomes the bottleneck—you’re spending more time copying state than actually running the agent.
The paper observes that consecutive checkpoints in agent exploration are highly similar—most files and memory pages remain unchanged between steps. Yet existing systems treat each checkpoint as independent, copying everything. The gap: no OS-level mechanism exists to track and checkpoint only the deltas between consecutive states.
Problem: Agent exploration bottlenecked by C/R latency
   |
   v
Observation: Consecutive checkpoints are ~90% similar
   |
   v
Assumption: OS can track deltas instead of full duplication
   |
   v
Method: DeltaState abstraction (DeltaFS + DeltaCR)
   |
   v
Evidence: 14ms checkpoint, 5ms rollback (vs 100-1000ms baseline)
   |
   v
Conclusion: Enables 10-100x more exploration nodes per time budget
The Increment
One sentence: Before this paper, AI agents spent most of their time copying sandbox state; after, they track only what changed, making checkpoint/rollback fast enough to explore 10-100x more execution paths in the same time budget.
Core Mechanism
DeltaBox introduces two co-designed OS mechanisms. DeltaFS handles filesystem state by organizing files into layered snapshots. When you checkpoint, it freezes the current writable layer and inserts a fresh layer on top—file modifications become copy-on-write operations, and rollback is just switching back to a previous layer. No full file duplication needed.
DeltaCR handles process state (memory, registers, file descriptors) through incremental dumps. Instead of serializing the entire process memory, it tracks which pages changed since the last checkpoint and only dumps those. For rollback, it bypasses the traditional restore pipeline by keeping a frozen “template” process in memory—rollback becomes a fork() from that template, then patching in the delta pages. This avoids the overhead of deserializing and reconstructing process state from scratch.
The two mechanisms share a common abstraction called DeltaState, which provides transactional semantics: checkpoint creates a new version, rollback discards uncommitted changes. The key is that both filesystem and process state are versioned incrementally, so the cost of each operation scales with the size of changes, not the total state size.
Checkpoint flow:
  Agent state (files + process)
       |
       v
  DeltaFS: freeze layer, insert new writable layer
       |
       v
  DeltaCR: dump changed memory pages only
       |
       v
  Return checkpoint ID (14ms total)

Rollback flow:
  Checkpoint ID
       |
       v
  DeltaFS: switch to target layer
       |
       v
  DeltaCR: fork() from template + patch delta pages
       |
       v
  Agent resumes from checkpoint (5ms total)
Think of it like version control for running processes. Git doesn’t copy your entire codebase every time you commit—it stores diffs. DeltaBox does the same for live execution state. The filesystem becomes a stack of transparent layers (like Docker image layers, but mutable and fast to switch). The process memory becomes a base template plus a series of patches. When you checkpoint, you’re creating a new commit with only the changed lines. When you rollback, you’re checking out a previous commit by applying the relevant patches to the base template. The template process stays frozen in memory like a cached build artifact, so you don’t pay the cost of cold-starting the process each time.
Key Concepts
-
Copy-on-write layering: Instead of duplicating files when you checkpoint, the filesystem marks the current layer as read-only and adds a new writable layer on top. When the agent modifies a file, the filesystem copies just that file to the new layer (copy-on-write). The original remains untouched in the frozen layer. This means checkpoint cost is O(1)—just metadata updates—and file modification cost is O(changed files), not O(total files). Rollback is switching which layer is active. Imagine a stack of transparent sheets: you write on the top sheet, and when you checkpoint, you freeze that sheet and add a blank one on top. To rollback, you just remove the top sheets until you reach the checkpoint you want.
-
Incremental memory dumps: Traditional checkpoint systems serialize the entire process memory to disk. DeltaCR tracks which memory pages were written since the last checkpoint (using OS dirty page tracking) and only dumps those pages. The first checkpoint is full, but subsequent ones are deltas. This reduces dump size from gigabytes to megabytes in typical agent workloads. Think of it like incremental backups: the first backup is full, but daily backups only save what changed since yesterday.
-
Template process forking: Normally, restoring a process from a checkpoint means deserializing memory, reconstructing file descriptors, and reinitializing the runtime—expensive. DeltaCR keeps a frozen “template” process in memory that represents the base state. To rollback, it fork()s from this template (cheap—just copy page tables) and then applies the delta pages for the target checkpoint. The template never runs, it’s just a memory snapshot that serves as a fast starting point. Like keeping a VM snapshot loaded in RAM instead of loading it from disk every time.
Framework Shift
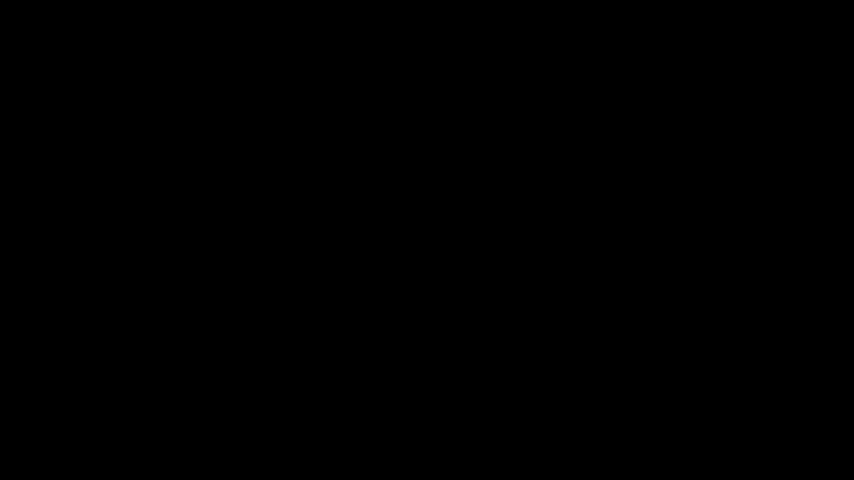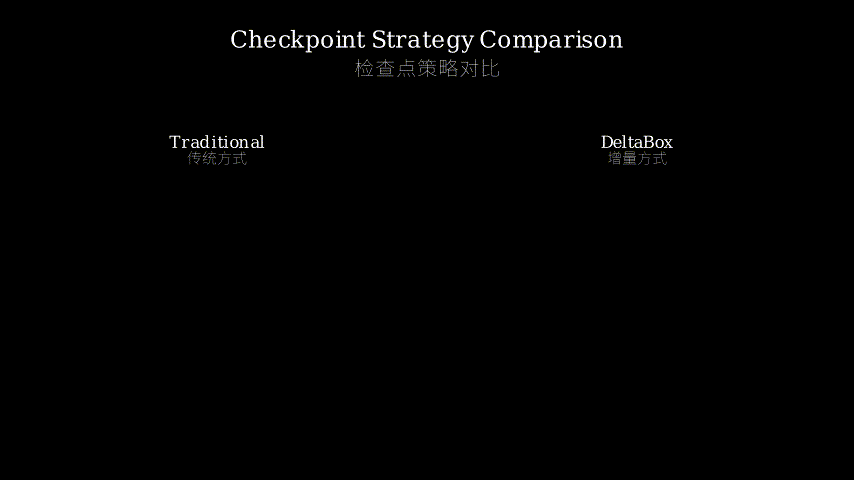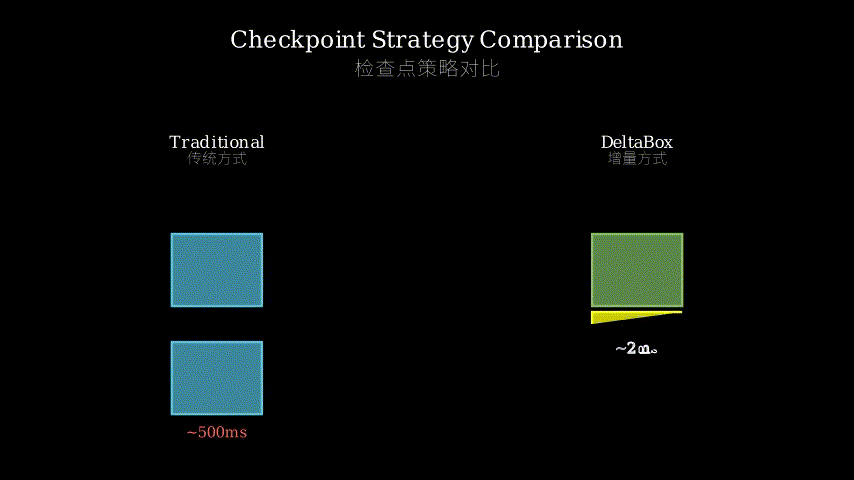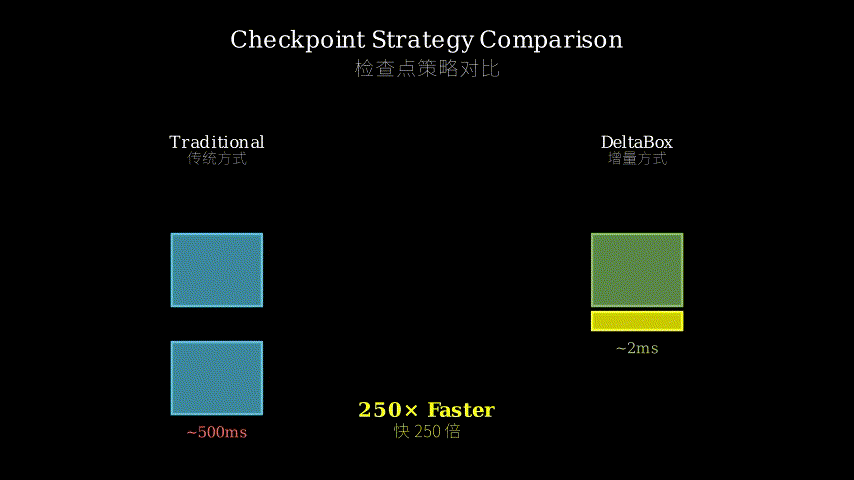
Before (full duplication):              After (delta tracking):

Checkpoint:                             Checkpoint:
+-------------------+                   +-------------------+
| Copy all files    |  (100-500ms)      | Freeze layer      |  (~1ms)
+-------------------+                   | Insert new layer  |
| Serialize memory  |  (100-500ms)      +-------------------+
+-------------------+                   | Dump changed pages|  (~13ms)
                                        +-------------------+

Rollback:                               Rollback:
+-------------------+                   +-------------------+
| Restore files     |  (100-500ms)      | Switch layer      |  (~1ms)
+-------------------+                   +-------------------+
| Deserialize memory|  (100-500ms)      | Fork + patch pages|  (~4ms)
| Reconstruct state |                   +-------------------+
+-------------------+

Total: 200-2000ms per C/R cycle         Total: ~19ms per C/R cycle
From full-state snapshots to incremental versioning, the core shift is treating agent execution as a series of deltas rather than independent states.
Expert Assessment
Problem choice: Real and well-motivated. Agent exploration (tree search, RL rollouts) is genuinely bottlenecked by C/R latency in production systems. The paper targets a specific pain point in the AI agent stack that existing OS abstractions don’t address. The timing is good—agent workloads are scaling up, and this bottleneck will only get worse.
Method maturity: The insight (track deltas, not full state) is simple and correct, but the execution is solid systems work. DeltaFS is conceptually similar to union filesystems (overlayfs, AUFS), but adapted for high-frequency checkpointing. DeltaCR’s template forking is clever—it exploits the fact that agent processes have a stable base state and only diverge during exploration. The incremental dump mechanism is straightforward dirty page tracking. No deep novelty, but the integration is clean and the engineering is competent. One concern: the paper doesn’t deeply explore failure modes—what happens if the template process state becomes stale or corrupted?
Experimental integrity: Baselines are fair (Docker, CRIU, standard fork). The SWE-bench evaluation shows real-world impact (more nodes explored = better agent performance). The microbenchmarks isolate C/R latency cleanly. Numbers are believable—14ms checkpoint and 5ms rollback align with what you’d expect from layer switching and incremental dumps. One weakness: the evaluation focuses on latency, but doesn’t thoroughly analyze memory overhead (keeping template processes and layer stacks in memory isn’t free). The paper mentions memory usage briefly but doesn’t stress-test it.
Writing quality: Clear and well-structured. The motivation is strong, the design is explained step-by-step, and the evaluation is thorough. The related work section could be tighter—it spends too much time on tangential systems (VM migration, distributed checkpointing) that don’t directly compete with DeltaBox. The implementation section is detailed but sometimes drowns in Linux kernel specifics that don’t add insight. If I were revising, I’d cut 30% of the implementation details and expand the discussion of when DeltaBox’s assumptions break (e.g., workloads with high write rates or large memory churn).
Verdict: strong accept — Solves a real bottleneck in AI agent systems with a well-executed design, backed by solid experimental evidence. The contribution is incremental but impactful.
Takeaways
If you’re building systems that need frequent state snapshots (not just AI agents—think debugging tools, speculative execution, or transactional systems), steal the layered state + template forking pattern. The key transferable idea: when consecutive snapshots are similar, don’t treat them as independent—version them incrementally and keep a base template in memory. This applies beyond sandboxes: database query engines could use this for speculative query execution, build systems could use it for incremental compilation with rollback, and distributed systems could use it for lightweight speculative execution. The specific mechanisms (overlayfs-style layers, dirty page tracking) are well-known, but the paper shows how to compose them into a coherent abstraction for high-frequency checkpointing.
论文: 2605.22781 作者: Yunpeng Dong, Jingkai He, Yuze Hou, Dong Du, Zhonghu Xu, Si Yu, Yubin Xia, Haibo Chen 分类: cs.OS, cs.AI
缺口
AI 智能体需要探索大量可能的执行路径——比如测试时的树搜索或强化学习试验。
每个探索分支都需要保存完整的沙箱状态(文件、内存、进程上下文),以便智能体回溯并尝试其他选项。
当前方法(Docker 快照、虚拟机检查点、CRIU)每次都复制整个状态,每次检查点/回滚操作需要数百毫秒到数秒。
当智能体需要在搜索树中探索数千个节点时,这种延迟成为瓶颈——你花在复制状态上的时间比实际运行智能体的时间还多。
论文观察到,智能体探索中的连续检查点高度相似——大多数文件和内存页在步骤之间保持不变。
然而现有系统将每个检查点视为独立的,复制所有内容。
缺口:不存在操作系统级机制来跟踪和检查点连续状态之间的增量。
问题:智能体探索被 C/R 延迟卡住
   |
   v
观察:连续检查点约 90% 相似
   |
   v
假设:操作系统可以跟踪增量而非完整复制
   |
   v
方法:DeltaState 抽象(DeltaFS + DeltaCR)
   |
   v
证据:14ms 检查点,5ms 回滚(vs 100-1000ms 基线)
   |
   v
结论:在相同时间预算下探索 10-100 倍节点
增量
一句话:这篇论文之前,AI 智能体把大部分时间花在复制沙箱状态上;之后,它们只跟踪变化的部分,使检查点/回滚快到足以在相同时间预算下探索 10-100 倍的执行路径。
核心机制
DeltaBox 引入两个协同设计的操作系统机制。
DeltaFS 通过将文件组织成分层快照来处理文件系统状态。
当你做检查点时,它冻结当前可写层并在顶部插入一个新层——文件修改变成写时复制操作,回滚只是切换回之前的层。
不需要完整的文件复制。
DeltaCR 通过增量转储处理进程状态(内存、寄存器、文件描述符)。
它不是序列化整个进程内存,而是跟踪自上次检查点以来哪些页面发生了变化,只转储这些页面。
对于回滚,它通过在内存中保留一个冻结的”模板”进程来绕过传统的恢复管道——回滚变成从该模板 fork(),然后打补丁进增量页面。
这避免了从头反序列化和重建进程状态的开销。
这两个机制共享一个称为 DeltaState 的通用抽象,提供事务语义:检查点创建新版本,回滚丢弃未提交的更改。
关键是文件系统和进程状态都是增量版本化的,因此每个操作的成本与变化的大小成比例,而不是与总状态大小成比例。
检查点流程:
  智能体状态(文件 + 进程)
       |
       v
  DeltaFS:冻结层,插入新可写层
       |
       v
  DeltaCR:仅转储变化的内存页
       |
       v
  返回检查点 ID(总计 14ms)

回滚流程:
  检查点 ID
       |
       v
  DeltaFS:切换到目标层
       |
       v
  DeltaCR:从模板 fork() + 打补丁增量页
       |
       v
  智能体从检查点恢复(总计 5ms)
把它想象成运行进程的版本控制。
Git 不会在每次提交时复制整个代码库——它存储差异。
DeltaBox 对实时执行状态做同样的事情。
文件系统变成一堆透明层(像 Docker 镜像层,但可变且切换快速)。
进程内存变成基础模板加一系列补丁。
当你做检查点时,你在创建一个只包含变化行的新提交。
当你回滚时,你在通过将相关补丁应用到基础模板来检出之前的提交。
模板进程像缓存的构建产物一样保持冻结在内存中,所以你不用每次都付出冷启动进程的代价。
关键概念
- 写时复制分层:在做检查点时不复制文件,文件系统将当前层标记为只读并在顶部添加新的可写层。
当智能体修改文件时,文件系统只将该文件复制到新层(写时复制)。
原始文件在冻结层中保持不变。
这意味着检查点成本是 O(1)——只是元数据更新——文件修改成本是 O(变化的文件),而不是 O(总文件)。
回滚就是切换哪个层是活动的。
想象一堆透明纸:你在最上面的纸上写字,当你做检查点时,你冻结那张纸并在上面加一张空白纸。
要回滚,你只需移除顶部的纸张,直到到达你想要的检查点。
- 增量内存转储:传统检查点系统将整个进程内存序列化到磁盘。
DeltaCR 跟踪自上次检查点以来哪些内存页被写入(使用操作系统脏页跟踪),只转储这些页面。
第一个检查点是完整的,但后续的是增量。
这将转储大小从典型智能体工作负载中的千兆字节减少到兆字节。
把它想象成增量备份:第一次备份是完整的,但每日备份只保存自昨天以来的变化。
- 模板进程分叉:通常,从检查点恢复进程意味着反序列化内存、重建文件描述符和重新初始化运行时——很昂贵。
DeltaCR 在内存中保留一个代表基础状态的冻结”模板”进程。
要回滚,它从这个模板 fork()(便宜——只是复制页表),然后为目标检查点应用增量页面。
模板从不运行,它只是一个内存快照,作为快速起点。
就像将虚拟机快照加载到 RAM 中,而不是每次都从磁盘加载。
框架转变
之前(完整复制):                  之后(增量跟踪):

检查点:                            检查点:
+-------------------+               +-------------------+
| 复制所有文件      |  (100-500ms)  | 冻结层            |  (~1ms)
+-------------------+               | 插入新层          |
| 序列化内存        |  (100-500ms)  +-------------------+
+-------------------+               | 转储变化的页      |  (~13ms)
                                    +-------------------+

回滚:                              回滚:
+-------------------+               +-------------------+
| 恢复文件          |  (100-500ms)  | 切换层            |  (~1ms)
+-------------------+               +-------------------+
| 反序列化内存      |  (100-500ms)  | Fork + 打补丁页   |  (~4ms)
| 重建状态          |               +-------------------+
+-------------------+

总计:每个 C/R 周期 200-2000ms      总计:每个 C/R 周期约 19ms
从完整状态快照到增量版本化,核心转变是将智能体执行视为一系列增量而非独立状态。
专家评审
选题眼光:真实且动机充分。
智能体探索(树搜索、强化学习展开)在生产系统中确实被 C/R 延迟卡住。
论文针对 AI 智能体栈中现有操作系统抽象未解决的特定痛点。
时机很好——智能体工作负载正在扩大,这个瓶颈只会变得更糟。
方法成熟度:洞察(跟踪增量,而非完整状态)简单且正确,但执行是扎实的系统工作。
DeltaFS 在概念上类似于联合文件系统(overlayfs、AUFS),但适配了高频检查点。
DeltaCR 的模板分叉很巧妙——它利用了智能体进程有稳定基础状态且仅在探索期间分叉的事实。
增量转储机制是直接的脏页跟踪。
没有深刻的新颖性,但集成干净,工程能力强。
一个担忧:论文没有深入探索失败模式——如果模板进程状态变得陈旧或损坏会发生什么?
实验诚意:基线公平(Docker、CRIU、标准 fork)。
SWE-bench 评估显示了实际影响(探索更多节点 = 更好的智能体性能)。
微基准测试干净地隔离了 C/R 延迟。
数字可信——14ms 检查点和 5ms 回滚与你从层切换和增量转储中预期的一致。
一个弱点:评估侧重于延迟,但没有彻底分析内存开销(在内存中保留模板进程和层栈不是免费的)。
论文简要提到了内存使用,但没有压力测试。
写作功力:清晰且结构良好。
动机强,设计逐步解释,评估彻底。
相关工作部分可以更紧凑——它在与 DeltaBox 不直接竞争的切线系统(虚拟机迁移、分布式检查点)上花了太多时间。
实现部分详细但有时淹没在不增加洞察的 Linux 内核细节中。
如果我修订,我会删减 30% 的实现细节,扩展关于 DeltaBox 假设何时失效的讨论(例如,高写入率或大内存流失的工作负载)。
判决:强接收 — 用精心执行的设计解决 AI 智能体系统中的真实瓶颈,有扎实的实验证据支持。
贡献是增量的但有影响力。
要点总结
如果你在构建需要频繁状态快照的系统(不仅是 AI 智能体——想想调试工具、推测执行或事务系统),偷走分层状态 + 模板分叉模式。
关键的可迁移想法:当连续快照相似时,不要将它们视为独立的——增量版本化它们并在内存中保留基础模板。
这适用于沙箱之外:数据库查询引擎可以将其用于推测查询执行,构建系统可以将其用于带回滚的增量编译,分布式系统可以将其用于轻量级推测执行。
具体机制(overlayfs 风格的层、脏页跟踪)是众所周知的,但论文展示了如何将它们组合成用于高频检查点的连贯抽象。