Paper: 2606.17029 Authors: Minghang Zhu, Chuyang Wei, Junhao Xu, Yilin Cheng, Zhumin Chen, Jiyan He Categories: cs.CL
The Gap
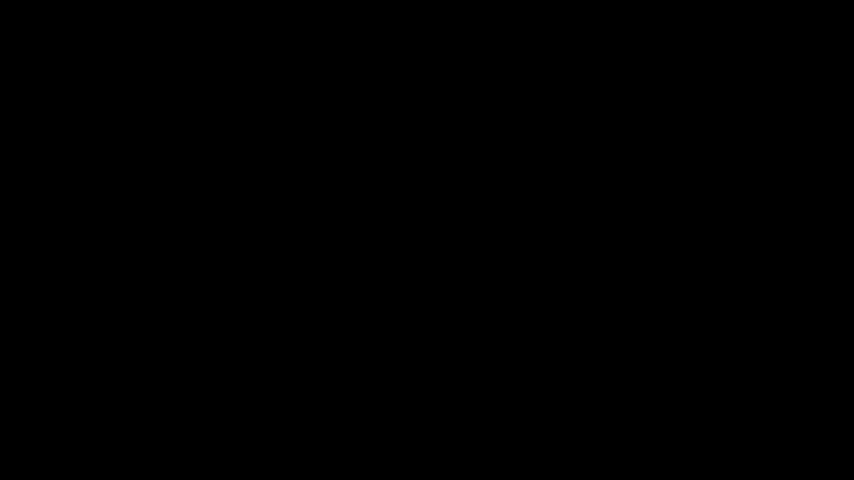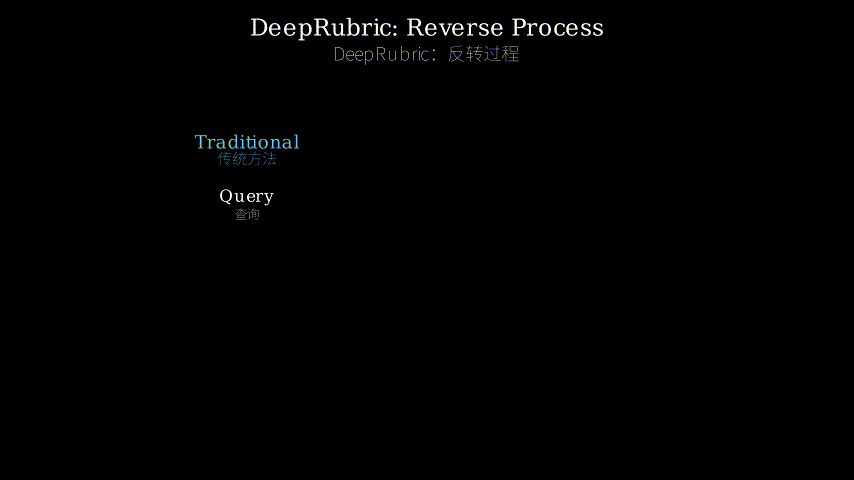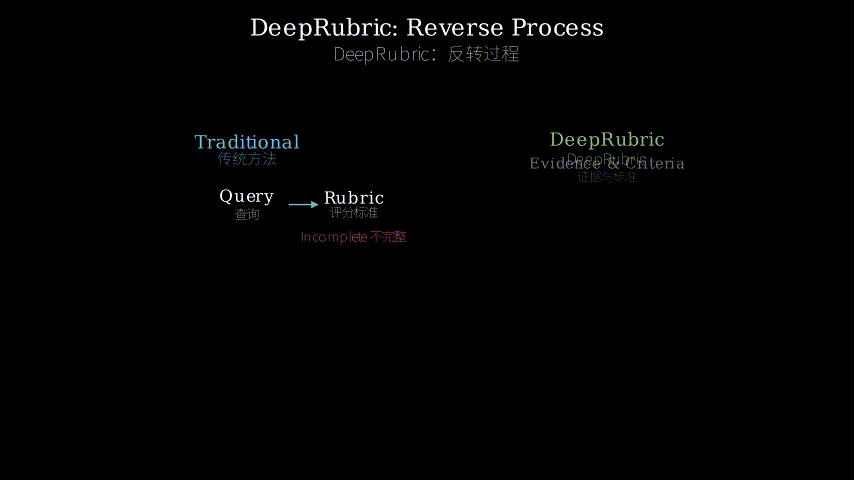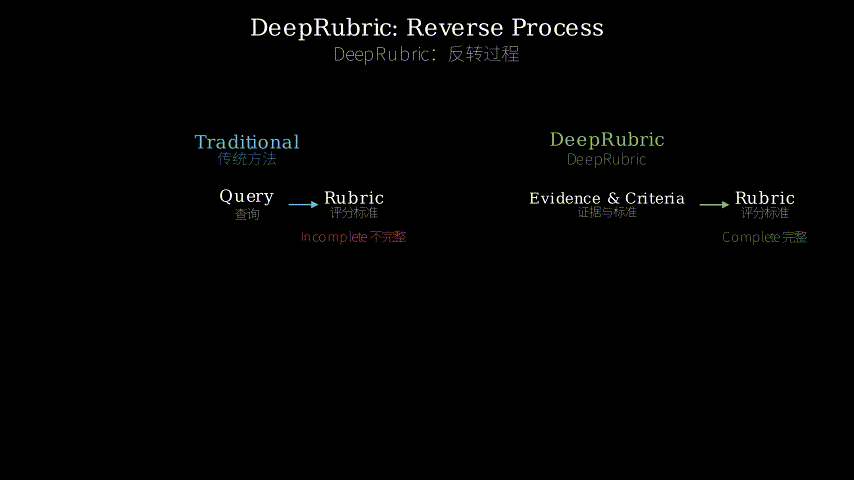
Existing deep research agents use reinforcement learning with rubric-based rewards to improve report quality. The rubrics—a set of checkable criteria—are typically generated by an LLM for a given user query. The assumption is that the LLM can correctly infer the underlying information needs from the query text alone. But when the query is ambiguous or the user’s true needs miss details, the generated rubrics can be incomplete or misaligned. This weakens the reward signal and reduces RL efficiency.
DeepRubric reverses the direction: instead of asking “what rubrics fit this query?”, it asks “what would a complete, evidence-backed report look like for this topic?” — then it generates both the query and the rubrics from that structure. The result: the reward always evaluates exactly what the query requests.
[Logic topology]
Problem: RL efficiency limited by incomplete rubrics from query
         |
         v
Assumption: rubrics should be derived from underlying evidence needs,
            not from surface query text
         |
         v
Method: build evidence tree from seed topic -> synthesize aligned
        query-rubric pairs from tree leaves -> train with GRPO
         |
         v
Evidence: 13x fewer RL GPU-hours while matching SOTA performance
         |
         v
Conclusion: evidence-driven rubric construction improves RL efficiency
            for deep research agents
The Increment
One sentence: Before this paper, rubrics were guessed from queries and often missed evidence needs; after this paper, rubrics are built from evidence trees, guaranteeing they align with what the query actually asks for.
Core Mechanism
DeepRubric has two stages. First, evidence tree construction: starting from a seed topic (e.g., “quantum computing applications in drug discovery”), the system recursively extracts sub-questions from retrieved evidence snippets. Each sub-question is decomposed further until the leaves are atomic, verifiable statements that can be checked directly (e.g., “Has drug A been used in a quantum chemistry simulation?”). The tree is built by a retrieval-augmented generation loop: a supervisor LLM reads retrieved passages, proposes decompositions, and keeps only those with concrete evidence support.
Second, query-rubric synthesis: from the complete tree, a training query is generated by prompting an LLM to produce a natural question whose answer would require all leaf-level evidence. Simultaneously, each leaf becomes a rubric criterion (“the report should include evidence that …”). The resulting query-rubric pair guarantees that the rubric covers exactly the information needed to answer the query — because both come from the same tree.
These pairs are used to train an 8B model with rubric-based GRPO (Group Relative Policy Optimization), where each generated report is scored against rubrics, and those scores serve as reward signals.
[Method internals]
Seed topic -> [Evidence tree builder]
              |  +-- recursive sub-question expansion with retrieval
              |  +-- leaf nodes = atomic verifiable claims
              |  +-- internal nodes = high-level questions
              v
         Evidence tree (complete hierarchy)
              |
              v
         [Query synthesis] -> training query
         [Rubric synthesis] -> list of leaf criteria
              |
              v
         Query-rubric pair (aligned)
              |
              v
         RL training (GRPO) with rubric rewards
Structural metaphor: Think of DeepRubric as a detective building a case file before writing the cold-case report.
- Seed topic: the unsolved murder (e.g., “did the butler do it?”).
- Evidence tree: the detective’s breakdown of the case into sub-investigations: alibis, fingerprints, motives. Each sub-investigation splits further (e.g., “was the butler’s alibi verified?” becomes “did anyone see him?” and “was he logged in to the security system?”).
- Leaf nodes: concrete, checkable facts (e.g., “fingerprints on the knife match the butler’s left hand”).
- Training query: a question that requires all leaf facts to answer (e.g., “compose a final report on who killed Mr. X, using all evidence collected”).
- Rubrics: the prosecutor’s checklist — “did the report mention the fingerprint match?” “did it cover the security log?”
- RL training: the detective practices writing cold-case reports, and each report is graded against the checklist. The detective learns to always include the key evidence.
Without the evidence tree, the detective might write a report that misses the security log (a rubric oversight). With DeepRubric, the checklist and the question are derived from the same tree, so nothing is missed.
Key Concepts
- Evidence tree: A recursively expanded hierarchy of sub-questions, each backed by retrieved evidence snippets. The tree’s leaves are atomic, verifiable statements that serve as evaluation targets.
Example: Seed “impact of remote work on productivity” → sub-questions: “effect on individual output?”, “effect on team collaboration?”, “long-term trends?” → leaf: “Study X found a 12% increase in individual output for knowledge workers in 2022.” - Rubric-based GRPO: A variant of policy gradient where the reward is computed from a rubric (a list of binary/ordinal criteria). GRPO normalizes rewards across a group of sampled responses to stabilize training. The rubric provides fine-grained, interpretable signals.
Example: For a rubric with 5 criteria, a report meeting 4 gets reward 4/5; GRPO then standardizes this across 8 parallel samples. - Query-rubric alignment: The property that the training query and the rubric criteria are generated from the same evidence tree. This ensures that the reward function evaluates exactly the information requested — no extra, no missing.
Contrast: Prior work uses a separate prompt to ask “what rubrics for query Q?” — the LLM may guess “talk about X” but the implicit need is for Y. Alignment breaks.
Framework Shift
Before (mainstream approach):        After (this paper):

User query Q                         Seed topic T
     |                                     |
     v                                     v
[LLM rubric generator]               [Evidence tree builder]
     |                                     |
     |  +-- "Create rubrics for Q"         |  +-- Recursively expand
     |  +-- may miss needs                 |  +-- with retrieval
     v                                     v
Rubrics R (maybe incomplete)         Evidence tree E (complete)
     |                                     |
     v                                     |---------+
[RL training]                         [Query synth.] [Rubric synth.]
     |                                     |             |
     v                                     v             v
Trained agent                        Query Q' from E   Rubrics R' from E
                                          |             |
                                          v             v
                                     [RL training with aligned pair]
                                          |
                                          v
                                     Trained agent
One sentence: From query-driven rubric generation (rubrics might not match hidden needs) to evidence-driven joint synthesis of query and rubrics (guaranteed alignment), the core shift is structural guarantee over predictive guess.
Expert Assessment
Problem choice: Real gap. Many RL-based research agents suffer from reward misalignment; this paper directly tackles the root cause (incomplete rubrics) rather than patching the reward model. It sits at the intersection of RL, data augmentation, and information retrieval — timely.
Method maturity: Clever insight, not brute force. The evidence tree construction is recursive and retrieval-heavy but well-motivated. A simpler approach could reuse existing hierarchical QA datasets (e.g., HotpotQA), but those have fixed queries; DeepRubric generates both queries and rubrics, increasing coverage. The overhead of building 9K trees is acceptable given the 13x training speedup.
Experimental integrity: Baselines are fair — they compare against prior open SOTA models (e.g., DeepSearch, STILL-2). The 13x reduction in RL GPU-hours is impressive. However, they only evaluate on three benchmarks (e.g., ALCE, ASQA, ELI5). Could overfit to datasets with atomic sub-questions. No ablation on tree construction depth or retrieval quality — that’s a red flag. Also, the seed topic selection process is not fully specified; reproducibility concerns.
Writing quality: Good clarity overall, but the evidence tree construction details are buried in the appendix. The main paper could benefit from a concrete example walkthrough (like a full query-rubric pair generated from one seed topic). The metaphor in this blog helps — the authors didn’t include one. That single added section would elevate the paper for a broader audience.
Verdict: strong accept — provides a principled, practical solution to a known efficiency bottleneck, with convincing experimental results and clear methodological improvement.
Takeaways
- Reverse rubric generation: Whenever you need to train a model with reward shaping, consider generating the evaluation criteria from the data structure (e.g., from a reference solution in code generation, from a decomposition tree in planning) rather than asking an LLM to predict them from the input.
- Evidence tree as a reusable asset: The tree itself can be used for data augmentation (generate multiple queries from different paths), curriculum learning, or even interpretability. Practitioners can export the framework to any domain where complex queries decompose into atomic checks (e.g., legal document analysis, medical report generation).
- GRPO with rubric rewards: The combination of normalized group rewards and fine-grained criteria is a simple yet effective trick. If you’re using RL for language generation, this recipe is worth copying: define criteria, compute rewards per criterion, then normalize across a batch.
论文: 2606.17029 作者: Minghang Zhu, Chuyang Wei, Junhao Xu, Yilin Cheng, Zhumin Chen, Jiyan He 分类: cs.CL
缺口
现有的深度研究智能体使用基于评分标准的奖励进行强化学习,以提升报告质量。 这些评分标准通常由大语言模型(LLM)根据用户查询生成。 假设是LLM能仅从查询文本正确推断用户的真实信息需求。 但当查询模糊或用户需求隐藏细节时,生成的评分标准可能不完整或错位。 这会削弱奖励信号,降低RL效率。
DeepRubric逆转了这一方向:不再问“什么评分标准适合这个查询?”, 而是问“一个完整、有证据支撑的报告应该长什么样?”, 然后从该结构中同时生成查询和评分标准。 结果:奖励永远准确评估查询所要求的内容。
[逻辑拓扑]
问题:从查询生成的评分标准不完整,限制RL效率
         |
         v
假设:评分标准应从底层的证据需求推导,而非表面查询文本
         |
         v
方法:从种子主题构建证据树 -> 从树叶子节点合成对齐的
      查询-评分标准对 -> 使用GRPO训练
         |
         v
证据:13倍RL GPU时长节省,同时达到SOTA性能
         |
         v
结论:证据驱动的评分标准构建提升了深度研究智能体的RL效率
增量
一句话:这篇论文之前,评分标准从查询猜测,常遗漏证据需求; 这篇论文之后,评分标准从证据树构建,保证与查询实际要求一致。
核心机制
DeepRubric包含两个阶段。 首先,证据树构建:从种子主题(例如“量子计算在药物发现中的应用”)出发, 系统从检索到的证据片段中递归提取子问题。 每个子问题进一步分解,直到叶子节点成为原子化、可验证的陈述 (例如“药物A是否曾用于量子化学模拟?”)。 树由检索增强生成循环构建:监督LLM阅读检索段落,提出分解方案, 仅保留有具体证据支持的节点。
其次,查询-评分标准合成:从完整的树出发,通过提示LLM生成一个 自然的训练查询,其答案需要涵盖所有叶子级别的证据。 同时,每个叶子节点变成一条评分标准 (“报告应包含证据证明……”)。 由此产生的查询-评分标准对保证评分标准恰好覆盖回答查询所需的信息 ——因为两者来自同一棵树。
这些数据对用于训练一个8B模型,采用基于评分标准的GRPO (组相对策略优化),每个生成的报告根据评分标准打分, 这些分数作为奖励信号。
[方法内部结构]
种子主题 -> [证据树构建器]
              |  +-- 递归子问题扩展 + 检索
              |  +-- 叶子节点 = 原子可验证声明
              |  +-- 内部节点 = 高层问题
              v
         证据树(完整层次结构)
              |
              v
         [查询合成] -> 训练查询
         [评分标准合成] -> 叶子标准列表
              |
              v
         查询-评分标准对(对齐)
              |
              v
         RL训练(GRPO)基于评分标准奖励
核喻:把DeepRubric想象成一名侦探在写冷案报告前先建立案件档案。
- 种子主题:未破命案(例如“管家是凶手吗?”)。
- 证据树:侦探将案件分解成多个子调查:不在场证明、指纹、动机。 每个子调查进一步分裂(例如“管家的不在场证明核实了吗?” 变成“有人看见他吗?”和“他登录了安保系统吗?”)。
- 叶子节点:具体、可核查的事实(例如“刀上的指纹与管家的左手吻合”)。
- 训练查询:需要所有叶子事实才能回答的问题 (例如“根据收集的所有证据撰写关于X先生谋杀案的最终报告”)。
- 评分标准:检察官的检查清单——“报告提到指纹匹配了吗?” “它涵盖安保日志了吗?”
- RL训练:侦探练习写冷案报告,每份报告对照检查清单评分。 侦探学会始终包含关键证据。
没有证据树,侦探可能会遗漏安保日志(评分标准疏忽)。 有了DeepRubric,检查清单和问题来自同一棵树,因此不会遗漏。
关键概念
- 证据树:递归展开的子问题层次结构,每个子问题由检索到的证据片段支持。 树的叶子是原子化、可验证的陈述,用作评估目标。 示例:种子“远程工作对生产力的影响” → 子问题:“对个人产出的影响?”、 “对团队协作的影响?”、“长期趋势?” → 叶子:“2022年研究发现知识工作者个人产出提高12%”。
- 基于评分标准的GRPO:策略梯度的一种变体, 奖励来自一个评分标准列表(二元或序数标准)。 GRPO将一组采样响应的奖励标准化,以稳定训练。 评分标准提供细粒度、可解释的信号。 示例:对于包含5条标准的标准集,满足4条的报告得4/5分; GRPO再在8个并行样本中标准化这个分数。
- 查询-评分标准对齐:训练查询和评分标准来自同一证据树的性质。 这保证奖励函数评估的正是查询所请求的信息——不多不少。 对比:先前工作使用单独的提示“为查询Q生成评分标准”—— LLM可能猜测“谈论X”,但隐含需求是Y。对齐被破坏。
框架转变
之前(主流方法):                之后(本文方法):

用户查询Q                          种子主题T
     |                                     |
     v                                     v
[LLM评分标准生成器]               [证据树构建器]
     |                                     |
     |  +-- "为Q创建评分标准"           |  +-- 递归扩展
     |  +-- 可能遗漏需求                |  +-- 结合检索
     v                                     v
评分标准R(可能不完整)            证据树E(完整)
     |                                     |
     v                                     |---------+
[RL训练]                          [查询合成]  [评分标准合成]
     |                                     |             |
     v                                     v             v
训练好的智能体                     来自E的查询Q'  来自E的评分标准R'
                                          |             |
                                          v             v
                                     [使用对齐对的RL训练]
                                          |
                                          v
                                     训练好的智能体
一句话:从查询驱动的评分标准生成(评分标准可能不匹配隐藏需求) 到证据驱动的联合合成查询和评分标准(保证对齐), 核心转变是从预测性猜测到结构性保证。
专家评审
选题眼光: 真缺口。 许多基于RL的研究智能体受奖励错位之困; 这篇论文直击根本原因(不完整的评分标准),而非修补奖励模型。 在RL、数据增强和信息检索的交汇处,时机恰当。
方法成熟度: 巧劲,非蛮力。 证据树构建递归且依赖检索,但动机充分。 更简单的方法可以复用现有的层次化QA数据集(如HotpotQA), 但那些有固定查询;DeepRubric同时生成查询和评分标准,覆盖更广。 构建9K棵树的代价在13倍训练加速面前是可接受的。
实验诚意: 基线公平——对比了先前开源SOTA模型 (如DeepSearch、STILL-2)。 13倍RL GPU时长削减令人印象深刻。 但仅在三个基准(如ALCE、ASQA、ELI5)上评估, 可能过度适配包含原子子问题的数据集。 未消融树构建深度或检索质量——这是红旗。 此外,种子主题选择过程未充分说明,有可复现性问题。
写作功力: 整体清晰,但证据树构建细节埋在附录。 主文若能有一个具体示例的完整走查 (例如从一个种子主题生成一个完整的查询-评分标准对),会更好。 本博客中使用的核喻——作者没加进去。 补上那一段,整篇论文就会对更广大的读者提升一个档次。
判决: 强接收 — 为一个已知的效率瓶颈提供了有原则、实用的解决方案, 实验有力,方法改进清晰。
要点总结
- 逆转评分标准生成:当你需要用奖励塑造训练模型时, 考虑从数据结构生成评价标准(例如代码生成中的参考解, 规划中的分解树),而不是让LLM从输入预测它们。
- 证据树作为可复用资产:树本身可以用于数据增强 (从不同路径生成多个查询)、课程学习或可解释性。 实践者可以将这个框架推广到任何复杂查询可分解为原子检查的领域 (例如法律文档分析、医学报告生成)。
- GRPO结合评分标准奖励:标准化组奖励与细粒度标准的结合, 是一个简单而有效的技巧。如果你在用RL做语言生成, 这个配方值得复制:定义标准,每条标准计算奖励,然后在批次内标准化。