Paper: 2605.22777 Authors: Tianhang Wang, Yitong Chen, Wei Song, Zuxuan Wu, Min Li, Jiaqi Wang Categories: cs.CV
The Gap
Representation Autoencoders (RAEs) freeze pretrained vision foundation models (VFMs) like DINOv2 as encoders, inheriting their semantic understanding for fast-converging latent diffusion. But freezing creates a dilemma: the VFM’s deep features excel at semantic abstraction but discard spatial details needed for pixel-perfect reconstruction. Fine-tuning to recover details destroys the pretrained semantic space, degrading generation quality. Prior work accepts this trade-off—good reconstruction or good generation, pick one.
Problem: Frozen VFM loses spatial detail
   |
   v
Assumption: Shallow layers retain fine-grained info
   |
   v
Method: Learnable queries extract details from intermediate features
   |
   v
Evidence: +3.7 dB PSNR, 3.3x faster convergence, <4% compute overhead
   |
   v
Conclusion: Reconstruction and generation are compatible via selective detail injection
The Increment
One sentence: Before DecQ, you chose between frozen VFMs (fast generation, blurry reconstruction) or fine-tuned VFMs (sharp reconstruction, degraded generation)—now you get both with 8 learnable queries.
Core Mechanism
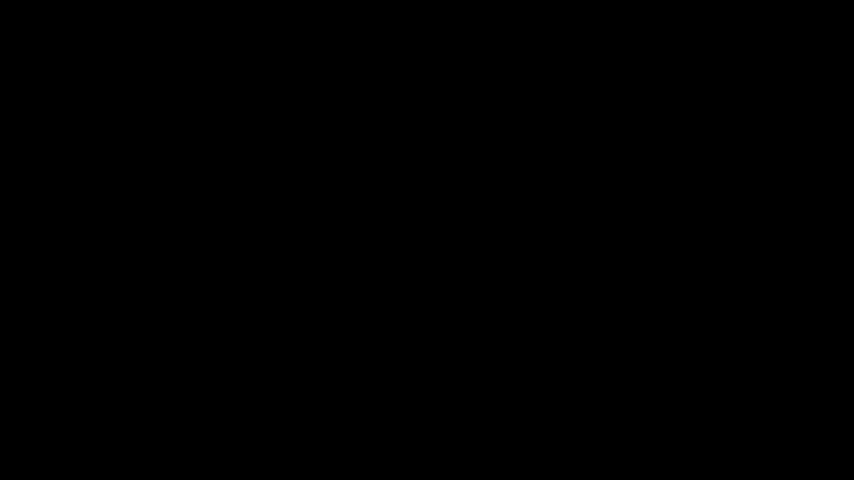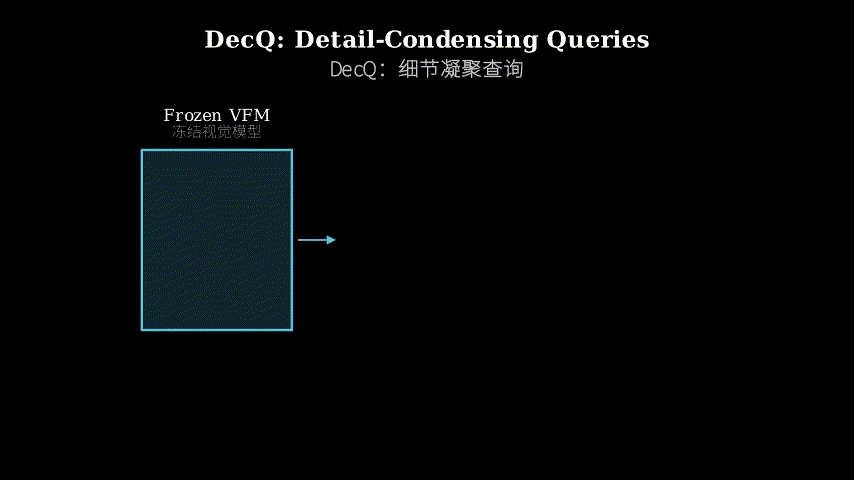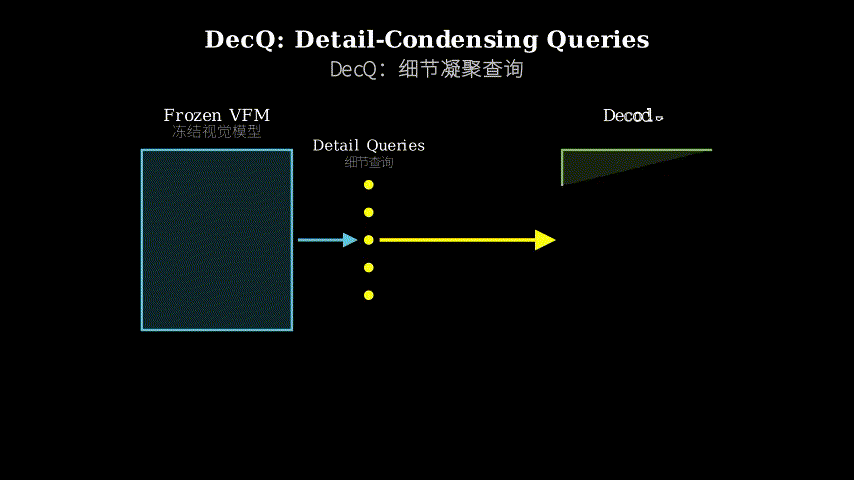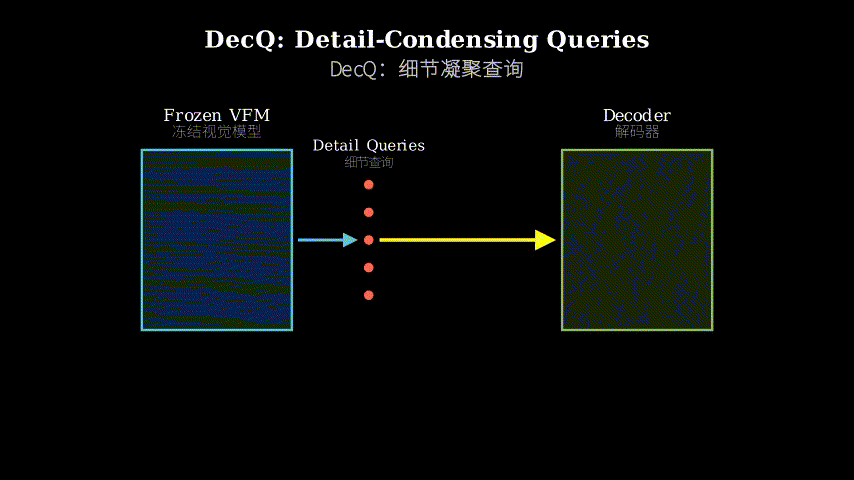
DecQ inserts lightweight “condenser modules” at multiple depths of the frozen VFM encoder. Each condenser takes intermediate feature maps and a small set of learnable queries (8 total across all layers) as input. Through cross-attention, queries extract fine-grained spatial information—texture edges, color gradients—that deep VFM layers discard. These detail-enriched queries are concatenated with the standard patch tokens from the VFM’s final layer, then fed to the decoder for reconstruction.
During generative modeling, the diffusion process jointly denoises both patch tokens and detail queries in the latent space. At inference, the model generates both types of tokens, which the decoder combines to produce high-fidelity images. The queries act as a side channel: they carry reconstruction-critical details without polluting the semantic patch tokens that drive generation quality.
Think of it like a restaurant kitchen with two communication channels. The main line (patch tokens) carries high-level orders: “table 5 wants pasta.” The frozen chef (VFM) interprets this semantically but loses specifics—al dente? what sauce? A separate detail line (queries) taps the prep stations (shallow layers) for texture and garnish info. The expeditor (decoder) combines both: semantic understanding from the main line, execution details from the side channel. Crucially, the detail line doesn’t interfere with the main line’s clarity—it just fills in what was lost in abstraction. The chef never changes their training (stays frozen), but the kitchen output improves.
Key Concepts
-
Condenser Module: A cross-attention block where learnable queries attend to intermediate VFM features. Unlike standard self-attention in transformers, queries here are fixed in number (not per-patch) and shared across images. They function as “detail extractors”—each query specializes in capturing specific types of fine-grained information (edges, textures, local color variations) by learning to attend to relevant spatial regions in shallow/mid-level features. The module is lightweight: a single cross-attention layer with layer norm and feedforward network, adding <4% computation.
-
Reconstruction-Generation Trade-off: Pretrained VFMs like DINOv2 are trained for semantic tasks (classification, retrieval), so their deep features prioritize category-level abstraction over pixel-level fidelity. Freezing preserves this semantic space—critical for generation—but sacrifices reconstruction. Fine-tuning recovers spatial detail but shifts the feature distribution, breaking the semantic structure that diffusion models rely on. DecQ resolves this by keeping the VFM frozen (preserving semantics) while extracting lost details from earlier layers via queries.
-
Joint Token Generation: Standard latent diffusion denoises patch tokens representing image semantics. DecQ extends this: the diffusion model learns to denoise both patch tokens and detail queries simultaneously. During training, both are corrupted with noise and jointly recovered. At inference, generating an image means sampling both token types from the learned distribution. This is efficient because queries are few (8 vs. 256+ patches) and share the same latent space, requiring no architectural changes to the diffusion model.
Framework Shift
Before (RAE):                          After (DecQ):

VFM Encoder (frozen)                   VFM Encoder (frozen)
  |                                      |    |    |
  | (deep features only)                 |    |    +---> Condenser 1
  |                                      |    +--------> Condenser 2
  v                                      +-------------> Condenser 3
Patch Tokens ---------> Decoder           |              |
                           |            Patch Tokens + Queries --> Decoder
                           v                              |
                        Output                            v
                                                        Output

Loss: Semantic space preserved,        Loss: Semantic space preserved,
      but blurry reconstruction              sharp reconstruction via queries
From single-path semantic encoding to dual-path semantic+detail encoding, the core shift is selective information recovery without retraining the foundation.
Expert Assessment
Problem choice: Real gap. The RAE framework (frozen VFM + latent diffusion) is gaining traction for its training efficiency, but the reconstruction ceiling is a documented limitation. This isn’t manufactured—practitioners building image editors on RAEs hit this wall immediately.
Method maturity: Elegant. Cross-attention for detail extraction is well-understood, but applying it as a frozen-model “patch” is clever. The design is minimal—8 queries, 3 condenser modules—avoiding the overengineering trap. However, the paper doesn’t explore why 8 queries suffice or whether query count should scale with image resolution. That’s a missed opportunity for principled design.
Experimental integrity: Baselines are fair (RAE, VAE, prior frozen-VFM work). The PSNR jump (19.13 → 22.76 dB) is substantial and visually verified in samples. FID improvements (1.41 vs. RAE’s slower convergence) are convincing. One concern: experiments are ImageNet-centric. Generalization to other domains (medical imaging, satellite imagery) is untested. Also, the 3.9% compute overhead is measured at training time—inference cost breakdown is missing.
Writing quality: The method section is crisp, but the related work undersells the novelty. The paper frames DecQ as “just adding queries,” which undersells the insight that shallow features can be tapped without fine-tuning. The ablation study (Section 4.3) is thorough, but Figure 3’s visualization of what queries capture is buried—it should be front and center.
Verdict: Weak accept — Solves a real problem with minimal complexity, but experimental scope is narrow and the paper doesn’t fully explore the design space (query scaling, domain transfer).
Takeaways
Steal the condenser pattern: If you’re working with frozen pretrained models and need task-specific information they don’t naturally provide, insert lightweight cross-attention modules at intermediate layers. Let learnable queries extract what you need without retraining the backbone. This generalizes beyond vision—language models, audio encoders, etc.
Dual-token generation: When your latent space has two types of information (semantic + detail, structure + texture), train the generative model to denoise both jointly rather than trying to cram everything into one token type. Keeps the latent space interpretable and modular.
Shallow layers matter: Don’t assume deep features are always better. For tasks requiring fine-grained information, explicitly tap earlier layers. The paper shows 3.7 dB gain from this alone—low-hanging fruit if your architecture currently ignores intermediate representations.
论文: 2605.22777 作者: Tianhang Wang, Yitong Chen, Wei Song, Zuxuan Wu, Min Li, Jiaqi Wang 分类: cs.CV
缺口
表示自编码器(RAE)冻结预训练视觉基础模型(VFM)如 DINOv2 作为编码器,继承其语义理解能力以实现快速收敛的潜在扩散。
但冻结带来两难:VFM 的深层特征擅长语义抽象,却丢弃了像素级重建所需的空间细节。
微调以恢复细节会破坏预训练的语义空间,降低生成质量。
先前工作接受这种权衡——好重建或好生成,二选一。
问题:冻结 VFM 丢失空间细节
   |
   v
假设:浅层保留细粒度信息
   |
   v
方法:可学习查询从中间特征提取细节
   |
   v
证据:+3.7 dB PSNR,3.3 倍收敛加速,<4% 计算开销
   |
   v
结论:通过选择性细节注入,重建与生成可兼容
增量
一句话: DecQ 之前,你在冻结 VFM(快速生成、模糊重建)和微调 VFM(清晰重建、生成退化)之间二选一——现在用 8 个可学习查询两者兼得。
核心机制
DecQ 在冻结 VFM 编码器的多个深度插入轻量级”压缩器模块”。
每个压缩器接收中间特征图和一小组可学习查询(所有层共 8 个)作为输入。
通过交叉注意力,查询提取细粒度空间信息——纹理边缘、颜色梯度——这些是深层 VFM 丢弃的。
这些富含细节的查询与 VFM 最终层的标准补丁令牌拼接,然后送入解码器进行重建。
在生成建模期间,扩散过程在潜在空间中联合去噪补丁令牌和细节查询。
推理时,模型生成两种令牌,解码器将它们结合以产生高保真图像。
查询充当侧信道:它们携带重建关键细节,而不污染驱动生成质量的语义补丁令牌。
把它想象成一个有两条通信渠道的餐厅厨房。
主线(补丁令牌)传递高层订单:“5 号桌要意面。
“冻结的厨师(VFM)在语义上理解这个,但丢失细节——要硬度如何?
什么酱汁?
单独的细节线(查询)从备菜站(浅层)获取质地和装饰信息。
传菜员(解码器)结合两者:主线的语义理解,侧信道的执行细节。
关键是,细节线不干扰主线的清晰度——它只是填补抽象中丢失的内容。
厨师从不改变训练(保持冻结),但厨房输出改善了。
关键概念
- 压缩器模块: 一个交叉注意力块,可学习查询关注中间 VFM 特征。
与 transformer 中的标准自注意力不同,这里的查询数量固定(不是每个补丁一个)且跨图像共享。
它们充当”细节提取器”——每个查询通过学习关注浅层/中层特征中的相关空间区域,专门捕获特定类型的细粒度信息(边缘、纹理、局部颜色变化)。
模块轻量:单个交叉注意力层加层归一化和前馈网络,增加 <4% 计算量。
- 重建-生成权衡: 预训练 VFM 如 DINOv2 为语义任务(分类、检索)训练,因此其深层特征优先考虑类别级抽象而非像素级保真度。
冻结保留了这个语义空间——对生成至关重要——但牺牲了重建。
微调恢复空间细节但改变特征分布,破坏扩散模型依赖的语义结构。
DecQ 通过保持 VFM 冻结(保留语义)同时通过查询从早期层提取丢失细节来解决这个问题。
- 联合令牌生成: 标准潜在扩散对表示图像语义的补丁令牌去噪。
DecQ 扩展了这一点:扩散模型学习同时对补丁令牌和细节查询去噪。
训练期间,两者都被噪声破坏并联合恢复。
推理时,生成图像意味着从学习的分布中采样两种令牌类型。
这很高效,因为查询很少(8 个 vs. 256+ 个补丁)且共享相同的潜在空间,不需要对扩散模型进行架构更改。
框架转变
之前(RAE):                          之后(DecQ):

VFM 编码器(冻结)                     VFM 编码器(冻结)
  |                                      |    |    |
  |(仅深层特征)                         |    |    +---> 压缩器 1
  |                                      |    +--------> 压缩器 2
  v                                      +-------------> 压缩器 3
补丁令牌 ---------> 解码器                 |              |
                      |                补丁令牌 + 查询 --> 解码器
                      v                                   |
                   输出                                   v
                                                       输出

损失:语义空间保留,                    损失:语义空间保留,
      但重建模糊                              通过查询实现清晰重建
从单路径语义编码到双路径语义+细节编码,核心转变是在不重训基础模型的情况下选择性恢复信息。
专家评审
选题眼光: 真实缺口。
RAE 框架(冻结 VFM + 潜在扩散)因其训练效率而受到关注,但重建上限是已记录的局限。
这不是人造的——在 RAE 上构建图像编辑器的实践者立即碰到这堵墙。
方法成熟度: 优雅。
用于细节提取的交叉注意力是成熟技术,但将其作为冻结模型”补丁”应用很巧妙。
设计极简——8 个查询、3 个压缩器模块——避免了过度工程化陷阱。
然而,论文没有探讨为什么 8 个查询足够,或查询数量是否应随图像分辨率缩放。
这是错失的原则性设计机会。
实验诚意: 基线公平(RAE、VAE、先前冻结 VFM 工作)。
PSNR 跃升(19.13 → 22.76 dB)显著且在样本中视觉验证。
FID 改进(1.41 vs. RAE 的较慢收敛)令人信服。
一个担忧:实验以 ImageNet 为中心。
对其他领域(医学成像、卫星图像)的泛化未经测试。
此外,3.9% 计算开销是在训练时测量的——推理成本分解缺失。
写作功力: 方法部分简洁,但相关工作低估了新颖性。
论文将 DecQ 框定为”只是添加查询”,低估了浅层特征可以在不微调的情况下被利用的洞察。
消融研究(第 4.3 节)彻底,但图 3 对查询捕获内容的可视化被埋没——它应该放在最前面。
判决: 弱接收 — 用最小复杂度解决真实问题,但实验范围狭窄,论文未充分探索设计空间(查询缩放、领域迁移)。
要点总结
偷学压缩器模式: 如果你使用冻结预训练模型且需要它们不自然提供的任务特定信息,在中间层插入轻量级交叉注意力模块。
让可学习查询提取你需要的内容,而不重训主干。
这超越视觉——语言模型、音频编码器等都适用。
双令牌生成: 当你的潜在空间有两种信息类型(语义+细节、结构+纹理)时,训练生成模型联合去噪两者,而不是试图将所有内容塞进一种令牌类型。
保持潜在空间可解释和模块化。
浅层很重要: 不要假设深层特征总是更好。
对于需要细粒度信息的任务,显式利用早期层。
论文显示仅此就有 3.7 dB 增益——如果你的架构目前忽略中间表示,这是低垂的果实。