Paper: 2604.11581 Authors: Solomon Messing Categories: cs.CL
The Gap
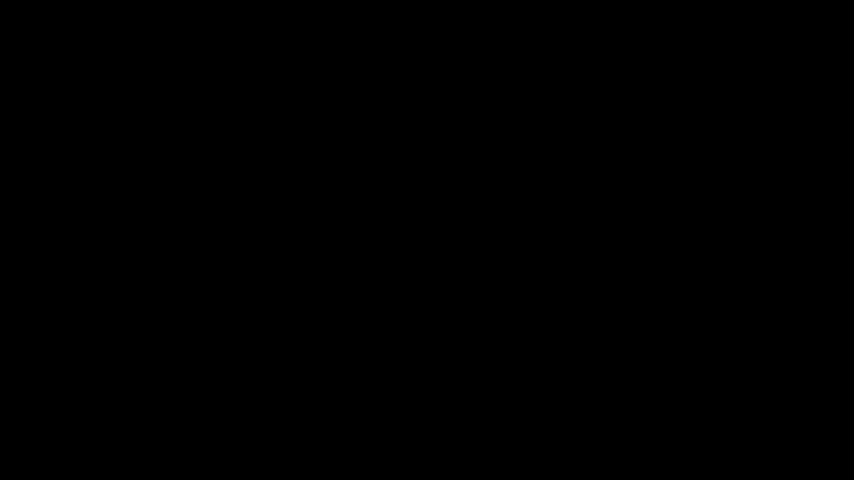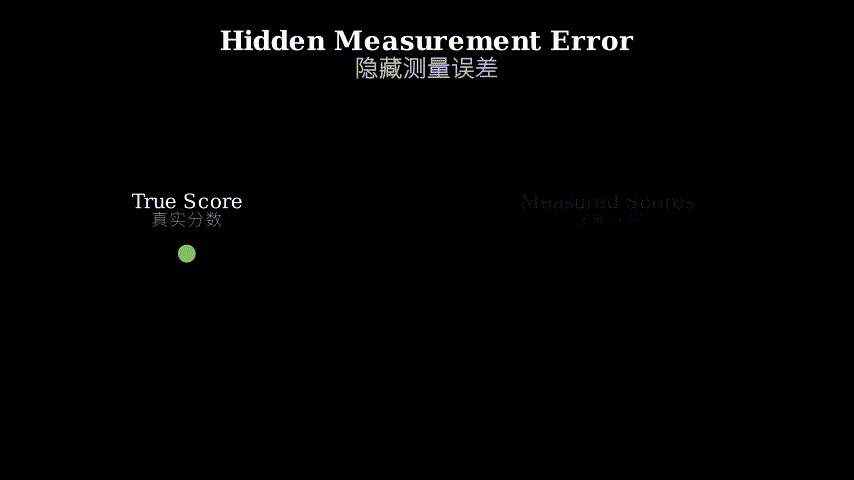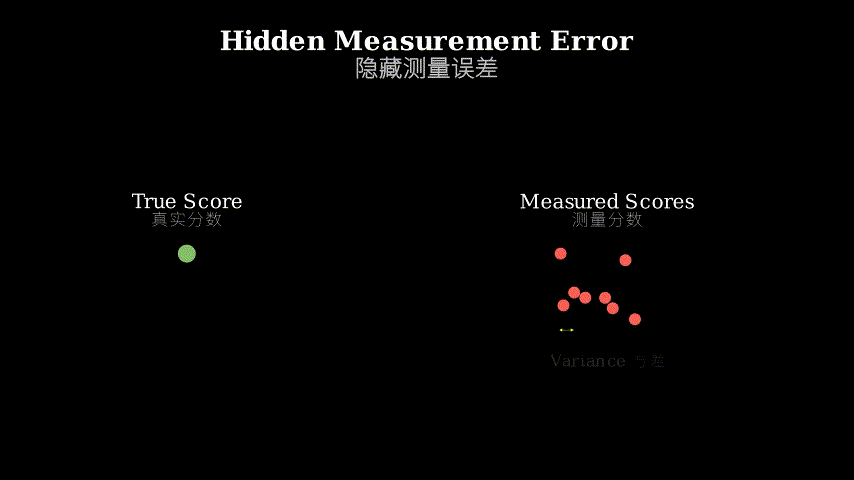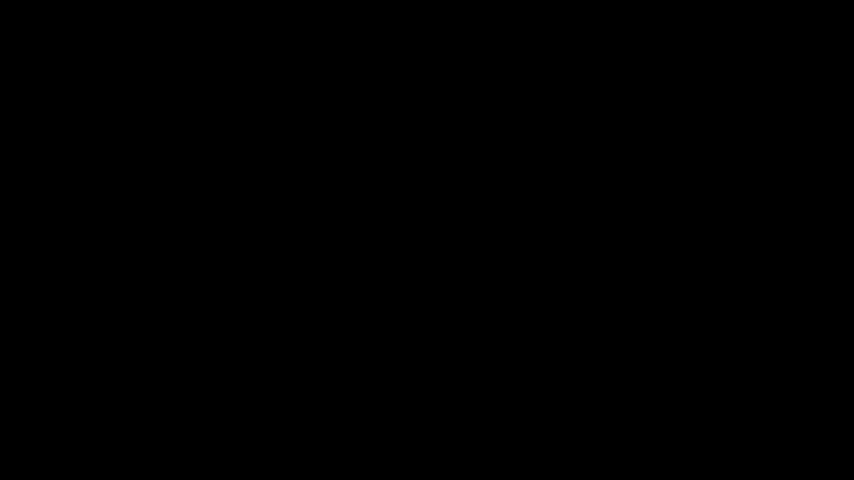
LLM evaluation has reached industrial scale—benchmark scores determine which models get deployed, which safety standards get adopted, which papers get published. But the field treats evaluation pipelines like precise instruments when they’re actually noisy measurement systems. Standard practice: run a prompt through a judge model, collect scores, compute confidence intervals assuming the only variance comes from sampling more examples. Reality: change the prompt phrasing, swap the judge model, adjust temperature—rankings flip, conclusions reverse.
Prior work acknowledges prompt sensitivity but treats it as a nuisance to minimize rather than a structural property to measure and decompose. The gap: no framework exists to separate variance that shrinks with more data (sampling error) from variance that persists regardless of sample size (design sensitivity). This matters because standard confidence intervals ignore design sensitivity, producing under-coverage that worsens as you collect more data. Worse, unmeasured variance creates exploitable surface—developers can optimize against measurement noise rather than genuine capability.
Problem: LLM eval scores unstable
    |
    v
Assumption: Design choices (prompt/judge/temp)
            create persistent variance distinct
            from sampling variance
    |
    v
Method: Variance decomposition framework
        + projection-based optimization
    |
    v
Evidence: 73% of naive pipelines outperformed
          MMLU error halved at same cost
    |
    v
Conclusion: Proper variance accounting enables
            robust benchmarks + efficient allocation
The Increment
One sentence: Before this paper, LLM evaluation treated pipeline design choices as fixed parameters; after, they’re recognized as variance components that can be measured, decomposed, and optimized against.
Core Mechanism
The method has three layers. First, variance decomposition: treat each design choice (prompt variant, judge model, temperature) as a random effect in a hierarchical model. Run a small pilot study crossing these factors, fit the model, extract variance components. This tells you how much uncertainty comes from sampling (shrinks with more data) versus design sensitivity (doesn’t shrink).
Second, projection-based optimization: given a budget, allocate resources to minimize total error. If prompt variance dominates, average over multiple prompts. If judge variance dominates, ensemble multiple judges. If sampling variance dominates, just collect more examples. The decomposition tells you where to spend.
Third, coverage-corrected inference: standard confidence intervals assume only sampling variance exists. When design variance is present, they under-cover—the true parameter falls outside the interval more often than claimed. The framework adjusts intervals to account for all variance sources, achieving nominal coverage.
Input data
    |
    v
[Pilot study] ---> Cross design factors
    |              (prompts x judges x temps)
    v
[Variance model] ---> Fit hierarchical model
    |                  Extract components:
    |                  - sigma_sampling
    v                  - sigma_prompt
[Decomposition] <---  - sigma_judge
    |                  - sigma_temp
    v
[Optimizer] ---> Given budget B, allocate:
    |            - n_examples
    |            - n_prompts
    v            - n_judges
[Projection] ---> Minimize total error
    |
    v
Robust scores + valid CIs
Think of it like tuning a radio. Standard evaluation is like assuming the signal is perfectly clear and any static is just from your antenna being too short—so you buy a longer antenna (collect more data). This paper says: actually, the static has multiple sources. Some is from your antenna (sampling), some from atmospheric interference (prompt sensitivity), some from the radio’s internal circuits (judge variance). A longer antenna won’t fix atmospheric interference. You need to measure each source separately, then decide: should I buy a longer antenna, add a noise filter, or use multiple radios and average their signals? The variance decomposition is your diagnostic tool; the projection optimizer is your resource allocation strategy.
Key Concepts
-
Design sensitivity vs sampling variance: Sampling variance is uncertainty from not seeing all possible examples—it shrinks as you collect more data, following 1/√n. Design sensitivity is uncertainty from arbitrary choices in your measurement pipeline—prompt phrasing, judge model selection, temperature settings. It doesn’t shrink with more data because it’s not about sample size; it’s about which measurement instrument you picked. Imagine measuring a table with a ruler: sampling variance is like measuring 10 spots versus 100 spots on the table. Design sensitivity is like using a wooden ruler versus a metal ruler—they might give slightly different readings, and measuring more spots won’t make that difference go away. Standard confidence intervals only account for sampling variance, so they claim 95% coverage but actually achieve 70% when design sensitivity is present.
-
Exploitable surface: When variance sources are unmeasured, they become targets for gaming. If prompt phrasing affects scores but isn’t accounted for in the benchmark, developers can search over prompts to find ones that inflate their model’s score without improving actual capability. It’s like a student who discovers the teacher always asks questions from odd-numbered chapters—they can optimize for the test without learning the material. The paper shows that variance decomposition identifies which design choices contribute exploitable surface, letting benchmark builders lock down those dimensions (e.g., average over multiple prompts) to make gaming harder.
-
Projection-based optimization: Given a fixed budget, how should you allocate resources across design dimensions to minimize total error? The projection approach: use your variance decomposition to predict total error for different allocation strategies, then pick the best one. If you have $1000 to spend on evaluation, should you run 1000 examples with one prompt, or 100 examples with 10 prompts, or 50 examples with 5 prompts and 4 judge models? The decomposition tells you which variance sources dominate, and the optimizer allocates budget to shrink the biggest sources first. It’s like deciding whether to spend your home renovation budget on fixing the leaky roof, repainting the walls, or upgrading the kitchen—you measure which problem causes the most damage, then allocate accordingly.
Framework Shift
Before (standard approach):        After (this paper):

[Prompt] ---> [Judge] ---> Score   [Prompt 1]---\
                |                  [Prompt 2]----+--> [Judge 1]---\
                v                  [Prompt 3]---/                  \
         Confidence interval                                        +---> Score
         (sampling variance only)  [Prompt 1]---\                  /      + CI
                                   [Prompt 2]----+--> [Judge 2]---/
         Assumes: design choices   [Prompt 3]---/                         (all variance
         are fixed parameters                                              sources)
                                   Treats: design choices as
                                   random effects to measure
From treating evaluation pipelines as fixed instruments to treating them as measurement systems with quantifiable uncertainty across multiple dimensions.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The field has been running large-scale benchmarks for years while ignoring a basic measurement theory principle: your instrument’s properties matter. The timing is right—LLM evaluation has reached the scale where measurement error actually affects decisions (model deployment, safety standards), so the stakes justify the overhead of proper variance accounting. It sits at the intersection of ML evaluation and survey methodology, borrowing from a mature field (survey statistics) to fix a young one (LLM benchmarking).
Method maturity: The core insight—decompose variance into sources—is borrowed from hierarchical modeling in statistics, not novel. But the application is clever: recognizing that LLM evaluation pipelines have the same structure as survey instruments (multiple raters, multiple items, design choices). The projection-based optimization is straightforward operations research once you have the variance components. No deep learning, no fancy algorithms—just careful accounting. This is a strength, not a weakness. The paper could have been simpler by focusing on variance decomposition alone; the projection optimizer feels like a second paper stapled on.
Experimental integrity: Baselines are fair—the paper compares against standard single-prompt evaluation, which is what everyone actually does. The human validation on propaganda detection is crucial; without it, we’d just be comparing noisy measurements to other noisy measurements. The 73% outperformance claim is solid but slightly misleading—it’s 73% of *naive pipelines, not 73% of reasonable pipelines. A practitioner who already averages over multiple prompts wouldn’t see that gain. The MMLU result (halving error at same cost) is more impressive because MMLU is widely used. One red flag: the paper doesn’t show what happens when the variance model is misspecified—what if there are interaction effects between prompt and judge that the model misses?
Writing quality: The introduction is excellent—clear problem statement, concrete examples, stakes are obvious. The method section bogs down in notation; a running example would help. The results section jumps between datasets without enough connective tissue—why these four tasks? What do they have in common? The discussion is where the paper should have elevated itself: what does this mean for benchmark design going forward? Should MMLU adopt this framework? Instead, it just recaps the results. Rewriting the discussion to focus on implications for benchmark builders would make this a stronger contribution.
Verdict: weak accept — Solid contribution to an important problem, but feels like two papers (variance decomposition + projection optimization) that would each be stronger standalone. The experimental validation is thorough, but the writing doesn’t fully capitalize on the insights.
Takeaways
Practitioners can steal the variance decomposition recipe: run a small pilot (50-100 examples) crossing your design choices (3-5 prompts × 2-3 judges × 2-3 temperatures), fit a hierarchical model, extract variance components. This tells you where your uncertainty actually comes from. If you’re building a benchmark, use this to identify exploitable surface—any design choice with high variance is a gaming target, so lock it down by averaging or ensembling. If you’re evaluating models, use the projection optimizer to allocate budget efficiently—don’t blindly collect more data if prompt variance dominates. The coverage-corrected confidence intervals are immediately usable: just include design factors as random effects in your model, and your CIs will actually achieve nominal coverage. The broader lesson: treat your evaluation pipeline like a measurement instrument, not a black box. Measure its properties, understand its error sources, optimize accordingly.
论文: 2604.11581 作者: Solomon Messing 分类: cs.CL
缺口
大模型评估已达到工业规模——基准测试分数决定哪些模型被部署、哪些安全标准被采纳、哪些论文被发表。
但学界把评估管道当作精密仪器,实际上它们是充满噪声的测量系统。
标准做法:让提示词通过评判模型,收集分数,计算置信区间,假设唯一的方差来自采样更多样本。
现实:改变提示措辞、更换评判模型、调整温度参数——排名翻转,结论逆转。
先前工作承认提示敏感性,但把它当作需要最小化的麻烦,而非需要测量和分解的结构性属性。
缺口在于:没有框架能够分离随数据增加而缩小的方差(采样误差)和无论样本量多大都持续存在的方差(设计敏感性)。
这很重要,因为标准置信区间忽略设计敏感性,产生覆盖不足,且随着数据增多而恶化。
更糟的是,未测量的方差创造了可利用的博弈空间——开发者可以针对测量噪声而非真实能力进行优化。
问题:大模型评估分数不稳定
    |
    v
假设:设计选择(提示/评判/温度)
      产生持续方差,区别于采样方差
    |
    v
方法:方差分解框架
      + 投影优化
    |
    v
证据:73%的朴素管道被超越
      MMLU误差在同等成本下减半
    |
    v
结论:正确的方差核算实现
      稳健基准 + 高效分配
增量
一句话: 这篇论文之前,大模型评估把管道设计选择当作固定参数;
之后,它们被识别为可测量、可分解、可优化的方差成分。
核心机制
方法分三层。
第一层,方差分解:把每个设计选择(提示变体、评判模型、温度)当作层次模型中的随机效应。
运行小规模试点研究,交叉这些因素,拟合模型,提取方差成分。
这告诉你有多少不确定性来自采样(随数据增加而缩小)还是设计敏感性(不会缩小)。
第二层,基于投影的优化:给定预算,分配资源以最小化总误差。
如果提示方差占主导,就对多个提示取平均。
如果评判方差占主导,就集成多个评判模型。
如果采样方差占主导,就收集更多样本。
分解告诉你该在哪里花钱。
第三层,覆盖校正推断:标准置信区间假设只存在采样方差。
当设计方差存在时,它们覆盖不足——真实参数落在区间外的频率高于声称的频率。
框架调整区间以考虑所有方差来源,实现名义覆盖率。
输入数据
    |
    v
[试点研究] ---> 交叉设计因素
    |           (提示 x 评判 x 温度)
    v
[方差模型] ---> 拟合层次模型
    |           提取成分:
    |           - sigma_采样
    v           - sigma_提示
[分解] <---     - sigma_评判
    |           - sigma_温度
    v
[优化器] ---> 给定预算B,分配:
    |         - n_样本数
    |         - n_提示数
    v         - n_评判数
[投影] ---> 最小化总误差
    |
    v
稳健分数 + 有效置信区间
把它想象成调收音机。
标准评估就像假设信号完全清晰,任何杂音都只是因为天线太短——所以你买更长的天线(收集更多数据)。
这篇论文说:实际上,杂音有多个来源。
有些来自天线(采样),有些来自大气干扰(提示敏感性),有些来自收音机内部电路(评判方差)。
更长的天线修不好大气干扰。
你需要分别测量每个来源,然后决定:我该买更长的天线、加噪声滤波器,还是用多台收音机取平均信号?
方差分解是你的诊断工具;
投影优化器是你的资源分配策略。
关键概念
- 设计敏感性 vs 采样方差: 采样方差是因为没看到所有可能样本而产生的不确定性——它随着收集更多数据而缩小,遵循1/√n规律。
设计敏感性是因为测量管道中的任意选择而产生的不确定性——提示措辞、评判模型选择、温度设置。
它不随更多数据而缩小,因为它与样本量无关;
它关乎你选了哪个测量工具。
想象用尺子测量桌子:采样方差就像测量桌子上10个点还是100个点。
设计敏感性就像用木尺还是金属尺——它们可能给出略微不同的读数,测量更多点也不会让这个差异消失。
标准置信区间只考虑采样方差,所以声称95%覆盖率但实际上当设计敏感性存在时只达到70%。
- 可利用的博弈空间: 当方差来源未被测量时,它们就成为博弈的目标。
如果提示措辞影响分数但基准测试中未被考虑,开发者可以搜索提示词来找到能提高模型分数的措辞,而不用改进实际能力。
就像学生发现老师总是从奇数章节出题——他们可以针对考试优化而不用学习材料。
论文表明方差分解能识别哪些设计选择贡献了可利用的博弈空间,让基准构建者锁定这些维度(例如对多个提示取平均)以增加博弈难度。
- 基于投影的优化: 给定固定预算,你应该如何在设计维度上分配资源以最小化总误差?
投影方法:用你的方差分解预测不同分配策略的总误差,然后选最好的。
如果你有1000美元用于评估,你应该用一个提示运行1000个样本,还是用10个提示运行100个样本,还是用5个提示和4个评判模型运行50个样本?
分解告诉你哪些方差来源占主导,优化器优先分配预算来缩小最大的来源。
就像决定把家庭装修预算花在修漏水的屋顶、重新粉刷墙壁还是升级厨房——你测量哪个问题造成最大损害,然后相应分配。
框架转变
之前(标准方法):              之后(本文方法):

[提示] ---> [评判] ---> 分数    [提示1]---\
                |               [提示2]----+--> [评判1]---\
                v               [提示3]---/                \
         置信区间                                           +---> 分数
         (仅采样方差)            [提示1]---\                /      + 置信区间
                                [提示2]----+--> [评判2]---/
         假设:设计选择          [提示3]---/                       (所有方差
         是固定参数                                                来源)

                                处理:设计选择为
                                需测量的随机效应
从把评估管道当作固定工具,到把它们当作跨多个维度具有可量化不确定性的测量系统。
专家评审
选题眼光: 这是真缺口,不是人造的。
学界运行大规模基准测试多年,却忽略了测量理论的基本原则:你的工具属性很重要。
时机恰当——大模型评估已达到测量误差实际影响决策(模型部署、安全标准)的规模,所以风险证明了正确方差核算的开销是合理的。
它处于机器学习评估和调查方法论的交叉点,从成熟领域(调查统计)借鉴来修复年轻领域(大模型基准测试)。
方法成熟度: 核心洞见——把方差分解为来源——借自统计学中的层次建模,并非新颖。
但应用很巧妙:认识到大模型评估管道与调查工具有相同结构(多个评分者、多个项目、设计选择)。
基于投影的优化是一旦有了方差成分就很直接的运筹学。
没有深度学习,没有花哨算法——只是仔细核算。
这是优点,不是缺点。
论文本可以更简单,只聚焦方差分解;
投影优化器感觉像是订在一起的第二篇论文。
实验诚意: 基线公平——论文与标准单提示评估对比,这是大家实际在做的。
宣传检测的人工验证至关重要;
没有它,我们只是在比较噪声测量和其他噪声测量。
73%超越声明是可靠的,但略有误导——是73%的朴素管道,不是73%的合理管道。
已经对多个提示取平均的实践者不会看到那么大的收益。
MMLU结果(同等成本下误差减半)更令人印象深刻,因为MMLU被广泛使用。
一个警示:论文没展示方差模型错误指定时会发生什么——如果提示和评判之间存在模型遗漏的交互效应怎么办?
写作功力: 引言很出色——清晰的问题陈述、具体例子、风险显而易见。
方法部分陷入符号泥潭;
一个贯穿的例子会有帮助。
结果部分在数据集之间跳跃,缺乏足够的连接组织——为什么是这四个任务?
它们有什么共同点?
讨论部分是论文本应提升自己的地方:这对未来的基准设计意味着什么?
MMLU应该采用这个框架吗?
相反,它只是重述了结果。
重写讨论以聚焦对基准构建者的启示,会让这成为更强的贡献。
判决: 弱接收 — 对重要问题的扎实贡献,但感觉像两篇论文(方差分解 + 投影优化),各自独立会更强。
实验验证很彻底,但写作没有充分利用洞见。
要点总结
实践者可以偷走方差分解配方:运行小规模试点(50-100个样本),交叉你的设计选择(3-5个提示 × 2-3个评判 × 2-3个温度),拟合层次模型,提取方差成分。
这告诉你不确定性实际来自哪里。
如果你在构建基准,用这个识别可利用的博弈空间——任何高方差的设计选择都是博弈目标,所以通过取平均或集成来锁定它。
如果你在评估模型,用投影优化器高效分配预算——如果提示方差占主导,不要盲目收集更多数据。
覆盖校正的置信区间可以立即使用:只需在模型中包含设计因素作为随机效应,你的置信区间就会实际达到名义覆盖率。
更广泛的教训:把你的评估管道当作测量工具,不是黑盒。
测量它的属性,理解它的误差来源,相应优化。