Paper: 2607.15258 Authors: Arthur G. Bubolz, Abreu Quevedo, Giancarlo Lucca, Rafael A. Berri, Eduardo Borges, Bruno L. Dalmazo Categories: cs.LG, cs.CE
The Gap
Most crypto market analysis papers fall into two camps: (1) social-media-text sentiment classifiers that look at tweets and Reddit posts to gauge mood, or (2) price prediction models using technical indicators and on-chain metrics. The first camp ignores the blockchain’s own signal — the transactions, mining activity, and fund flows that reflect real economic behavior. The second camp predicts a number (price) but doesn’t explain why the market feels a certain way. The gap this paper targets: nobody has systematically fused on-chain behavioral data, financial time-series, and social sentiment into a single sentiment explanation framework with interpretable feature attribution. The prior approaches each see one slice of the elephant. This paper asks: what if we give the model all three slices and let it explain which slice matters for what kind of market emotion?
                         PRIOR LANDSCAPE
                               |
          +--------------------+--------------------+
          |                    |                    |
   Social Media Only    Price Prediction     On-chain Only
   (text sentiment)    (technical signals)   (transaction data)
          |                    |                    |
          v                    v                    v
   Sees tweets,         Sees numbers,        Sees blockchain
   ignores chain        ignores emotion      ignores humans
          |                    |                    |
          +--------------------+--------------------+
                               |
                    G A P : no fusion of
                    all three for sentiment
                    e x p l a n a t i o n
                               |
                               v
                    +---------------------+
                    | This paper's method  |
                    +---------------------+
                               |
                    Assumption: on-chain +
                    financial + social each
                    carry complementary
                    sentiment signal
                               |
                               v
                    Method: normalize all
                    three into one dataset,
                    train XGBoost classifier
                               |
                               v
                    Evidence: 0.84 F1-score,
                    SHAP shows on-chain
                    features contribute
                    meaningfully
                               |
                               v
                    Conclusion: multi-source
                    fusion enriches sentiment
                    classification quality
The Increment
One sentence: Before this paper, crypto sentiment analysis either read the room from tweets alone or predicted prices from charts — after it, we have evidence that the blockchain’s own transaction fingerprint, combined with financial and social signals, produces an interpretable sentiment classifier where you can actually see which features drove each prediction.
Core Mechanism
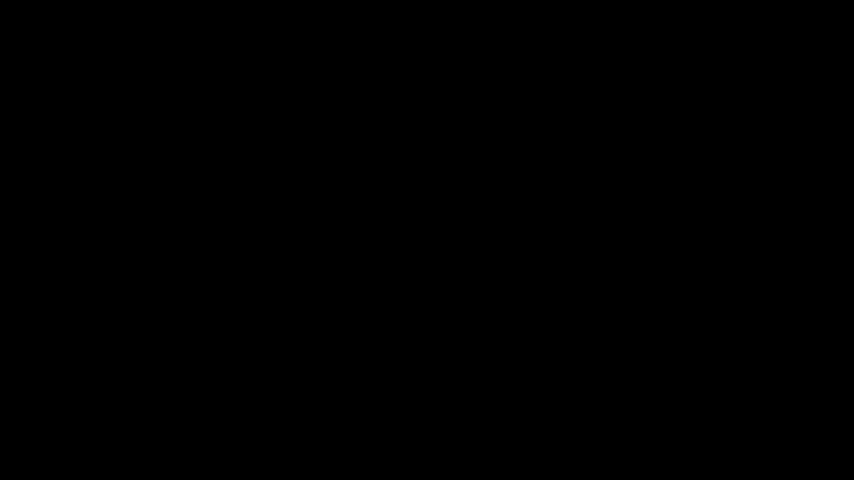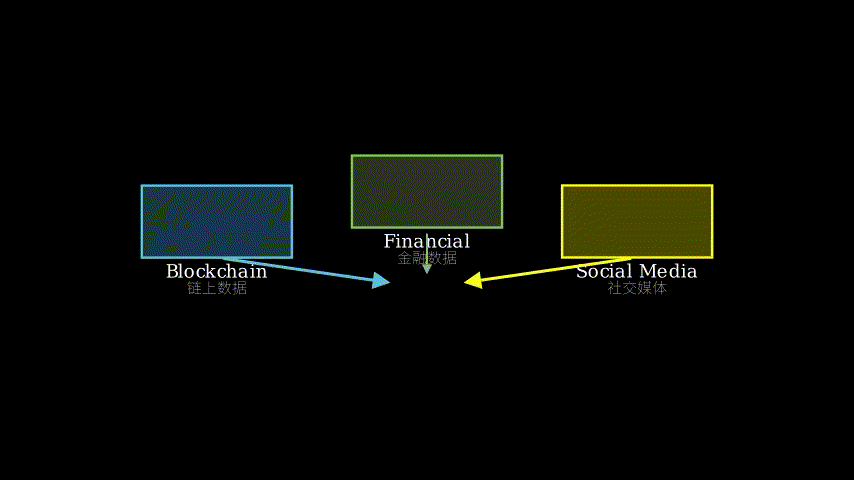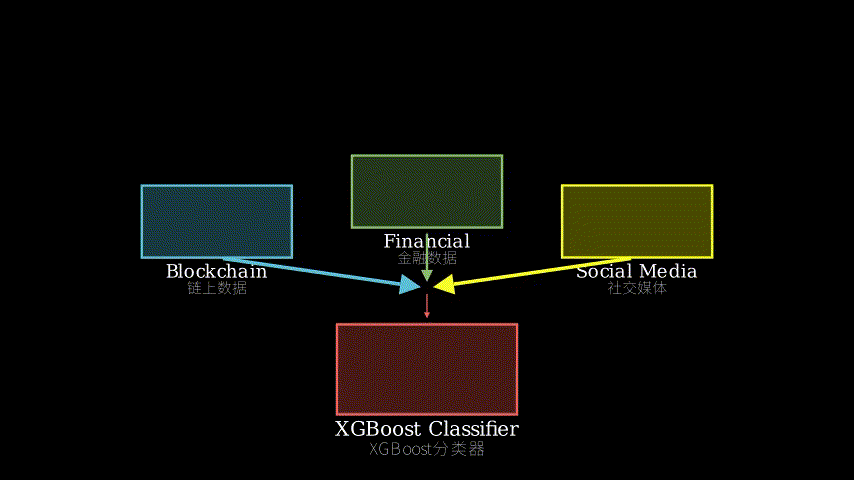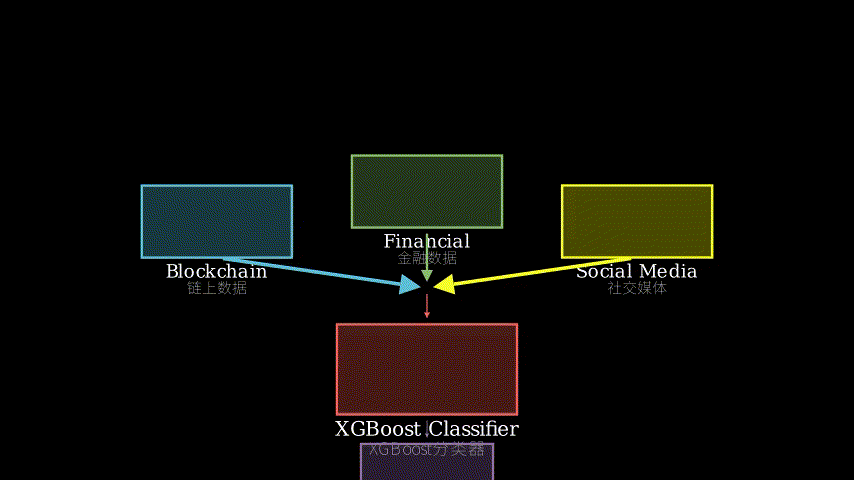
The pipeline has three data ingestion channels feeding into a unified classification system. First, on-chain metrics are collected — things like transaction count, hash rate, active addresses, and network value — these capture the behavioral fingerprint of blockchain participants. Second, financial data (Bitcoin price history, volume, volatility indicators) provides the market’s technical context. Third, daily Twitter sentiment classifications — already labeled as positive, negative, or neutral — supply the social dimension. Each channel produces time-series data at daily granularity.
The three streams are normalized and merged into a single dataset where each row represents one day and each column is a feature from any of the three sources. This flat table becomes the input to the classification stage. Multiple machine learning models were tested with cross-validation — Decision Trees, Random Forests, SVMs, and Gradient Boosting (XGBoost). XGBoost emerged as the winner with an average F1-score of approximately 0.84. After training, SHAP (SHapley Additive exPlanations) was applied to the XGBoost model to decompose each prediction into the contribution of individual features. This tells you not just what the model predicted, but why — which on-chain metric pushed the sentiment toward positive, which financial indicator pulled it negative, and so on.
DATA SOURCES                    PIPELINE
============                    ========

[On-chain metrics]              [Financial data]           [Twitter sentiment]
 transaction count               daily price               labeled posts
 hash rate                       trading volume            pos/neg/neutral
 active addresses                volatility indicators     daily aggregation
 network value
       |                              |                           |
       v                              v                           v
 +-----------+                 +-----------+              +--------------+
 | Normalize |                 | Normalize |              |  Normalize   |
 +-----------+                 +-----------+              +--------------+
       |                              |                           |
       +------------------------------+---------------------------+
                                      |
                                      v
                          +-----------------------+
                          |   Merge into single   |
                          |   feature matrix      |
                          |   (one row per day)   |
                          +-----------------------+
                                      |
                                      v
                          +-----------------------+
                          |  Train ML classifiers |
                          |  (cross-validated)    |
                          |  XGBoost wins: 0.84   |
                          +-----------------------+
                                      |
                                      v
                          +-----------------------+
                          |  SHAP interpretation  |
                          |  per-feature attribution|
                          +-----------------------+
The restaurant kitchen analogy: Imagine you’re running a restaurant and you want to understand *why customers are happy or unhappy on any given day. You have three information streams. The first is the kitchen log — how many orders came in, how busy the stove was, what ingredients were used (that’s on-chain data: the raw activity inside the system). The second is the financial ledger — revenue, average check size, cost fluctuations (that’s price and market data). The third is the customer reviews posted online that night, already tagged as positive or negative (that’s Twitter sentiment).
Before this paper, most food critics (researchers) would only read the online reviews and declare “customers are happy” or “customers are unhappy.” Some would only look at the ledger and predict tomorrow’s revenue. This paper says: let’s combine all three into a single daily report, feed it to a smart analyst (XGBoost), and then use a transparency tool (SHAP) to ask that analyst: “When you said customers were unhappy today, was it because the kitchen was chaotic, because the prices were too high, or because the reviews were brutal?” The kitchen’s chaos — the on-chain metric nobody else was looking at — turns out to carry real signal about customer mood. That’s the insight.
Key Concepts
-
On-chain metrics: Think of Bitcoin’s blockchain as a public diary of every transaction ever made. On-chain metrics are statistics you can compute from this diary — like counting how many unique people wrote in it today (active addresses), how many entries were made (transaction count), or how much computing power was guarding the diary (hash rate). These metrics don’t come from human opinions; they come from the actual economic activity on the network. If hash rate suddenly drops, miners are leaving. If active addresses spike, lots of people are transacting. These are behavioral facts, not vibes.
-
SHAP (SHapley Additive exPlanations): Imagine you and three friends cook a meal together, and it tastes amazing. SHAP answers: “How much of the amazingness did each person contribute?” It borrows from cooperative game theory — specifically, the idea that you should credit each player by measuring how the outcome changes when they join or leave every possible coalition. In a machine learning model, SHAP does the same for each feature: it measures how much each feature (hash rate, tweet sentiment, price volatility) pushed the prediction up or down for a specific day. The result is a transparent breakdown: “Today’s sentiment was classified as positive, and here’s the receipt — on-chain activity contributed +0.3, Twitter contributed +0.1, but price volatility dragged it down by -0.15.”
-
F1-score: If you’re classifying something into categories (positive vs. negative sentiment), you care about two things: not missing real positives (recall) and not falsely labeling things as positive (precision). F1-score is the harmonic mean of these two — it punishes you harshly if either one is bad. A score of 0.84 means the model is reasonably good at both catching true sentiment and not hallucinating false ones. It’s not perfect (1.0), but for a noisy domain like crypto sentiment, it’s a solid result.
Framework Shift
Before (mainstream approach):           After (this paper):

  [Social text]                         [On-chain] [Financial] [Social text]
       |                                     |          |           |
       v                                     v          v           v
  [NLP sentiment]                          [Normalize + Merge]
       |                                     |
       v                                     v
  "Tweet says bullish"                  [XGBoost classifier]
       |                                     |
       v                                     v
  (no chain context)                    [SHAP explanation]
                                        "On-chain X pushed
                                         sentiment toward
                                         positive by +0.3"

  Single-source input                   Multi-source fusion
  Black-box or no model                 Interpretable model
  Prediction or description             Explanation of sentiment
From single-source sentiment reading to multi-source sentiment explanation, the core shift is treating the blockchain itself as a participant whose behavior speaks alongside human tweets and market prices.
Expert Assessment
Problem choice: The gap is real but not razor-sharp. Combining on-chain and off-chain signals for crypto analysis isn’t entirely new — some portfolio management and trading signal papers have done similar fusions. The distinct angle here is framing it as *sentiment explanation rather than price prediction, and adding SHAP for interpretability. It sits at a natural intersection that hasn’t been deeply explored, so the positioning is reasonable, though the novelty ceiling is moderate. This is more of a “connect the dots” contribution than a breakthrough.
Method matureness: The method is competent but conservative. XGBoost is a fine choice, but it’s also the default choice for tabular data in 2024-2025 — there’s no surprising model selection insight here. SHAP is also well-established. The real workhorse is the data fusion and normalization step, but the paper doesn’t spend enough time justifying *why these particular on-chain features were selected or how normalization choices affect results. Simpler approaches like logistic regression with SHAP would have been a valuable ablation to show XGBoost’s lift isn’t marginal. The authors mention deep learning as future work, but even a simple attention-based model could have been tested now.
Experimental integrity: This is where I have the most concern. The F1-score of 0.84 is reported without clear comparison to strong baselines — what would a naive classifier or a sentiment-only model achieve on the same data? Cross-validation is used, but the paper doesn’t describe how temporally structured the splits are (time-series leakage is a constant risk in financial data — if validation data comes before training data chronologically, the score is meaningless). The abstract says “about 0.84” which raises questions about variance across folds. No confidence intervals, no statistical significance tests. The SHAP analysis is valuable but presented as post-hoc validation rather than a rigorous ablation.
Writing quality: The abstract is well-structured and readable, but the paper as described seems to cut corners on the most important section: experimental methodology. The data preprocessing and normalization pipeline — arguably the core contribution — likely deserves far more space than it gets. If the authors rewrote the methods section with the rigor of a data engineering paper (reproducibility details, normalization sensitivity, temporal validation), the whole paper would gain an order of magnitude more credibility.
Verdict: weak accept — The multi-source fusion idea for sentiment *explanation is a worthwhile direction, and SHAP adds genuine transparency value, but the experimental rigor needs tightening and the novelty is incremental rather than transformative.
Takeaways
Three concrete things a practitioner can steal:
-
Multi-source feature fusion as a general pattern: The idea of combining behavioral traces (on-chain), financial indicators (prices), and human-generated signals (social text) into a single classifier applies far beyond crypto. Any domain with a digital substrate (supply chains, IoT networks, digital health) has “on-chain-equivalent” behavioral data that’s underexploited alongside traditional metrics.
-
SHAP as a communication tool, not just a technical tool: Using SHAP to make a classifier’s reasoning visible is not new, but the paper demonstrates a useful framing — SHAP receipts that show “here’s exactly which signals mattered today.” For any stakeholder-facing ML system, this pattern of per-instance explanation is directly transferable.
-
Sentiment explanation vs. sentiment prediction as a framing choice: Reframing the task from “predict the next price” to “explain today’s mood” is a subtle but powerful reorientation. It lowers the performance bar (explanation is more forgiving than prediction), increases interpretability expectations, and produces outputs that are more actionable for humans. If your stakeholders ask “why?” more than “how much?”, this framing is worth adopting.
论文: 2607.15258 作者: Arthur G. Bubolz, Abreu Quevedo, Giancarlo Lucca, Rafael A. Berri, Eduardo Borges, Bruno L. Dalmazo 分类: cs.LG, cs.CE
缺口
加密货币市场分析的研究大致分两个阵营:一是社交媒体文本情感分类器,盯着推特和 Reddit 帖子来判断市场情绪;二是价格预测模型,用技术指标和链上指标来预测未来价格走势。 前者忽略了区块链自身的行为信号——交易笔数、挖矿活动、资金流动,这些都是真实的经济行为痕迹。 后者能预测一个数字(价格),但解释不了市场为什么呈现出某种情绪。
这篇论文瞄准的缺口是:没有人系统地把链上行为数据、金融时间序列和社交情感融合成一个统一的情感解释框架,并附带可解释的特征归因。 之前的方法各看到大象的一条腿。这篇论文问:如果我们把三条腿都交给模型,让它解释哪条腿对应哪种市场情绪,会怎样?
                      先前研究图景
                           |
       +-------------------+-------------------+
       |                   |                   |
  仅社交媒体           仅价格预测          仅链上数据
  (文本情感)         (技术指标)          (交易数据)
       |                   |                   |
       v                   v                   v
  看见推文            看见数字            看见区块链
  忽略链上            忽略情绪            忽略人类
       |                   |                   |
       +-------------------+-------------------+
                           |
                 缺 口 :三者未融合
                 用于情感解释
                           |
                           v
                 +--------------------+
                 | 本文的方法         |
                 +--------------------+
                           |
                 假设:链上+金融+社交
                 各自携带互补的情感信号
                           |
                           v
                 方法:归一化后合并
                 用 XGBoost 分类器
                           |
                           v
                 证据:F1 约 0.84,
                 SHAP 显示链上特征
                 贡献显著
                           |
                           v
                 结论:多源融合提升
                 情感分类质量
增量
一句话:在此之前,加密情感分析要么只读推文,要么只看图表来预测价格——在此之后,我们有了证据表明,区块链自身的交易指纹、加上金融和社交信号,能产生一个可解释的情感分类器,让你真正看到是哪些特征驱动了每次预测。
核心机制
整个流水线有三个数据入口,汇入一个统一的分类系统。 第一个通道采集链上指标——交易笔数、哈希率、活跃地址数、网络价值等——这些捕获了区块链参与者的行为指纹。 第二个通道提供金融数据(比特币价格历史、交易量、波动率指标),给出市场的技术上下文。 第三个通道是每日推特情感分类——已经标注为正面、负面或中性——提供社交维度。 三个通道都产出以天为粒度的时间序列数据。
三条数据流经过归一化后合并成一张数据表,每一行代表一天,每一列是来自任意通道的特征。 这张扁平表格就是分类阶段的输入。 多个机器学习模型在交叉验证下测试——决策树、随机森林、SVM 和梯度提升(XGBoost)。 XGBoost 以平均 F1 分数约 0.84 胜出。 训练完成后,将 SHAP 应用于 XGBoost 模型,把每个预测分解为各个特征的贡献。 这样你不仅知道模型预测了什么,还知道为什么——哪个链上指标把情绪推向正面,哪个金融指标把它拉向负面。
数据源                        流水线
======                        ======

[链上指标]              [金融数据]              [推特情感]
 交易笔数                每日价格               已标注帖子
 哈希率                  交易量                 正面/负面/中性
 活跃地址                波动率指标             每日汇总
 网络价值
     |                       |                       |
     v                       v                       v
 +-------+             +-------+              +----------+
 | 归一化 |             | 归一化 |              |  归一化   |
 +-------+             +-------+              +----------+
     |                       |                       |
     +-----------------------+-----------------------+
                             |
                             v
                 +------------------------+
                 |   合并为统一特征矩阵   |
                 |   (每天一行)         |
                 +------------------------+
                             |
                             v
                 +------------------------+
                 |  训练 ML 分类器        |
                 | (交叉验证)           |
                 | XGBoost 胜出:0.84    |
                 +------------------------+
                             |
                             v
                 +------------------------+
                 |  SHAP 可解释性分析     |
                 |  逐特征归因           |
                 +------------------------+
餐厅后厨的比喻:想象你在经营一家餐厅,想知道每天顾客高兴或不高兴的**原因*。你有三个信息来源。第一个是后厨日志——今天接了多少单、灶台有多忙、用了什么食材(这就是链上数据:系统内部的原始活动量)。第二个是财务账本——营收、人均消费、成本波动(这就是价格和市场数据)。第三个是当晚顾客在网上发的点评,已经标好了好评或差评(这就是推特情感)。
在这篇论文之前,大多数美食评论家(研究者)只读网上点评就说”顾客满意”或”顾客不满意”。有些人只看账本来预测明天的营收。这篇论文说:把三个信息源合并成一份每日报告,交给一个聪明的分析师(XGBoost),然后用一个透明度工具(SHAP)去问这个分析师:“你说今天顾客不满意,是因为后厨太乱,还是因为价格太高,还是因为点评很差?“后厨的混乱——那个没人看的链上指标——居然真的携带了关于顾客情绪的有效信号。这就是核心洞察。
关键概念
-
链上指标:把比特币的区块链想象成一本公开日记,记录了每一笔交易。链上指标就是你从这本日记里算出来的统计量——比如今天有多少不同的人写了日记条目(活跃地址数)、写了多少条(交易笔数)、或者有多少算力在守护这本日记(哈希率)。这些指标不来自人的观点,而来自网络上实际的经济活动。如果哈希率突然下降,说明矿工在撤退。如果活跃地址数激增,说明大量用户在交易。这些是行为事实,不是情绪。
-
SHAP(SHapley 可加解释):想象你和三个朋友一起做饭,做出来的菜非常好吃。SHAP 回答的问题是:“好吃这件事里,每个人贡献了多少?“它借鉴了合作博弈论的思路——通过测量每个玩家加入或离开每种可能的组合时结果如何变化来分配功劳。在机器学习模型里,SHAP 对每个特征做同样的事:它测量每个特征(哈希率、推文情感、价格波动率)在某一天把预测往上推了多少或往下拉了多少。结果是一张透明的账单:“今天的情感被分类为正面,这里是明细——链上活动贡献了 +0.3,推特贡献了 +0.1,但价格波动拉低了 -0.15。”
-
F1 分数:如果你在做分类(正面 vs 负面情感),你关心两件事:别漏掉真正的正面案例(召回率),别把不是正面的也标成正面(精确率)。F1 分数是这两个指标的调和平均——如果任何一个太差,它会严厉惩罚你。0.84 的分数意味着模型在捕捉真实情感和不乱标之间取得了不错的平衡。不是满分(1.0),但在加密情感这种噪声很大的领域,这是一个扎实的结果。
框架转变
之前(主流方法):                  之后(本文方法):

  [社交文本]                      [链上] [金融] [社交文本]
     |                               |      |       |
     v                               v      v       v
  [NLP 情感]                      [归一化 + 合并]
     |                               |
     v                               v
 "推文说看涨"                    [XGBoost 分类器]
     |                               |
     v                               v
 (无链上下文)                  [SHAP 解释]
                                 "链上 X 将情感
                                  推向正面 +0.3"

  单源输入                        多源融合
  黑箱或无模型                    可解释模型
  预测或描述                      情感归因解释
从单源情感阅读到多源情感解释,核心转变是把区块链本身视为一个参与者,它的行为与人类推文和市场价格一起说话。
专家评审
选题眼光:缺口真实存在,但边界不够锋利。将链上和链外信号融合用于加密分析并非全新——一些投资组合管理和交易信号论文做过类似的事。这篇论文的独特角度是把它定位为**情感解释而非价格预测*,并加入 SHAP 做可解释性。它处在一个尚未被深入探索的自然交叉点上,定位合理,但新颖性上限中等。更像”连线题”贡献,而非突破性成果。
方法成熟度:方法称职但保守。XGBoost 是个不错的选择,但也是 2024-2025 年表格数据的默认选择——模型选择上没有令人意外的洞见。SHAP 同样是成熟工具。真正的核心工作在于数据融合和归一化步骤,但论文没有花足够篇幅论证**为什么*选了这些特定的链上特征,或者归一化方式如何影响结果。用逻辑回归加 SHAP 做消融实验本应是必要的对照——以此展示 XGBoost 的提升不是微乎其微。作者提到深度学习作为未来工作,但即使是简单的注意力模型现在也可以测试。
实验诚意:这是我最关注的地方。0.84 的 F1 分数没有明确与强基线比较——同一个数据集上,朴素分类器或仅用情感的模型能得多少?用了交叉验证,但没有清楚说明分割方式是否具有时序性(时间序列泄漏在金融数据中是持续风险——如果验证数据在训练数据之前,分数就毫无意义)。摘要写”约 0.84”,让人质疑各折之间的方差。没有置信区间,没有统计显著性检验。SHAP 分析有价值,但被呈现为事后验证而非严格的消融实验。
写作功力:摘要结构清晰、可读性强,但论文似乎在最重要的部分——实验方法论——偷工减料。数据预处理和归一化流水线(可以说是核心贡献)理应得到比实际更多的篇幅。如果作者以数据工程论文的严谨度重写方法部分(可复现性细节、归一化敏感性、时序验证),整篇论文的可信度会提升一个数量级。
判决:弱接收——多源融合用于情感**解释*是一个有价值的方向,SHAP 增加了真正的透明度价值,但实验严谨性需要加强,创新是渐进式的而非变革性的。
要点总结
实践者可以从这篇论文”偷”走三样具体的东西:
-
多源特征融合作为通用模式:将行为痕迹(链上)、金融指标(价格)和人类生成的信号(社交文本)融合进一个分类器的想法,远超加密货币的范畴。任何有数字基底的领域(供应链、物联网、数字健康)都有”链上等价”的行为数据,与传统指标一起被严重低估了。
-
SHAP 作为沟通工具,而不仅仅是技术工具:用 SHAP 让分类器的推理可见并非新事,但论文展示了一个有用的叙事框架——“SHAP 账单”,表明”今天是这些信号在起作用”。对于任何面向利益相关者的机器学习系统,这种逐实例解释的模式都可以直接迁移。
-
情感解释 vs. 情感预测作为框架选择:把任务从”预测下一个价格”重新定位为”解释今天的情绪”,是一个微妙但有力的转向。它降低了性能门槛(解释比预测更宽容),提高了解释性的期望,产出对人类更具可操作性。如果你的利益相关者问”为什么”比问”多少”更多,这个框架值得采用。