Paper: 2606.19319 Authors: Anoushka Vyas, Aarushi Dhanuka, Sina Khoshfetrat Pakazad, Henrik Ohlsson Categories: cs.MA, cs.AI, cs.DB
The Gap
Existing data integration in production pipelines relies on a serial handoff: data owners describe schemas to engineers who write ETL scripts, then analysts craft SQL queries. Tools like data catalogs and LLM-based assistants (e.g., SQL-Copilot, DAIL-SQL) have reduced some friction, but they still operate on a generate-then-approve cycle where the artifact (schema, query) is text that must be manually validated and adjusted. The key limitation: these systems have no internal mechanism to execute the generated code, observe failures, and repair errors autonomously. Human bottlenecks remain for every edge case. This paper identifies that gap and proposes an architecture where agents not only generate code but also execute it, evaluate correctness, and iterate—treating the code as a first-class executable object rather than a static text.
[ASCII logic topology]
Problem: Data integration bottleneck from repeated human handoffs
    |
    v
Assumption: LLM can generate correct code if given good prompts
    |
    +---< Prior work: text-only generation, no execution feedback
    |
    v
Paper's method: Agents that generate, execute, validate, repair code
    |
    v
Evidence: 7 SQL benchmarks across 4 dialects, matches/surpasses SOTA
    |
    v
Conclusion: Execution-grounded ACAs + shared memory generalize across data intelligence tasks
The Increment
One sentence: Before this paper, data integration agents could only propose code; after this paper, agents can execute code, catch errors, and fix themselves—then reuse that experience across future tasks.
Core Mechanism
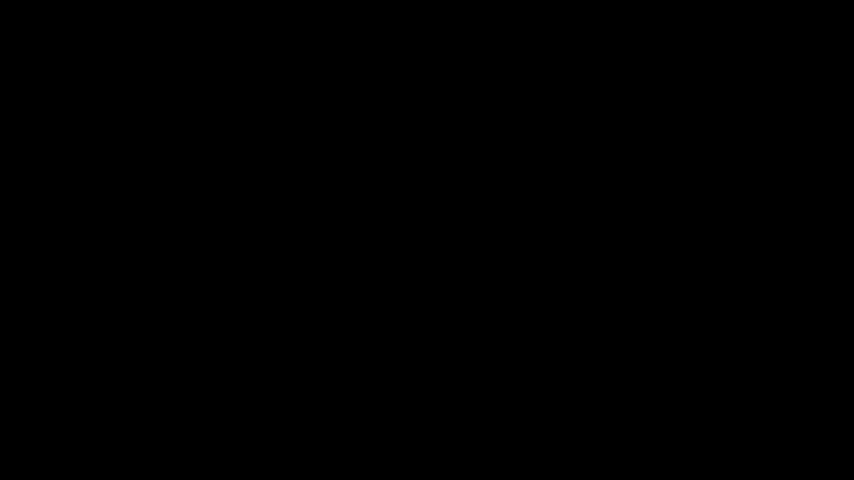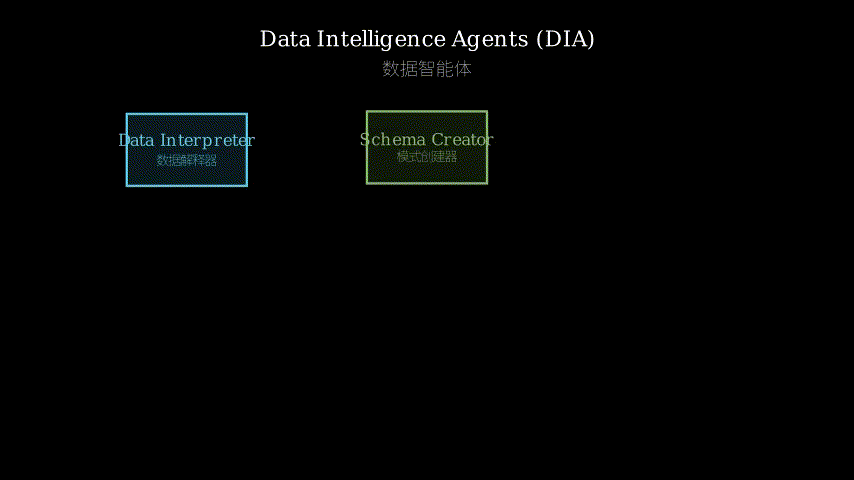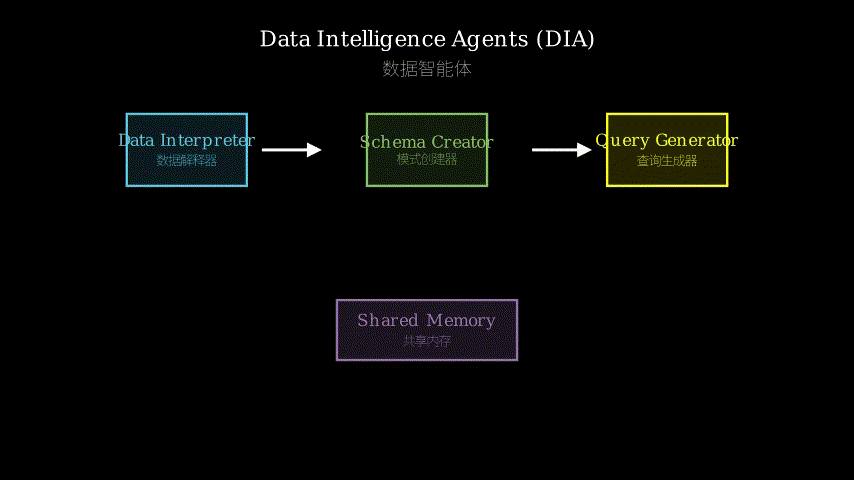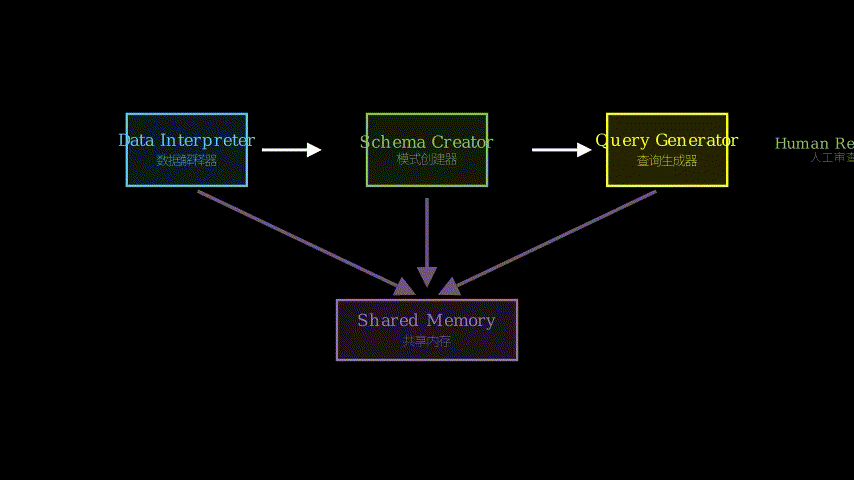
The system (DIA) comprises three specialized agents: Data Interpreter (reads raw files and outputs structured descriptions), Schema Creator (infers and formalizes a schema), and Query Generator (writes and validates SQL queries). Each agent is built on top of an Autonomous Coding Agent (ACA). An ACA operates in a loop: (1) receive a natural-language instruction, (2) generate code (Python or SQL), (3) execute it in a sandbox, (4) capture execution results and errors, (5) if errors or incorrect results, repair the code and repeat, (6) once correct, store both the code and the execution trace into a shared memory. The shared memory acts as an experience database: future agents can retrieve past successes and failures for similar tasks, reducing trial and error. The Query Generator is studied in depth; it uses this loop plus retrieval from shared memory to produce SQL queries that are syntactically and semantically correct.
                      [ASCII diagram of method internals]
  User -> NL instruction
        |
        v
  [Shared Memory] <-----> [ACA core loop]
        ^                    |
        |                    v
        |              [Generate code]
        |                    |
        |                    v
        |              [Execute (sandbox)]
        |                    |
        |                    +---[Success]--> Store trace
        |                    |
        |                    v
        |              [Catch error]
        |                    |
        +---[Retrieve]---> [Repair code] <-- loop back
Here’s the structural metaphor: think of the ACA loop as a tireless apprentice cook working in a kitchen. The apprentice receives a recipe (natural-language instruction). First, they select ingredients (generate code). Then they cook a small test batch (execute in sandbox). If the taste is off or the dish burns (error or wrong output), they adjust the ingredients or technique (repair code). Once the test batch is perfect, they write down the exact process and store it in a shared recipe book (shared memory). The next time someone asks for a similar dish, the apprentice can look up the recipe book instead of starting from scratch. The three agents (Interpreter, Schema Creator, Query Generator) are like three different stations in the kitchen—each apprentice specializes in a different part of the meal, but they all share the same recipe book. The crucial point: the apprentice actually cooks, tastes, and corrects. That’s what makes this system different from a cook who just describes what they *would do.
Key Concepts
-
Autonomous Coding Agent (ACA): An LLM-based loop that not only generates code but also executes it, observes the outcome, and self-corrects. It is not a one-shot generator. Example: given “Write a SQL query to find the top 5 customers by total revenue in 2025”, the ACA generates a query, runs it against a test database, sees an error “column ‘revenue’ does not exist”, checks the schema, rewrites using ‘amount’, re-runs, gets a result with 10 rows, filters to top 5, and finally stores the correct query. Without execution, you’d have to manually catch the column name mistake.
-
Shared Memory: A persistent store of (instruction, code, execution trace, outcome) triples. It enables experience reuse across agents and tasks. Example: after the Schema Creator has inferred a schema for a dataset, that schema is stored. When the Query Generator later needs to write a query on the same dataset, it retrieves the schema from memory instead of re-inferring it, saving time and reducing errors. The memory is indexed by natural-language similarity so agents can find relevant past examples.
-
Execution-grounded code generation: The principle that generated code is only considered correct if it produces the expected result when run. This contrasts with “text-grounded” approaches where correctness is evaluated by human review or abstract metrics (like BLEU). In practice, it means the agent can catch subtle errors like type mismatches, empty results due to incorrect joins, or performance issues (by checking execution time). The paper shows this leads to higher accuracy on SQL benchmarks.
Framework Shift
Before (mainstream approach):        After (this paper):
Human describes task                Human describes task
    |                                   |
    v                                   v
LLM generates code (text)           ACA generates code
    |                                   |
    v                                   v
Human reviews and edits              ACA executes code
    |                                   |
    +---[iterate manually]               +---[error?]--> repair loop
    |                                   |
    v                                   v
Final code stored (static)           Code + trace stored in shared memory
    |                                   |
    v                                   v
Next task: repeat from scratch       Next task: retrieve similar experience
One sentence: From text-only code generation with manual validation to execution-grounded, self-repairing code generation with experience reuse, the core shift is making code a live, testable artifact rather than a frozen proposal.
Expert Assessment
Problem choice: Real gap. The handoff problem in data integration is painful in every enterprise. The paper targets a practical bottleneck, not a fabricated one. It sits at the intersection of “AI for data” and “agentic systems”, a hot area where many papers propose ideas but few validate in production.
Method maturity: Clever insight—execution feedback with shared memory is obvious in hindsight but underexplored in data integration. The implementation appears solid: sandbox execution, repair loop, memory retrieval. However, the approach is computationally expensive: each query goes through multiple execute-repair cycles, and memory retrieval adds overhead. Simpler alternatives like fine-tuning a specialized LLM on SQL benchmarks might achieve similar accuracy without the loop, but the paper’s advantage is adaptability to new dialects and schemas without retraining.
Experimental integrity: Fair baselines—they compare against well-known methods like DAIL-SQL, DIN-SQL, and others on seven benchmarks (Spider, Bird, etc.). The results show matching or surpassing SOTA on all. One red flag: the evaluation is only on the Query Generator, not the full DIA system (Data Interpreter and Schema Creator are not benchmarked). Also, the “fully autonomous mode” means no human feedback, which is good for reproducibility but may not reflect production where a human can intervene. The shared memory component is not isolated in ablations to quantify its contribution; it’s always present.
Writing quality: Clear, well-structured. The paper is long but readable. The authors cut corners in the related work section—it’s a list of prior work without deep comparison. The section that could elevate the whole paper is a dedicated ablation study showing the contribution of execution feedback vs. shared memory vs. baseline LLM. That would make the architecture’s necessity undeniable.
Verdict: weak accept — Solid practical contribution with strong empirical results, but the novelty is incremental (execution + memory) and the evaluation leaves some questions about component-level impact. Worth attention if you build data tools; less so if you study theoretical AI.
Takeaways
- Execution sandbox as a core agent component: If you’re building any code-generating agent, adding a sandbox to run and validate the generated code is a cheap way to boost reliability. Don’t let the LLM hallucinate silently—let it crash and fix.
- Experience reuse via shared memory: Store not just the final code but the full trace (inputs, errors, corrections). This turns the agent into a learning system that gets cheaper over time. For practitioners, this means you can start with a generic LLM and let the memory specialize to your domain.
- Separate agents for separate concerns: The paper decomposes the problem into interpretation, schema, query. This modularity makes each agent simpler and easier to debug. In your own system, consider breaking a complex task into sub-agents with clear interfaces.
论文: 2606.19319 作者: Anoushka Vyas, Aarushi Dhanuka, Sina Khoshfetrat Pakazad, Henrik Ohlsson 分类: cs.MA, cs.AI, cs.DB
缺口
现有数据集成在生产管线中依赖串行交接:数据所有者描述模式,工程师编写ETL脚本,分析师再撰写SQL查询。数据目录和基于LLM的助手(如SQL-Copilot、DAIL-SQL)减少了一些摩擦,但它们仍然运行在“生成-审批”循环中,生成的工件(模式、查询)是文本,必须人工验证和调整。关键限制:这些系统没有内部机制来执行生成的代码、观察失败并自主修复错误。每个边界情况仍需人类介入。这篇论文识别了这一缺口,并提出一种架构,其中智能体不仅能生成代码,还能执行、评估正确性并迭代——将代码视为一级可执行对象而非静态文本。
[ASCII 逻辑拓扑图]
问题:反复人工交接导致的数据集成瓶颈
    |
    v
假设:若提示词得当,LLM能生成正确代码
    |
    +---< 前期工作:纯文本生成,无执行反馈
    |
    v
本文方法:智能体能生成、执行、验证、修复代码
    |
    v
证据:在7个SQL基准测试(4种方言)上匹配或超越最佳结果
    |
    v
结论:基于执行的ACAs + 共享记忆泛化到多种数据智能任务
增量
一句话: 这篇论文之前,数据集成智能体只能提出代码;之后,智能体可以执行代码、捕捉错误并自行修复,还能将经验复用于未来的任务。
核心机制
该系统(DIA)包含三个专门智能体:数据解释器(读取原始文件并输出结构化描述)、模式创建器(推断并形式化模式)和查询生成器(编写并验证SQL查询)。每个智能体都构建在自主编码体(ACA)之上。ACA运行在一个循环中:(1) 接收自然语言指令,(2) 生成代码(Python或SQL),(3) 在沙盒中执行,(4) 捕获执行结果和错误,(5) 若出错或结果不正确则修复代码并重复,(6) 正确后,将代码和执行跟踪存入共享记忆。共享记忆充当经验数据库:未来智能体可以检索类似任务的历史成功和失败,减少试错。论文重点研究了查询生成器,它使用该循环加上从共享记忆中检索,生成语法和语义正确的SQL。
                      [ASCII 方法内部图]
  用户 -> 自然语言指令
        |
        v
  [共享记忆] <-----> [ACA 核心循环]
        ^                    |
        |                    v
        |              [生成代码]
        |                    |
        |                    v
        |              [执行(沙盒)]
        |                    |
        |                    +---[成功]--> 存储跟踪
        |                    |
        |                    v
        |              [捕捉错误]
        |                    |
        +---[检索]-------> [修复代码] <-- 循环返回
这里用一个结构性比喻:把ACA循环想象成一位永不疲倦的学徒厨师在厨房里工作。学徒收到一份菜谱(自然语言指令)。首先,他挑选食材(生成代码)。然后他做一小批试验(在沙盒中执行)。如果味道不对或菜烧焦了(错误或错误输出),他调整食材或技巧(修复代码)。一旦试验品完美,他将确切的过程写下来,存入共享菜谱(共享记忆)。下次有人问类似的菜,学徒可以查阅菜谱,而不必从头开始。三个智能体(解释器、模式创建器、查询生成器)就像厨房里的三个不同工位——每个学徒专攻菜品的一个部分,但他们共享同一本菜谱。关键点是:学徒确实做菜、试吃、纠正。这使该系统不同于那些只描述自己**应该*怎么做的厨师。
关键概念
-
自主编码体 (ACA): 基于LLM的循环,不仅生成代码,还执行代码、观察结果并自我纠正。它不是一次性生成器。例如:给定“写一条SQL查询找出2025年总收入前5的客户”,ACA生成查询,对测试数据库执行,看到错误“列’revenue’不存在”,检查模式,用’amount’重写,重新执行,得到10行的结果,再过滤出前5,最后存储正确的查询。如果没有执行,你就得手动捕捉列名错误。
-
共享记忆: 存储(指令、代码、执行跟踪、结果)三元素组的持久化仓库。它使得经验和任务可以在不同智能体间复用。例如:模式创建器推断出某个数据集的模式后,该模式被存储。之后查询生成器需要对同一数据集编写查询时,它从记忆中检索该模式,而不用重新推断,既节省时间又减少错误。记忆通过自然语言相似性索引,智能体可以找到相关的历史例子。
-
基于执行的代码生成: 原则是生成的代码只有在运行后产生预期结果时才被认为是正确的。这与“基于文本”的方法形成对比,后者通过人工审查或抽象指标(如BLEU)评估正确性。在实践中,这意味着智能体可以捕捉微妙的错误,如类型不匹配、由不正确联接导致的空结果,或性能问题(通过检查执行时间)。论文显示这提高了SQL基准测试的准确性。
框架转变
之前(主流方法):                之后(本文方法):
人类描述任务                     人类描述任务
    |                                  |
    v                                  v
LLM生成代码(文本)               ACA生成代码
    |                                  |
    v                                  v
人类审查和修改                    ACA执行代码
    |                                  |
    +---[手动迭代]                      +---[出错?]-->修复循环
    |                                  |
    v                                  v
最终代码存储(静态)             代码+跟踪存入共享记忆
    |                                  |
    v                                  v
下一个任务:从头开始              下一个任务:检索类似经验
一句话:从纯文本代码生成+人工验证到基于执行的、自我修复的代码生成+经验复用,核心转变是让代码成为活的、可测试的工件,而不是冻结的提案。
专家评审
选题眼光: 真缺口。数据集成中的交接问题在每个企业都很痛苦。论文瞄准了实际问题,不是人造的。它处于“AI for data”和“智能体系统”的交汇点,这是热门领域,但许多论文只提想法,很少在生产中验证。
方法成熟度: 巧劲——执行反馈+共享记忆事后看起来显而易见,但在数据集成中尚未充分探索。实现似乎扎实:沙盒执行、修复循环、记忆检索。然而,该方法计算开销大:每个查询要经过多次执行-修复循环,记忆检索也有额外成本。更简单的替代方案如对SQL基准微调专用LLM可能在没有循环的情况下达到相近的准确性,但论文的优势在于无需重新训练即可适应新的方言和模式。
实验诚意: 基线公平——他们与DAIL-SQL、DIN-SQL等已知方法在七个基准测试(Spider, Bird等)上比较。结果在所有测试上匹配或超越最佳。一个值得警惕之处:评估只针对查询生成器,没有评估完整的DIA系统(数据解释器和模式创建器未经基准测试)。另外,“完全自主模式”意味着没有人工反馈,这对可重复性有好处,但可能不能反映有人类干预的生产环境。共享记忆组件没有通过消融实验来量化其贡献——它总是存在。
写作功力: 清晰,结构良好。论文较长但可读。作者在相关工作部分偷懒了——只是一个列表,没有深入比较。如果能重写,应该加入专门的消融实验,展示执行反馈、共享记忆与基线LLM各自的贡献。这会让架构的必要性变得无法辩驳。
判决: 弱接收 — 扎实的实践贡献,实证结果强,但新颖性增量(执行+记忆),评估留下一些关于组件层面影响的疑问。如果你构建数据工具,值得关注;如果你研究理论AI,则不那么重要。
要点总结
- 执行沙盒作为核心智能体组件: 如果你在构建任何代码生成智能体,添加一个沙盒来运行和验证生成的代码是提高可靠性的廉价方法。不要让LLM静默地胡编——让它出错并修复。
- 通过共享记忆复用经验: 不仅存储最终代码,还要存储完整的跟踪(输入、错误、修正)。这将智能体变成一个学习系统,随着时间推移成本越来越低。对实践者来说,这意味着你可以从通用LLM开始,让记忆专门化到你的领域。
- 为不同关切分离智能体: 论文将问题分解为解释、模式、查询。这种模块化使每个智能体更简单、更易调试。在你自己的系统中,考虑将一个复杂任务分解为具有清晰接口的子智能体。