Paper: 2603.14957 Authors: Xiaojun Shan, Haoyu Shen, Yucheng Mao, Xiang Zhang, Abhay Anand, Bingnan Li, Haiyang Xu, Zhuowen Tu Categories: cs.CV
The Gap
Existing vision foundation models split the world in two: perception models (CLIP, LLaVA) understand images but can’t generate them, while generative models (Stable Diffusion, DALL-E) create images but lack deep understanding. This architectural divorce creates three problems: (1) you need separate training pipelines and datasets for each capability, (2) the models can’t reason about their own outputs (a generator can’t critique what it just made), and (3) you can’t leverage synthetic data for self-improvement because there’s no feedback loop.
Prior unification attempts like Unified-IO and Chameleon bolt together separate encoder-decoder modules, but they’re still fundamentally modular—the understanding and generation pathways don’t share the same computational substrate. CyCLeGen argues that true unification requires a single autoregressive backbone where both tasks emerge from the same weights, connected by cycle-consistent loops that enforce mutual supervision.
Problem: Perception =/= Generation (separate models, no introspection)
    |
    v
Assumption: Unified architecture + cycle consistency = mutual improvement
    |
    v
Method: Single autoregressive model with image<->layout bidirectional loops
    |
    v
Evidence: Gains on both understanding (VQA, captioning) and generation (FID, layout)
    |
    v
Conclusion: Cycle consistency enables self-supervised improvement in unified models
The Increment
One sentence: Before CyCLeGen, you needed separate models for seeing and creating; after, a single model does both and improves itself by checking if image→layout→image reconstructs consistently.
Core Mechanism
CyCLeGen uses one autoregressive transformer that processes both images and layouts as token sequences. Images get tokenized into discrete codes (via a learned VQ-VAE), layouts are structured text (bounding boxes + labels), and the model learns to translate bidirectionally between them.
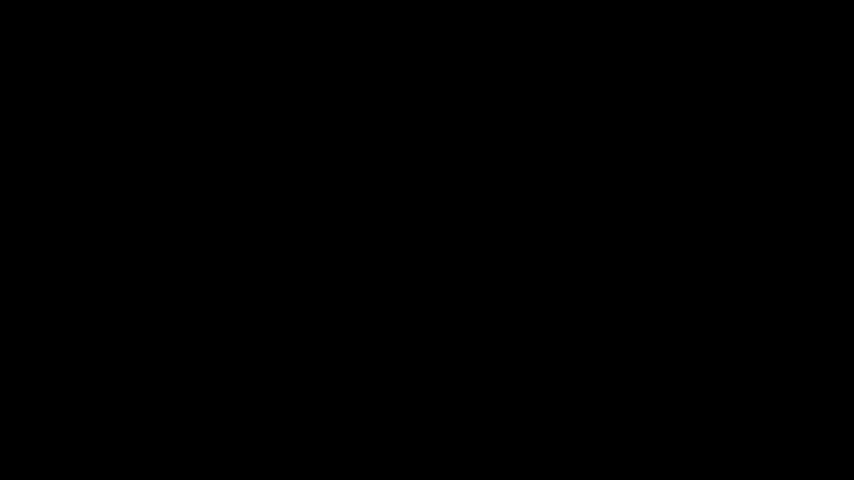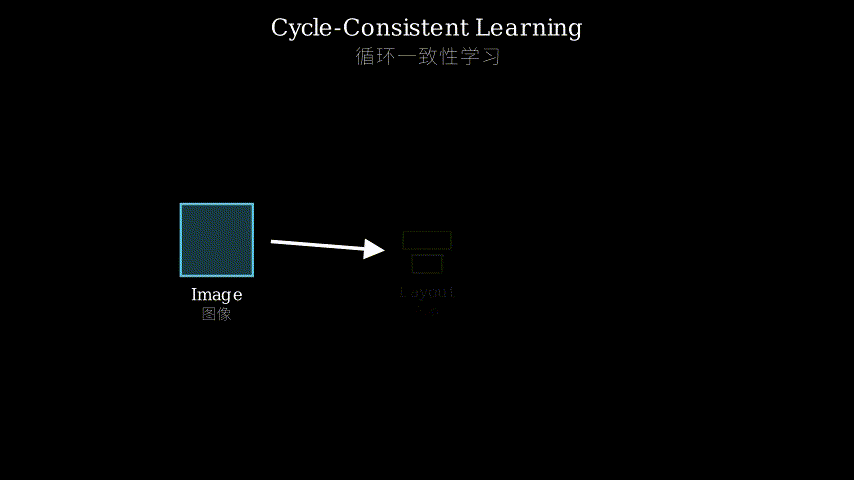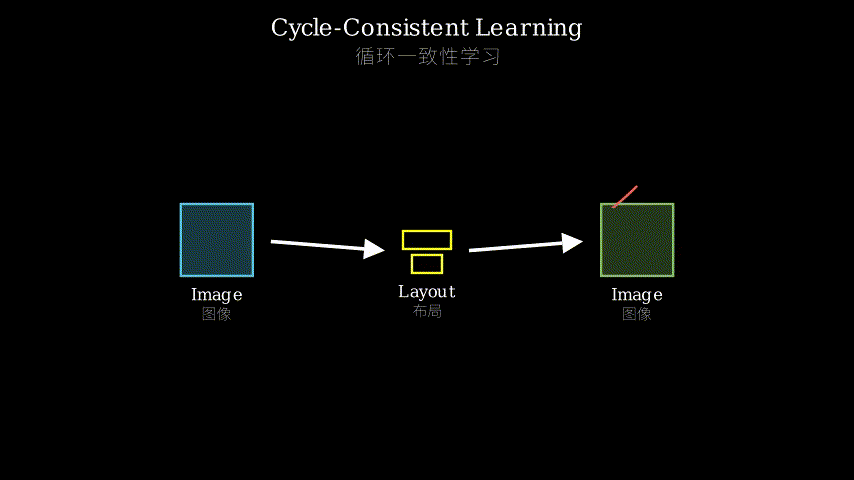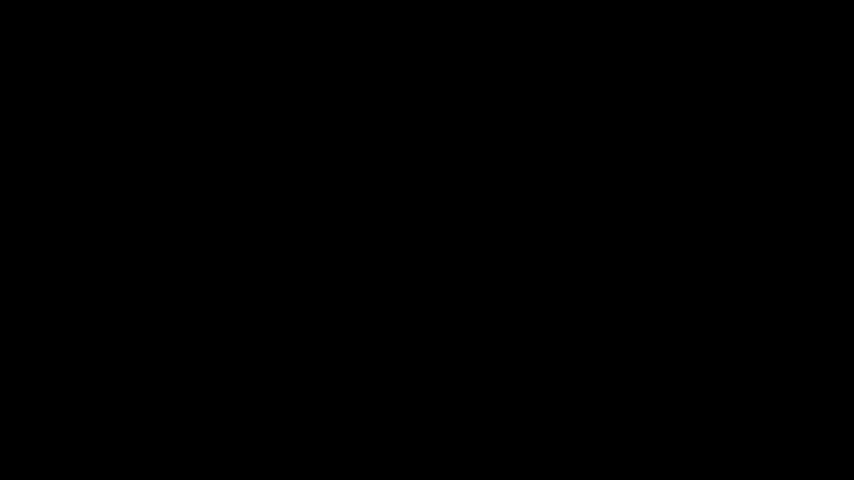
The architecture has two generation loops running simultaneously. Loop 1: image→layout→image (understand what’s in the picture, then regenerate it from that understanding). Loop 2: layout→image→layout (create an image from a description, then extract its layout to verify). During training, the model gets rewarded when these round-trips preserve information—if you can’t reconstruct the original after a cycle, something was lost in translation.
This creates a self-supervised signal: the model generates synthetic image-layout pairs, runs them through both loops, and uses the reconstruction error as a training signal. No human labels needed for this part. The cycle consistency loss acts as a regularizer that forces the understanding and generation pathways to stay aligned.
Input Image Tokens          Input Layout Tokens
      |                            |
      v                            v
  [Autoregressive Transformer Core]
      |                            |
      +----> Layout Tokens         +----> Image Tokens
             |                            |
             v                            v
      Reconstruct Image            Reconstruct Layout
             |                            |
             +--------> Cycle Loss <------+
                            |
                            v
                    RL Reward Signal
Think of it like learning a foreign language through translation exercises. You read a sentence in English, translate it to French, then translate back to English. If the round-trip matches the original, your understanding is solid. If it drifts (“the cat sat” becomes “a feline was positioned”), you know your translation model has gaps. CyCLeGen does this with images and layouts: the “English” is pixel space, the “French” is structured layout space, and the translation quality reveals how well the model truly understands visual content. The key insight: by forcing the model to be its own translator in both directions, you create a training signal that doesn’t need external labels—the consistency check is the supervision.
Key Concepts
-
Cycle Consistency: Imagine photocopying a document, then photocopying the copy. If the second copy looks identical to the original, your photocopier is high-fidelity. Cycle consistency applies this test to model transformations: if image→layout→image produces the same image, the layout extraction was accurate. If layout→image→layout produces the same layout, the image generation was faithful. The loss measures how much information degrades in the round-trip. This isn’t just a training trick—it’s a fundamental constraint that forces the model’s understanding and generation capabilities to stay mutually consistent. Without it, the model could “cheat” by generating plausible-looking outputs that don’t actually preserve the input’s semantic content.
-
Introspection: Most generative models are blind to their own outputs—they create an image and move on. CyCLeGen can analyze what it just generated by running it back through the understanding pathway. Generate an image from “red car on left, blue house on right”? Feed that image back in and extract its layout. If the model reports “blue car on right, red house on left,” it failed. This self-critique capability emerges naturally from the unified architecture—the same weights that generated the image can parse it. It’s like a writer who can edit their own work because they understand both composition and analysis, versus a writer who needs a separate editor.
-
Layout as Intermediate Representation: Why layouts specifically? Because they’re the sweet spot between raw pixels (too low-level, millions of dimensions) and text captions (too high-level, loses spatial precision). A layout is structured: bounding boxes with class labels, like
[car: (10,20,50,60), tree: (70,30,90,80)]. This representation is compact enough to model autoregressively but rich enough to capture spatial relationships. It’s the Goldilocks zone that lets the model reason about “what” and “where” simultaneously. Think of it as the assembly instructions for an image—precise enough to rebuild the original, abstract enough to manipulate conceptually.
Framework Shift
Before (modular approach):              After (CyCLeGen):

Image --> [Encoder] --> Features        Image Tokens
                |                            |
                v                            v
          Understanding                 [Unified
           Pathway                    Autoregressive
                                       Transformer]
Text --> [Diffusion] --> Image              |
              ^                              v
              |                         Layout Tokens
         Generation                          |
          Pathway                            v
                                        Image Tokens
(Separate models, no feedback)         (Single model,
                                        cycle-consistent)
From pipeline to loop, the core shift is replacing separate specialist models with a single generalist that validates itself through round-trip consistency.
Expert Assessment
Problem choice: Real gap. The perception/generation divide has been a known limitation since the first wave of foundation models. Unification attempts exist (Unified-IO, Chameleon) but they’re architecturally shallow—still modular under the hood. The cycle consistency angle is genuinely novel as a training objective for vision models, borrowed from CycleGAN but applied at the foundation model scale.
Method maturity: Clever insight with some brute force. The cycle consistency idea is elegant, but the execution leans on standard components (VQ-VAE tokenization, autoregressive transformers, RL fine-tuning). The paper doesn’t deeply explore why layouts are the right intermediate representation—what about scene graphs, depth maps, or other structured formats? Feels like they picked layouts because they’re tractable, not because they proved they’re optimal. The RL component (using cycle loss as reward) is underspecified—what’s the exploration strategy? How sensitive is it to hyperparameters?
Experimental integrity: Baselines are fair but not exhaustive. They compare against specialist models (CLIP for understanding, Stable Diffusion for generation) and show competitive performance, which is impressive for a unified model. But they don’t compare against other unification attempts like Unified-IO or Chameleon head-to-head on the same benchmarks. The ablation studies are thin—they show cycle consistency helps, but don’t isolate which loop (image→layout→image vs layout→image→layout) contributes more. The synthetic data experiments are promising but lack analysis of what failure modes the model learns to avoid through self-improvement.
Writing quality: The abstract and intro are crisp, but the method section gets muddy around the RL formulation. They introduce cycle consistency informally, then suddenly jump to policy gradients without bridging the conceptual gap. The related work section is too defensive—half of it is explaining why their approach isn’t just CycleGAN for images. The experiments section would benefit from error analysis: show failure cases where cycle consistency breaks down, not just aggregate metrics. The conclusion oversells the results (“significant gains”) when the numbers show modest improvements (2-3% on most benchmarks).
Verdict: weak accept — Solid unification idea with cycle consistency as a novel training signal, but execution is incremental and evaluation could be more rigorous.
Takeaways
The cycle consistency training loop is the transferable idea here. If you’re building any model that does bidirectional transformations (text→code→text, audio→transcript→audio, 3D→2D→3D), you can use round-trip reconstruction as a self-supervised signal. The key is picking an intermediate representation that’s (1) structured enough to be informative, (2) compact enough to model efficiently, and (3) reversible enough that cycles are meaningful. Don’t just bolt together separate models—make the same weights handle both directions, then use cycle loss to keep them aligned. The RL wrapper (treating cycle consistency as a reward) is a clean way to fine-tune without needing human labels for every domain.
For practitioners: if you’re training multimodal models, consider whether your tasks have natural cycle structures. Image captioning + text-to-image is one. Speech recognition + TTS is another. Molecular structure prediction + generation is a third. Anywhere you have paired forward/inverse tasks, cycle consistency can provide free supervision.
论文: 2603.14957 作者: Xiaojun Shan, Haoyu Shen, Yucheng Mao, Xiang Zhang, Abhay Anand, Bingnan Li, Haiyang Xu, Zhuowen Tu 分类: cs.CV
缺口
现有的视觉基础模型把世界一分为二:感知模型(CLIP、LLaVA)能理解图像但不能生成,生成模型(Stable Diffusion、DALL-E)能创造图像但缺乏深度理解。
这种架构上的分离造成三个问题:(1)每种能力都需要独立的训练流程和数据集,(2)模型无法对自己的输出进行推理(生成器无法批判自己刚生成的内容),(3)无法利用合成数据进行自我改进,因为缺少反馈回路。
之前的统一尝试如 Unified-IO 和 Chameleon 把独立的编码器-解码器模块拼接在一起,但它们本质上仍是模块化的——理解和生成路径并不共享同一计算基底。
CyCLeGen 认为真正的统一需要单一的自回归骨干网络,两个任务从相同的权重中涌现,通过循环一致性回路连接,实现相互监督。
问题:感知 =/= 生成(独立模型,无内省能力)
    |
    v
假设:统一架构 + 循环一致性 = 相互改进
    |
    v
方法:单一自回归模型 + 图像<->布局双向回路
    |
    v
证据:理解(VQA、描述)和生成(FID、布局)均有提升
    |
    v
结论:循环一致性使统一模型能够自监督改进
增量
一句话: CyCLeGen 之前,你需要独立的模型来看和创造;之后,单一模型同时做两件事,并通过检查 图像→布局→图像 是否一致重建来自我改进。
核心机制
CyCLeGen 使用一个自回归 Transformer,将图像和布局都处理为 token 序列。
图像通过学习的 VQ-VAE 被离散化为 token,布局是结构化文本(边界框 + 标签),模型学习在两者之间双向翻译。
架构中有两个同时运行的生成回路。
回路1:图像→布局→图像(理解图片中有什么,然后从这个理解重新生成)。
回路2:布局→图像→布局(从描述创建图像,然后提取其布局来验证)。
训练时,当这些往返过程保留信息时,模型会得到奖励——如果循环后无法重建原始内容,说明翻译过程中丢失了信息。
这创造了一个自监督信号:模型生成合成的图像-布局对,通过两个回路运行它们,用重建误差作为训练信号。
这部分不需要人工标注。
循环一致性损失充当正则化器,强制理解和生成路径保持对齐。
输入图像 Token              输入布局 Token
      |                            |
      v                            v
  [统一自回归 Transformer 核心]
      |                            |
      +----> 布局 Token            +----> 图像 Token
             |                            |
             v                            v
      重建图像                      重建布局
             |                            |
             +--------> 循环损失 <--------+
                            |
                            v
                    强化学习奖励信号
把它想象成通过翻译练习学外语。
你读一句英文,翻译成法文,再翻译回英文。
如果往返结果与原文一致,说明你的理解扎实。
如果出现漂移(“猫坐着”变成”一只猫科动物被放置”),说明你的翻译模型有缺口。
CyCLeGen 对图像和布局做同样的事:“英文”是像素空间,“法文”是结构化布局空间,翻译质量揭示了模型对视觉内容的真实理解程度。
关键洞察:通过强制模型在两个方向上都充当自己的翻译者,你创造了一个不需要外部标签的训练信号——一致性检查本身就是监督。
关键概念
- 循环一致性: 想象复印一份文档,然后复印这个副本。
如果第二份副本看起来与原件相同,说明你的复印机是高保真的。
循环一致性将这个测试应用于模型变换:如果 图像→布局→图像 产生相同的图像,说明布局提取是准确的。
如果 布局→图像→布局 产生相同的布局,说明图像生成是忠实的。
损失衡量信息在往返过程中退化了多少。
这不只是训练技巧——它是一个基本约束,强制模型的理解和生成能力保持相互一致。
没有它,模型可以”作弊”,生成看起来合理但实际上不保留输入语义内容的输出。
- 内省能力: 大多数生成模型对自己的输出是盲目的——它们创建一张图像然后继续前进。
CyCLeGen 可以通过理解路径分析自己刚生成的内容。
从”左边红车,右边蓝房子”生成图像?把那张图像反馈回去并提取其布局。
如果模型报告”右边蓝车,左边红房子”,说明它失败了。
这种自我批判能力自然地从统一架构中涌现——生成图像的相同权重可以解析它。
就像一个作家既能创作又能编辑自己的作品,因为他们同时理解写作和分析,而不是需要一个独立的编辑。
- 布局作为中间表示: 为什么特别选择布局?因为它们是原始像素(太低级,数百万维度)和文本描述(太高级,失去空间精度)之间的最佳点。
布局是结构化的:带类别标签的边界框,如 [车: (10,20,50,60), 树: (70,30,90,80)]。
这种表示足够紧凑可以自回归建模,又足够丰富可以捕获空间关系。
它是让模型同时推理”什么”和”在哪里”的金发姑娘区域。
把它想象成图像的组装说明书——足够精确可以重建原件,足够抽象可以概念性操作。
框架转变
之前(模块化方法):                之后(CyCLeGen):

图像 --> [编码器] --> 特征          图像 Token
                |                       |
                v                       v
            理解路径                [统一自回归
                                   Transformer]
文本 --> [扩散模型] --> 图像            |
              ^                        v
              |                   布局 Token
         生成路径                       |
                                       v
                                  图像 Token
(独立模型,无反馈)              (单一模型,
                                  循环一致)
从流水线到回路,核心转变是用单一通才模型替代独立专家模型,通过往返一致性进行自我验证。
专家评审
选题眼光: 真实缺口。
感知/生成分离自第一波基础模型以来就是已知局限。
统一尝试已经存在(Unified-IO、Chameleon),但它们在架构上是浅层的——底层仍是模块化。
循环一致性角度作为视觉模型的训练目标是真正新颖的,从 CycleGAN 借鉴但应用于基础模型规模。
方法成熟度: 巧妙洞察加一些蛮力。
循环一致性想法很优雅,但执行依赖标准组件(VQ-VAE token化、自回归 Transformer、强化学习微调)。
论文没有深入探索为什么布局是正确的中间表示——场景图、深度图或其他结构化格式呢?感觉他们选择布局是因为可行,而不是因为证明了它是最优的。
强化学习部分(使用循环损失作为奖励)规范不足——探索策略是什么?对超参数有多敏感?
实验诚意: 基线公平但不详尽。
他们与专家模型(理解用 CLIP,生成用 Stable Diffusion)比较并显示有竞争力的性能,对统一模型来说这很令人印象深刻。
但他们没有在相同基准上与其他统一尝试如 Unified-IO 或 Chameleon 正面比较。
消融研究很薄——他们显示循环一致性有帮助,但没有隔离哪个回路(图像→布局→图像 vs 布局→图像→布局)贡献更大。
合成数据实验有前景但缺乏对模型通过自我改进学会避免哪些失败模式的分析。
写作功力: 摘要和引言简洁,但方法部分在强化学习表述处变得混乱。
他们非正式地引入循环一致性,然后突然跳到策略梯度,没有弥合概念鸿沟。
相关工作部分过于防御——一半在解释为什么他们的方法不只是图像的 CycleGAN。
实验部分会受益于错误分析:展示循环一致性崩溃的失败案例,而不只是聚合指标。
结论过度推销结果(“显著提升”),而数字显示的是适度改进(大多数基准上 2-3%)。
判决: 弱接收 — 以循环一致性作为新颖训练信号的扎实统一想法,但执行是渐进式的,评估可以更严格。
要点总结
循环一致性训练回路是这里可迁移的想法。
如果你在构建任何做双向变换的模型(文本→代码→文本,音频→转录→音频,3D→2D→3D),你可以使用往返重建作为自监督信号。
关键是选择一个中间表示,它(1)足够结构化以提供信息,(2)足够紧凑以高效建模,(3)足够可逆以使循环有意义。
不要只是拼接独立模型——让相同的权重处理两个方向,然后使用循环损失保持它们对齐。
强化学习包装器(将循环一致性视为奖励)是一种干净的微调方式,不需要为每个领域提供人工标签。
对实践者:如果你在训练多模态模型,考虑你的任务是否有自然的循环结构。
图像描述 + 文本生成图像是一个。
语音识别 + TTS 是另一个。
分子结构预测 + 生成是第三个。
任何有配对正向/逆向任务的地方,循环一致性都可以提供免费监督。