Paper: 2602.24286 Authors: Weinan Dai, Hanlin Wu, Qiying Yu, Huan-ang Gao, Jiahao Li, Chengquan Jiang, Weiqiang Lou, Yufan Song, Hongli Yu, Jiaze Chen Categories: cs.LG, cs.AI
The Gap
CUDA kernel optimization sits at the heart of modern deep learning infrastructure, but it’s a dark art. Writing fast GPU code requires intimate knowledge of memory hierarchies, warp scheduling, bank conflicts, and dozens of other hardware quirks. The current frontier has two camps: compiler-based systems like torch.compile that apply deterministic optimization passes, and LLM-based approaches that generate code through prompting or fine-tuning.
The problem? Compilers hit a ceiling—they can’t discover novel optimization patterns beyond their programmed heuristics. Meanwhile, LLMs like GPT-4 and Claude, despite excelling at general programming, consistently produce CUDA kernels that are slower than compiler output. Existing LLM approaches either use training-free refinement (prompting the model to iteratively improve code) or fine-tune within fixed multi-turn feedback loops. Both fail to fundamentally upgrade the model’s intrinsic understanding of GPU performance characteristics. The result: LLMs remain uncompetitive for this critical task, leaving a performance gap that blocks their deployment in production ML systems.
The Increment
Before: LLMs generate CUDA code that’s correct but slow, losing to compilers. After: An RL-trained agent writes kernels that beat compilers by 2x and frontier LLMs by 40%.
Think of CUDA Agent as a flight simulator for GPU programming. The data synthesis pipeline is the scenario generator, creating thousands of varied optimization challenges—simple maneuvers (basic kernels) to emergency landings (complex fusions). The skill-augmented development environment is the cockpit with full instrumentation: automated verification checks if the code “flies” (correctness), profiling tools measure “fuel efficiency” (performance), and the reward signal tells the pilot how smooth the landing was. The RL training loop is the repeated practice sessions where the agent learns not just to follow checklists (like compilers) but to develop intuition for when to bank left or right based on real-time feedback.
The system has three structural components working in concert. First, a scalable data synthesis pipeline generates training problems by mining real-world PyTorch operations and systematically varying their parameters (batch sizes, dimensions, data types). This creates a curriculum from trivial to fiendishly complex. Second, a skill-augmented CUDA development environment wraps the agent’s code generation with automated compilation, execution, and profiling—providing dense, reliable reward signals based on actual GPU performance metrics. Third, RL algorithmic techniques (PPO with careful hyperparameter tuning, curriculum learning, and exploration bonuses) enable stable training at scale without the catastrophic forgetting or reward hacking that plague naive RL setups.
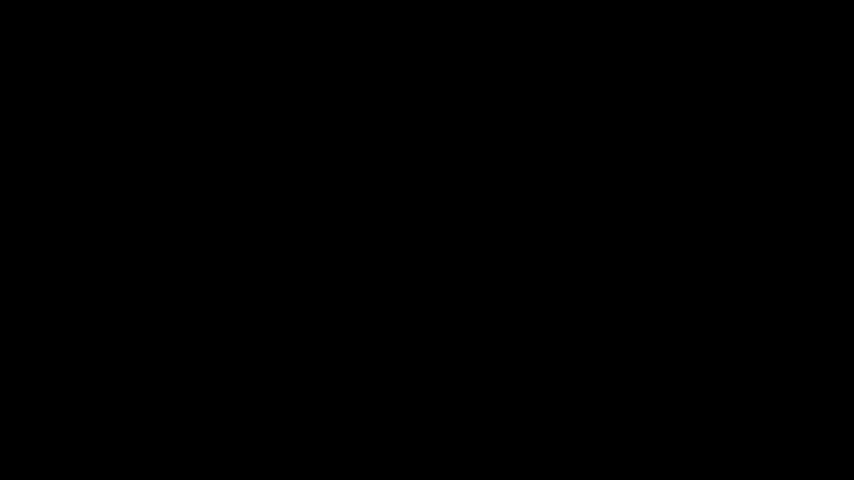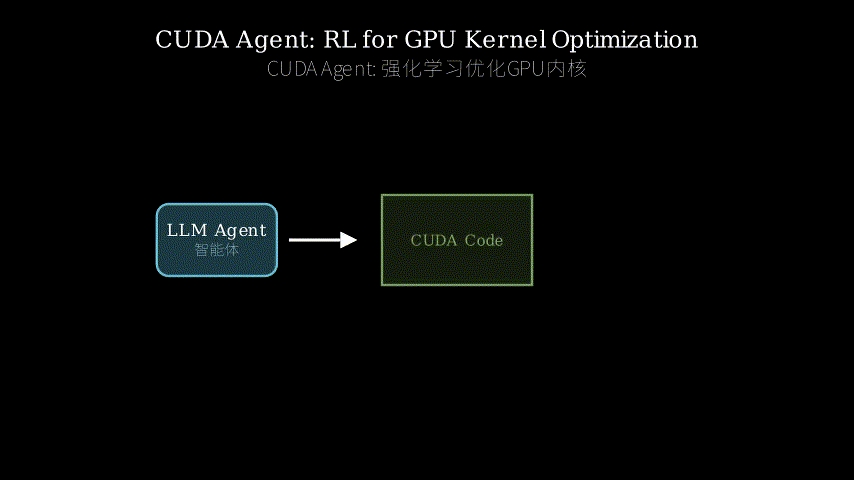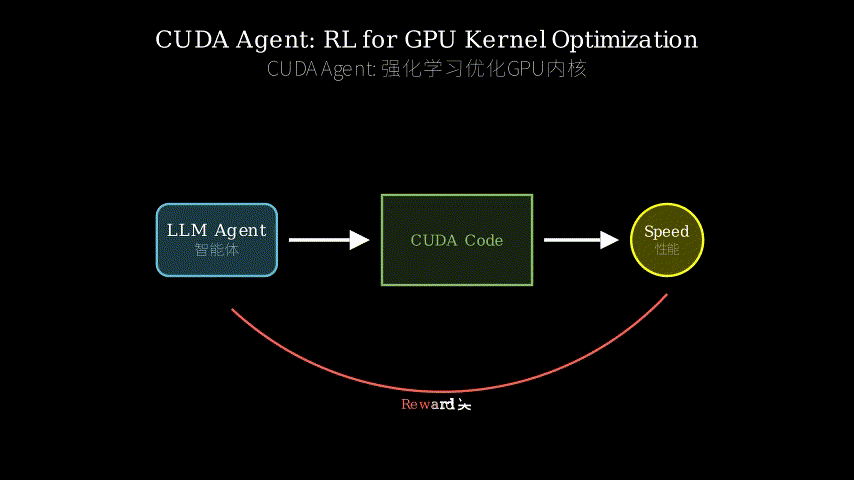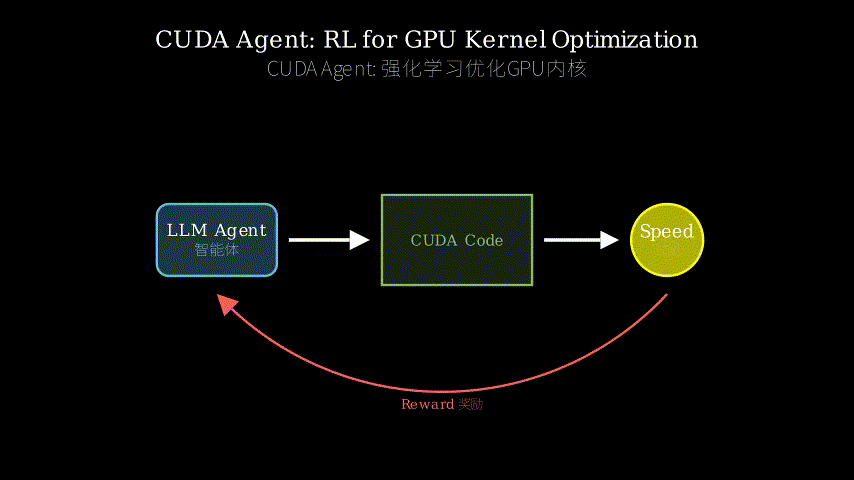
The key insight: instead of asking an LLM to generate good code in one shot, train it through thousands of attempts with real performance feedback, letting it internalize the cause-and-effect relationship between code patterns and execution speed.
Key Concepts
Agentic Reinforcement Learning for Code
Most code generation systems treat the LLM as a one-shot oracle: you prompt it, it spits out code, done. Agentic RL flips this. The model becomes an agent that takes actions (writing code), observes outcomes (execution time, correctness), and receives rewards (faster = better). Over many episodes, it learns a policy—a mapping from problem specifications to high-performance code.
Here’s the concrete difference. Imagine you’re learning to cook. The one-shot approach is reading a recipe once and trying to make the dish—you might succeed, but you won’t develop deep intuition. The RL approach is cooking the same dish 10,000 times, tasting the result each time, and adjusting. By episode 5,000, you’ve internalized that searing meat at high heat creates flavor, that salt added early vs. late matters, that resting time affects texture. You’re not following a recipe anymore—you’ve developed taste.
For CUDA Agent, the “taste” is performance intuition: knowing that coalesced memory access patterns are fast, that shared memory reduces global memory traffic, that loop unrolling helps but only to a point. The agent learns these through trial and error, not by memorizing rules.
Reward Signal Design in Performance Optimization
In RL, the reward function is everything—it defines what “good” means. For CUDA kernels, the naive reward is simple: faster execution = higher reward. But this creates problems. What if the code is fast but wrong? What if it’s correct but uses so much memory it crashes on real GPUs? What if the agent discovers a “hack” like returning cached results instead of computing?
CUDA Agent’s reward function is a carefully engineered composite. First, correctness is a hard gate: if the output doesn’t match the reference implementation within numerical tolerance, reward is zero (or negative). Second, performance is measured as speedup ratio over a baseline (torch.compile), normalized to prevent outliers from dominating. Third, penalties are added for excessive memory usage or compilation failures. This creates a reward landscape where the agent must satisfy multiple constraints simultaneously—like optimizing a multi-objective function.
The profiling infrastructure is critical here. The environment doesn’t just run the kernel once; it runs it multiple times, warms up the GPU, measures median execution time, and checks for numerical stability. This provides a stable, low-noise reward signal that the RL algorithm can actually learn from. Without this, the agent would be optimizing random noise.
Curriculum Learning for Complexity Scaling
You don’t teach calculus to kindergarteners. Similarly, you don’t start an RL agent on the hardest CUDA optimization problems. Curriculum learning structures the training data from easy to hard, allowing the agent to build foundational skills before tackling complex cases.
CUDA Agent’s curriculum has three levels. Level-1 problems are simple element-wise operations (add, multiply, ReLU)—the agent learns basic CUDA syntax, memory access patterns, and thread indexing. Level-2 introduces reductions and simple fusions (softmax, layer norm)—the agent learns shared memory usage and synchronization. Level-3 presents complex multi-stage kernels (attention mechanisms, fused optimizers)—the agent learns advanced optimization techniques like register tiling and warp-level primitives.
The key is gradual exposure. If you throw Level-3 problems at an untrained agent, it flails randomly and learns nothing (the reward signal is too sparse). But if you start with Level-1, the agent quickly learns that certain patterns (coalesced access, avoiding divergence) consistently yield rewards. It then transfers these patterns to Level-2, refining them. By Level-3, it has a toolkit of proven techniques to combine creatively.
This mirrors how human experts learn: you master basics, then build on them, eventually developing the ability to tackle novel problems by composing known patterns in new ways.
Expert Assessment
Problem significance: This is a high-value problem. CUDA kernel performance directly impacts training and inference costs for every major ML system. The affected community includes ML engineers at every company running GPU workloads, researchers pushing model scale, and infrastructure teams optimizing serving costs. A 2x speedup translates to halving compute bills or doubling throughput—real money and real capability gains.
Method maturity: This is closer to proof-of-concept than production-ready, though it’s a strong proof-of-concept. The system works on KernelBench, a curated benchmark, but real-world deployment faces challenges the paper doesn’t fully address. First, the training cost: large-scale RL with GPU profiling in the loop is expensive—how much compute did this take, and can smaller labs reproduce it? Second, generalization: KernelBench covers common operations, but production systems have long-tail exotic kernels. Does the agent handle novel operation types it wasn’t trained on? Third, safety: the paper mentions automated verification, but what happens when the agent generates code with subtle race conditions or numerical instabilities that only appear under specific inputs? These aren’t fatal flaws, but they’re gaps between “works in the lab” and “ships in PyTorch.”
The authors acknowledge training cost implicitly (mentioning “large-scale” RL) but don’t provide wall-clock time or GPU-hours. They also don’t discuss failure modes in detail—what percentage of generated kernels are correct? How often does the agent produce code that compiles but crashes?
Experimental rigor: The baselines are fair and comprehensive—torch.compile (the industry standard), Claude Opus 4.5, Gemini 3 Pro (frontier LLMs), and prior work. The benchmark (KernelBench) is reasonable, covering a range of operation types and complexity levels. The evaluation metrics (speedup ratio, pass rate) are appropriate.
One red flag: the paper reports “100%, 100%, and 92% faster rate” over torch.compile, which sounds like pass rates, not speedup. The phrasing is ambiguous—does this mean the agent’s kernels are 2x faster on average, or that 100% of Level-1 problems beat torch.compile? Clearer reporting would help. Also, the 40% margin over frontier LLMs on Level-3 is impressive, but we don’t see error bars or statistical significance tests. Given the stochasticity in RL training, how stable are these results across different random seeds?
Verdict: Weak accept — strong results on a real problem, but maturity and reproducibility concerns prevent a strong accept.
Takeaways
Dense reward signals beat sparse ones: CUDA Agent’s success hinges on automated profiling providing immediate, accurate feedback. This principle transfers to any domain where you’re training agents to optimize complex systems—compiler optimization, database query planning, network routing. If you can build a fast, reliable simulator or evaluator, RL becomes viable. If evaluation is slow or noisy, you’re stuck.
Curriculum learning is not optional for hard tasks: Throwing an agent into the deep end doesn’t build competence; it builds random thrashing. The structured progression from simple to complex is what enables learning. This applies beyond RL—it’s how you should structure any training pipeline for difficult skills, whether it’s teaching a model to prove theorems or a robot to manipulate objects.
Agentic RL for code is underexplored: Most code generation research focuses on supervised learning (train on code, predict code) or prompting (ask nicely, hope for the best). CUDA Agent shows that RL with execution feedback can surpass both. This opens a design space: what other programming tasks have objective, measurable quality metrics? Systems programming (optimize for latency), data structure design (optimize for cache efficiency), algorithm implementation (optimize for asymptotic complexity). Anywhere you can run code and measure outcomes, you can apply this paradigm.
Reward engineering is the hard part: The technical contribution isn’t the RL algorithm (PPO is standard) or the model architecture (likely a fine-tuned LLM). It’s the reward function and environment design—ensuring correctness, measuring performance reliably, preventing reward hacking. This is the unsexy infrastructure work that makes or breaks RL projects. If you’re building an RL system, budget 80% of your effort here.
论文: 2602.24286 作者: Weinan Dai, Hanlin Wu, Qiying Yu, Huan-ang Gao, Jiahao Li, Chengquan Jiang, Weiqiang Lou, Yufan Song, Hongli Yu, Jiaze Chen 分类: cs.LG, cs.AI
缺口
CUDA内核优化是现代深度学习基础设施的核心,但它是一门黑魔法。编写高性能GPU代码需要对内存层次结构、warp调度、bank冲突等几十种硬件特性有深入理解。当前的技术前沿分为两派:基于编译器的系统如torch.compile应用确定性优化pass,以及基于大语言模型的方法通过提示或微调生成代码。
问题在哪?编译器遇到了天花板——它们无法发现超出预设启发式规则的新优化模式。与此同时,GPT-4和Claude等大模型尽管在通用编程上表现出色,但生成的CUDA内核始终比编译器输出慢。现有的LLM方法要么使用无训练的迭代改进(提示模型逐步优化代码),要么在固定的多轮反馈循环中微调。两种范式都未能从根本上提升模型对GPU性能特征的内在理解。结果就是:LLM在这个关键任务上缺乏竞争力,性能差距阻碍了它们在生产ML系统中的部署。
增量
之前: 大模型生成的CUDA代码正确但慢,输给编译器。之后: 强化学习训练的智能体编写的内核比编译器快2倍,比前沿大模型快40%。
把CUDA Agent想象成GPU编程的飞行模拟器。数据合成管线是场景生成器,创建数千个不同的优化挑战——从简单操作(基础内核)到紧急迫降(复杂融合)。技能增强的开发环境是配备完整仪表的驾驶舱:自动验证检查代码能否”飞行”(正确性),性能分析工具测量”燃油效率”(性能),奖励信号告诉飞行员着陆有多平稳。强化学习训练循环是反复的练习课程,智能体学会的不只是遵循检查清单(像编译器那样),而是基于实时反馈培养何时左转或右转的直觉。
系统由三个结构化组件协同工作。首先,可扩展的数据合成管线通过挖掘真实PyTorch操作并系统性地变化其参数(批大小、维度、数据类型)来生成训练问题。这创建了从简单到极其复杂的课程。其次,技能增强的CUDA开发环境将智能体的代码生成包装在自动编译、执行和性能分析中——基于实际GPU性能指标提供密集、可靠的奖励信号。第三,强化学习算法技术(带精心调优超参数的PPO、课程学习和探索奖励)实现了大规模稳定训练,避免了困扰朴素RL设置的灾难性遗忘或奖励欺骗。
核心洞察:与其要求LLM一次性生成好代码,不如通过数千次尝试和真实性能反馈来训练它,让它内化代码模式与执行速度之间的因果关系。
关键概念
代码生成的智能体强化学习
大多数代码生成系统把LLM当作一次性预言机:你提示它,它输出代码,完事。智能体强化学习翻转了这个模式。模型变成一个智能体,采取行动(编写代码),观察结果(执行时间、正确性),接收奖励(更快=更好)。经过许多回合,它学习一个策略——从问题规格到高性能代码的映射。
具体区别在哪?想象你在学做菜。一次性方法是读一遍菜谱就尝试做菜——你可能成功,但不会培养深层直觉。强化学习方法是做同一道菜10000次,每次品尝结果并调整。到第5000次时,你已经内化了高温煎肉能产生风味、早加盐和晚加盐有区别、静置时间影响口感。你不再遵循菜谱——你培养出了味觉。
对CUDA Agent来说,“味觉”就是性能直觉:知道合并的内存访问模式快、共享内存减少全局内存流量、循环展开有帮助但要适度。智能体通过试错学习这些,而非记忆规则。
性能优化中的奖励信号设计
在强化学习中,奖励函数就是一切——它定义了什么是”好”。对CUDA内核来说,朴素的奖励很简单:执行越快=奖励越高。但这会产生问题。如果代码快但错误怎么办?如果正确但使用太多内存导致真实GPU崩溃怎么办?如果智能体发现”作弊”方法比如返回缓存结果而非计算怎么办?
CUDA Agent的奖励函数是精心设计的复合体。首先,正确性是硬门槛:如果输出在数值容差内不匹配参考实现,奖励为零(或负值)。其次,性能测量为相对基线(torch.compile)的加速比,归一化以防止异常值主导。第三,对过度内存使用或编译失败添加惩罚。这创建了一个奖励景观,智能体必须同时满足多个约束——就像优化多目标函数。
性能分析基础设施在这里至关重要。环境不只运行内核一次;它多次运行,预热GPU,测量中位执行时间,检查数值稳定性。这提供了稳定、低噪声的奖励信号,强化学习算法才能真正从中学习。没有这个,智能体就是在优化随机噪声。
复杂度递增的课程学习
你不会给幼儿园小朋友教微积分。类似地,你不会让强化学习智能体从最难的CUDA优化问题开始。课程学习将训练数据从易到难结构化,让智能体在处理复杂案例前建立基础技能。
CUDA Agent的课程分三级。Level-1问题是简单的逐元素操作(加法、乘法、ReLU)——智能体学习基本CUDA语法、内存访问模式和线程索引。Level-2引入归约和简单融合(softmax、layer norm)——智能体学习共享内存使用和同步。Level-3呈现复杂的多阶段内核(注意力机制、融合优化器)——智能体学习高级优化技术如寄存器分块和warp级原语。
关键是逐步暴露。如果你把Level-3问题扔给未训练的智能体,它会随机挣扎且学不到东西(奖励信号太稀疏)。但如果从Level-1开始,智能体很快学到某些模式(合并访问、避免分歧)持续产生奖励。然后它将这些模式迁移到Level-2,进一步精炼。到Level-3时,它有了一套经过验证的技术工具箱,可以创造性地组合。
这反映了人类专家的学习方式:你掌握基础,然后在此基础上构建,最终培养出通过以新方式组合已知模式来处理新问题的能力。
专家评审
问题重要性: 这是一个高价值问题。CUDA内核性能直接影响每个主要ML系统的训练和推理成本。受影响的群体包括每家运行GPU工作负载的公司的ML工程师、推动模型规模的研究人员、优化服务成本的基础设施团队。2倍加速意味着计算账单减半或吞吐量翻倍——真金白银和真实能力提升。
方法成熟度: 这更接近概念验证而非生产就绪,尽管是一个强有力的概念验证。系统在KernelBench(一个精选基准)上有效,但实际部署面临论文未充分解决的挑战。首先是训练成本:在循环中进行GPU性能分析的大规模强化学习很昂贵——这花了多少计算资源,小实验室能复现吗?其次是泛化:KernelBench覆盖常见操作,但生产系统有长尾的奇特内核。智能体能处理训练时未见过的新操作类型吗?第三是安全性:论文提到自动验证,但当智能体生成带有微妙竞态条件或仅在特定输入下出现的数值不稳定性的代码时会怎样?这些不是致命缺陷,但它们是”实验室有效”和”在PyTorch中发布”之间的差距。
作者隐含地承认了训练成本(提到”大规模”强化学习)但没有提供实际时间或GPU小时数。他们也没有详细讨论失败模式——生成的内核有多少百分比是正确的?智能体多久产生一次能编译但会崩溃的代码?
实验严谨性: 基线公平且全面——torch.compile(行业标准)、Claude Opus 4.5、Gemini 3 Pro(前沿大模型)和先前工作。基准(KernelBench)合理,覆盖了一系列操作类型和复杂度级别。评估指标(加速比、通过率)恰当。
一个警示信号:论文报告”相比torch.compile快100%、100%和92%“,这听起来像通过率而非加速比。措辞模糊——这是指智能体的内核平均快2倍,还是100%的Level-1问题击败了torch.compile?更清晰的报告会有帮助。此外,在Level-3上比前沿大模型快40%令人印象深刻,但我们没看到误差条或统计显著性检验。考虑到强化学习训练的随机性,这些结果在不同随机种子下有多稳定?
判决: 弱接收——在真实问题上有强结果,但成熟度和可复现性担忧阻止了强接收。
要点总结
密集奖励信号胜过稀疏信号: CUDA Agent的成功依赖于自动性能分析提供即时、准确的反馈。这个原则可迁移到任何训练智能体优化复杂系统的领域——编译器优化、数据库查询规划、网络路由。如果你能构建快速、可靠的模拟器或评估器,强化学习就可行。如果评估慢或有噪声,你就卡住了。
课程学习对困难任务不可或缺: 把智能体扔进深水区不会培养能力;它培养随机挣扎。从简单到复杂的结构化进展才能实现学习。这超越了强化学习——这是你应该如何为困难技能构建任何训练管线的方式,无论是教模型证明定理还是教机器人操纵物体。
代码的智能体强化学习探索不足: 大多数代码生成研究聚焦于监督学习(在代码上训练,预测代码)或提示(好好请求,寄希望于最好结果)。CUDA Agent表明带执行反馈的强化学习能超越两者。这打开了一个设计空间:还有哪些编程任务有客观、可测量的质量指标?系统编程(优化延迟)、数据结构设计(优化缓存效率)、算法实现(优化渐近复杂度)。任何你能运行代码并测量结果的地方,都能应用这个范式。
奖励工程是难点: 技术贡献不是强化学习算法(PPO是标准的)或模型架构(可能是微调的大模型)。而是奖励函数和环境设计——确保正确性、可靠测量性能、防止奖励欺骗。这是决定强化学习项目成败的不性感的基础设施工作。如果你在构建强化学习系统,把80%的精力预算在这里。