Paper: 2608.07460 Authors: Ananya Sahu, Mohit Bansal, Elias Stengel-Eskin Categories: cs.CL, cs.AI
The Gap
Everyone in the field knows the tax: SFT plus preference optimization makes a model helpful, safe, and formatted — and also makes it write the same story ten times in a row. Mode collapse under RLHF/DPO is well documented, and the existing fixes fall into three families, each with a real cost.
Decoding-time tricks (higher temperature, nucleus/typical/min-p sampling) buy diversity by pushing the model into its own tail, which means quality degrades roughly monotonically with variety. Multi-model inference (contrastive decoding against the base model, proxy tuning, logit interpolation, ensembles of differently-tuned checkpoints) genuinely works but requires holding two or more models in memory at inference, and the diversity knob is global rather than local. Data-side approaches (persona conditioning, seed-word injection, diversity-aware DPO) keep single-model inference but bake the diversity in as a fixed style rather than something the model can dial up exactly where it matters.
There is also a measurement gap. The field mostly reports distinct-n / self-BLEU (lexical) and embedding cosine spread (semantic). Both are blind to the thing readers actually notice in stories: whether the plot shape differs. Ten stories can use disjoint vocabulary and still be “orphan discovers power, mentor dies, orphan wins.”
This paper’s bet: make creativity a controllable, locally-scoped, learned behavior of a single model, and measure it at the level of narrative structure.
PROBLEM: post-training raises quality but collapses diversity
    |
    +-- prior fix A: hotter decoding ...... quality falls with diversity
    +-- prior fix B: base+instruct at test . 2x memory, global knob only
    +-- prior fix C: diverse SFT data ...... fixed style, no control
    |
    v
ASSUMPTION: creativity is a *span-level* mode the model can be
            taught to enter and exit on its own
    |
    v
METHOD: build tagged data where creative segments are wrapped in
        [StartCreativity]; SFT the model to emit the tag itself
    |
    v
EVIDENCE: (1) matches/beats multi-model + distilled baselines on
              lexical + semantic + new structural diversity
          (2) human raters prefer it as more creative 70.3% of time
          (3) GRPO from this checkpoint: +~4% AMC, +~5pt MATH
    |
    v
CONCLUSION: a single model can hold both distributions, and the
            creative one is a better substrate for exploration/RL
The Increment
One sentence: Before, getting base-model variety out of an aligned model meant paying at inference time (two models, or a temperature that hurts quality); after, the aligned model carries a learned in-band switch that turns variety on for the spans where it helps — and that switch turns out to also make RL work better.
Core Mechanism
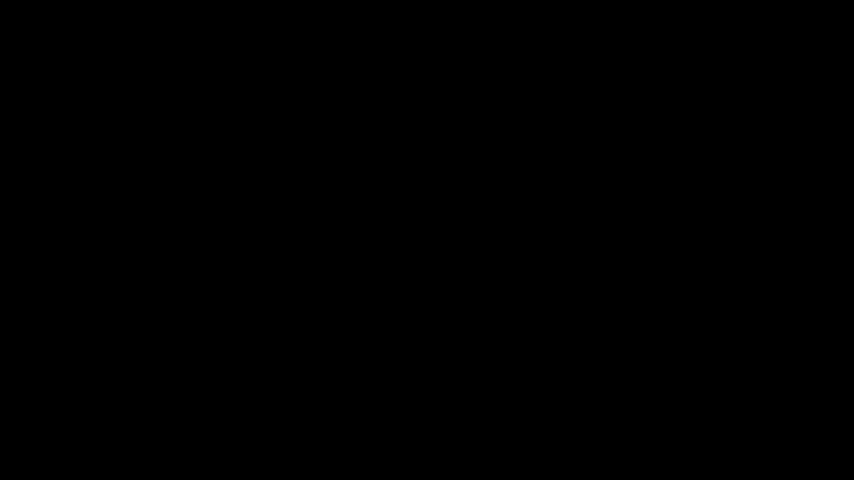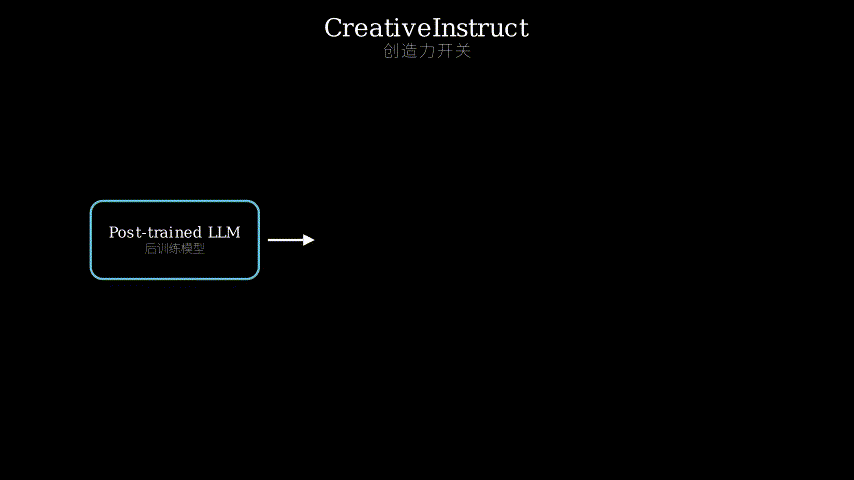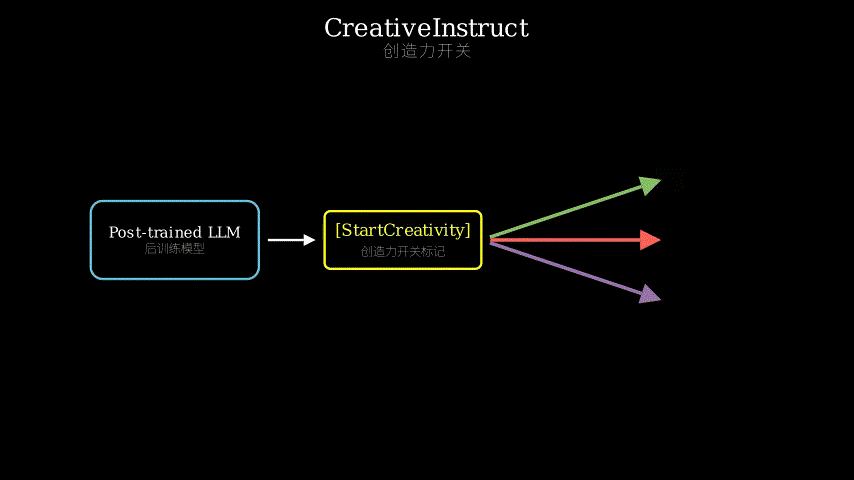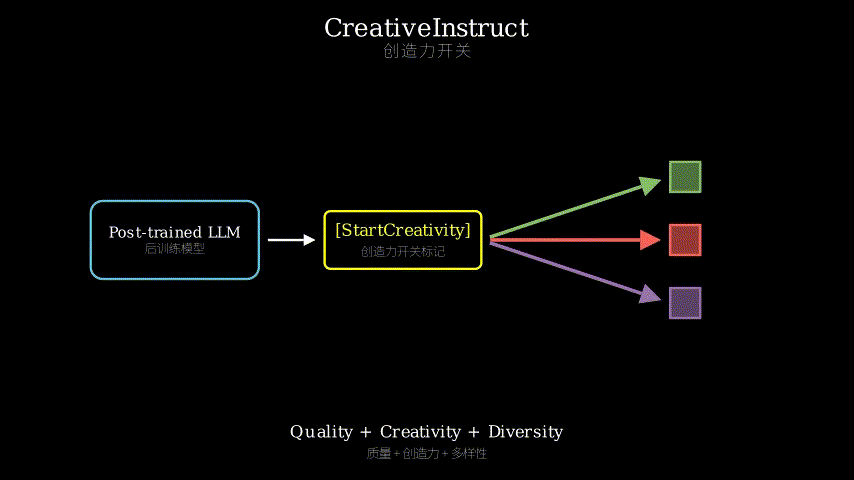
Three pieces. First, data construction. You need supervision that says “here is a span where base-model-like unpredictability is the right move, and here is a span where post-trained competence is the right move.” The scalable way to get this is to generate from both distributions on the same prompt, then splice: keep the structural/quality scaffolding from the post-trained model and substitute creative segments sourced from the base-model-like generations, wrapping those segments in a [StartCreativity] marker. The scaling story matters here — this is the difference between the method and a hand-curated diversity dataset. No human writes the tags.
Second, training. Plain instruction tuning on the tagged corpus. Critically, the tag is in the vocabulary and in the loss, so the model learns two coupled things at once: when to open a creative span (a planning decision) and how to write inside one (a distributional shift). At inference you sample normally from a single model; the tags appear on their own and are stripped from the final output. You can also force or suppress the tag if you want the knob explicitly.
Third, measurement. The structural diversity metric abstracts each generation into a graph — entities and events as nodes, relations between them as edges — and measures pairwise graph edit distance across a sample set. Graph edit distance is the minimum number of node/edge insertions, deletions, and relabelings to morph one graph into another. High average distance means the stories differ in shape, not just wording.
DATA BUILD
  prompt --+--> [ post-trained model ] --> fluent, safe, generic draft
           |                                        |
           +--> [ base-like model    ] --> odd, varied, uneven text
                                                    |
                          v                         v
                    [ splice + tag ]  <-------------+
                          |
                          v
        "... she opened the door. [StartCreativity] the hallway
         was inventory, not architecture ... "

TRAIN
  tagged corpus --> SFT --> single model M  (tag token in loss)

INFERENCE
  prompt --> M --> tokens ... [StartCreativity] ... tokens
                     |                |
                quality mode     creative mode
                     |                |
                     +------ strip tags -----> output

EVALUATE
  N samples --> parse to graphs --> pairwise graph edit distance
      G1: (hero)-fights->(dragon)-guards->(gold)
      G2: (clerk)-audits->(dragon)-owes->(bank)
      GED large ==> structurally diverse
      lexical/semantic metrics would also fire here, but they
      also fire on G1 vs a re-worded G1; GED does not
The metaphor: a jazz chart. A big-band arrangement is fully written out — every note fixed, reliably good, and identical every night. That is the post-trained model. A free improv session is different every night and sometimes falls apart. That is the base model. What working charts actually do is write the heads and the ensemble passages, then print a marked box that says *solo here, 16 bars. The [StartCreativity] tag is that printed box.
Now walk the method through the chart. The data-construction pipeline is the arranger deciding which bars should be written and which should be solo space — and it makes that decision by listening to both a written version and an improvised version of the same tune and stitching. Training is the band rehearsing until players internalize not just how to solo but when the solo is supposed to start — nobody has to cue them. Inference is the performance: one band, one chart, no second orchestra standing by in the wings (that is the multi-model baseline, which is like hiring a separate improv ensemble and cross-fading between stages). Cranking the temperature, by contrast, is telling the whole band to play loose all night, including during the tight ensemble hits — which is exactly why it costs quality.
And the RL result fits the metaphor too: a band that knows how to solo has more material to discover when you tell it to go find something new. A band that can only play the chart has nothing to search over.
Key Concepts
-
Mode collapse from post-training: Imagine asking 100 people to name a fruit. Raw human answers scatter across apple, mango, persimmon, durian. Now train them by rewarding whichever answer a judge liked most — everyone converges on “apple.” Nothing is wrong with apple; it is just that you have destroyed the distribution. Preference optimization does this at the sequence level: it sharpens probability mass onto whatever the reward model rated highest, so a model that could write 50 story openings now writes one opening 50 ways. The pathology is not lower quality, it is lower *entropy over good options.
-
In-band control tokens: Instead of controlling a model from outside (change the sampler, change the prompt, mix in another model’s logits), you put the control signal *inside the text as a special token and train on data where that token predicts a real distributional shift. The model then generates its own control signal. This is the same trick as control codes in conditional generation and reward-conditioned tokens in offline RL, applied to creativity. The elegant part is that the model chooses where to place it, so control becomes span-local instead of global.
-
Graph edit distance for narrative structure: Take two Lego builds. You can compare them by counting how many bricks of each color they use (lexical diversity) or by asking people whether they feel similar (semantic diversity). Or you can count the minimum number of brick add/remove/swap operations to turn one into the other — that is edit distance, and it is sensitive to *assembly, not inventory. Applied to stories: turn each story into a graph of who did what to whom, then ask how many surgical edits map one plot onto another. Two stories about completely different characters that both run “protagonist loses mentor, then avenges them” will have small graph edit distance even though every noun differs. That is the signal the paper claims prior metrics were missing.
Framework Shift
Before (mainstream approach):          After (this paper):

 [ base model ]   [ RLHF model ]        [ one CreativeInstruct model ]
      |                 |                          |
      +--- mix logits --+                   emits its own tag
              |                                    |
              v                          +---------+---------+
        one global knob                  |                   |
        (temp / alpha / lambda)      normal span      [StartCreativity]
              |                          |                   |
              v                          v                   v
     diversity <==> quality        quality mode       creative mode
       (tradeoff dial)                    |                   |
              |                           +-------+-----------+
              v                                   v
     2 models at inference                one model, span-level control
                                                  |
                                                  v
                                          better RL starting point


 measurement before:                    measurement after:
   distinct-n, self-BLEU  (words)         + graph edit distance
   embedding cosine       (meaning)         over event graphs (shape)
One sentence: From *tuning a global dial between two models at inference to teaching one model to open and close creative spans by itself, the core shift is moving diversity control from the sampler into the model’s own token stream.
Expert Assessment
A caveat up front: I am working from the abstract and the shape of the surrounding literature, not a full read of the data-construction section — so treat my method reconstruction as a plausible reading, not a verified one, and weight the experimental critiques accordingly.
Problem choice: Real gap, and well-positioned. Diversity collapse from post-training is one of the field’s genuinely unsolved practical problems, and the framing that it hurts *implicitly creative tasks — RL exploration especially — is the most valuable sentence in the abstract. There is a growing body of evidence that RL from a low-entropy policy just re-ranks what the policy already does, so “creativity as exploration substrate” is exactly where the field’s attention is heading. The paper is riding a real wave, not manufacturing one.
Method maturity: Clever, but the cleverness is in the packaging rather than the primitive. In-band control tokens are old (control codes, reward tokens, quality-conditioned pretraining); the contribution is applying them at *span granularity to creativity and building the tagged data automatically. That is a good idea, and the automatic-splicing pipeline is where the real risk lives: splice quality determines everything, and I would want to see how brittle the “which spans should be creative” heuristic is. Simpler baselines that deserve explicit refutation: min-p or entropy-targeted sampling (much stronger than plain temperature, and free), and simply distilling base-model outputs with light quality filtering. The abstract says distilled variants were compared, which is the right instinct.
Experimental integrity: Two things I would push on at a poster. First, the paper introduces its own headline diversity metric and then wins on it. That is not disqualifying — someone has to introduce new metrics — but a self-authored metric that favors the authors’ method needs independent validation, and the human eval should be doing that work. The 70.3% creativity preference is a decent signal, but *creativity preference alone does not settle the quality question; I want the paired quality judgment at the same time, not a separate automatic quality score. Second, the RL numbers are the flashiest claim and the thinnest evidence: AMC is a tiny benchmark (tens of problems), so “+4%” can be one or two items, and single-seed GRPO comparisons are notoriously noisy. Multiple seeds with variance, or this result gets downgraded to “suggestive.”
Writing quality: Based on the abstract’s emphasis, the likely soft spot is the data-construction description — it is the load-bearing part and the easiest to compress into “we splice and tag.” The section I would most want rewritten is the RL experiment: if the authors expanded it with more benchmarks, seeds, and an entropy analysis showing *why the creative checkpoint explores better, that section alone would move the paper from “nice method paper” to “result the field cites.” Right now it reads as a promising appendix promoted to the abstract.
Verdict: weak accept — the mechanism is sound and clearly useful, but the two most exciting claims (the new structural metric and the RL transfer) each rest on evidence one notch thinner than the claim.
Takeaways
Things you can lift and use elsewhere:
Span-level control tokens as a general pattern. Any time you want a model to behave differently in *part of its output — more terse here, more rigorous there, more speculative in this paragraph — you can build tagged data by splicing generations from two different sources and letting the model learn both the placement and the behavior. This generalizes far beyond creativity: verbosity control, citation-required spans, “I am guessing here” spans, code sections that should be defensive versus fast.
Make the model emit its own control signal. The reason this beats a prompt or a sampler flag is that the *placement decision is itself learned from data. If you have been solving control problems with system prompts, ask whether the decision of when to apply the control is something you actually want the model to learn.
Edit distance on structured abstractions as a diversity metric. If your outputs have structure — API call sequences, SQL query plans, test suites, agent trajectories, molecules — abstract to a graph and use graph edit distance instead of embedding cosine. Embeddings tell you if two outputs *feel different; edit distance tells you if they are built differently. This one is immediately portable and cheap.
Check the entropy of your RL starting point. The most actionable claim in the paper: if you are running GRPO/PPO and plateauing, the problem may be that your SFT checkpoint has already collapsed the distribution you are trying to search. Before tuning the RL recipe, measure the entropy and sample diversity of the initialization.
One honest caveat to carry: the multi-model baselines this replaces are not expensive in absolute terms. If you have the memory, base+instruct contrastive decoding is a strong, training-free baseline. The case for CreativeInstruct is strongest when you need single-model deployment or when you want the creative checkpoint as an RL starting point.
论文: 2608.07460 作者: Ananya Sahu, Mohit Bansal, Elias Stengel-Eskin 分类: cs.CL, cs.AI
缺口
这个税大家都交过:SFT 加偏好优化让模型变得有用、安全、格式规整,同时也让它把同一个故事写十遍。
RLHF/DPO 造成的模式崩塌已有充分记录,现有的补救办法分三类,每类都有实打实的代价。
解码期技巧(提高温度、nucleus / typical / min-p 采样)靠把模型推向自己的分布尾部换取多样性,代价是质量随多样性单调下滑。
多模型推理(与基座模型做对比解码、proxy tuning、logit 插值、多检查点集成)确实有效,但推理时要同时装载两个以上模型,而且多样性旋钮是全局的,不是局部的。
数据侧方法(人格设定、种子词注入、多样性感知 DPO)保住了单模型推理,但把多样性烘焙成了一种固定风格,模型无法在真正需要的地方精准调高。
还有一个测量缺口。
领域内报告的主要是 distinct-n / self-BLEU(词汇层)和 embedding 余弦分散度(语义层)。
这两者都看不见读者真正察觉的东西:情节的形状是否不同。
十个故事可以用完全不重叠的词汇,却仍然都是”孤儿觉醒力量,导师身亡,孤儿获胜”。
这篇论文的赌注是:把创造力做成单一模型内部可控、局部作用、被学出来的行为,并在叙事结构层面测量它。
问题: 后训练提升质量却压塌多样性
    |
    +-- 旧方案A: 提高温度 .......... 质量随多样性一起掉
    +-- 旧方案B: 基座+对齐双模型 ... 双倍显存 只有全局旋钮
    +-- 旧方案C: 多样化SFT数据 ..... 风格固定 无法控制
    |
    v
假设: 创造力是一种 *片段级* 模式
      模型可以学会自己进入和退出
    |
    v
方法: 构造带标记的数据 创造性片段用 [StartCreativity] 包裹
      SFT 让模型自己学会吐出这个标记
    |
    v
证据: (1) 在词汇 语义 及新结构指标上追平或超过
          多模型基线与蒸馏变体
      (2) 人工评测 70.3% 认为更有创造力
      (3) 从该检查点做 GRPO: AMC +约4% MATH +约5点
    |
    v
结论: 单个模型可以同时持有两个分布
      而更有创造力的那个是更好的 RL 探索底座
增量
一句话: 以前想从对齐模型里榨出基座模型的多样性,必须在推理时付费(两个模型,或一个伤害质量的温度);现在对齐模型自带一个学出来的带内开关,只在需要的片段打开多样性——而且这个开关顺带让 RL 跑得更好。
核心机制
三个部件。
第一是数据构造。
你需要这样的监督信号:“这一段适合基座模型式的不可预测”,“那一段适合后训练模型的规范能力”。
可扩展的做法是对同一个 prompt 从两个分布各自采样,然后拼接:保留后训练模型给出的结构与质量骨架,把创造性片段替换为来自基座式生成的内容,并用 [StartCreativity] 把这些片段包起来。
可扩展这件事很关键——它是本方法与”人工精选多样性数据集”的分界线。
标记不是人写的。
第二是训练。
就是在带标记语料上做普通的指令微调。
关键在于标记本身在词表里、也在 loss 里,所以模型同时学两件耦合的事:何时开启一个创造性片段(一个规划决策),以及在片段内部怎么写(一次分布迁移)。
推理时你从单个模型正常采样,标记自己会出现,最后从输出中剥掉。
想要显式旋钮的话,也可以强制或抑制这个标记。
第三是测量。
结构多样性指标把每条生成抽象成一张图——实体与事件作节点,它们之间的关系作边——然后在样本集内计算两两图编辑距离。
图编辑距离是把一张图变形为另一张所需的节点/边增、删、改标签的最小操作数。
平均距离大,意味着故事在形状上不同,不只是措辞不同。
数据构造
  prompt --+--> [ 后训练模型 ] --> 流畅 安全 但套路的初稿
           |                              |
           +--> [ 基座式模型 ] --> 古怪 多变 参差不齐
                                          |
                    v                     v
              [ 拼接 + 打标 ]  <-----------+
                    |
                    v
      "... 她推开门。[StartCreativity] 走廊不是建筑
       而是一份清单 ..."

训练
  带标记语料 --> SFT --> 单个模型 M  (标记 token 计入 loss)

推理
  prompt --> M --> tokens ... [StartCreativity] ... tokens
                     |                |
                  质量模式         创造模式
                     |                |
                     +------ 剥除标记 -----> 输出

评测
  N 个样本 --> 解析成图 --> 两两图编辑距离
      G1: (英雄)-战斗->(巨龙)-守护->(黄金)
      G2: (职员)-审计->(巨龙)-欠款->(银行)
      GED 大 ==> 结构上多样
      词汇/语义指标在这里也会响 但它们对
      "G1 换个说法" 同样会响 GED 不会
核喻:一张爵士谱。
大乐队的编曲是全写死的——每个音固定,稳定好听,每晚一模一样。
这就是后训练模型。
自由即兴则每晚都不同,有时会崩。
这就是基座模型。
而真正在用的谱子怎么做?把主题段和合奏段写满,然后印一个框:此处 solo,16 小节。
[StartCreativity] 就是那个印出来的框。
现在沿着这张谱把方法走一遍。
数据构造流程就是编曲者在决定哪些小节该写死、哪些留给 solo——而他做这个决定的方式,是同时听同一首曲子的”写死版”和”即兴版”,然后缝合。
训练是乐队排练,直到乐手内化的不只是怎么 solo,还有solo 该从哪一拍开始——不需要任何人打手势。
推理是演出:一支乐队,一份谱,侧台没有第二支管弦乐团待命(那就是多模型基线,等于另请一支即兴乐团、在两个舞台之间交叉推子)。
相比之下,调高温度等于告诉全队整晚都松着弹,包括那些必须咬紧的合奏重音——这正是它为什么要付质量代价。
RL 的那个结果也落在这个比喻里:会 solo 的乐队,在你叫它去找新东西时有更多素材可搜;只会照谱吹的乐队,搜索空间是空的。
关键概念
-
后训练导致的模式崩塌: 让 100 个人各说一种水果,原始答案会散布在苹果、芒果、柿子、榴莲上。现在按”评委最喜欢哪个答案”来奖励训练他们——所有人都收敛到”苹果”。苹果本身没错,问题是你把分布毁了。偏好优化在序列层面干的就是这件事:它把概率质量锐化到奖励模型评分最高的那条上,于是本来能写 50 个开头的模型,变成了把 1 个开头写 50 遍。病灶不是质量变低,而是在好选项上的熵变低。
-
带内控制标记: 与其从外部控制模型(改采样器、改 prompt、混入另一个模型的 logits),不如把控制信号作为特殊 token 放进文本内部,并在”该 token 确实预示分布迁移”的数据上训练。于是模型自己生成自己的控制信号。这与条件生成里的 control code、离线 RL 里的 reward-conditioned token 是同一招,只是被用在了创造力上。精妙之处在于模型自己决定放在哪里,控制因此从全局变成片段局部。
-
用图编辑距离测叙事结构: 拿两个乐高作品。你可以数各色积木的用量(词汇多样性),也可以问人们感觉是否相似(语义多样性)。或者你数把一个变成另一个所需的最少增删换操作——这就是编辑距离,它敏感于装配方式而非零件清单。用到故事上:把每个故事变成”谁对谁做了什么”的图,再问需要多少次手术式编辑才能把一个情节映射到另一个。两个人物完全不同、但都走”主角失去导师,随后复仇”的故事,图编辑距离会很小——尽管每一个名词都不一样。这正是论文说旧指标漏掉的信号。
框架转变
之前(主流方法):                    之后(本文方法):

 [ 基座模型 ]   [ RLHF 模型 ]         [ 一个 CreativeInstruct 模型 ]
      |               |                          |
      +--- 混合 logits +                   自己吐出标记
              |                                  |
              v                        +---------+---------+
        一个全局旋钮                    |                   |
      (温度 / alpha / lambda)        普通片段      [StartCreativity]
              |                        |                   |
              v                        v                   v
     多样性 <==> 质量                 质量模式          创造模式
      (此消彼长的刻度盘)                 |                   |
              |                         +-------+-----------+
              v                                 v
      推理时需要 2 个模型            单模型 + 片段级控制
                                                |
                                                v
                                        更好的 RL 起点


 之前的测量:                          之后的测量:
   distinct-n self-BLEU  (词)          + 事件图上的
   embedding 余弦        (义)            图编辑距离 (形)
一句话:从**在推理时于两个模型之间调一个全局旋钮*,到让一个模型学会自己开合创造性片段,核心转变是把多样性控制从采样器搬进模型自己的 token 流里。
专家评审
先说一个前提:我依据的是摘要和周边文献的形状,不是对数据构造章节的完整通读——所以我对方法的重建请当作一种合理读法而非已核实的事实,实验批评也请据此打折。
选题眼光: 真缺口,位置也占得好。
后训练造成的多样性崩塌是领域内真正未解的实用问题之一,而摘要里”它也伤害了隐式需要创造力的任务,尤其是 RL 探索”这句话是最有价值的一句。
越来越多证据表明,从低熵策略出发的 RL 基本只是在给策略已有的行为重排序,所以”创造力作为探索底座”正是领域注意力正在移动的方向。
这篇论文是在骑一波真浪,不是在造缺口。
方法成熟度: 巧,但巧在包装而非原语。
带内控制标记是老东西(control code、reward token、质量条件预训练);贡献在于把它用在片段粒度上服务创造力,并自动构造带标记数据。
这是个好主意,而自动拼接流程正是真风险所在:拼接质量决定一切,我想看到”哪些片段该创造”这个启发式有多脆。
值得被显式驳倒的更简单基线有两个:min-p 或熵目标采样(远强于朴素温度,而且免费),以及直接蒸馏基座输出再做轻量质量过滤。
摘要说比较了蒸馏变体,这个直觉是对的。
实验诚意: 站在海报前我会追问两点。
第一,论文自己提出了主打的多样性指标,然后在这个指标上赢了。
这不构成否决——总得有人提新指标——但自创且偏向自家方法的指标需要独立验证,而人工评测本该承担这个活。
70.3% 的创造力偏好是不错的信号,但创造力偏好本身并不能解决质量问题;我想要的是同时给出的成对质量判断,而不是另一个自动质量分。
第二,RL 数字是最抢眼的宣称,却是最薄的证据:AMC 是个很小的基准(几十道题),“+4%“可能就是一两道题;而单种子的 GRPO 对比出了名地噪。
要多种子加方差,否则这个结果只能降级为”有启发性”。
写作功力: 按摘要的着力点推断,软肋大概是数据构造的描述——它最承重,也最容易被压缩成”我们拼接并打标”。
我最想被重写的是 RL 实验:如果作者把它扩展到更多基准、多种子,并加一个熵分析说明为什么创造性检查点探索得更好,仅这一节就能把论文从”不错的方法论文”推到”领域会引用的结果”。
现在它读起来像一个被提拔进摘要的有潜力的附录。
判决: 弱接收 — 机制扎实且明显有用,但两个最激动人心的宣称(新结构指标、RL 迁移)各自的证据都比宣称薄一档。
要点总结
可以直接搬走用在别处的东西:
片段级控制标记是个通用范式。
任何时候你想让模型在输出的局部表现不同——这里更简洁、那里更严谨、这一段更敢推测——你都可以从两个不同来源的生成里拼接出带标记数据,让模型同时学会放置位置和相应行为。
它远远超出创造力:详略控制、必须给引用的片段、“我这里在猜”的片段、代码里该防御 vs 该快的段落。
让模型自己吐出控制信号。
它优于 prompt 或采样器开关的原因是:放置决策本身是从数据里学来的。
如果你一直用系统提示解决控制问题,先问一句:何时施加控制,是不是本该由模型学?
在结构化抽象上做编辑距离,可作多样性指标。
如果你的输出有结构——API 调用序列、SQL 查询计划、测试套件、agent 轨迹、分子——抽象成图,用图编辑距离替代 embedding 余弦。
embedding 告诉你两个输出感觉是否不同,编辑距离告诉你它们构造是否不同。
这一条立刻可移植,而且便宜。
检查你 RL 起点的熵。
论文里最可操作的一条:如果你在跑 GRPO/PPO 并且卡住了,问题可能是你的 SFT 检查点已经把你想搜索的那个分布压塌了。
在调 RL 配方之前,先量一下初始化的熵和采样多样性。
一个要带走的诚实警告: 它取代的多模型基线其实并不算贵。
如果显存充裕,基座+对齐的对比解码是一个很强的、无需训练的基线。
CreativeInstruct 最站得住的场景是:你必须单模型部署,或者你想拿创造性检查点当 RL 起点。