Paper: 2607.05377 Authors: Jiaqi Peng, Xiqian Yu, Delin Feng, Yuqiang Yang, Wenzhe Cai, Jing Xiong, Ganlin Yang, Jinliang Zheng, Jiafei Cao, Xueyuan Wei Categories: cs.RO, cs.AI, cs.CV
The Gap
Current research has two competing approaches for embodied manipulation, and both hit walls.
Monolithic VLA models (like RT-2, OpenVLA) take in an image and language instruction, output actions directly. They’re end-to-end, which is elegant, but they’re fundamentally Markovian — each decision only sees the current frame. Ask them to “pick up the cup, pour water, then place it on the shelf” and they lose the thread halfway through. They have no internal plan, no memory of what step they’re on.
Hierarchical dual-system methods (like SayCan, Code as Policies, CaP) try to fix this by splitting the problem: a high-level VLM plans subtasks, a low-level policy executes them. But here’s the catch — there’s a semantic-kinematic gap. The VLM says “pour the liquid” but the VLA doesn’t know what “pour” means in terms of joint angles and gripper poses. The plans are semantically rich but kinematically vague. The robot either can’t execute them or executes them incorrectly.
Cortex sits squarely at this gap. The insight: you need a shared language between planner and executor — one that’s both semantically meaningful to the VLM and kinematically precise enough for the VLA.
Problem:  VLA fails on long-horizon (Markovian)
              |
              v
Prior fix: Hierarchical VLM -> VLA
              |
              v
Residual gap: Semantic plans != Executable actions
              |
              v
Assumption: Standardized skill primitives can bridge this gap
              |
              v
Method: 32 canonical primitives + bidirectional alignment
         + 4k-hour auto-annotated data + event-balanced sampling
              |
              v
Evidence: +3.1% Libero-long, +4.1% RoboTwin
          + zero-shot real-world chemistry experiments
              |
              v
Conclusion: Standardized executable interface unlocks
            long-horizon manipulation for hierarchical agents
The Increment
One sentence: Before Cortex, hierarchical robot systems had a broken communication channel between planning and execution — after Cortex, they share a bidirectionally aligned vocabulary of 32 standardized skill primitives that are simultaneously meaningful to language models and executable by action models.
Core Mechanism
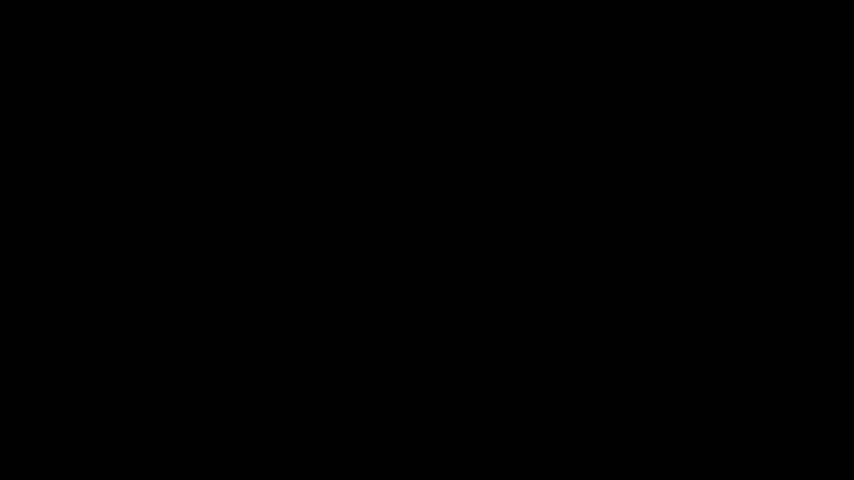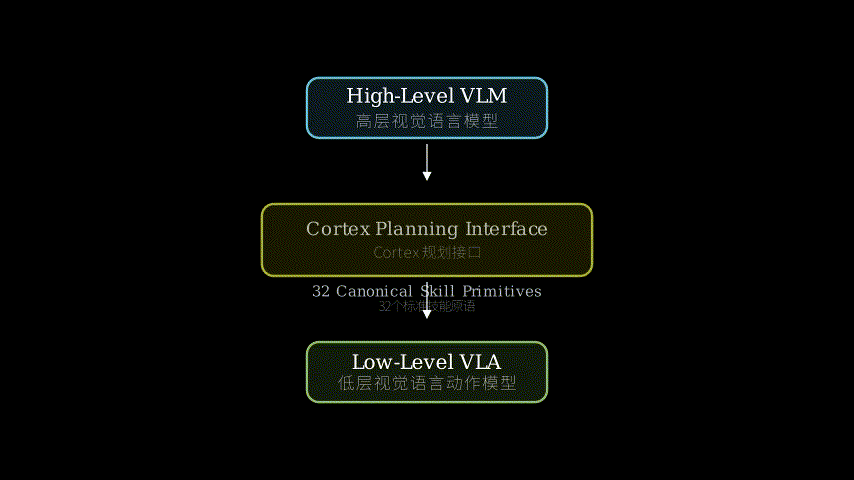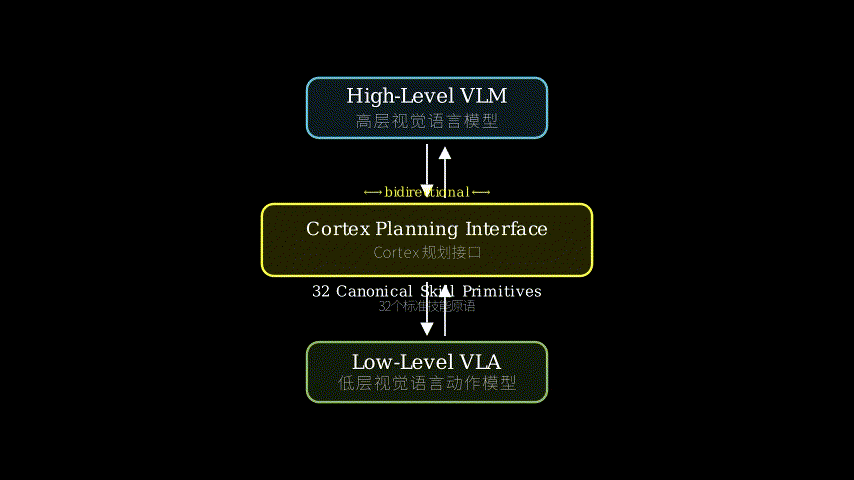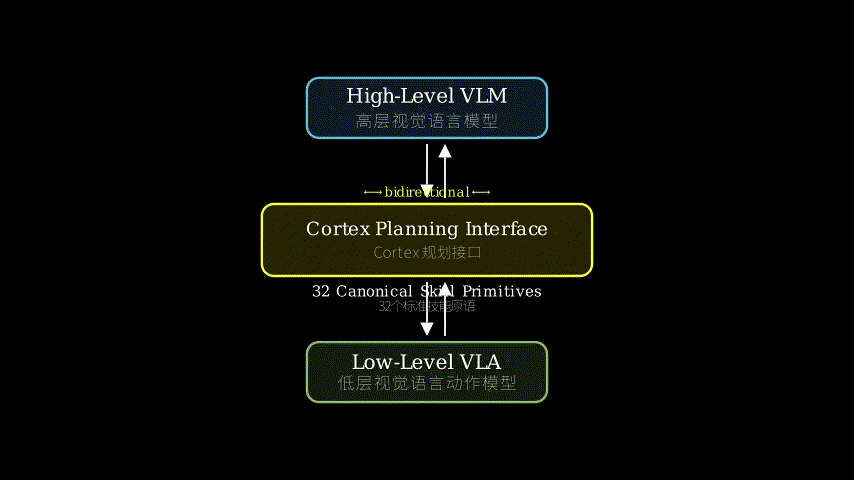
Cortex has three tightly coupled layers: a high-level VLM (the planner), a low-level VLA (the executor), and a customized planning interface between them that translates in both directions.
The VLM receives a task description and current observation, then decomposes it into subtask sequences. But unlike prior work where subtasks are free-form natural language, Cortex constrains them to 32 canonical skill primitives — things like “grasp(object)”, “pour(source, target)”, “place(location)”. Each primitive has standardized parameters (object attributes, spatial relations) that the VLA has been specifically trained to execute.
The data pipeline is where the heavy lifting happens. The authors inject tractability principles into data generation: they identify representative object attributes (shape, size, affordance) and ensure trajectory reachability. This lets them automatically annotate over 4,000 hours of open-source manipulation video and generate 30 hours of simulation data with ground-truth primitive labels. An event-balanced sampling strategy ensures the training data covers transitions between subtasks — the exact moments where ambiguity is highest.
During inference, harness engineering provides additional guardrails: task context is encoded to help the VLM plan correctly, and skill constraints are applied to keep the VLA in executable regions of the action space.
Task Description
      |
      v
[High-Level VLM] --plans--> Subtask Sequence
      |                            |
      |                      (32 canonical
      |                       primitives)
      v                            v
[Planning Interface] <-----> [Low-Level VLA]
  |        |                     |
  |        |                     |
  v        v                     v
Skill     Tractability       Action
Primitives  Principles       Execution
  |                             |
  +------- Event-Balanced ------+
            Sampling
                  |
                  v
         4k+ hr auto-annotated
           video + 30hr sim
Structural Metaphor
Think of Cortex like a restaurant kitchen with a head chef and line cooks.
In a badly run kitchen (prior hierarchical methods), the head chef (VLM) shouts vague instructions: “Make it taste better!” or “Plate it nicely!” The line cooks (VLA) stare blankly — they need to know exactly which pan, which burner, which garnish. There’s a communication gap between culinary vision and kitchen execution.
Cortex fixes this by establishing a standardized ticket system (the 32 skill primitives). The head chef now writes tickets that say: “Sauté [protein=chicken, size=diced] in [pan=cast-iron, heat=medium-high] for [duration=4min]”. Every ticket uses the same format. Every line cook knows exactly what each term means in terms of hand movements.
But here’s the clever part — the system is bidirectional. The line cooks also provide feedback through the ticket system: “That pan is already in use” or “The burner takes 3 minutes to heat up.” This constraints feedback flows back to the head chef, who adjusts the plan accordingly.
The tractability principles are like the kitchen’s mise en place rules — you can’t write a ticket for “julienne the truffle” if the kitchen doesn’t have truffles. The system checks what’s actually available and reachable before generating plans.
The event-balanced sampling is like training new cooks on the hardest moments — not the easy parts where everything is calm, but the transitions: “The pasta is done, the sauce is almost done, and you need to time the plating.” Those transitional moments are where chaos happens, so you train on them disproportionately.
The harness engineering during inference is like having a kitchen manager who walks around making sure no one puts metal in the microwave — real-time guardrails that catch mistakes before they cascade.
Key Concepts
-
Canonical Skill Primitives: Imagine you’re teaching someone to cook, but instead of teaching “make an omelette,” you teach them 32 fundamental techniques: crack, whisk, heat, fold, plate, etc. Every recipe in the world can be decomposed into combinations of these 32 techniques. That’s what Cortex does for manipulation. Rather than letting the VLM invent arbitrary subtask descriptions, it maps everything to 32 standardized primitives. Each primitive has a defined input schema (what objects, what parameters) and the VLA is trained specifically on executing each one. The beauty is that the VLM only needs to learn *when to invoke which primitive — it doesn’t need to learn kinematics.
-
Tractability Principles: This is the “reality check” baked into the system. When generating training data, Cortex doesn’t just say “here’s a video of someone pouring water.” It extracts tractable information: what’s the object’s shape? How heavy does it look? Can the robot actually reach it from this angle? By injecting these constraints into the data annotation pipeline, the system learns plans that are not just semantically correct but *physically plausible. Think of it as the difference between a recipe written by someone who’s never cooked (“cook until done”) versus a chef (“cook until the internal temperature reaches 165°F”).
-
Event-Balanced Sampling: Most training data for sequential tasks is dominated by the “boring middle” — the steady-state moments where the robot is just moving smoothly. But the hard parts are the *transitions: picking up object A and switching to object B, finishing one subtask and starting the next. Event-balanced sampling deliberately oversamples these transition moments so the model learns to handle ambiguity at exactly the points where it fails most. It’s like a driving school that spends 50% of practice time on merging and lane changes rather than straight highway cruising.
Framework Shift
Before (mainstream approach):           After (this paper):

  "Make breakfast"                     "Make breakfast"
       |                                    |
       v                                    v
  [VLM generates                        [VLM generates
   free-form plan]                       primitive plan]
       |                                    |
       v                                    v
  "Pour cereal",                        grasp(cereal_box)
  "add milk"                            pour(milk, bowl)
  (semantically vague)                  place(bowl, table)
       |                                (kinematically precise)
       v                                    |
  [VLA guesses                             v
   what "pour"                          [VLA executes
   looks like]                           each primitive]
       |                                    |
       v                                    v
  ??? (semantic-kinematic                Aligned: plan IS
       gap)                              executable plan
From free-form natural language subtasks to standardized skill primitives, the core shift is making the planning interface executable by construction rather than hoping semantics and kinematics magically align downstream.
Expert Assessment
Problem choice: This is a real and well-identified gap. The semantic-kinematic divide in hierarchical robot systems has been acknowledged by many (SayCan’s grounding, CaP’s code generation) but rarely addressed head-on with a principled interface design. It’s the right problem at the right time — as VLMs get more capable at reasoning, the bottleneck shifts to the execution interface.
Method maturity: The 32-primitive design is clever but somewhat brittle. Who decides which 32? What happens when a task requires a 33rd primitive not in the taxonomy? The paper doesn’t discuss extensibility or failure modes when primitives don’t match. The tractability principles are the paper’s strongest conceptual contribution — injecting physical plausibility into planning is a genuine insight. The data pipeline (auto-annotating 4k hours) is impressive engineering, but raises questions about annotation quality and error propagation.
Experimental integrity: The benchmarks (Libero-long, RoboTwin) are appropriate for long-horizon evaluation. The 3-4% improvements are modest but consistent. The zero-shot real-world chemistry experiment is the most compelling evidence — it demonstrates genuine compositional generalization. However, the paper would benefit from more ablation: how much does the primitive standardization help vs. the data scale? How sensitive is performance to the choice of 32 primitives? The baselines seem fair but I’d like to see more recent hierarchical approaches compared.
Writing quality: The paper reads well technically but cuts corners on failure analysis. Section 4 (experiments) could be stronger with error case studies — when does Cortex fail and why? The related work section adequately positions the contribution. The harness engineering details in Section 3.4 feel underspecified — this is where many practical systems succeed or fail, and the paper treats it as an afterthought.
Verdict: weak accept — The bidirectional alignment concept is valuable and the standardized primitive approach is worth the community’s attention, but the modest empirical gains and limited ablation prevent a stronger endorsement.
Takeaways
Three concrete ideas to steal:
-
Standardized interface layers for hierarchical systems: If you’re building any system with a planner and executor, define a constrained shared vocabulary. Don’t let the planner speak free-form English to the executor. This principle applies beyond robotics — think code generation, multi-agent systems, or any pipeline where a “smart” module feeds a “precise” module.
-
Inject domain constraints into data generation: The tractability principle is broadly applicable. When curating training data, don’t just collect examples — annotate them with physical or structural constraints that make the data “executable” in your domain. This makes your model’s outputs more grounded.
-
Oversample transitions in sequential data: If your model handles sequences, your training data is probably biased toward steady states. Deliberately rebalance toward transitions and boundaries — that’s where models fail and where learning efficiency is highest. This is essentially curriculum learning for temporal structure.
论文: 2607.05377 作者: Jiaqi Peng, Xiqian Yu, Delin Feng, Yuqiang Yang, Wenzhe Cai, Jing Xiong, Ganlin Yang, Jinliang Zheng, Jiafei Cao, Xueyuan Wei 分类: cs.RO, cs.AI, cs.CV
缺口
当前研究有两条路线,都撞了墙。
端到端VLA模型(如RT-2、OpenVLA)直接从图像和语言指令输出动作。 优雅是优雅,但本质上是马尔可夫的——每步决策只看当前帧。 让它”拿起杯子、倒水、放到架子上”,它走到一半就忘了自己在干嘛。 没有内部规划,没有步骤记忆。
层级式双系统方法(如SayCan、Code as Policies)试图修复这个问题: 高层VLM规划子任务,低层策略执行。 但问题在于——语义-运动学之间有鸿沟。 VLM说”倒液体”,但VLA不知道”倒”在关节角度和夹爪姿态上意味着什么。 计划语义丰富,但运动学上模糊。 机器人要么执行不了,要么执行错。
Cortex就站在这条鸿沟的正中间。 核心洞察:需要一个双向共享语言——既要对VLM语义上有意义,又要对VLA运动学上精确。
问题:VLA在长时序任务上失败(马尔可夫性)
              |
              v
此前的方案:层级式 VLM -> VLA
              |
              v
残余缺口:语义计划 != 可执行动作
              |
              v
假设:标准化技能原语可以弥合这一缺口
              |
              v
方法:32个标准原语 + 双向对齐
      + 4000小时自动标注数据 + 事件均衡采样
              |
              v
证据:Libero-long +3.1%,RoboTwin +4.1%
      + 零样本完成真实世界化学实验
              |
              v
结论:标准化可执行接口解锁了
      层级式智能体的长时序操作能力
增量
一句话:在Cortex之前,层级式机器人系统的规划层和执行层之间通信是断裂的;在Cortex之后,它们共享一套由32个标准化技能原语组成的双向对齐词汇表,这套词汇表同时对语言模型有意义、对动作模型可执行。
核心机制
Cortex有三个紧密耦合的层级:高层VLM(规划者)、低层VLA(执行者)、以及两者之间的定制化规划接口,实现双向翻译。
VLM接收任务描述和当前观察,将其分解为子任务序列。 但不同于之前用自由形式自然语言表达子任务的做法,Cortex将其约束为32个标准技能原语——比如”grasp(物体)”、“pour(源,目标)”、“place(位置)”。 每个原语都有标准化参数(物体属性、空间关系),VLA被专门训练来执行这些原语。
数据管线是重头戏。 作者向数据生成中注入了可执行性原则:识别代表性物体属性(形状、大小、可供性)并确保轨迹可达性。 这让他们能够自动标注超过4000小时的开源操作视频,并生成30小时带真实原语标签的仿真数据。 事件均衡采样策略确保训练数据覆盖子任务之间的过渡——这些恰恰是歧义最大的时刻。
推理阶段,约束工程提供了额外保障:编码任务上下文帮助VLM正确规划,施加技能约束将VLA限制在可执行的动作空间区域内。
任务描述
      |
      v
[高层 VLM] --规划--> 子任务序列
      |                     |
      |               (32个标准
      |                原语)
      v                     v
[规划接口] <-----------> [低层 VLA]
  |        |                |
  |        |                |
  v        v                v
技能    可执行性         动作
原语    原则             执行
  |                        |
  +------- 事件均衡 --------+
            采样
                  |
                  v
         4000+小时自动标注
        视频 + 30小时仿真
核喻
把Cortex想象成一个有总厨和厨师团队的餐厅厨房。
在一个管理混乱的厨房里(此前的层级方法),总厨(VLM)喊模糊指令:“做得好吃点!""摆盘漂亮点!“厨师们(VLA)面面相觑——他们需要知道具体用哪口锅、哪个灶、什么配料。烹饪愿景和厨房执行之间有沟通鸿沟。
Cortex通过建立标准化订单系统(32个技能原语)来修复这个问题。 总厨现在写的订单是这样的:“中高温铸铁锅翻炒[食材=鸡肉,切法=丁],[时长=4分钟]”。 每个订单格式一致,每个厨师都清楚每个术语对应什么手部动作。
但妙处在于——系统是双向的。 厨师也通过订单系统反馈:“那口锅正在用”或”这个灶要预热3分钟”。 这些约束信息回流给总厨,总厨据此调整计划。
可执行性原则就像厨房的备料规则——你不能写”切松露丝”的订单,如果厨房没有松露。 系统在生成计划前会检查什么是实际可用和可达的。
事件均衡采样就像训练新厨师应对最困难的时刻——不是一切平静的轻松时段,而是过渡时刻:“意面好了,酱汁快好了,你需要把握上盘时机。“那些过渡时刻正是混乱发生的地方,所以要重点训练。
推理时的约束工程就像厨房巡场经理,确保没人把金属放进微波炉——实时的防护栏,在错误级联之前将其拦住。
关键概念
-
标准技能原语:想象你在教人做菜,但不是教”做一份蛋卷”,而是教32种基础技法:打蛋、搅打、加热、折叠、摆盘…… 世界上任何菜谱都能分解为这32种技法的组合。 Cortex对操作做了同样的事。 它不允许VLM随意编造子任务描述,而是将一切映射到32个标准原语。 每个原语有定义好的输入格式(哪些物体、哪些参数),VLA专门训练执行每个原语。 精妙之处在于:VLM只需要学会何时调用哪个原语——它不需要学运动学。
-
可执行性原则:这是嵌入系统的”现实检查”。 生成训练数据时,Cortex不是简单地说”这是一段倒水的视频”。 它提取可执行的信息:物体什么形状?看起来多重?从这个角度机器人够得着吗? 通过将这些约束注入数据标注管线,系统学到的计划不仅语义正确,而且物理上可行。 这就像从未下过厨的人写的菜谱(“煮到熟”)和真正厨师写的菜谱(“内部温度达到74度”)之间的区别。
-
事件均衡采样:顺序任务的大多数训练数据都被”无聊的中间段”主导——机器人平稳运动的稳态时刻。 但最难的部分是过渡:拿起物体A切换到物体B,完成一个子任务开始下一个。 事件均衡采样故意对这些过渡时刻过采样,让模型学会处理它最容易失败的歧义点。 这就像驾校把50%的练习时间花在并线和变道上,而不是一直跑直线高速。
框架转变
之前(主流方法):                   之后(本文方法):

  "做早餐"                         "做早餐"
       |                                |
       v                                v
  [VLM生成                          [VLM生成
   自由形式计划]                      原语计划]
       |                                |
       v                                v
  "倒麦片"、                        grasp(麦片盒)
  "加牛奶"                          pour(牛奶, 碗)
  (语义模糊)                        place(碗, 桌子)
       |                            (运动学精确)
       v                                |
  [VLA猜测                            v
   "倒"是什么样的]                  [VLA执行
       |                             每个原语]
       v                                |
  ???(语义-运动学                     v
       鸿沟)                       对齐:计划本身
                                    就是可执行计划
从自由形式自然语言子任务到标准化技能原语,核心转变是让规划接口从构造上就可执行,而不是寄希望于语义和运动学在下游自动对齐。
专家评审
选题眼光:这是一个真实且识别精准的缺口。 层级机器人系统中的语义-运动学鸿沟已被多人认知(SayCan的接地、CaP的代码生成),但很少有人正面用原则性的接口设计来解决。 这是正确时间的正确问题——随着VLM推理能力增强,瓶颈转移到了执行接口上。
方法成熟度:32个原语的设计巧妙但有些脆弱。 谁来决定哪32个?当任务需要第33个不在分类中的原语时怎么办? 论文没有讨论可扩展性或原语不匹配时的失败模式。 可执行性原则是论文最强的概念贡献——向规划中注入物理可行性是真正的洞见。 数据管线(自动标注4000小时)是令人印象深刻的工程,但引发了关于标注质量和错误传播的疑问。
实验诚意:基准测试(Libero-long、RoboTwin)适合长时序评估。 3-4%的提升虽然不大但一致。 零样本真实世界化学实验是最有说服力的证据——展示了真正的组合泛化能力。 但论文需要更多消融实验:标准化原语的帮助有多大vs数据规模的影响? 当32个原语的选择变化时,性能敏感度如何? 基线看起来公平,但希望能看到更多近期层级方法的对比。
写作功力:论文技术层面写得流畅,但在失败分析上偷懒了。 第4节(实验)如果加上错误案例分析会更强——Cortex什么时候失败、为什么失败? 约束工程的细节在3.4节感觉不够详细——这往往是实际系统成败的关键,论文却把它当成了附带内容。
判决:弱接收——双向对齐的概念有价值,标准化原语方法值得关注,但实证提升有限、消融不足,无法给出更强的评价。
要点总结
三个可以”偷”走的具体想法:
-
层级系统的标准化接口层:如果你在构建任何有规划器和执行器的系统,定义一个约束化的共享词汇表。不要让规划器用自由英语和执行器对话。这一原则超越机器人领域——想想代码生成、多智能体系统、或任何”聪明”模块向”精确”模块输送信息的管线。
-
向数据生成注入领域约束:可执行性原则具有广泛适用性。整理训练数据时,不要只收集样本——用物理或结构约束来标注它们,让数据在你的领域中”可执行”。这让你的模型输出更加落地。
-
在序列数据中过采样过渡段:如果你的模型处理序列,你的训练数据大概率偏向稳态。刻意对过渡和边界重新平衡——那里才是模型失败的地方,也是学习效率最高的地方。这本质上是针对时间结构的课程学习。