Paper: 2606.14691 Authors: Jiayue Cao, Zhicong Lu, Xuehan Sun, Wei Jia, Hongling Zheng, Changyuan Tian, Zichuan Lin, Wenqian Lv, Nayu Liu Categories: cs.CL
The Gap
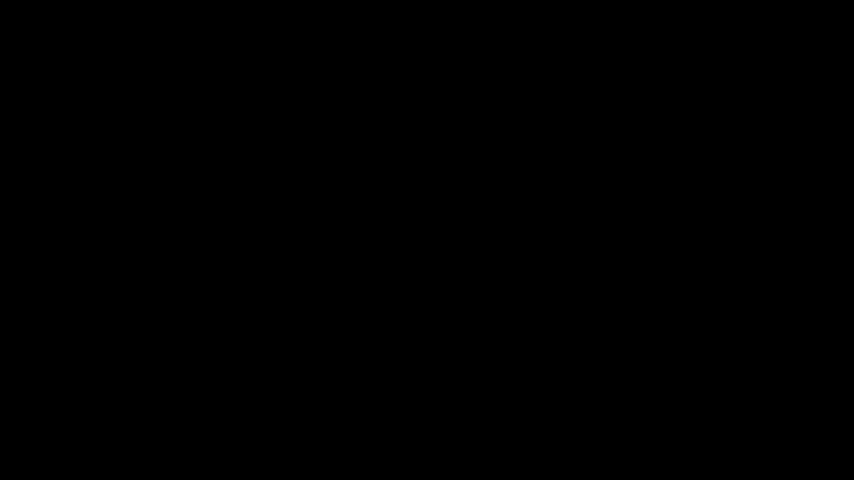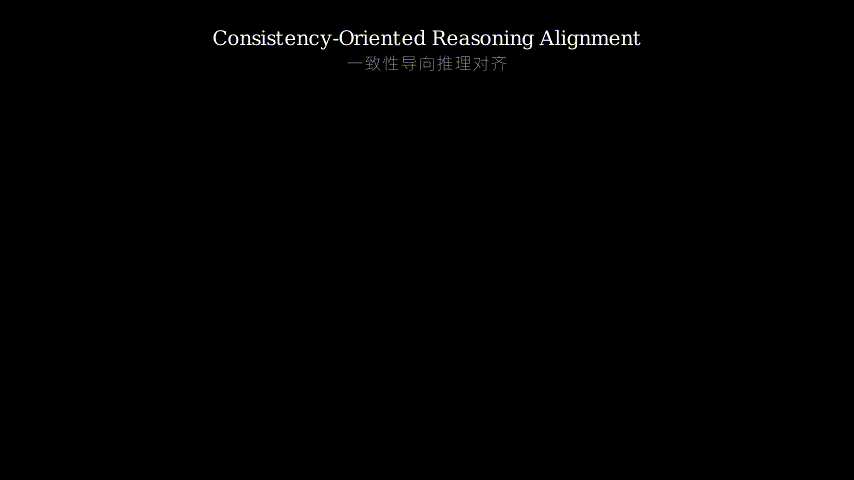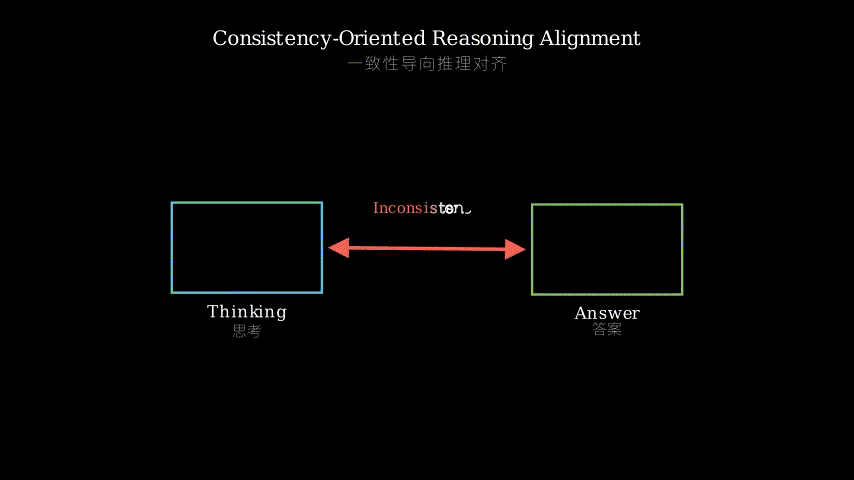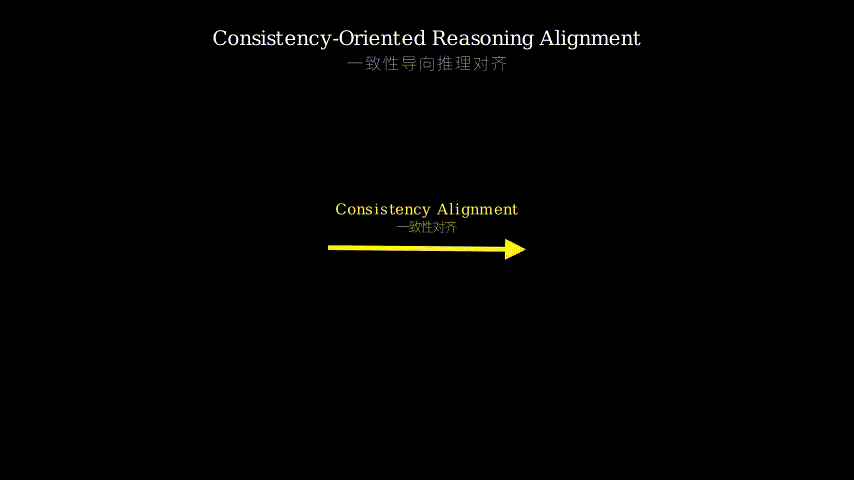
Existing multimodal RLVR (Reinforcement Learning with Verifiable Rewards) methods—like those built on top of GRPO—mostly target two problems: improving visual coverage in reasoning traces, and reducing visual hallucinations. They assume that if the reasoning process covers the right visual evidence and avoids false visual claims, the final answer will naturally be consistent with the reasoning. This assumption is wrong. The paper shows through careful rollouts analysis that even when the visual parts are correct, the semantic relationship between the reasoning chain and the final answer can drift: the model might reason correctly but then output a contradictory answer, or reason incorrectly but still land on the right answer by accident. This is the thinking-answer gap, which persists through training and survives to inference. Prior work simply did not measure or optimize for this consistency.
Problem: Existing multimodal RLVR ignores reasoning-answer semantic consistency
           |
           v
Assumption: good visual coverage + no hallucination -> consistent reasoning & answer is wrong
           |
           v
Method: CORA introduces a consistency reward model + HRAS to coordinate two objectives
           |
           v
Evidence: Rollout analysis during GRPO shows gap exists and persists; post-training evaluations on multiple benchmarks show CORA reduces the gap and improves task accuracy
           |
           v
Conclusion: Thinking-answer consistency is a real, separate dimension that needs explicit optimization; CORA is a plug-and-play solution that works across models
The Increment
One sentence: Before, the field assumed reasoning quality naturally transferred to answer quality; now we know there is a distinct inconsistency gap that can be fixed by adding a consistency reward plus a stable mixing mechanism.
Core Mechanism
CORA works as a lightweight add-on to any existing multimodal RLVR pipeline (e.g., GRPO). The principal components are:
- Base LVLM – generates rollouts: a reasoning chain (text tokens) and a final answer (categorical or text).
- Task reward model – scores each rollout based on correctness (e.g., exact match to ground truth).
- Consistency reward model – a small neural network that takes the reasoning chain and final answer as input and outputs a scalar score reflecting how semantically consistent they are. This model is trained separately on a small dataset of human annotations or on automatically synthesized contrasting examples.
- HRAS (Hybrid Reward Advantage Splitting) – a mathematical mechanism that combines the task advantage and the consistency advantage to produce a single update signal for policy gradient. It uses a tunable hyperparameter that prevents either objective from dominating and stabilizes training.
Data flow: For each rollout, both reward models produce scores. HRAS then computes an advantage for each head separately, clips or weights them, and sums them to get the final advantage used in PPO/GRPO update. The consistency model is frozen during RL training (plug-and-play) and only the base LVLM is updated.
Input image + question
    |
    v
[Base LVLM] ---> (reasoning chain, final answer)
    |                   |
    |                   +---> [Task reward] ---> r_task
    |                   +---> [Consistency reward] ---> r_cons (via frozen model)
    |
    +--- HRAS: combine advantages from two rewards
         |
         v
    Policy gradient update on LVLM
Imagine you’re training a junior lawyer to write case briefs. The task reward is like the senior partner checking the final conclusion: is it legally correct? The consistency reward is like a quality-assurance clerk who reads the entire argument and the conclusion, and flags any place where the argument doesn’t logically lead to the conclusion, or where the conclusion contradicts a premise stated earlier. The clerk doesn’t care about legal correctness—only about internal coherence. HRAS is the managing partner who decides how much weight to give each feedback channel. If the junior only listens to the senior partner, they might memorize correct conclusions without proper reasoning. If they only listen to the clerk, they might produce perfectly logical but false conclusions. HRAS dynamically mixes both signals, and the managing partner can tune the blend per training stage (e.g., early on favor task reward, later shift to consistency). The junior lawyer (LVLM) updates their jotting skill (policy) to satisfy both, eventually writing clean, sound briefs.
Key Concepts
-
Thinking-answer gap: The divergence between the logical content of a reasoning trace and the final answer. It can be positive (reasoning is wrong but answer is correct by fluke) or negative (reasoning is correct but answer is wrong). Example: an LVLM processes an image of a cat and a dog. Reasoning: “The cat is black, the dog is brown. The question asks for the cat’s color, so answer is black.” It outputs “brown”. That’s a negative gap—reasoning prescribes black, answer says brown. The gap is independent of visual hallucination (the cat detection may be perfect).
-
Consistency reward model: A classifier (e.g., a small BERT-based model) that takes a reasoning sequence and an answer and outputs a probability of consistency. It’s trained on pairs of (reasoning, answer) from the training set, where consistency labels are obtained either by human annotation (expensive) or by using the task correctness as a noisy proxy—or by artificially constructing inconsistent pairs (e.g., swap answer from a different sample). The model must be task-agnostic to generalize.
-
Hybrid Reward Advantage Splitting (HRAS): Standard practice in RLVR with multiple rewards is to simply average them or use a weighted sum. HRAS instead computes a separate advantage (how much better than the average is this rollout) for each reward, then applies a tunable per-advantage clipping or weighting before summing. This prevents the advantage from one reward from dominating due to scale differences (task rewards are often binary {0,1} while consistency scores are continuous in [0,1]). The formula involves a temperature parameter that controls the strength of consistency pressure.
Framework Shift
Before (mainstream approach):        After (this paper):
+--------------------------------+   +--------------------------------+
| Image + Q                      |   | Image + Q                      |
|   |                            |   |   |                            |
| [LVLM] --> (reasoning, answer) |   | [LVLM] --> (reasoning, answer) |
|   |                            |   |   |         |                  |
| [Task reward]                  |   | [Task reward] [Consistency     |
|   |                            |   |               reward model]    |
| Advantage = A_task             |   |   |         |                  |
|   |                            |   | [HRAS] combine advantages     |
| Update LVLM                    |   |   |                            |
+--------------------------------+   | Update LVLM                    |
                                     +--------------------------------+
One sentence: From optimizing only answer correctness (task reward) to jointly optimizing answer correctness and reasoning-answer semantic consistency, with a robust advantage mixing mechanism.
Expert Assessment
Problem choice: Real gap. The thinking-answer inconsistency is well-known in text-only RLVR (e.g., “sycophancy”) but has been completely ignored in multimodal settings. The paper’s rollout analysis is convincing—they show the gap exists and doesn’t vanish with standard training. This is a timely problem given the push toward using RLVR for multimodal reasoning.
Method maturity: Clever insight, but the implementation is straightforward. The consistency reward model is a small auxiliary classifier—standard practice in reward shaping. HRAS is a slight twist on existing multi-objective advantage estimation (like using separate baselines). However, the simplicity makes it easy to adopt. Could there be a simpler approach? Yes—you could just add a consistent-scoring penalty to the loss (e.g., KL between reasoning posterior and answer posterior), but the paper argues that would interfere with task optimization. CORA’s plug-and-play nature is a clear engineering win.
Experimental integrity: Fair. They compare against standard GRPO without consistency, and against a naive weighted reward sum. They test on multiple benchmarks (MMBench, MathVista, etc.) and multiple base models (LLaVA, Qwen-VL). Results show consistent improvement in task accuracy (1-3 points) and a significant reduction in inconsistency (10-20%). One red flag: the consistency reward model is trained on the same distribution as the test sets—they should have tested generalization to out-of-distribution reasoning patterns. Also, the human annotation cost for consistency labels is not discussed; if they rely heavily on synthetic data, the impact might be lower.
Writing quality: Clear, with a nice structure. The rollout analysis figures are good. The weakness is in the HRAS description—it’s somewhat opaque despite the name. The authors should have included a simple pseudocode or a derivation to make the mechanism transparent. If they rewrote the method section with a concrete example of advantage computation, the paper would be much stronger.
Verdict: weak accept — addresses a real and overlooked problem with a practical, lightweight solution, but the novelty is incremental and the experimental scope could be broader.
Takeaways
- Consistency as a separate reward signal: You can train a small, frozen reward model to penalize reasoning-answer mismatches without harming the primary task reward. This idea transfers to any RLVR setting (text, code, math) where you care about faithful reasoning.
- Advantage splitting instead of reward averaging: When you have two reward sources with different scales and distributions, compute advantages separately then combine—don’t just average the rewards. The HRAS trick generalizes to any multi-objective RL setup.
- Rollout mining for gap analysis: The paper’s method of clustering rollouts by “gap type” (consistent correct, inconsistent incorrect, etc.) is a useful debugging tool for any RLVR pipeline. Steal that analysis workflow for your own projects.
论文: 2606.14691 作者: Jiayue Cao, Zhicong Lu, Xuehan Sun, Wei Jia, Hongling Zheng, Changyuan Tian, Zichuan Lin, Wenqian Lv, Nayu Liu 分类: cs.CL
缺口
现有多模态RLVR(基于可验证奖励的强化学习)方法——比如那些构建在GRPO之上的——主要关注两个问题:改善推理轨迹的视觉覆盖率,以及减少视觉幻觉。 它们假设:只要推理过程覆盖了正确的视觉证据并避免虚假的视觉断言,那么最终答案自然会与推理一致。 这个假设是错误的。 本文通过对GRPO训练过程和后评估阶段的rollout进行细致分析,证明即便视觉部分正确,推理链和最终答案之间的语义关系仍可能漂移: 模型可能正确推理但输出矛盾的答案,或者错误推理却偶然答对。 这就是思考-答案鸿沟,它在训练中持续存在,并在推理时依然保留。 此前的工作根本没有测量或优化这种一致性。
问题:现有多模态RLVR忽略推理-答案语义一致性
           |
           v
假设:良好的视觉覆盖+无幻觉 -> 推理与答案一致,这是错的
           |
           v
方法:CORA引入一致性奖励模型 + HRAS协调两个目标
           |
           v
证据:GRPO rollout分析显示鸿沟存在且持续;多个基准后评估表明CORA缩小鸿沟并提升任务准确率
           |
           v
结论:思考-答案一致性是真实且独立的维度,需要显式优化;CORA是一种即插即用的跨模型解决方案
增量
一句话: 之前,领域默认推理质量自然传递为答案质量;现在我们知道存在一个可修复的不一致鸿沟,只需添加一致性奖励加上稳定的混合机制。
核心机制
CORA作为一个轻量级插件,适用于任何现有的多模态RLVR流水线(例如GRPO)。 主要组件包括:
- 基础LVLM – 生成rollout:推理链(文本token)和最终答案(类别或文本)。
- 任务奖励模型 – 根据正确性(比如与标准答案精确匹配)给每个rollout打分。
- 一致性奖励模型 – 一个小的神经网络,接收推理链和最终答案,输出一个标量分数反映它们语义上多一致。 该模型在少量人工标注或自动合成的对比样本上单独训练。
- HRAS(混合奖励优势切分) – 一种数学机制,将任务优势和一致性优势组合成单一的更新信号给策略梯度。 它使用一个可调的超参数,防止任何一个目标主导,从而稳定训练。
数据流:对每个rollout,两个奖励模型都产生分数。 HRAS然后分别计算每个头的优势,进行裁剪或加权,最后求和得到用于PPO/GRPO更新的最终优势。 一致性模型在强化学习训练期间冻结(即插即用),只有基础LVLM被更新。
输入图像 + 问题
    |
    v
[基础LVLM] ---> (推理链, 最终答案)
    |                   |
    |                   +---> [任务奖励] ---> r_task
    |                   +---> [一致性奖励] ---> r_cons (通过冻结模型)
    |
    +--- HRAS: 合并两个奖励的优势
         |
         v
    策略梯度更新LVLM
想象你在训练一名初级律师写案件摘要。 任务奖励就像高级合伙人检查最终结论:法律上是否正确? 一致性奖励就像一个质量控制文员,通读整个论点与结论,标记任何论点逻辑上不能推导出结论的地方,或者结论与先前陈述的前提矛盾的地方。 文员不在乎法律正确性——只在乎内部连贯性。 HRAS就是管理合伙人,决定两个反馈通道各给多大权重。 如果初级律师只听高级合伙人,可能死记硬背正确结论但缺乏合理推理。 如果只听文员,可能产出完全逻辑严密但结论错误的摘要。 HRAS动态混合两个信号,管理合伙人可以根据训练阶段调整混合比例(例如早期偏向任务奖励,后期转向一致性)。 初级律师(LVLM)更新其笔记技巧(策略)以满足两者,最终写出的简报既干净又坚实。
关键概念
-
思考-答案鸿沟:推理逻辑内容与最终答案之间的偏离。 可以是正偏离(推理错误但答案偶然正确)或负偏离(推理正确但答案错误)。 例子:LVLM处理一张有猫和狗的图片。 推理:“猫是黑色,狗是棕色。问题问猫的颜色,所以答案是黑色。” 但它输出”棕色”。 这就是负偏离——推理给出黑色,答案说棕色。 该鸿沟独立于视觉幻觉(猫的检测可能完全正确)。
-
一致性奖励模型:一个分类器(例如一个小型BERT模型),接收推理序列和答案,输出一致性的概率。 它在来自训练集的(推理,答案)对上训练,一致性标签可通过人工标注(昂贵),或用任务正确性作为噪声代理,或通过人工构造不一致对(例如交换另一样本的答案)获得。 该模型必须任务无关以泛化。
-
混合奖励优势切分(HRAS):标准的多奖励RLVR做法是简单平均或加权求和。 HRAS则分别为每个奖励计算单独的优势(该rollout比平均值好多少),然后对每个优势应用可调的裁剪或加权,再求和。 这防止了因尺度差异(任务奖励通常是二值的{0,1},而一致性分数在[0,1]连续)而导致一个奖励的优势压倒另一个。 公式中含有一个温度参数控制一致性压力的强度。
框架转变
之前(主流方法):                之后(本文方法):
+--------------------------------+   +--------------------------------+
| 图像 + 问题                    |   | 图像 + 问题                    |
|   |                            |   |   |                            |
| [LVLM] --> (推理链, 答案)     |   | [LVLM] --> (推理链, 答案)     |
|   |                            |   |   |         |                  |
| [任务奖励]                      |   | [任务奖励] [一致性奖励模型]   |
|   |                            |   |   |         |                  |
| 优势 = A_task                  |   | [HRAS] 合并优势               |
|   |                            |   |   |                            |
| 更新LVLM                       |   | 更新LVLM                       |
+--------------------------------+   +--------------------------------+
一句话:从仅优化答案正确性(任务奖励)转向联合优化答案正确性与推理-答案语义一致性, 并配以稳健的优势混合机制。
专家评审
选题眼光: 真缺口。思考-答案不一致在纯文本RLVR中已知(如”谄媚”),但在多模态场景中完全被忽视。 本文的rollout分析令人信服——他们展示了该鸿沟存在且标准训练无法消除。 在RLVR被推向多模态推理的当下,这是一个及时的课题。
方法成熟度: 巧劲但实现直接。一致性奖励模型是一个标准的小型辅助分类器——奖励塑形的常见做法。 HRAS是对现有多目标优势估计(如使用分离基线)的小改造。 不过,简洁性使其易于采用。 有没有更简单的方法?有——你可以在损失中加入一致性评分惩罚(如推理后验与答案后验之间的KL散度), 但论文认为这会干扰任务优化。 CORA的即插即用性质是工程上的胜利。
实验诚意: 公平。他们与标准GRPO(无一致性)和朴素加权奖励求和进行了比较。 在多个基准(MMBench、MathVista等)和多个基础模型(LLaVA、Qwen-VL)上测试。 结果显示任务准确率一致提升1-3个百分点,不一致性显著降低10-20%。 一个警示:一致性奖励模型在测试集相同分布上训练——他们应测试对分布外推理模式的泛化性。 另外,一致性标签的人工标注成本未讨论;如果严重依赖合成数据,影响可能打折扣。
写作功力: 清晰,结构好。rollout分析图表不错。 薄弱之处在于HRAS的描述——尽管有名字,机制仍有些晦涩。 作者若用简单的伪代码或具体例子来推导优势计算,论文会强很多。
判决: 弱接收——解决了一个真实且被忽略的问题,提供了实用轻量的方案, 但新颖性增量有限,实验范围可更广。
要点总结
- 将一致性作为独立的奖励信号:你可以训练一个小的、冻结的奖励模型来惩罚推理-答案不匹配, 而不损害主要任务奖励。这个想法可迁移到任何你在意忠实推理的RLVR场景(文本、代码、数学)。
- 优势切分而非奖励平均:当你有两个不同尺度和分布的奖励源时, 分别计算优势再组合——不要直接平均奖励。HRAS技巧可泛化到任何多目标强化学习设置。
- 面向鸿沟的rollout挖掘:本文按”鸿沟类型”(一致正确、不一致错误等)聚类rollout的方法, 是任何RLVR流水线的有用调试工具。把这个分析工作流拿到你自己的项目中去用。