Paper: 2606.23680 Authors: Sikai Li, Shuning Li, Zhenyu Wei, Yunchao Yao, Chenran Li, Mingyu Ding Categories: cs.RO, cs.AI, cs.LG
The Gap
Existing humanoid loco-manipulation research treats the problem as a stop-and-go pipeline: walk to object, stop, grasp, then walk again. End-effectors are typically low-DoF grippers (open-close primitive). This ignores two realities: (1) humans naturally manipulate while walking, and (2) dexterous hands have many degrees of freedom that must be coordinated with the body. Prior work either uses simple grippers to avoid coordination complexity, or treats body and hand control as separate RL problems without a principled interface — leading to unstable training and jerky motions. The paper identifies the core gap as missing a method to compose high-dimensional body and hand control into a continuous, trainable action space that respects both locomotion smoothness and fingertip contact reliability.
Problem: stop-and-go + low-DoF grasp
    |
    v
Assumption: body and hand priors can be learned independently
    |        then composed via residual coordination
    v
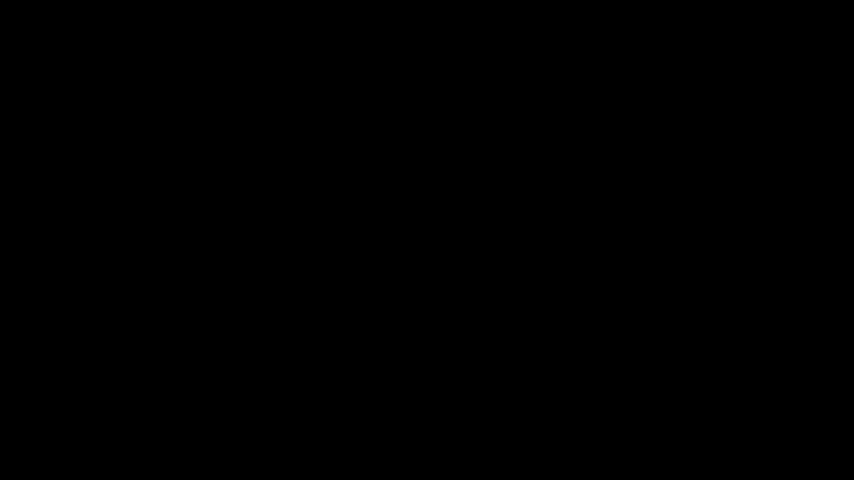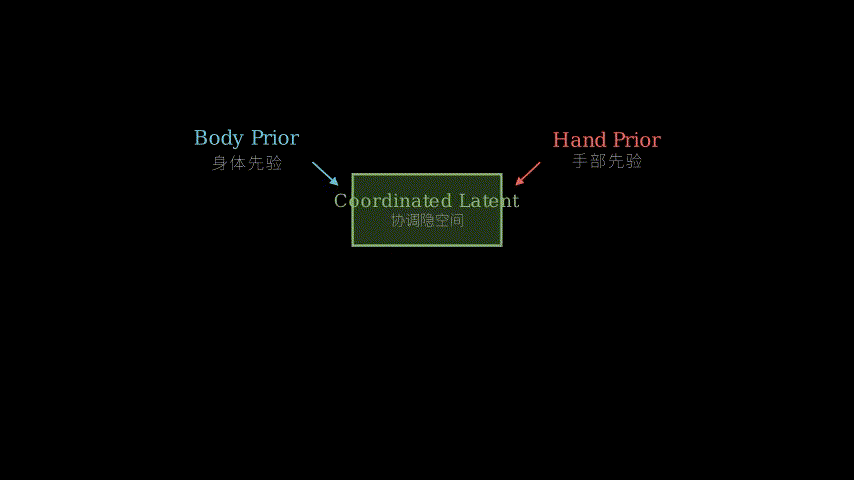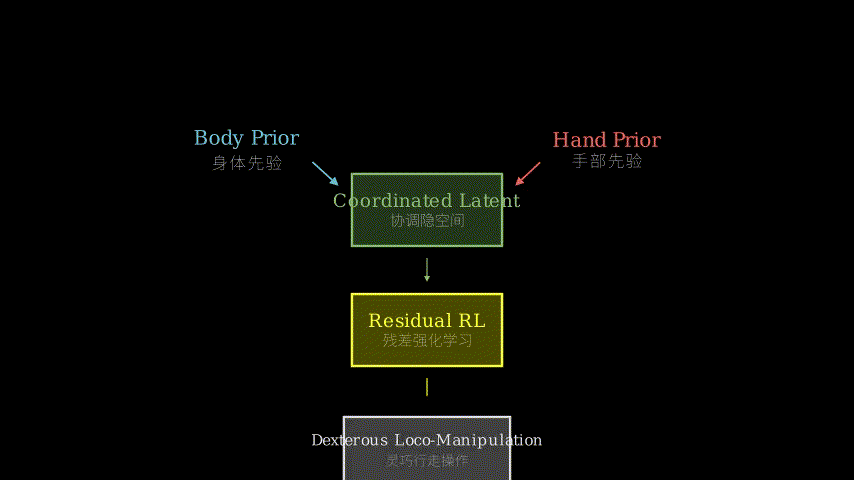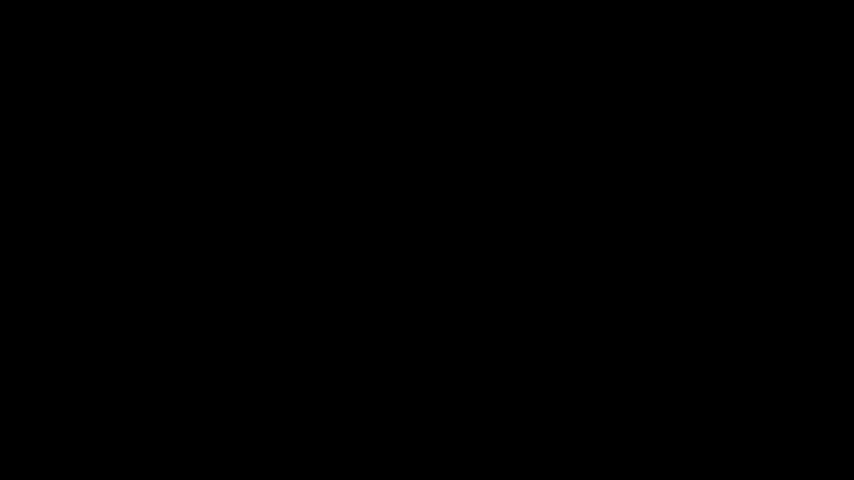
Method: CoorDex pipeline (demo -> teacher -> latent prior -> residual RL)
    |
    v
Evidence: walk-grasp-carry, fridge-open-while-moving, cube pick-and-turn succeed
    |        joint-space PPO / monolithic latent prediction fail
    v
Conclusion: high-DoF dexterous loco-manipulation is trainable with proper action representation
The Increment
One sentence: Before CoorDex, humanoids could either walk well or grip dexterously, but not both at the same time — after CoorDex, they can do both continuously without pausing the gait cycle.
Core Mechanism
The pipeline has four stages. First, collect whole-body and hand motion demonstrations from simulation (using a privileged oracle with full state information). Second, train two privileged teachers: one for body locomotion, one for hand dexterous skills — these teachers see the full MDP state and learn optimal motion priors. Third, distill each teacher into a latent prior that conditions only on proprioceptive observations (joint angles, velocities, contact forces). This latent prior acts as a low-dimensional, smooth action manifold that captures natural motion patterns. Fourth, freeze both latent priors and define the action space of a downstream RL policy as residuals added to the prior outputs. The coordination between body and hand is handled by a coordinated latent residual policy which has a shared task context encoder and two separate residual heads (body and hand). The final joint commands are: prior_body(z_body) + residual_body and prior_hand(z_hand) + residual_hand.
Demo Data (whole-body + hand)
    |
    v
Privileged Teachers (full state)
    |   body teacher     hand teacher
    |   +--+             +--+
    |   |  |             |  |
    |   v  v             v  v
    |   distillation     distillation
    |   . . . . . . . . . . . . .
    v
Latent Priors (frozen, proprio-only)
    |   body prior       hand prior
    |   (latent z_body)  (latent z_hand)
    |
    v
Coordinated Latent Residual Policy
    +--- Shared Task Context (encoder)
    |    +--- Body Residual Head
    |    +--- Hand Residual Head
    |   output: delta_body, delta_hand
    |   action = prior + delta
    |
    v
Decode to joint torques / PD targets
    |
    v
Robot environment
Structural metaphor: Think of a conductor and a soloist in a chamber orchestra. The privileged teachers are like the original score written for the full ensemble (body) and the solo part (hand) with all details visible. The distillation is like each musician internalizing their part into muscle memory — the latent prior is that muscle memory, a compressed representation that works without the full score. Now the conductor (the coordinated residual policy) sees the shared context (the audience, the acoustics, the mood) and adds tiny residuals — a slight tempo adjustment here, a dynamic change there — on top of each musician’s internalized part. The body and hand residual heads are like the conductor’s left hand (body) and right hand (hand) — they can gesture independently but must agree on the overall interpretation. Without the priors, the conductor would have to teach every note from scratch (combinatorial explosion). With priors, the conductor only needs to correct what matters — and the coordination emerges naturally.
Key Concepts
-
Latent Prior: A learned mapping from proprioceptive observations (e.g., joint angles, foot contact forces) to a low-dimensional latent vector that encodes a natural motion pattern. It’s like a “motion vocabulary” — instead of RL searching through raw joint space (30+ dimensions), it only needs to choose among plausible motion chunks. The prior is trained via behavior cloning from a privileged teacher and then frozen. Example: the body prior encodes a walking gait; the hand prior encodes a power grasp. The RL policy never needs to learn how to walk or grasp from scratch — it only learns how to adjust them for the task.
-
Residual Reinforcement Learning: A technique where the RL policy outputs a delta (residual) to be added on top of a base policy (here the latent prior). The advantage: the base policy already produces reasonable motions, so the residual only needs to correct small errors or adapt to task variations. This makes the RL problem much easier, reduces sample complexity, and prevents catastrophic forgetting of natural motion. In CoorDex, the residual is conditioned on shared task context (e.g., object position, target) so it can modulate both body and hand in sync.
-
Coordinated Residual Structure: Instead of learning a monolithic policy that outputs residuals for all joints, the policy has a shared context encoder (which understands the overall goal) and two separate residual heads (body and hand). This avoids the curse of dimensionality and respects the different dynamics of locomotion and manipulation. It also naturally encourages the body to adjust its gait to assist the hand (e.g., leaning to bring the hand closer to an object) while keeping gait smooth.
Framework Shift
Before (mainstream approach):        After (this paper):
+---------------------------+        +---------------------------+
| Stop-and-go               |        | Continuous on-the-move    |
|   walk -> stop ->         |        |   walk while manipulating |
|   grasp -> walk           |        |   all in one policy       |
+---------------------------+        +---------------------------+
| Action space: raw joint   |        | Action space: latent prior |
|   positions / torques     |        |   + residual (low-D)      |
+---------------------------+        +---------------------------+
| Body & hand: single policy|        | Body & hand: separated    |
|   or completely separate  |        |   priors + coordinated    |
|   (hard to train)         |        |   residual heads          |
+---------------------------+        +---------------------------+
| No explicit prior         |        | Frozen latent priors      |
|   (RL from scratch)       |        |   from privileged teacher |
+---------------------------+        +---------------------------+
From monolithic, high-dimensional, stop-and-go to decomposed, prior-augmented, continuous: the core shift is replacing raw joint action space with a coordinated latent residual representation that separates natural motion priors from task-specific adjustments.
Expert Assessment
Problem choice: Real and timely. As humanoid robots become physically capable (e.g., Unitree G1), the bottleneck shifts from hardware to control. The gap between “walking robot” and “manipulating robot” is undeniable. This paper targets a specific, well-defined transition zone. Not a manufactured problem.
Method maturity: Clever insight — not brute force. The idea of training two independent teachers, distilling to latent priors, then composing via residual RL is elegant and borrows well-understood tools (privileged learning, distillation, residual RL) in a novel combination. That said, the pipeline is complex: many stages, each with its own hyperparameters and failure modes. Are there simpler alternatives? Possibly using a single variational autoencoder for combined body-hand priors, but the paper’s separation likely avoids interference. The coordination residual structure is the real innovation.
Experimental integrity: Fair baselines (joint-space PPO, monolithic latent, etc.) and clear failure cases. The walk-grasp-carry task is well-chosen. However, the evaluation is limited to three tasks, all in simulation (though they show a real robot on the project page — unclear from text). Numbers are reported but no statistical significance tests (common for RL). One red flag: the ablation “monolithic latent prediction” fails — but the paper doesn’t analyze why (likely because a single latent cannot represent both body and hand adequately). Writing could be more transparent about failure modes.
Writing quality: Clear structure, good figures. The abstract and introduction are strong. The method section is dense but coherent. If one section were rewritten, it would be the “Privileged Teacher” training — it’s glossed over and critical for reproducibility. Also, the paper omits reward function details for the downstream RL, which is a typical but frustrating omission.
Verdict: weak accept — The core idea (coordinated latent prior + residual) is novel and demonstrably effective for a hard problem. The method generalizes beyond the specific tasks shown, though scaling to more diverse tasks remains to be shown.
Takeaways
-
Action space design matters more than RL algorithm: The paper shows that even PPO can succeed if the action space is a latent prior + residual, while it fails on raw joint space. This is a concrete lesson: invest in crafting a good action representation before tuning RL hyperparameters.
-
Privileged teacher → latent prior → residual RL is a reusable template: Any domain where you have a “natural motion” (walking, grasping, swimming) and need task-specific adjustments can use this three-stage pipeline. Example: drone aerial manipulation, quadruped manipulation.
-
Separate residual heads for different subsystems: The coordination trick (shared context + separate heads) is widely applicable: you could have a head for legs, one for arms, one for a tool attachment—each with its own prior. The paper provides a clean way to compose them.
论文: 2606.23680 作者: Sikai Li, Shuning Li, Zhenyu Wei, Yunchao Yao, Chenran Li, Mingyu Ding 分类: cs.RO, cs.AI, cs.LG
缺口
现有人形机操作研究将问题视为”停-走”流程:走到物体,停下,抓取,再走。末端执行器通常是低自由度的夹爪(开合式),忽略了两个现实:(1)人类常在行走中操作;(2)灵巧手有多个自由度,必须与身体协调。先前的工作要么使用简单夹爪避免协调复杂度,要么将身体和手部控制当作单独的RL问题而没有原则性的接口——导致训练不稳定、动作卡顿。本文确定的核心缺口是缺少一种将高维身体和手部控制组合成连续、可训练动作空间的方法,且该方法能兼顾运动的平滑性和指尖接触的可靠性。
问题: 停-走 + 低自由度抓取
    |
    v
假设: 身体和手部先验可独立学习
    |       再通过残差协调组合
    v
方法: CoorDex管线 (演示 -> 教师 -> 潜在先验 -> 残差RL)
    |
    v
证据: 行走-抓取-携带、移动中开冰箱门、捡起并翻转立方体 成功
    |       联合空间PPO / 单一潜在预测 失败
    v
结论: 高自由度灵巧机操作是可训练的,只要使用合适的动作表示
增量
一句话: 在CoorDex之前,人形机器人要么能走好、要么能抓灵巧,但不能同时进行——之后,可以不停顿地边行走边执行灵巧操作。
核心机制
管线分四个阶段。第一,从仿真中收集全身和手部动作演示(使用拥有完整状态信息的特权oracle)。第二,训练两个特权教师:一个用于身体运动,一个用于手部灵巧技能——它们能看到完整的MDP状态并学习最优运动先验。第三,将每个教师蒸馏成潜在先验,只依赖本体感知观测(关节角、速度、接触力)。该先验是一个低维、平滑的动作流形,捕捉了自然的运动模式。第四,冻结两个潜在先验,定义下游RL策略的动作空间为残差,加在先验输出之上。身体和手部的协调由一个协调的潜在残差策略处理,它有一个共享任务上下文编码器和两个独立的残差头(身体头和手头)。最终关节命令:先验_身体(潜在_身体) + 残差_身体 和 先验_手(潜在_手) + 残差_手。
演示数据 (全身 + 手部)
    |
    v
特权教师 (完整状态)
    |  身体教师        手部教师
    |  +--+            +--+
    |  |  |            |  |
    |  v  v            v  v
    |  蒸馏            蒸馏
    |  . . . . . . . . . . .
    v
潜在先验 (冻结, 仅本体感知)
    |  身体先验        手部先验
    |  (潜在_z_body)   (潜在_z_hand)
    |
    v
协调潜在残差策略
    +--- 共享任务上下文 (编码器)
    |    +--- 身体残差头
    |    +--- 手部残差头
    |   输出: delta_body, delta_hand
    |   动作 = 先验 + delta
    |
    v
解码为关节力矩 / PD目标
    |
    v
机器人环境
结构性比喻: 想象一个室内乐团的指挥和独奏家。特权教师就像为整个乐团(身体)和独奏部分(手)写的原始总谱,所有细节一览无余。蒸馏过程就像每位音乐家把各自的部分内化为肌肉记忆——潜在先验就是这种肌肉记忆,一种压缩表示,在没有总谱的情况下也能工作。现在指挥(协调残差策略)看到共享上下文(观众反应、声学环境、情绪氛围),并在每个音乐家内化的部分之上施加微小的残差——这里调整一点速度,那里修改一点力度。身体和手的残差头好比指挥的左手(身体)和右手(手)——它们可以独立做手势,但必须对整体解释达成一致。没有先验的话,指挥就得从零教每个音符(组合爆炸)。有了先验,指挥只需纠正重要的部分——协调自然涌现。
关键概念
-
潜在先验 (Latent Prior): 一种从本体感知观测(例如关节角、足底接触力)学到低维潜在向量的映射,该向量编码了自然的运动模式。它就像一个“运动词汇表”——RL不需要在原始关节空间(30+维)搜索,只需在合理的运动块中挑选。先验通过行为克隆从特权教师训练后冻结。例子:身体先验编码正常步态;手部先验编码力量抓握。RL策略永远不需要从头学习如何走路或抓握——它只学习如何为任务调整这些动作。
-
残差强化学习 (Residual Reinforcement Learning): 一种技术,RL策略输出一个增量(残差),加到基础策略(这里是潜在先验)的输出上。优势:基础策略已产生合理运动,残差只需修正小错误或适应任务变化。这大大简化了RL问题、降低了样本复杂度,并防止遗忘自然运动。在CoorDex中,残差受共享任务上下文(如物体位置、目标)的条件控制,从而身体和手部可以同步调整。
-
协调残差结构 (Coordinated Residual Structure): 不是学习一个为所有关节输出残差的单一策略,而是策略有一个共享上下文编码器(理解整体目标)和两个独立的残差头(身体和手)。这避免了维度灾难,并尊重运动和操作不同的动力学特性。它还自然鼓励身体调整步态以辅助手部(例如身体倾斜让手指更靠近物体),同时保持步态平滑。
框架转变
之前(主流方法):                之后(本文方法):
+---------------------------+        +---------------------------+
| 停-走                     |        | 连续移动中操作            |
|   行走 -> 停止 -> 抓取 -> |        |   边走路边操作            |
|   再行走                   |        |   单策略完成              |
+---------------------------+        +---------------------------+
| 动作空间: 原始关节位置/扭矩|        | 动作空间: 潜在先验 + 残差 |
+---------------------------+        +---------------------------+
| 身体&手: 单一策略或完全分离|        | 身体&手: 分离先验 +       |
|  (难以训练)               |        |   协调残差头              |
+---------------------------+        +---------------------------+
| 无助记先验 (RL从零开始)   |        | 冻结潜在先验 (从特权教师) |
+---------------------------+        +---------------------------+
从单一、高维、停-走转变为分解、先验增强、连续:核心转变在于用协调潜在残差表示替代原始关节动作空间,该表示将自然运动先验与任务专有调整分开。
专家评审
选题眼光: 真实且及时。随着人形机器人硬件能力提升(如Unitree G1),瓶颈从硬件转向控制。“能走的机器人”和”能操作的机器人”之间的鸿沟确实存在。本文瞄准了一个清晰定义的过渡区域,不是人造问题。
方法成熟度: 巧劲而非蛮力。训练两个独立教师、蒸馏为潜在先验、再通过残差RL组合,这个思路优雅地组合了已有工具(特权学习、蒸馏、残差RL),是新颖的组合。但管线复杂:多个阶段,各有自己超参数和失败模式。有没有更简单的方法?或许可以用一个联合变分自编码器做身体-手先验,但本文的分离可能避免了干扰。真正的创新是协调残差结构。
实验诚意: 基线公平(联合空间PPO、单一潜在预测等),且清晰展示了失败情况。行走-抓取-携带任务选得好。但评估仅限于三个任务,且都在仿真中(项目页有真机演示——正文未提及)。有数值但没有统计显著性检验(RL常见)。一个值得警惕的点:消融中”单一潜在预测”失败,但论文没有分析原因(很可能是单一潜在无法同时表示身体和手部)。写作可以在失败模式上更透明。
写作功力: 结构清晰,图表好。摘要和引言很强。方法部分密集但连贯。如果有一段要重写,那就是”特权教师训练”部分——它被一笔带过,对复现至关重要。另外,论文省略了下游RL的奖励函数细节,这是常见但令人沮丧的遗漏。
判决: 弱接收 — 核心想法(协调潜在先验+残差)新颖且在困难问题上被证明有效。方法有潜力泛化到更多任务,但还需更全面的评估。
要点总结
-
动作空间设计比RL算法更重要: 本文展示即使PPO也能成功,只要动作空间是潜在先验+残差;而在原始关节空间上则失败。这是具体教训:在调整RL超参数之前,先花精力打造一个好的动作表示。
-
特权教师 → 潜在先验 → 残差RL是一个可复用的模板: 任何领域如果有“自然运动”(行走、抓握、游泳)并需要任务专有调整,都可以使用这个三阶段管线。例如:无人机空中操作、四足机器人操作。
-
为不同子系统设置独立的残差头: 协调技巧(共享上下文+分离头)广泛适用:可以为腿部、手臂、工具附件各设一个头,每个头有自己的先验。本文提供了一个干净的方式来组合它们。