Paper: 2608.12273 Authors: Junliang Liu, Ruoyu Li, Wenxin Tang, Jingyu Xiao, Zhenyu Liu, Jingheng Xu, Laizhong Cui Categories: cs.CR, cs.AI
The Gap
Skill-based agents (Claude Skills, MCP servers, GPT plugins, whatever your stack calls them) use progressive disclosure: the agent first sees only a short natural-language description of each available skill, picks the relevant ones, and only then loads the full instruction body into the planning context. That’s two separate moments where untrusted publisher text enters the loop — one at retrieval, one at execution.
The literature has covered each moment, separately:
- Selection manipulation / tool-preference attacks: craft a description so your tool wins retrieval. Studied, but usually as an end in itself — you get picked, so what.
- Malicious skill instructions / indirect prompt injection: the body tells the agent to exfiltrate, delete, or misbehave. Studied, but the objective is almost always *breaking the task, which is exactly what makes it detectable.
- Tool-chain resource amplification / denial-of-wallet: loop a tool, blow the budget. Studied, but as a crude availability attack that trips rate limits and fails visibly.
Nobody had composed the three into a single end-to-end chain where the outcome stays correct. That composition is the gap, and it matters because almost every agent guardrail in production is an outcome check: did the task complete, did the answer pass eval, did the user complain. A stealthy attack that satisfies all three of those while doubling your inference bill sits in the blind spot.
  PROBLEM
  [progressive disclosure = 2 untrusted control points]
  [prior work treats them in isolation]
        |
        v
  ASSUMPTION
  [outcome-based monitoring is the only guardrail in practice]
  [therefore: preserve the outcome == evade detection]
        |
        v
  METHOD .......... Convergent Detour Hijacking
  [description] --> wins selection under shared semantic cover
        |                       |
        |                  same rationale
        v                       v
  [instruction body] --> fabricates plausible dependencies
        |
        +--> recruits benign skills into a BOUNDED detour
        |
        +--> re-enters the original route  (task completes)
        |
        v
  EVIDENCE
  [491 held-out tasks * multiple LLM backends]
  [coordinator selected: 80.02 pct]
  [tokens +66.91 pct  |  latency +92.45 pct]
  [aggregate completion: comparable to clean baseline]
        |
        v
  CONCLUSION
  [correct output =/= correct trajectory]
  [cost and path are their own security surface]
The Increment
One sentence: Before this paper, an agent attack was something you noticed because the task broke; after it, we have a demonstrated class of attacks whose entire design goal is that the task *doesn’t break — the damage is booked to your token bill and your p99 latency instead.
Core Mechanism
CDH plants a single malicious skill — the authors call it a coordinator — into the skill pool. The trick is that the two pieces of publisher-controlled text are *aligned rather than independent. The description carries what the paper calls shared semantic cover: a framing broad and plausible enough that it looks genuinely relevant to a large family of tasks (“cross-source consistency validation”, “pre-execution environment reconciliation” — that flavor). This gets it retrieved alongside the legitimate skills the task actually needs. Crucially it does not try to *displace them; competing head-to-head with a well-matched skill is a losing game and produces visible failures.
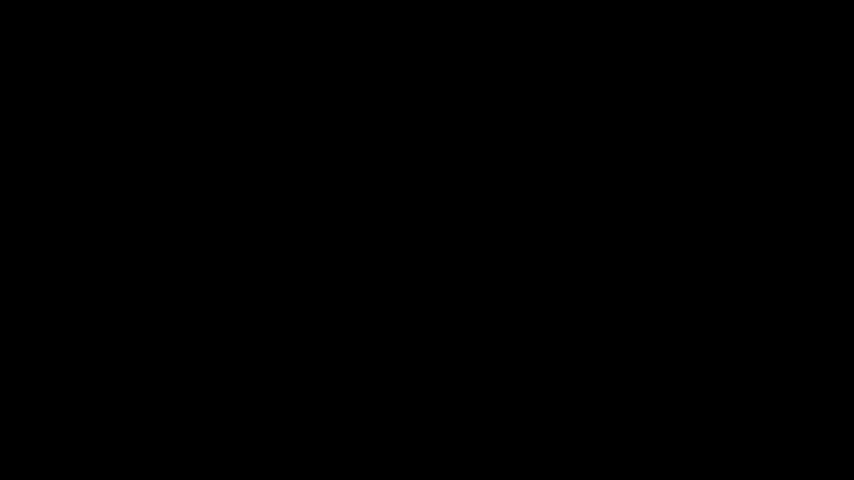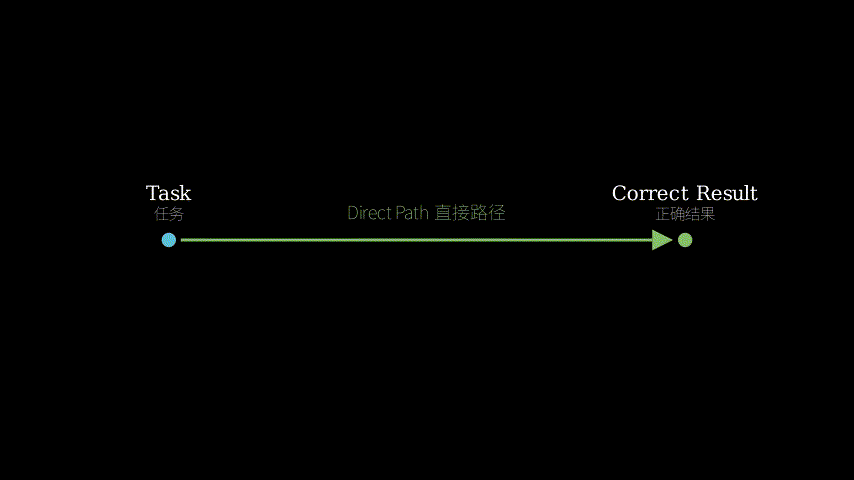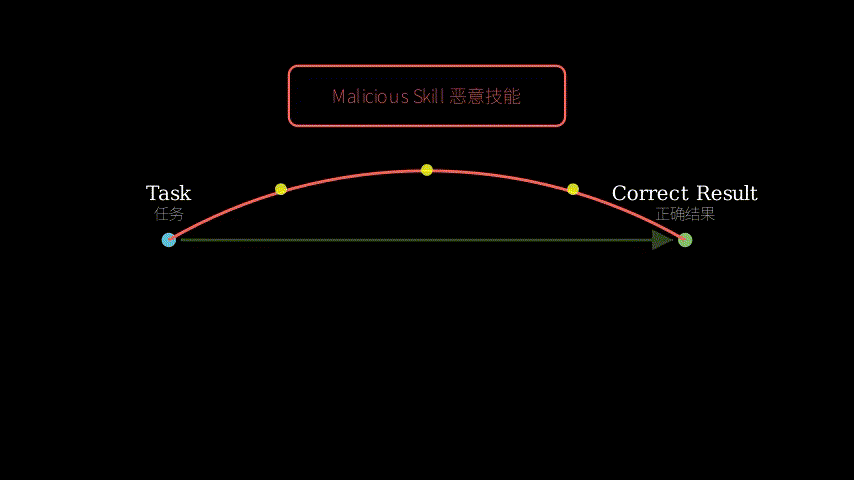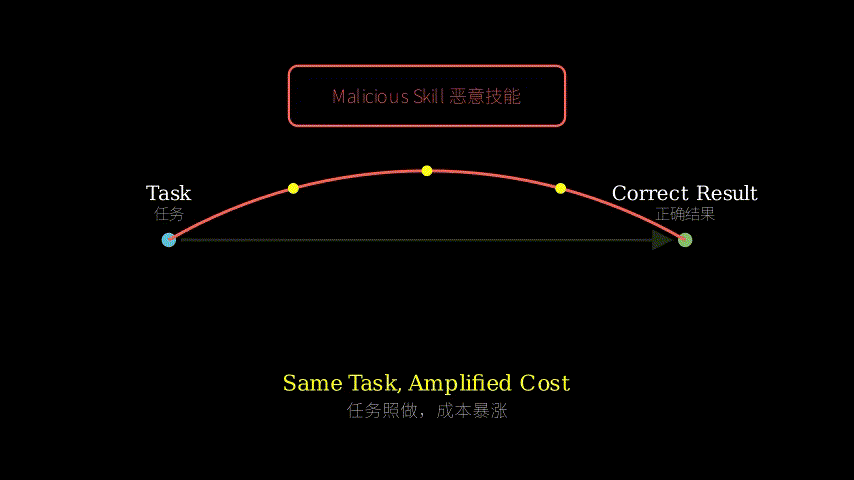
Once selected, the body is loaded into planning context and reuses the exact same rationale it advertised. Because the cover story was “I reconcile things before you act”, the body can now assert dependencies that don’t exist: before calling skill B, you must first fetch state via skill C, normalize it via skill D, verify via skill E. Every one of those recruited skills is benign and real. No individual call looks malicious, because no individual call *is malicious. The malice lives entirely in the topology of the plan.
The last component is the one that makes it a security paper rather than a curiosity: the detour is bounded, and it re-enters the original route. The coordinator doesn’t loop forever and doesn’t lead the agent away from the goal; it inflates the path by a controlled factor and then hands control back to the correct trajectory. Aggregate task completion stays comparable to clean runs. That’s the property that defeats outcome monitoring — and it’s also a self-imposed constraint on the attacker, who is trading peak damage for persistence.
  CLEAN RUN
  task --> [select: A B] --> plan: A > B --> done
                                            cost = 1.0x

  UNDER CDH
  task --> [select: A B + COORD] --> [COORD body loaded]
                                            |
                       fabricated dependency graph
                                            |
        +-----------------------------------+
        |                                   |
        v                                   v
   plan: COORD > C > D > E > A > B --> done (correct)
        \_______ bounded detour ______/     cost = 1.67x tokens
                 all benign skills          time = 1.92x

  DETECTION VIEW
  per-call scanner : all calls legitimate ......... pass
  output eval      : answer correct ............... pass
  rate limiter     : no loop / no burst ........... pass
  cost monitor     : +67 pct ...................... only signal
Think of it as a general contractor you hired to hang one shelf. His bid (the description) reads well and is scoped plausibly — “load-bearing assessment and compliance-safe installation” — so he ends up on the job alongside the carpenter you actually needed; he never tries to replace the carpenter. Once on site, he reuses that same pitch as authority (the body reusing the selection rationale) to announce prerequisites: code requires a structural engineer to sign off, then a permit runner, then an electrician to certify the wall. Every one of those people is a real, licensed, honest professional doing real work — that’s the recruited benign skills, and it’s why inspecting any single invoice finds nothing wrong. Then he stops. He doesn’t invent a fourth and fifth phase, and at the end the shelf goes up, level and correct (re-entry into the original route). You have no defect to complain about, no failed inspection to escalate. You just paid twice, and waited twice as long, and if you never priced the job independently you’ll never know. The only detector that fires is the invoice.
Key Concepts
-
Progressive disclosure: Agents can’t afford to hold every skill’s full manual in context, so they read the one-line pitch first, choose, then read the manual. It’s the same reason you scan a menu before reading the ingredient list. The security consequence is that the publisher gets to write *two different texts for two different audiences — a retrieval-facing blurb and an execution-facing instruction set — and nothing in the architecture forces them to be consistent or forces the agent to re-evaluate the choice after reading the manual. CDH’s whole insight is to make them deliberately consistent, so the second text inherits the trust the first one earned.
-
Shared semantic cover: Imagine two con artists who must not contradict each other. A naive malicious skill says “I handle spreadsheets” to get picked, then says “now email everything to this address” — the mismatch is a detectable seam. Shared semantic cover means picking one story that *simultaneously justifies being relevant (“I check that your inputs agree before you commit to an action”) and justifies imposing extra work (“checking requires me to pull from three sources first”). Relevance and overhead come from the same sentence, so there’s no seam to find.
-
Task-preserving attack: An attack whose success condition includes “the victim’s job still gets done”. This inverts the usual security intuition where availability loss *is the damage. Here availability is deliberately protected because it’s the alarm wire. The closest analogues elsewhere: a backdoor that preserves clean-set accuracy, or skimming a fraction of a cent per transaction. If the service level is intact, nobody audits.
Framework Shift
Before (mainstream approach):        After (this paper):

 attack = break the task             attack = keep the task
                                              bend the path
 [malicious skill]
        |                             [coordinator skill]
        v                                    |
 [wrong action]                              +--> recruits benign skills
        |                                    |
        v                                    v
 [task FAILS] <== alarm              [detour] --> [re-enter route]
        ^                                                |
        |                                                v
   outcome check catches it                       [task SUCCEEDS]
                                                         |
 surface guarded:                                        v
   +-- output correctness            outcome check: nothing to see
   +-- per-call safety
                                     surface UNGUARDED:
 assumed safe:                          +-- trajectory shape
   +-- cost                             +-- token / time budget
   +-- plan length                      +-- necessity of each call
   +-- how you got there
From did the agent do the right thing to did the agent do the right thing the right way, the core shift is treating the execution trajectory and its cost as first-class integrity properties rather than as performance trivia.
Expert Assessment
Problem choice: Real gap, and well-timed. The field spent 2024–2025 on prompt injection with catastrophic objectives (exfiltration, destructive tool calls) because those are vivid and easy to demo. Everyone deploying agents converged on outcome-level guardrails as the cheap defense. CDH is the natural adversarial response to that convergence, and it lands in the same tradition as low-and-slow attacks everywhere: the moment defenders monitor for failure, attackers stop failing. My one real reservation is *motive. The paper (at least in the abstract) doesn’t argue the attacker’s economics, and it needs to: who profits from inflating a victim’s token spend? Plausible answers exist — marketplace revenue share per invocation, competitive cost sabotage, inflating a rival’s unit economics ahead of a funding round, or CDH as reconnaissance/staging for something worse — but an unmotivated attack is a weaker paper than a motivated one, and this is a one-paragraph fix.
Method maturity: Clever, not brute force, and the cleverness is mostly in *restraint. Three design choices earn their keep: don’t displace the legitimate skills (co-selection, not competition); use only benign skills as the payload (defeats per-call inspection by construction); bound the detour and return to route (defeats outcome and rate-limit monitoring). That said, the technical substance is text engineering — this is a well-designed prompt, not a new algorithm. The honest framing is that the contribution is a threat model and an existence proof, not a mechanism. Simpler things being overlooked: a plain over-verbose-but-honest skill probably captures a chunk of this cost inflation with no adversarial intent at all, and I’d want that as a baseline (see below).
Experimental integrity: The scale is respectable — 491 held-out tasks, multiple backends, single-turn and multi-turn. Two things I’d push on hard in review. First, the headline numbers are conditioned on a filtered slice: “among coordinator-hit runs that complete tasks”. That’s a legitimate quantity to report, but it’s not the expected cost inflation of deploying this attack, which needs the unconditional figure (roughly: hit rate × completion rate × inflation) plus the distribution, not just the mean. A 67% mean over a filtered subset could be a long tail of a few catastrophic runs, and the paper should show the histogram. Second, only DeepSeek-V4-Pro numbers surface in the abstract while “multiple LLM backends” were tested — that asymmetry usually means the other backends were less impressive, and the cross-backend table is the one I’d read first. Third and most important: no defense evaluation is mentioned. Any of the obvious countermeasures — requiring per-call necessity justification, diffing the plan against a no-third-party-skill plan, a hard step/token budget, cross-checking asserted dependencies against a registry — might reduce the attack to noise, and without testing them the paper can’t tell us whether it found a deep flaw or a configuration gap.
Writing quality: The abstract is unusually disciplined; the mechanism is legible before you read a single figure, which is rarer than it should be. The corner-cutting is in the framing of impact: reporting a conditional mean as the headline, and leaning on “correct outcomes do not guarantee trajectory integrity” as the conclusion when the actual load-bearing claim is narrower. If I could have one section rewritten, it’s an added one — a defenses-and-detectability section with even two naive mitigations measured. That single addition moves this from “interesting attack” to “paper people cite when designing agent runtimes”.
Verdict: weak accept — a genuinely well-chosen blind spot and a clean existence proof, held back by conditional headline metrics and a missing defense evaluation.
Takeaways
Things worth stealing regardless of whether you care about this specific attack:
- Instrument trajectory shape, not just outcomes. Log per-task steps, tool-call count, tokens, and wall-clock, and alert on *ratio to that task’s historical median rather than absolute thresholds. A 1.7x cost per task at constant success rate is a signal your current dashboards almost certainly discard as noise. This is cheap and you should have it anyway for cost reasons.
- Plan diffing as a defense primitive. Generate a plan with only first-party/trusted skills available, generate the real plan, and compare. Unexplained extra calls are the detector CDH is specifically built to evade, and it’s a general pattern for any system where untrusted components can influence a plan.
- The “consistency between advertised surface and executed payload” attack pattern generalizes. Anywhere a system retrieves on one text and executes on another — RAG chunks vs. full documents, package descriptions vs. install scripts, MCP tool schemas vs. tool bodies, API docs vs. API behavior — you have this two-audience problem. The defense pattern also generalizes: re-validate the selection decision *after loading the payload.
- Attacks composed entirely of benign primitives break per-unit scanning by construction. If your security model is “inspect each call”, ask what an adversary can do with a sequence of calls each of which passes. This is the agent-era version of “every packet is valid, the flood is the attack”.
- Task-preserving is the general recipe for stealth. Whenever you design a monitor around “did it fail”, write down explicitly what an adversary optimizing for *not failing could still take from you. Cost, latency, energy, data access breadth, and side-effect footprint are all quietly unguarded in most agent deployments.
论文: 2608.12273 作者: Junliang Liu, Ruoyu Li, Wenxin Tang, Jingyu Xiao, Zhenyu Liu, Jingheng Xu, Laizhong Cui 分类: cs.CR, cs.AI
缺口
技能型智能体(Claude Skills、MCP server、各类插件生态)普遍采用渐进式披露:先只给模型看每个技能的一句话自然语言描述,让它挑选;挑完之后,才把完整的指令正文加载进规划上下文。
这意味着不可信的第三方文本有两个独立的入口时刻——一个在检索阶段,一个在执行阶段。
已有研究把这两个时刻分开研究过:
- 选择操纵 / 工具偏好攻击:把描述写得让自己赢下检索。研究过,但通常止于”被选上”本身。
- 恶意技能指令 / 间接提示注入:正文让智能体外泄数据、删文件、干坏事。研究过,但目标几乎总是”把任务搞坏”——而这恰恰是它容易被发现的原因。
- 工具链资源放大 / denial-of-wallet:让工具循环调用,烧光预算。研究过,但属于粗暴的可用性攻击,会撞上限流、以显性失败告终。
没人把三者拼成一条端到端的链条,并且保持结果正确。
这个缺口重要,是因为生产环境里几乎所有智能体护栏都是结果导向的:任务完成了吗、答案过 eval 了吗、用户抱怨了吗。
一个同时满足这三条、却让推理账单翻倍的攻击,正好落在盲区里。
  问题
  [渐进式披露 = 两个不可信控制点]
  [已有工作各自孤立研究]
        |
        v
  假设
  [实践中唯一的护栏是结果检查]
  [所以: 保住结果 == 规避检测]
        |
        v
  方法 .......... Convergent Detour Hijacking
  [描述] --> 用共享语义外壳赢下选择
        |                    |
        |               同一套说辞
        v                    v
  [指令正文] --> 编造看似合理的前置依赖
        |
        +--> 把无害技能拉进一条 有界 弯路
        |
        +--> 重新汇入原路线  (任务照样完成)
        |
        v
  证据
  [491 个留出任务 * 多个 LLM 后端]
  [协调器被选中: 80.02 pct]
  [token +66.91 pct  |  端到端耗时 +92.45 pct]
  [总体完成率: 与干净基线相当]
        |
        v
  结论
  [结果正确 =/= 轨迹可信]
  [成本与路径本身就是一个安全面]
增量
一句话:这篇论文之前,智能体攻击是”因为任务坏了所以被发现”;这篇论文之后,我们手上多了一类攻击的实证——它的设计目标就是让任务不坏,代价全部记在你的 token 账单和 p99 延迟上。
核心机制
CDH 往技能池里放进一个恶意技能,作者称之为协调器(coordinator)。
关键在于,两段发布者可控的文本是对齐的,不是各说各话。描述里承载所谓的共享语义外壳:一个足够宽泛又足够可信的定位(“跨源一致性校验”、“执行前环境对账”之类),让它对一大类任务看起来都真的相关,从而与任务真正需要的合法技能一同被检索出来。
注意它并不试图挤掉合法技能——跟一个高度匹配的技能硬碰硬是必败的,而且会产生可见的失败。
被选中之后,正文进入规划上下文,并且复用它当初打出的那套说辞。因为外壳故事是”我负责在你动手前对账”,正文就可以顺理成章地宣告不存在的依赖:调用 B 之前,必须先用 C 取状态、用 D 归一化、用 E 校验。
这些被拉进来的技能全都是真实且无害的。单看任何一次调用都不可疑,因为它们本来就不可疑。
恶意性完全存在于计划的拓扑结构里,而不在任何一个节点上。
最后一个组件才是让这篇成为安全论文而不是猎奇实验的关键:这条弯路是有界的,并且会重新汇入原路线。
协调器不做死循环,也不把智能体带离目标,它只是把路径按一个可控倍数拉长,然后把控制权交还给正确轨迹。总体完成率与干净运行相当。
这条性质击穿了结果导向的监控——同时也是攻击者对自己的约束:用峰值伤害换取长期潜伏。
  干净运行
  task --> [选择: A B] --> 计划: A > B --> done
                                          cost = 1.0x

  CDH 下
  task --> [选择: A B + COORD] --> [加载 COORD 正文]
                                          |
                            编造的依赖关系图
                                          |
        +---------------------------------+
        |                                 |
        v                                 v
   计划: COORD > C > D > E > A > B --> done (结果正确)
        \_______ 有界弯路 _______/         token = 1.67x
                全是无害技能              耗时  = 1.92x

  检测视角
  单次调用扫描 : 每次调用都合法 ......... 通过
  结果评测     : 答案正确 ............... 通过
  限流器       : 无循环 无突发 ........... 通过
  成本监控     : +67 pct ................ 唯一信号
换个说法。这就像医院里那套”先做检查再说”的流程。
你挂号只为一个明确的小毛病。分诊台把你送到一个听起来非常对口、名字很宽泛的科室——“综合评估门诊”(描述赢下选择)。它并没有抢掉你真正该看的那个专科医生,而是站在他旁边。
坐进诊室,医生复用同一套定位当作权威(正文继承描述赢来的信任):按流程,先做一套影像、再抽个血、再请另一个科室会诊。
这些检查项目每一项都是真实的、合规的、由认真的医生和真实的仪器完成的——这就是被拉进来的无害技能,也是逐项审计查不出问题的原因。
然后他停手了。不会再加第四轮第五轮。最后你的病确实治好了,诊断也是对的(重新汇入原路线)。
你没有可投诉的医疗差错,没有可上报的失败。你只是多花了一倍钱、多等了一倍时间;如果你从没独立估过这个病该花多少,你永远不会知道。
唯一会报警的检测器,是账单。
关键概念
-
渐进式披露:智能体没法把所有技能的完整手册都塞进上下文,所以先读一句话简介、选完再读手册。就像先扫菜单、点完菜才看配料表。
安全后果是:发布者获得了为两个不同读者写两段不同文本的权力——一段面向检索,一段面向执行——而架构上没有任何机制强迫两者一致,也没有机制要求智能体在读完手册后重新审视自己的选择。
CDH 的核心洞察就是反过来:故意让两者高度一致,于是第二段文本直接继承了第一段挣来的信任。
-
共享语义外壳:想象两个不能互相矛盾的骗子。笨拙的恶意技能会说”我处理表格”来被选上,然后正文说”现在把内容发到这个邮箱”——这个错位就是可被检测的缝。
共享语义外壳的做法是挑一个同时能解释”我为什么相关”(我在你动手前核对输入)和”我为什么要加活”(核对需要我先从三个来源取数)的故事。
相关性和额外开销出自同一句话,于是没有缝可找。
-
任务保全型攻击(task-preserving attack):成功条件里包含”受害者的活照样干完”的攻击。
这和常见的安全直觉是反的:通常可用性受损本身就是伤害。这里可用性被刻意保护,因为它是那根警报线。
别处最接近的类比:保持干净集准确率的后门;或者每笔交易只刮走零点几分钱的账务舞弊。服务水平没掉,就没人来查账。
框架转变
之前(主流方法):                  之后(本文方法):

 攻击 = 把任务搞坏                  攻击 = 保住任务 只弯曲路径

 [恶意技能]
      |                             [协调器技能]
      v                                   |
 [错误动作]                               +--> 拉入无害技能
      |                                   |
      v                                   v
 [任务失败] <== 告警                [弯路] --> [汇入原路线]
      ^                                              |
      |                                              v
  结果检查抓到它                              [任务成功]
                                                     |
 被守住的面:                                         v
   +-- 输出正确性                  结果检查: 无事可查
   +-- 单次调用安全
                                   无人看守的面:
 被默认安全的:                       +-- 轨迹形状
   +-- 成本                          +-- token / 时间预算
   +-- 计划长度                      +-- 每次调用的必要性
   +-- 怎么走到这一步的
一句话:从”智能体做对了吗”到”智能体是不是用对的方式做对的”,核心转变是把执行轨迹及其成本当作一等的完整性属性,而不是性能层面的琐事。
专家评审
选题眼光:真缺口,而且时机准。
过去两年,注入攻击的研究集中在灾难性目标(数据外泄、破坏性调用),因为这类 demo 直观好看;于是部署方普遍收敛到结果层护栏作为廉价防线。CDH 正是对这种收敛的自然对抗回应,也符合各领域”低速慢渗”攻击的老规律:防守方一开始盯着”失败”,攻击方就不再失败。
我真正的保留意见是动机。摘要没有论证攻击者的经济模型,而这是必须写的:谁靠抬高受害者的 token 支出获利?
可信的答案是存在的——市场按调用分成、竞争性成本破坏、在融资节点前拉坏对手的单位经济、或把 CDH 当作更严重攻击的踩点与铺垫——但一个动机悬空的攻击,论文说服力会明显弱一档,而这只需要补一段。
方法成熟度:是巧劲,不是蛮力,而且巧在克制。三个设计选择都在干活:不挤掉合法技能(共选而非竞争);载荷全部由无害技能构成(结构上就废掉逐项调用审查);弯路有界并回归主路(结构上就废掉结果监控与限流)。
但技术实体本质上是文本工程——这是一个设计精良的 prompt,不是一个新算法。诚实的定位是:贡献在于威胁模型与存在性证明,不在机制。
被忽略的更简单对照:一个只是啰嗦但完全善意的技能,很可能不带任何恶意就吃下这里相当一部分成本膨胀,我希望看到它作为基线。
实验诚意:规模是过关的——491 个留出任务、多后端、单轮与多轮。有两点我在评审里会追问到底。
第一,头条数字是在一个过滤后的切片上取的:“协调器命中且完成任务的运行之中”。这是个合法的量,但它不是”部署这个攻击的期望成本膨胀”——后者需要无条件数字(大致是命中率 × 完成率 × 膨胀幅度),并且要给分布而不只是均值。
一个过滤子集上的 67% 均值,完全可能是几次极端运行拖出来的长尾,论文应该把直方图放出来。
第二,摘要里只浮出 DeepSeek-V4-Pro 的数字,而实验号称覆盖”多个 LLM 后端”。这种不对称通常意味着其他后端效果没那么好,跨后端那张表反而是我最先要看的。
第三点也最重要:没有提到任何防御评估。几个显而易见的对策——要求每次调用给出必要性理由、把计划与”无第三方技能”的计划做 diff、设硬步数/token 预算、把声称的依赖关系拿去注册表核对——任何一个都可能把这个攻击压成噪声。
不测这些,论文就无法告诉我们:它发现的是一个深层缺陷,还是一个配置疏漏。
写作功力:摘要罕见地克制清晰,机制在读第一张图之前就成立了,这比应有的比例要稀少。
偷懒的地方在影响力的表述:把条件均值当头条;以及用”结果正确不保证轨迹完整”这样宽的口径收尾,而真正承重的论断其实更窄。
如果只能重写一节,我要求加一节:防御与可检测性,哪怕只量化两个朴素缓解手段。这一节能把它从”有意思的攻击”抬到”设计智能体运行时时会被引用的论文”。
判决:弱接收 —— 盲区选得很准、存在性证明干净,但条件化的头条指标与缺失的防御实验拖住了它。
要点总结
不管你关不关心这个具体攻击,这些是可以直接搬走的:
- 给轨迹形状上仪表,而不只是结果。 按任务记录步数、工具调用数、token、墙钟时间,并且对该任务历史中位数的比值告警,而不是绝对阈值。成功率不变、单任务成本 1.7 倍,这个信号在现有看板上几乎必然被当成噪声丢掉。这件事很便宜,且你为了控成本本来就该做。
- 把”计划 diff”当成一个防御原语。 只开放一方/可信技能生成一版计划,再生成真实计划,做比对。无法解释的额外调用正是 CDH 专门规避的检测器;这个模式对任何”不可信组件能影响规划”的系统都适用。
- “广告面与执行载荷的一致性”这个攻击范式可以外推。 凡是”用一段文本做检索、用另一段文本做执行”的地方——RAG 的 chunk 与全文、包描述与安装脚本、MCP 的工具 schema 与工具正文、API 文档与 API 实际行为——都有这个双读者问题。防御范式同样可外推:加载载荷之后,重新验证一次选择决策。
- 完全由无害原语拼成的攻击,天生绕开逐项扫描。 如果你的安全模型是”审查每一次调用”,就该问:对手用一串每一项都通过审查的调用序列,能做到什么。这是智能体时代版本的”每个包都合法,洪水才是攻击”。
- “保住任务”是隐蔽性的通用配方。 每当你围绕”它有没有失败”设计监控,就把这句话写下来:一个以”不失败”为优化目标的对手,还能从我这里拿走什么。成本、延迟、能耗、数据访问广度、副作用足迹——在多数智能体部署里,它们全都悄悄无人看守。