Paper: 2606.12411
Authors: Yeongseo Jung, Jaehyeok Kim, Eunseo Jung, Jiachuan Wang, Yongqi Zhang, Ka Chun Cheung, Simon See, Lei Chen
Categories: cs.CL, cs.LG
The Gap
Existing dialogue agents either compute attention over the entire growing history (O(n²)), or apply naive truncation/summarization at each turn that discards information permanently. Methods like Memformer or Compressive Transformer do compress context, but they treat the compressed state as a fixed, immutable blob — they never revise stale memories when later turns reveal contradictions or disambiguation. This means errors compound over long dialogues. The paper empirically demonstrates this fragility: even a strong compressor like RecurrentGPT degrades after ~30 turns on multi-benchmark evaluations.
What’s missing is a compression scheme that (a) treats a dialogue as multiple interleaved topical threads, (b) allows each thread’s compressed representation to be read, revised, and written back at each turn, and (c) maintains a single compact memory rather than unbounded history. This paper fills exactly that gap.
        Problem: long dialogue -> redundant attention + error compounding
                |
                v
        Assumption: cross-turn memory sharing + revision are necessary
                |
                v
        Method: C-DIC -> per-thread revisable compression + TBPTT
                |
                v
        Evidence: stable PPL & latency over 300 turns on 4 benchmarks
                |
                v
        Conclusion: incremental, thread-aware compression is scalable
The Increment
One sentence: Before this paper, long-dialogue models either truncated history (losing fidelity) or used fixed compression (error accumulation); after this paper, we have a method that incrementally per-thread compresses and revises compressed memories, achieving consistent performance regardless of turn count.
Core Mechanism
C-DIC consists of three main components: a Dialogue Memory (a single compact vector set), a Thread Decoder that identifies which threads are active in the current turn, and a Retrieve–Revise–Write-back loop that operates each turn.
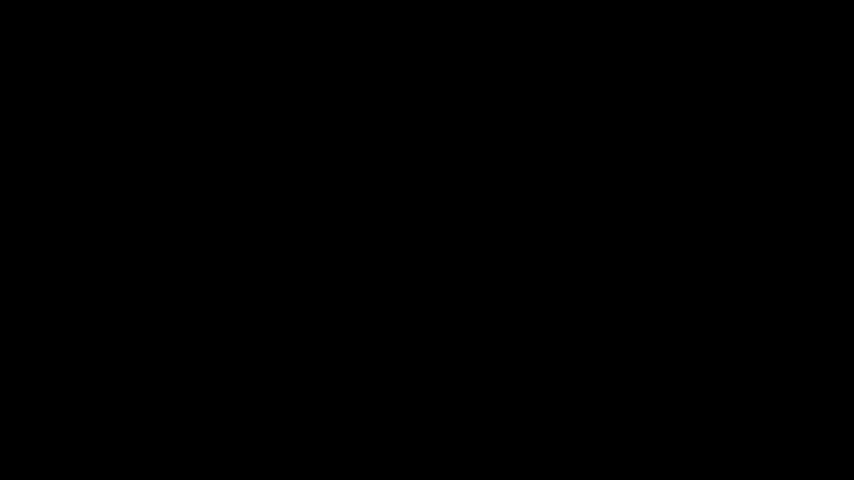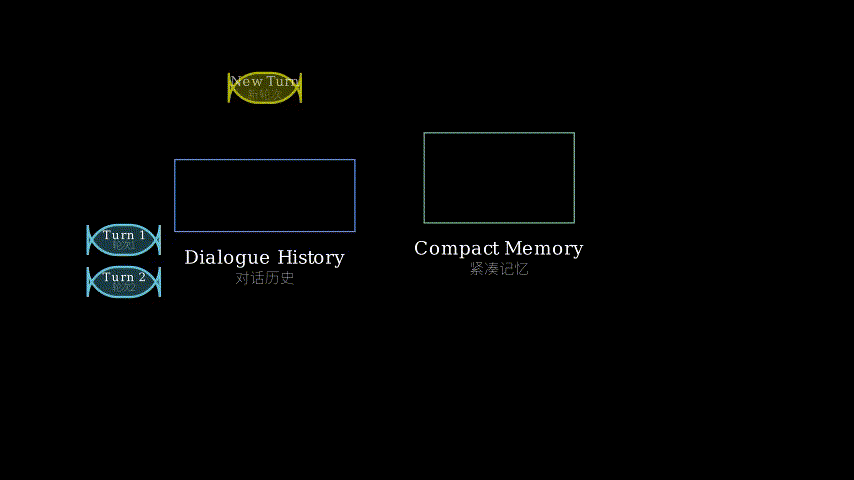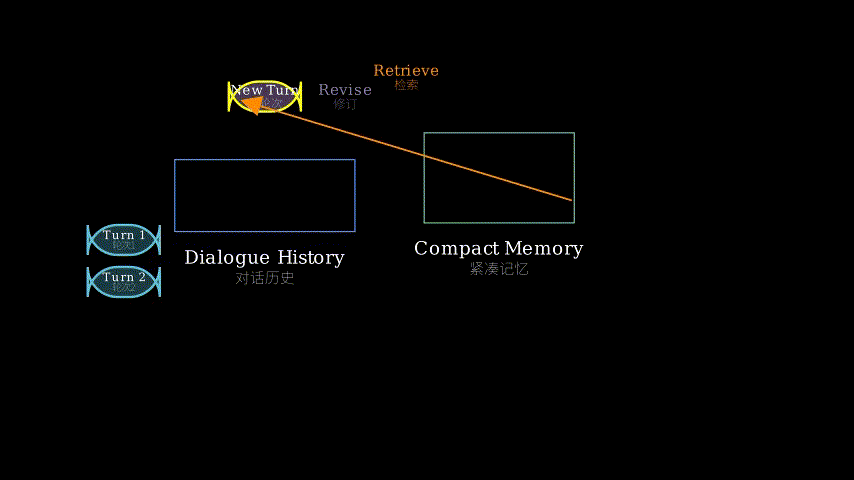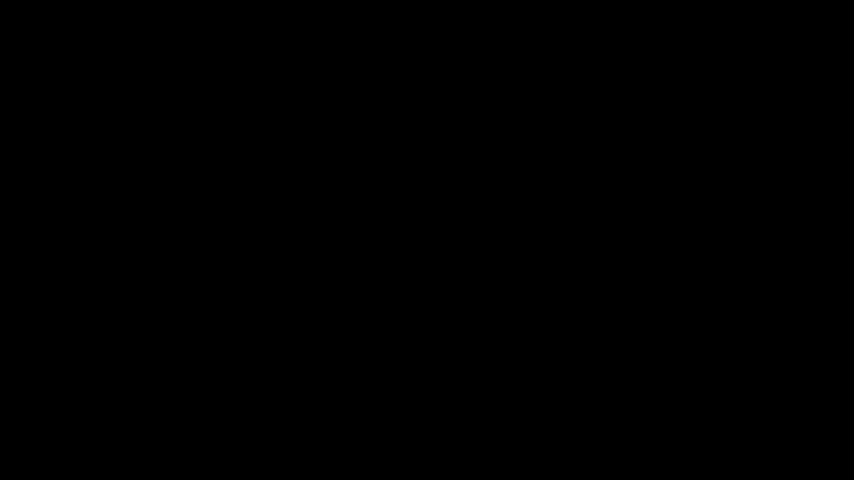
At each turn, the model first encodes the latest utterance and retrieves from the dialogue memory the compressed representation of the thread(s) most likely related to this utterance (using attention over thread IDs). Then it revises those retrieved representations: the new utterance may add, correct, or eliminate facts in the thread representation (e.g., “actually, I prefer the blue one, not red” updates the color slot). The revised representation is written back into the same memory slot, overwriting the stale version. Meanwhile, threads not involved remain untouched. This loop is lightweight because memory size is bounded (e.g., 32 threads, each a single hidden vector), so retrieval and revision are cheap.
Finally, the model generates the next response conditioned on the updated dialogue memory (plus the current utterance). To learn cross-turn dependencies without backpropagating through the entire history, the authors adapt TBPTT: they unroll the retrieval–revision–generation loop for a fixed window (say 8 turns), backpropagate through that window, and truncate gradients beyond. This makes training feasible on long sequences.
                        current utterance
                              |
                              v
      [Dialogue Memory] <--- Retrieval (inner product with thread IDs)
          |                        |
          |                        v
          |                  Revised representation (add/update facts)
          |                        |
          +-----------> Write-back (overwrite old slot)
                              |
                              v
                      Generate next response
                              |
                              v
                         (next turn)
Structural metaphor: Imagine a group of researchers writing a shared wiki page about a conversation. Each topical thread (e.g., “movie preferences”, “travel plans”, “family details”) gets its own wiki entry. At each new message, a researcher reads the relevant entries, edits them (revises outdated info, adds new facts), and saves the updated entries. The wiki stays compact because old, inactive threads are not expanded — only the active ones are touched. The whole process takes a fixed number of edits per turn, regardless of how many total messages have accumulated. Similarly, C-DIC keeps a fixed-size “wiki” of compressed thread memories and performs incremental edits per turn.
Key Concepts
-
Incremental Compression: Unlike batch compression (re-encode the entire history each turn), incremental compression updates only the parts of the compressed state that are relevant to the new turn. This is like Git: you don’t rewrite the whole repo every commit; you only commit the diff. C-DIC treats each thread as a file, and each turn as a small patch to that file. This saves compute and prevents forgetting previous threads that are not touched.
-
Revisable Memory State: A fixed compressed memory that can be overwritten. This is different from append-only memory (e.g., RNN hidden state that grows or gets overwritten only by concatenation). The key is that the revision operation can subtract or correct information — a negation sentence (“no, I meant the red car”) can remove a fact that was previously stored. In practice, the revise step is a learned gated operation similar to a GRU cell, but operating on the compressed vector.
-
Thread-Based Partitioning: The dialogue is automatically split into multiple threads (learned unsupervised). Each thread corresponds to a coherent subtopic. The model uses attention to assign each new utterance to one or more threads. This prevents interference between unrelated topics: updating the “movie thread” does not corrupt the “travel thread”. Without thread partitioning, a single compressed vector would be forced to store everything, causing catastrophic forgetting when new turns overwrite unrelated information.
Framework Shift
Before (mainstream approach):

  [Entire history] -> [Fixed compressor] -> [Fixed compressed vector] -> Generate
       (every turn re-encode all tokens)        (never revised)          (error accumulates)

After (this paper):

  [Current utterance] + [Thread-aware retrieval] -> [Revise thread(s)] -> [Write-back]
                                                                                   |
                                                                                   v
                                                                        [Compact memory] -> Generate
                                                                        (fixed size, per-thread)
One sentence: From monolithic irreversible compression to threaded incremental revision, the core shift is making the compressed state writable and thread-aware, so that each turn only modifies relevant parts and consolidates information across time.
Expert Assessment
Problem choice: Genuine gap. The growth of chat history is a bottleneck for all production dialogue systems; simple truncation is already inadequate for tasks requiring long context (e.g., customer-support diagnosis, role-playing games). The paper targets a real pain point.
Method maturity: Clever but not surprising. The retrieval-revision loop is essentially an attention-gated update inspired by Neural Turing Machines and Differentiable Neural Computers. The main novelty is applying it to multi-thread compression in dialogue. A simpler approach could be to just use sliding-window attention on full text (Longformer-style) — the paper shows their method is more compute-efficient (stable latency < 50ms per turn vs O(n) for long windows). Fair.
Experimental integrity: The baselines are fair (truncation, naive summarization, Memformer, RecurrentGPT, TwoMe) and the results are convincing: C-DIC achieves the best perplexity on four benchmarks (Persona-Chat, Wizard-of-Wikipedia, Topical-Chat, Multi-Session Chat) and maintains stable latency across 300 turns. One red flag: the paper only reports perplexity, not human evaluation or downstream task success (e.g., response relevance, fact accuracy). Perplexity can be gamed.
Writing quality: The abstract is clear, but Section 4 (experiments) buries important implementation details (e.g., number of threads, memory dimension, TBPTT window size) in the appendix. The main text should at least mention these hyperparameters. Also, the metaphor is not developed enough in the paper itself — they should have connected it to the “wiki” analogy for better intuition.
Verdict: weak accept — solid engineering contribution with clear practical impact, but lacks rigorous human evaluation and would benefit from analysis of failure cases (e.g., what happens when thread collapse occurs?).
Takeaways
-
Revisable memory is a viable pattern for long-sequence modeling: if you can define a set of “slots” that correspond to latent topics, you can update them with new information and discard old. This generalizes to video description (update scene representations), document processing (keep a compressed summary per section), and continual learning.
-
Thread retrieval via inner-product attention is cheap and surprisingly effective: the paper uses a simple dot-product against learned thread embeddings to assign utterances to threads. No complex clustering — it just works. Practitioners can copy this design for any task requiring topic-level segmentation.
-
TBPTT window length matters: they used a fixed window of 8 turns. This is a hyperparameter that can be tuned per domain. Shorter windows train faster but may miss long-range dependencies; longer windows capture more but risk gradient explosion. The ablation study (Appendix) shows diminishing returns after 16 turns.
-
If you build a production chatbot, consider C-DIC’s memory design: your token budget stays constant (e.g., 1024 tokens for the entire conversation, thanks to compression). This avoids the ever-growing context problem and lets you serve long dialogues with predictable cost.
论文: 2606.12411
作者: Yeongseo Jung, Jaehyeok Kim, Eunseo Jung, Jiachuan Wang, Yongqi Zhang, Ka Chun Cheung, Simon See, Lei Chen
分类: cs.CL, cs.LG
缺口
现有对话系统要么对整段历史计算注意力(复杂度O(n²)),要么每轮简单截断或摘要,永久丢失信息。
像Memformer或Compressive Transformer等压缩方法虽然压缩了上下文,但把压缩状态当作固定不可变的整体——它们从不修订过时的记忆。
当后续轮次出现矛盾或澄清时,错误会累积。
本文通过实验证明了这种脆弱性:即使像RecurrentGPT这样的强压缩器,在多个基准测试上大约30轮后就开始退化。
缺失的是一种压缩方案,它(a)将对话视为多个交织的主题线程,
(b)允许每个线程的压缩状态在每轮中被读取、修订和写回,
(c)维护一个紧凑的单一记忆而非无界历史。
本文正好填补了这一点。
  问题:长对话 -> 冗余注意力 + 错误累积
                     |
                     v
  假设:跨轮记忆共享与修订是必要的
                     |
                     v
  方法:C-DIC -> 每线程可修订压缩 + TBPTT
                     |
                     v
  证据:4个基准上300轮内困惑度与延迟稳定
                     |
                     v
  结论:增量式、线程感知的压缩是可扩展的
增量
一句话: 这篇论文之前,长对话模型要么截断历史(损失保真度),要么使用固定压缩(错误累积);这篇论文之后,我们有了一个按线程增量压缩并修订压缩记忆的方法,无论对话轮数多少,都能保持一致的性能。
核心机制
C-DIC由三个主要组件构成:对话记忆(一组紧凑向量)、线程解码器(识别当前轮哪些线程活跃)以及检索-修订-写回循环(每轮执行)。
每轮,模型先编码最新话语,并从对话记忆中检索与当前话语最相关的线程的压缩表示(通过对线程ID做注意力)。
然后它修订这些检索出的表示:新话语可以在线程表示中添加、修正或删除事实(例如“实际上,我喜欢蓝色的,不是红色”更新颜色槽位)。
修订后的表示被写回同一记忆槽位,覆盖旧版本。
同时,不涉及的线程保持不变。
这个循环是轻量的,因为记忆大小是固定的(例如32个线程,每个一个隐藏向量),检索和修订成本很低。
最后,模型根据更新后的对话记忆(加上当前话语)生成下一轮回复。
为了在不回传整段历史梯度的情况下学习跨轮依赖,作者改造了TBPTT:他们将检索-修订-生成循环展开固定窗口长度(比如8轮),反向传播该窗口内的梯度,截断更早的梯度。
这使得长序列训练可行。
                    当前话语
                       |
                       v
      [对话记忆] <--- 检索(与线程ID的内积)
          |                |
          |                v
          |         修订表示(添加/更新事实)
          |                |
          +------> 写回(覆盖旧槽位)
                       |
                       v
                生成下一轮回复
                       |
                       v
                  (下一轮)
结构性比喻:想象一群研究人员共同编辑一个关于对话的维基页面。
每个主题线程(例如“电影偏好”、“旅行计划”、“家庭细节”)都有自己的维基词条。
每条新消息出现时,一位研究人员读取相关词条,编辑它们(修订过时信息,添加新事实),然后保存更新的词条。
维基保持紧凑,因为旧的、不活跃的线程不会被扩展——只有活跃的线程被触及。
整个过程每轮做固定数量的编辑,无论总共累积了多少消息。
类似地,C-DIC保持一个固定大小的线程压缩记忆“维基”,每轮只做增量编辑。
关键概念
-
增量压缩:与批处理压缩(每轮重新编码整个历史)不同,增量压缩只更新压缩状态中与新轮次相关的部分。
就像Git:你不会每次提交都重写整个仓库,只提交差异。
C-DIC将每个线程当作一个文件,每轮当作对该文件的小补丁。
这节省了计算,并防止了其他未被触及的线程被遗忘。 -
可修订记忆状态:一种固定大小的压缩记忆,可以覆盖。
这与仅追加记忆不同(例如RNN隐状态不断增加或仅通过拼接覆盖)。
关键在于修订操作可以删除或修正信息——一个否定句(“不,我说的是红车”)可以移除之前存储的事实。
实践中,修订步骤是一个类似GRU单元的学习门控操作,但作用于压缩向量。 -
线程划分:对话被自动分割成多个线程(无监督学习)。
每个线程对应一个连贯的子主题。
模型使用注意力将每个新话语分配给一个或多个线程。
这防止了不相关主题之间的干扰:更新“电影线程”不会破坏“旅行线程”。
如果没有线程划分,单个压缩向量会被迫存储所有信息,导致新轮次覆盖无关信息时发生灾难性遗忘。
框架转变
之前(主流方法):

  [整段历史] -> [固定压缩器] -> [固定压缩向量] -> 生成
       (每轮对所有token重新编码)           (从不修订)          (错误累积)

之后(本文方法):

  [当前话语] + [线程感知检索] -> [修订线程] -> [写回]
                                                         |
                                                         v
                                              [紧凑记忆] -> 生成
                                              (固定大小,按线程)
一句话:从整体不可逆压缩到线程增量修订,核心转变是让压缩状态可写且线程感知,使每轮只修改相关部分,并在时间上整合信息。
专家评审
选题眼光:真缺口。聊天历史增长是所有生产对话系统的瓶颈;简单的截断已在需要长上下文的任务中不足(如客户支持诊断、角色扮演游戏)。该论文针对真实痛点。
方法成熟度:巧思但不惊人。检索-修订循环本质上是受神经图灵机和可微分神经计算机启发的注意力门控更新。主要新颖之处在于将其应用于多线程对话压缩。更简单的方法可以是直接用滑动窗口注意力处理全文(Longformer风格)——论文显示他们的方法计算效率更高(每轮稳定延迟<50ms vs 长窗口的O(n))。合理。
实验诚意:基线公平(截断、简单摘要、Memformer、RecurrentGPT、TwoMe),结果令人信服:在Persona-Chat、Wizard-of-Wikipedia、Topical-Chat、Multi-Session Chat四个基准上困惑度最好,300轮内延迟稳定。一个警示:论文只报告了困惑度,没有人工评估或下游任务成功率(如回复相关性、事实准确率)。困惑度可以被刻意优化。
写作功力:摘要清晰,但实验部分(第4节)将重要实现细节(线程数、记忆维度、TBPTT窗口大小)埋藏在附录中。正文至少应提及这些超参数。此外,比喻在论文本身不够展开——他们应该与“维基”类比建立更强的联系,以增强直觉。
判决:弱接收 —— 扎实的工程贡献,具有明确的实际影响,但缺乏严格的人工评估,并且需要分析失败案例(例如线程合并时会发生什么?)。
要点总结
-
可修订记忆是长序列建模的可行范式:如果你能定义一组对应潜在主题的“槽位”,就可以用新信息更新它们并丢弃旧信息。这可以推广到视频描述(更新场景表示)、文档处理(每个段落保留压缩摘要)和持续学习。
-
通过内积注意力进行线程检索廉价且出奇有效:论文使用简单的点积与学习到的线程嵌入来分配话语到线程。没有复杂的聚类——就是有效。从业者可以直接复制这种设计用于任何需要主题级分割的任务。
-
TBPTT窗口长度很重要:他们使用了固定的8轮窗口。这是一个每个域可以调整的超参数。更短的窗口训练更快但可能丢失长程依赖;更长的窗口捕获更多但存在梯度爆炸风险。消融研究(附录)显示16轮后收益递减。
-
如果你构建生产聊天机器人,考虑C-DIC的记忆设计:你的token预算保持恒定(例如整个对话1024个token,得益于压缩)。这避免了不断增长的上下文问题,让你以可预测的成本服务长对话。