Paper: 2606.17053 Authors: Peiyang Xu, Bangzheng Li, Sijia Liu, Karthik R. Narasimhan, Pramod Viswanath, Prateek Mittal, Xingyu Fu Categories: cs.CL, cs.CV
The Gap
Standard RL fine-tuning for LLMs (GRPO, PPO) treats each training example as a single reward signal on the final output. This works fine when the reasoning chain is short or the evidence is obvious, but it breaks when a critical piece of evidence is buried in a long tool trace, or when a tiny visual detail determines the correct answer. Recent work has tried to mitigate this by augmenting contexts with extra retrieval or by using step‑wise rewards, but those require expensive human annotation or assume the evidence locations are known in advance. The core assumption behind ContextRL is that the model already sees all the evidence – it just isn’t forced to pay attention to it. The authors propose an indirect auxiliary objective: instead of telling the model to produce a better answer, they give it a binary choice between two near‑identical contexts and reward the correct selection. This shifts the learning signal from answer accuracy to evidence localization.
[Problem]                         [Assumption]
LLMs ignore subtle evidence -----> Fine-grained grounding
  in long / multimodal contexts     requires more than
                                    answer-level reward
         |
         v
   [Method: ContextRL]
   - Build contrastive context pairs (1k code + 7k images)
   - Reward model for selecting the context that supports
     a fixed (query, answer) pair
   - Combine with standard GRPO on main task
         |
         v
   [Evidence]
   +2.2% avg on 5 long-horizon benchmarks
   +1.8% avg on 12 VQA benchmarks
   Data-augmentation baselines show no gain ==> objective matters
         |
         v
   [Conclusion]
   Indirect context-selection reward is an effective,
   data-efficient way to improve fine-grained grounding
ASCII logic topology:
+-------------------------------------+
| LLMs miss subtle evidence in        |
| long context                        |
+------------------+------------------+
                   |
                   v
+------------------+------------------+
| Assumption: need fine-grained       |
| supervision beyond final answer     |
+------------------+------------------+
                   |
                   v
+------------------+------------------+
| Method: ContextRL                   |
| - Contrastive context pairs         |
| - RL reward for correct selection   |
| - Combined with main-task RL        |
+------------------+------------------+
                   |
                   v
+------------------+------------------+
| Evidence: gains over GRPO;          |
| data-aug baselines fail ==>         |
| objective is the active ingredient  |
+------------------+------------------+
                   |
                   v
+------------------+------------------+
| Conclusion: indirect auxiliary RL   |
| objective improves grounding        |
+-------------------------------------+
The Increment
One sentence: Before this paper, standard RL ignored subtle evidence because it only rewarded the final answer; after ContextRL, the model is explicitly rewarded for selecting the correct supporting context – a cheap auxiliary signal that yields consistent gains without additional supervision on the reasoning path.
Core Mechanism
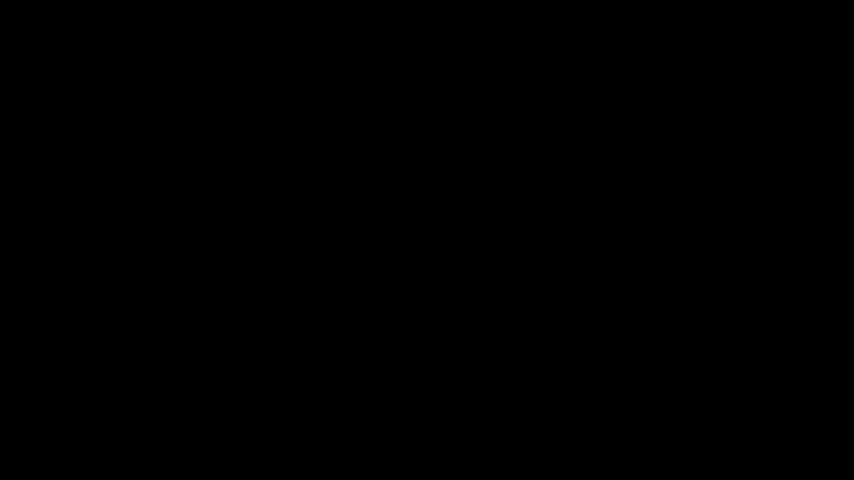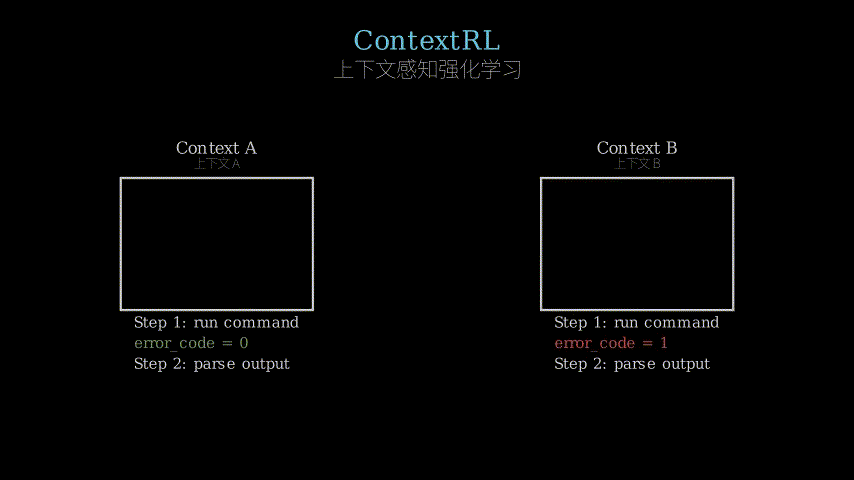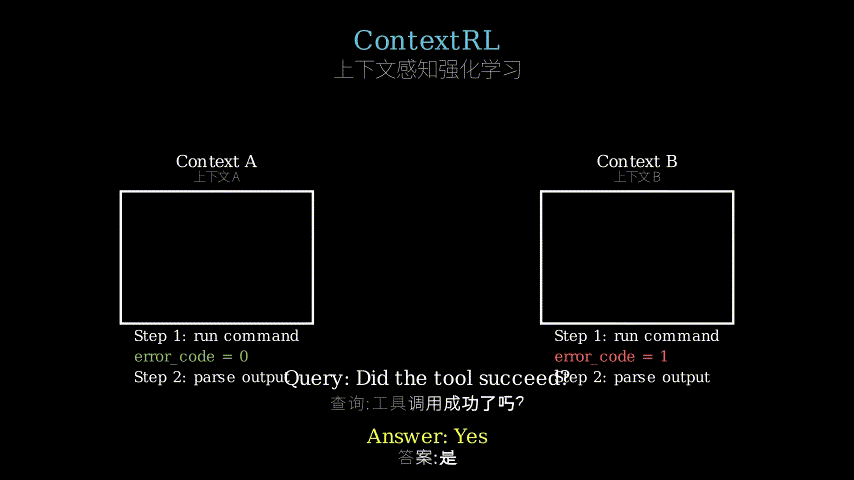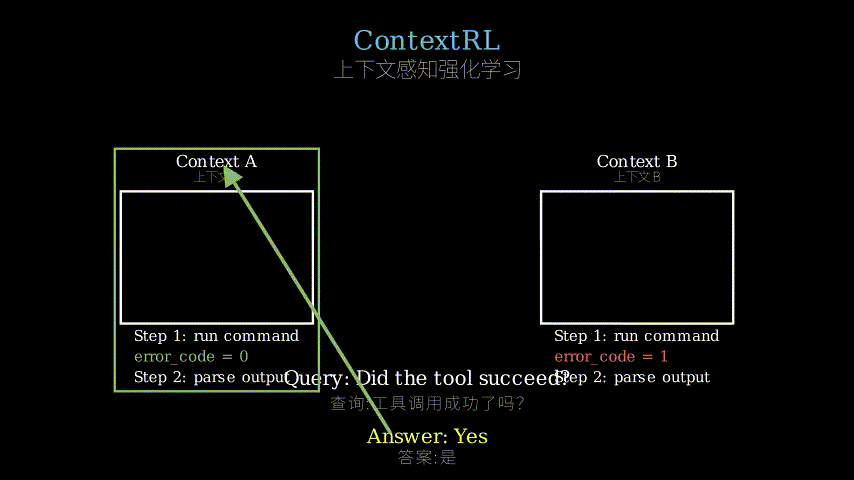
The method has three layers: data construction, reward design, and joint training. First, they create contrastive context pairs. For coding agents (long‑horizon reasoning), they take trajectories from a code‑execution environment and filter pairs where two trajectories lead to different outcomes but are superficially similar – e.g., one line difference in a tool call. For multimodal reasoning, they take images and use generative editing (caption‑guided image manipulation) plus embedding similarity search to produce two images that differ only in the critical detail (e.g., a traffic light changing from red to green). In total they build 1k code context pairs and 7k image context pairs.
Second, the reward function: given a (query, answer) pair that is kept fixed, and two contexts (C_left, C_right) that are highly similar, the model must select which context is the correct one for that answer. The reward is 1 for a correct selection, 0 otherwise. This selection can be formulated as a binary classification head on top of the LLM, or as a decision at the end of a generated chain (e.g., “Context A is correct”). Importantly, the main task (answer generation) is still trained with standard GRPO. The context‑selection loss is added as an auxiliary term with a tunable weight.
Third, during training, each batch contains both standard (query, context, answer) triplets for the main task and (query, answer, C_left, C_right) quadruplets for the auxiliary task. The total loss is GRPO loss + lambda * context‑selection loss. The auxiliary reward forces the model’s internal representations to be sensitive to the feature that distinguishes the two contexts – exactly the kind of fine‑grained grounding that long‑horizon and multimodal tasks demand.
[Data Flow in ContextRL]

Main Task Batch:
  (query, context, answer) ---------> LLM -------> main answer
                                              |
  Auxiliary Task Batch:                       |
  (query, answer, C_left, C_right)            |
        |                                     |
        v                                     |
  LLM encodes both contexts (tied or shared)  |
        |                                     |
        v                                     |
  Selection output (left / right) ---------> reward: 0 or 1
                                              |
                                              v
  Total loss = GRPO_loss + lambda * aux_loss
Structural Metaphor: Think of the model as a detective questioning a witness. The witness (query + answer) describes a crime scene: “The suspect wore a red scarf and entered through the window.” Two crime‑scene photos (contexts) are nearly identical – in one the scarf is red, in the other it’s maroon. Standard RL says: “Did you find the suspect? Great, here’s a cookie.” ContextRL says: “Before I give you a cookie for finding the suspect, show me WHICH photo you used. If you picked the wrong photo but still found the right suspect, you get half credit. Let’s start by making sure you can see the red vs maroon difference.” In this metaphor, the detective’s ability to identify the correct photo is the auxiliary objective. Even if the detective is lucky with the final answer, failing the photo test forces retraining on subtle visual clues. Over many iterations, the detective becomes better at spotting the tiniest details in all crime‑scene photos – i.e., the LLM’s representations get sharper.
Key Concepts
-
Contrastive Context Pair: Two pieces of context (text or image) that are superficially identical except for a single feature that determines the correctness of a given answer. For example, one code trajectory prints “Success” because a check passed, another prints “Failure” because a single variable was missing. The contrast is not about the answer (the answer is always fixed) but about the context that supports it. Constructing these pairs is the main engineering effort. The paper shows that naively using the same data as standard (query‑context‑answer) triplets gives no benefit – the format of the auxiliary task is what matters.
-
Indirect Auxiliary Objective: Instead of directly optimizing the final performance (answer accuracy), you optimize a proxy task that forces the model to use the relevant information in the context. This is indirect because the model is rewarded for which context is correct, not for producing a correct answer from that context. Yet improving this proxy empirically improves the downstream answer accuracy – because the model’s attention and internal feature extraction become more faithful.
-
GRPO (Group Relative Policy Optimization): A variant of PPO for language models where multiple responses are sampled per input, and the advantage is computed relative to the group average rather than an absolute baseline. ContextRL layers its auxiliary reward on top of GRPO’s original reward. The key is that the auxiliary reward is a binary signal (0/1) that is orthogonal to the main reward (which can be sparse or continuous), providing a denser gradient on the feature‑extraction part of the model.
Framework Shift
Before (standard GRPO):
  [Temp: reward on final answer only]

  (query, context) ---> LLM ---> answer
                                |
                                v
                           reward = accuracy(answer, gt)
                                |
                                v
                           update LLM to increase reward

  Problem: if the answer is right by accident (e.g., the model ignores context but guesses well), reward is high; model never learns to use subtle context.

After (ContextRL):
  [Temp: auxiliary reward on context selection]

  Main path:
    (query, context) ---> LLM ---> answer
                                |
                                v
                           main reward = accuracy(answer, gt)

  Auxiliary path:
    (query, answer, C_left, C_right) ---> LLM ---> selection
                                                |
                                                v
                           aux reward = 1 if correct context selected
                                |
                                v
                           total reward = main + lambda * aux
                                |
                                v
                           update LLM to increase both rewards

  Key: the auxiliary reward directly penalizes ignoring the context, even when the main answer is correct. This forces the model to align its internal features with the discriminative details in the contexts.
One sentence: From “reward the answer” to “also reward the evidence you used”, the core shift is making the model accountable for its reasoning substrate – a meta‑level signal that improves generalization across tasks.
Expert Assessment
Problem choice: Real gap. The paper targets a known failure mode of LLMs: missing signals in long or complex contexts. It’s not a manufactured problem – every practitioner has seen a model get the right answer for the wrong reason. Situating this within the RL fine‑tuning paradigm is timely (GRPO is hot) and the contrastive approach is a natural fit.
Method maturity: Clever, not brute force. The insight that you can reuse the same data as contrastive pairs with a different loss function, and that this gives gains over just using the data as more examples, is elegant. The data construction is non‑trivial but feasible; the paper describes specific strategies for two domains. Simpler alternatives (e.g., just adding a contrastive loss in supervised fine‑tuning) might work too, but the RL framing aligns with the main task. Some concerns: the auxiliary reward is binary and may saturate; the weight lambda is crucial and was swept – a sensitivity analysis would strengthen the paper.
Experimental integrity: Baselines are fair. They compare against GRPO (no auxiliary), and against data‑augmentation baselines that use the same contrastive pairs but as ordinary (query, context, answer) examples. This is a clean ablation that isolates the effect of the auxiliary objective. Gains are modest (2‑2%) but consistent across many benchmarks (5 + 12). One red flag: the paper doesn’t report variance across seeds; small improvements could be noise. But the multi‑benchmark consistency mitigates this. Also, the contexts in the auxiliary task are the same as those used in the main task? If they leak information (e.g., the correct context is always the first one shown), performance could be artificially high. The paper should randomize order.
Writing quality: Generally clear. The method section could be more explicit about how the selection decision is implemented (classification head? token‑level?); currently it’s hand‑waved. The related work is thin – they could better differentiate from contrastive learning and step‑wise reward baselines. A rewritten “Implementation Details” subsection with pseudo‑code would elevate the paper.
Verdict: Strong accept – clean idea, well‑executed ablation, and the contrastive context pairs are a reusable resource. The modest gain is acceptable given the task difficulty and the simplicity of the intervention.
Takeaways
- Data augmentation trick: You can take your existing (query, context, answer) data and re‑pair contexts to create contrastive examples. The key is that the answer must be fixed and the contexts must be highly similar (so the only way to pick the correct one is to notice the subtle difference). This is a cheap way to generate dense training signals without human annotation.
- Auxiliary objective design: If your main RL reward is sparse (only correct/incorrect), consider adding a discrimination‑based auxiliary reward that forces the model to separate two nearly‑identical inputs. This can be applied to any domain where you have multiple contexts for the same query‑answer pair, such as multi‑document QA, legal reasoning, or medical diagnosis.
- Evaluation methodology: The paper’s greatest contribution to evaluation practice is the “data‑augmentation baseline” – many papers claim gains from new objectives but fail to control for the extra data. Always run this control: use the same data but with a standard loss, and compare. If the gain disappears, it’s not your objective that matters.
论文: 2606.17053 作者: Peiyang Xu, Bangzheng Li, Sijia Liu, Karthik R. Narasimhan, Pramod Viswanath, Prateek Mittal, Xingyu Fu 分类: cs.CL, cs.CV
缺口
标准强化学习微调(GRPO、PPO)只给最终输出一个奖励信号。 这在推理链短或证据明显时没问题,但当关键证据埋在长长的工具调用日志里,或者图片里一个像素决定答案时,它就失效了。 最近的工作用检索增强或分步奖励来缓解,但要么需要昂贵的人工标注,要么预先知道证据位置。 ContextRL 的核心假设是:模型其实看到了全部证据,只是没有被强迫去注意它们。 作者提出了一个间接辅助目标:不给模型更高的答案奖励,而是给它两条几乎一样的上下文,让它在其中选出支持给定问答的那条,并奖励正确选择。 这样就把学习信号从答案正确性转移到了证据定位能力上。
[问题]                         [假设]
LLM 忽略长上下文或                     需要比最终答案
多模态中的细微证据                     更细粒度的监督
         |
         v
   [方法: ContextRL]
   - 构建对比上下文对 (1k 代码 + 7k 图片)
   - 奖励模型选出支持固定 (查询, 回答) 的上下文
   - 与主任务的 GRPO 联合训练
         |
         v
   [证据]
   5 个长程推理基准平均 +2.2%
   12 个视觉问答基准平均 +1.8%
   数据增广基线无提升 ==> 是目标函数起了作用,不是数据本身
         |
         v
   [结论]
   间接上下文选择奖励是一种有效、节省数据的
   细粒度理解改进方法
ASCII 逻辑拓扑:
+---------------------------+
| LLM 在长上下文中          |
| 遗漏细微证据              |
+----------+----------------+
           |
           v
+----------+----------------+
| 假设:需要超越            |
| 最终答案的细粒度监督      |
+----------+----------------+
           |
           v
+----------+----------------+
| 方法:ContextRL            |
| - 对比上下文对             |
| - RL 奖励正确选择          |
| - 与主任务 RL 联合         |
+----------+----------------+
           |
           v
+----------+----------------+
| 证据:优于 GRPO;          |
| 数据增广基线无效 ==>       |
| 目标函数是真正生效的因素   |
+----------+----------------+
           |
           v
+----------+----------------+
| 结论:间接辅助 RL 目标     |
| 提升了证据定位能力         |
+---------------------------+
增量
一句话: 在这篇论文之前,标准 RL 只奖励最终答案,所以模型可以忽略上下文瞎猜;之后,ContextRL 额外奖励“选出正确的上下文”这个动作——一个便宜的辅助信号,且不需要对推理路径额外监督,就在多个任务上带来了一致提升。
核心机制
方法分为三层:数据构建、奖励设计、联合训练。 首先,构建对比上下文对。 对于代码 agent(长程推理),他们从代码执行环境获取轨迹,通过条件过滤选出两条结果不同但表面相似的轨迹——例如只有一行工具调用不同。 对于多模态推理,他们用生成式编辑(基于标题的图片修改)加上向量相似度搜索,得到两张只在关键细节上不同的图片(比如交通灯从红变绿)。 总共构建了 1k 个代码上下文对和 7k 个图片上下文对。
其次,奖励函数:给定一个固定的(查询, 回答)对,以及两条高度相似的上下文(C_left, C_right),模型必须选出哪条上下文是该回答的正确依据。 选择正确得 1,错误得 0。 这个选择可以用 LLM 顶层的二分类头实现,也可以放在生成的末尾(比如模型说“上下文 A 正确”)。 重要的是,主任务(生成答案)仍然用标准 GRPO 训练。 上下文选择损失作为一个辅助项加入,通过权重 lambda 调节。
第三,训练时,每个 batch 同时包含主任务所需的(查询, 上下文, 回答)三元组和辅助任务所需的(查询, 回答, C_left, C_right)四元组。 总损失 = GRPO 损失 + lambda * 上下文选择损失。 辅助奖励强迫模型的内部表示对两条上下文之间的细微差异敏感——这正是长程和多模态任务需要的细粒度定位能力。
[数据流]

主任务 batch:
  (query, context, answer) ---------> LLM -------> 主回答
                                              |
辅助任务 batch:                                |
  (query, answer, C_left, C_right)            |
        |                                     |
        v                                     |
  LLM 编码两条上下文(共享或分开)              |
        |                                     |
        v                                     |
  选择输出(left / right) ----------> 奖励: 0 或 1
                                              |
                                              v
  总损失 = GRPO_loss + lambda * aux_loss
结构比喻:把模型当作一个侦探在询问证人。 证人(查询+回答)描述现场:“嫌疑人戴红围巾,从窗户进入。” 两张现场照片(上下文)几乎一样——一张围巾是红色,另一张是暗红。 标准 RL 说:“你抓到嫌疑人了?好,给你饼干。” ContextRL 说:“在给你饼干之前先告诉我你用了哪张照片。 如果照片选错但人抓对了,只给半块饼干。 我们先确保你分清红色和暗红。” 在这个比喻里,侦探识别正确照片的能力就是辅助目标。 即使侦探运气好猜对了嫌疑人,选错照片也会扣分,让他不得不重新关注细微线索。 多次迭代后,侦探对所有现场照片的细节都变得敏锐——即 LLM 的表示变得更加精准。
关键概念
-
对比上下文对:两条上下文(文字或图片)表面几乎一样,只在一个决定答案是否成立的属性上不同。 例如一条代码轨迹输出“成功”因为检查通过,另一条输出“失败”因为一个变量缺失。 对比的关键不是答案(答案是固定的),而是支持该答案的上下文。 构建这样的对比对是主要的工程工作量。 论文证明,如果只是把这些数据当作普通的(查询, 上下文, 回答)三元组来用,几乎没有提升——辅助任务的格式才是重点。
-
间接辅助目标:不是直接优化最终性能(答案正确率),而是优化一个代理任务,迫使模型使用上下文中的相关信息。 说它间接,是因为奖励的是哪条上下文正确,而不是从那条上下文产生正确的答案。 然而优化这个代理任务在经验上提升了下游答案准确率——因为模型注意力和内部特征提取变得更忠诚于证据。
-
GRPO(组相对策略优化):PPO 的一个变体,对每个输入采样多个回复,用组平均值作为基线计算优势。 ContextRL 把它的辅助奖励叠加在 GRPO 的原始奖励之上。 关键是辅助奖励是二值信号(0/1),与主奖励(可能稀疏或连续)正交,在模型的特征提取部分提供了更稠密的梯度。
框架转变
之前(标准 GRPO):
  [重点:只奖励最终答案]

  (查询, 上下文) ---> LLM ---> 答案
                                |
                                v
                           奖励 = 答案准确率
                                |
                                v
                           更新 LLM 提高奖励

  问题:如果模型蒙对了答案(比如忽略了上下文但猜对了),奖励很高;模型永远学不会利用细微上下文。

之后(ContextRL):
  [重点:增加辅助目标奖励上下文选择]

  主路径:
    (查询, 上下文) ---> LLM ---> 答案
                                |
                                v
                           主奖励 = 答案准确率

  辅助路径:
    (查询, 回答, C左, C右) ---> LLM ---> 选择
                                        |
                                        v
                           辅奖励 = 1 如果选中正确上下文
                                |
                                v
                           总奖励 = 主 + lambda * 辅
                                |
                                v
                           更新 LLM 同时提高两种奖励

  关键:即使主答案正确,辅助奖励也会直接惩罚忽视上下文的行为。
  这迫使模型把内部特征与上下文的判别性细节对齐。
一句话:从“奖励答案”到“也奖励你用了什么证据”,核心转变是让模型对其推理依据负责——一个元层面的信号,提升了跨任务的泛化能力。
专家评审
选题眼光:真缺口。 作者瞄准了 LLM 一个已知的失败模式:在长或复杂上下文中遗漏信号。 这不是人造问题——每个实践者都见过模型用错误理由得到正确答案。 把这个放在 RL 微调范式中非常及时(GRPO 正在热门),对比式方法也很自然。
方法成熟度:巧劲,不是蛮力。 把同样的数据换一种损失函数变成对比对就能产生增益,而且比直接用更多数据效果好——这个洞察很优雅。 数据构建不平凡但可行;论文针对两个领域给出了具体策略。 可能有更简单的替代方案(比如在监督微调中加入对比损失),但 RL 框架与主任务一致是合理的。 一个隐忧:辅助奖励是二值的,可能容易饱和;超参 lambda 做了扫描但没给出敏感性分析,这会增强可信度。
实验诚意:基线公平。 他们对比了 GRPO(无辅助),以及用相同的对比对但当作普通(查询, 上下文, 回答)三元组的数据增广基线。 这个消融干净地隔离了辅助目标的效果。 增益不大(2-2%)但在多个基准上一致(5 + 12)。 一个红旗:论文没有报告多次实验的方差;小提升可能是噪音。但多基准的一致性减轻了这个担忧。 另外,辅助任务中的上下文和主任务中的上下文是否相同?如果信息泄露(比如正确上下文总是第一个出现),可能会人为提高性能。论文应该随机化展示顺序。
写作功力:总体清晰。 方法部分可以更明确地说明“选择”是怎么实现的(分类头?token 级?),目前有点含糊。 相关工作写得不够厚——可以更好地区分对比学习和分步奖励基线。 如果能重写一个“实现细节”小节并附上伪代码,整篇论文会升一个档次。
判决:强接收 —— 想法干净,消融实验执行到位,对比上下文对是可复用的资源。鉴于任务难度和干预的简单性,2% 的增益是可以接受的。
要点总结
- 数据增广技巧:你可以把自己现有的(查询, 上下文, 回答)数据重新配对成对比对。关键是答案必须固定,上下文必须高度相似(以至于唯一能选出正确上下文的方式就是注意到细微差异)。这是一个低成本生成稠密训练信号的方法,无需人工标注。
- 辅助目标设计:如果你的主 RL 奖励很稀疏(只有对/错),可以考虑增加一个基于判别的辅助奖励,迫使模型分离两个几乎相同的输入。这可以应用于任何有多个上下文对应同一个查询-回答对的领域,比如多文档问答、法律推理或医疗诊断。
- 评估方法论:这篇论文对评估实践的最大贡献是“数据增广基线”——很多论文声称新目标带来了提升,但没有控制额外数据的因素。一定要跑这个对照:用同样的数据但用标准损失训练,然后比较。如果提升消失了,那并不是你的目标函数起了作用。