Paper: 2608.09898 Authors: Lecheng Kong, Like Hui, Haitao Mao, Jun Huan Categories: cs.CL, cs.LG
The Gap
Test-time scaling is simple in principle: sample N rollouts, keep the good one. The whole difficulty is “keep the good one.” With a verifier — a compiler, a unit test suite, a learned value function — the problem is basically solved. Without one, you need a proxy signal, and the field has converged on a small menu: majority voting / self-consistency (needs an extractable, comparable answer, so it dies on free-form code), LLM-as-judge (another full forward pass per candidate, and the judge inherits the generator’s blind spots), and confidence-based scoring — rank rollouts by mean token log-probability, by perplexity, by self-certainty, or by the lowest-confidence window inside the trace (the DeepConf family).
Confidence-based scoring is the attractive branch because it is nearly free. You already have the logits. No extra sampling, no extra model, no task-specific parsing. It works across models and tasks with minimal access to internals.
This paper’s contribution is to show where that branch breaks, and it breaks in a specific and interesting way. On hard problems, ranking by aggregate confidence does not just degrade toward random — it actively selects wrong answers. The reason: for a difficult question, a rollout with uniformly high confidence from token one is a rollout that never considered an alternative. Flat high confidence is a signature of failed exploration, not of competence. Aggregate-confidence scoring is therefore systematically biased toward the confidently wrong.
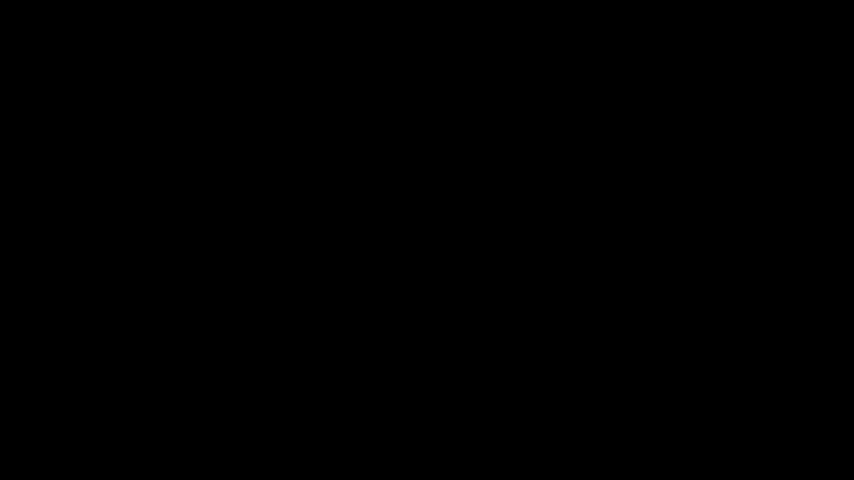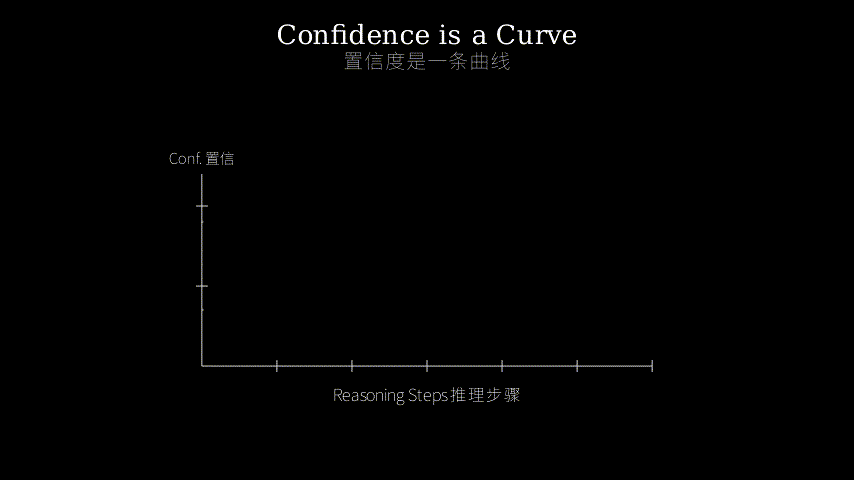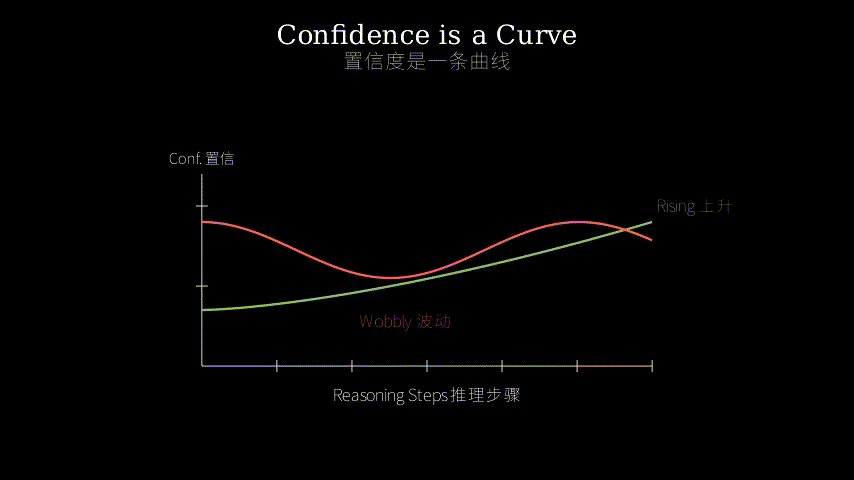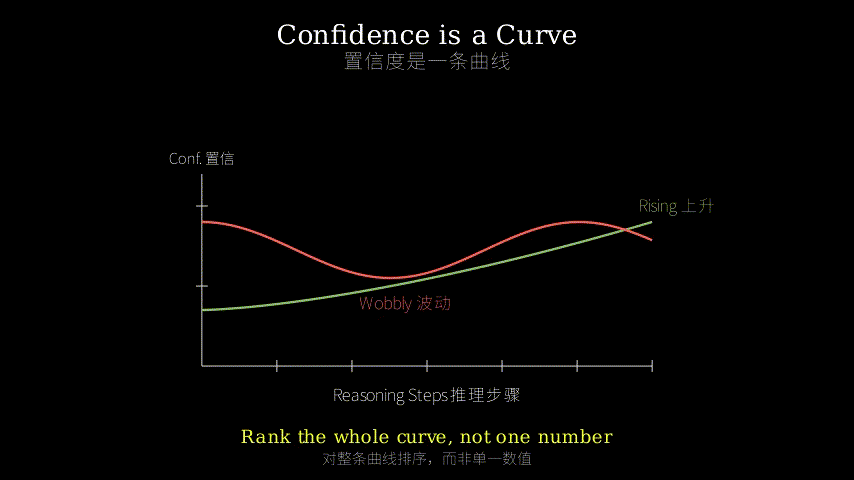
The proposed fix is to stop treating confidence as a scalar summary and start treating it as a trajectory with a diagnostic shape: doubt early, certainty late.
[ Problem ]
  no verifier at test time
  must pick 1 of N rollouts using only internal signals
      |
      v
[ Prior art ]
  score = aggregate over all tokens
  mean logprob / perplexity / self-certainty / min-window conf
      |
      v
[ Observed breakdown ]
  on hard tasks the winners are the flat-high-confidence rollouts
  those are exactly the ones that never branched
  ==> confidently wrong answers get promoted
      |
      v
[ Assumption ]
  good cognitive search has a SHAPE
  low confidence early: exploratory branching
  high confidence late: convergence on a solution
      |
      v
[ Method: consilience ]
  split trace into early and late
  combinatorial score that punishes early certainty
  and strictly demands late certainty
      |
      v
[ Evidence ]
  graduate-level mathematics + free-form code generation
  outperforms confidence and voting baselines
      |
      v
[ Conclusion ]
  the informative part of confidence is its temporal asymmetry
  not its average
The Increment
One sentence: Before, verifier-free selection asked “how confident is this rollout”; after, it asks “did this rollout earn its confidence” — the same logits, read as a time series instead of a number.
Core Mechanism
Start where every confidence method starts. Sample N rollouts for a prompt. For each rollout you have a per-token confidence series c(t) — some monotone function of the token distribution, typically the log-probability of the emitted token or a negative-entropy style self-certainty. Prior methods collapse c(t) into one number: mean, min, or the minimum over sliding windows. Collapsing is exactly where the information dies, because mean and min are order-invariant. A trace that doubts then commits and a trace that commits then doubts get identical scores.
Consilience keeps the ordering. Split the trace into a head region and a tail region, aggregate confidence separately in each, and combine them asymmetrically: the tail term rewards high confidence (the model must actually land somewhere), while the head term is penalized for high confidence (a model that was sure before it did any work is suspect). The abstract describes this as a combinatorial metric that “actively penalizes high initial confidence while strictly demanding final certainty” — read it as a monotone combination S = g(tail) - lambda * h(head), where the “strictly demanding” phrasing suggests the tail acts closer to a hard gate than a soft additive term. Rank by S, return the argmax. Cost over vanilla best-of-N confidence: one extra pass over an array you already have.
The critical structural point is that this comparison happens within a question. All N rollouts face the same problem, so difficulty is held fixed. That matters, because across questions “low early confidence” mostly measures how hard the question is — an easy arithmetic problem should be answered confidently from token one, and penalizing that would be nonsense. Within a fixed question, low early confidence measures something else: which of these N attempts actually opened up the space before closing it.
prompt
  +--> rollout 1 : c1 c2 c3 ... cT
  +--> rollout 2 : ...
  +--> rollout N : ...

read each rollout as a confidence trajectory

  conf
  1.0 |                  ...._____   commit
      |          ___/~~~~
  0.5 |     ___/
      |  __/    doubt
  0.0 +--------------------------------> t
        GOOD SHAPE: explored then converged

  conf
  1.0 |~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
  0.5 |
  0.0 +--------------------------------> t
        BAD SHAPE: never doubted
        flat high == no branching == likely wrong on hard tasks

  conf
  1.0 |  ___
      | /   \____                 ....
  0.5 |            \___     ..../
  0.0 +--------------------------------> t
        BAD SHAPE: ends hedging == no convergence

scoring:
  HEAD = early segment of c(t)
  TAIL = late segment of c(t)

  A = agg( HEAD )    "was it sure before it thought"
  B = agg( TAIL )    "did it land on something"

  S = g( B )  -  lambda * h( A )
      ^^^^^^         ^^^^^^^^^^^
      demand         penalize

rank by S  ==>  argmax  ==>  final answer
The metaphor: this is a detective case review, and the review board never gets to check whether the arrest was actually correct.
Each rollout is a detective who worked the same case. The board cannot verify the verdict — no confession, no DNA, no verifier. All it has is each detective’s own log of how certain they felt, hour by hour.
The old policy was to promote whichever detective was most confident on average across the whole investigation. On a routine case that is fine. On a genuinely hard case it selects for the worst possible officer: the one who walked into the room, decided it was the husband, and never wavered. Nothing in his log ever dips, so his average certainty is the highest in the department. His flat log is not evidence of skill; it is evidence that he never canvassed anyone else.
Consilience reads the log’s shape. A good detective’s certainty starts low — three suspects on the board, contradictory timelines — and ends high, because independent threads eventually pointed the same way. That is what the word means, in Whewell’s original sense: independent lines of inference jumping together. So the board applies two rules. First, hedging at the end disqualifies you; an investigation that closes with “probably the husband, maybe the brother” is not a solved case. Second, certainty at the start counts against you, because on a hard case, day-one certainty is tunnel vision wearing the costume of competence. The head term is the tunnel-vision penalty; the tail term is the closed-case requirement; lambda is how harshly the board treats a cop who never doubted.
Key Concepts
-
Token confidence: When an LLM writes a token, it first produces a probability over every possible next token. If it puts 0.99 on “4” after “2 + 2 =”, it is confident. If the top three candidates each get roughly 0.3, it is not. Confidence is just that number, tracked token by token, and averaged or otherwise summarized. The thing to internalize is what it actually measures: how predictable the *next word was given everything written so far. It is a fluency measurement, not a truth measurement. A model marching down a wrong but internally coherent chain of reasoning is highly confident at every step, because each wrong step follows smoothly from the last wrong step. This is precisely why average confidence fails as a correctness proxy on hard problems.
-
Temporal asymmetry: Take a rollout’s confidence trace and reverse it. Mean confidence: unchanged. Minimum confidence: unchanged. Perplexity: unchanged. Every mainstream confidence score is blind to time order — which means it throws away the entire distinction between “figured it out” and “fell apart.” Temporal asymmetry is any score that changes when you reverse the sequence. The paper’s specific claim is narrower and testable: the useful asymmetry is rising, and rising specifically from a low start. Concretely, on a hard geometry problem, rollout A opens with “hmm, could be similar triangles, or maybe coordinates” (low confidence) and closes with a clean numeric answer (high confidence); rollout B opens with “The answer is clearly 12 by symmetry” and stays smooth throughout. Old scoring picks B. Consilience picks A.
-
Verifier-free vs. verifier-based: With a verifier, test-time scaling is a search problem with ground truth at the leaves — run the unit tests, keep what passes. Verifier-free means the only oracle you have is the model’s own internal state, which is correlated with correctness but also correlated with familiarity, template-ness, and how confidently it can be wrong. Every VF-TTS paper is fundamentally an argument about which internal statistic is least contaminated by those confounds. This paper’s argument: not the level, the slope.
Framework Shift
Before (mainstream confidence VF-TTS):   After (consilience):

  rollout: [==================]            rollout: [=====|........|=====]
                    |                                HEAD           TAIL
                    v                                  |              |
       collapse to a scalar                            v              v
       mean / min / perplexity                   penalize high    demand high
       (order-invariant)                                 \           /
                    |                                     \         /
                    v                                       v     v
       pick max total confidence                       S = shape match
                    |                                          |
                    v                                          v
       flat-high rollout wins                     explored-then-converged wins
       == the one that never                      == the one whose certainty
          explored                                   was earned

  confidence as a LEVEL                     confidence as a TRAJECTORY
From “how sure is the model” to “how did the model become sure,” the core shift is treating the derivative of confidence as the signal and the level as merely its endpoint.
Expert Assessment
Problem choice: Real gap, well-placed. Confidence-based selection is currently the default cheap knob for verifier-free scaling, and “it degrades on hard problems” is a live, widely-felt failure. The diagnosis — flat high confidence as a marker of absent exploration — is a genuinely nice observation and is worth the paper on its own even if the metric does not survive. It also sits at a productive intersection with the reasoning-model literature, where backtracking behavior (“wait,” “alternatively”) is now understood as load-bearing. Consilience is essentially a logit-level proxy for that behavior. The risk is that the paper is one observation plus one heuristic, which is a thin core for the framing weight it carries.
Method maturity: Clever, but closer to a well-chosen feature than to a framework. Two things nag. First, the obvious cheaper competitor: just count backtracking markers in the trace, or measure confidence variance, or fit a slope. If “number of ‘wait’ tokens” recovers most of the gain, consilience is an elaborate way to detect exploration. The paper needs that ablation, and the abstract does not tell me whether it exists. Second, defining “initial” is genuinely delicate. The opening tokens of any CoT are boilerplate — “Okay, so I need to find the value of…” — which is near-deterministic and therefore near-maximally confident regardless of whether real exploration follows. Any head window that includes the preamble measures template-ness, not doubt. Where exactly the head starts, and how sensitive results are to that choice, is the load-bearing detail. I would also want to know how many hyperparameters (window sizes, lambda, aggregation choices) were tuned, and whether tuning was done on held-out tasks. A shape-matching score with three knobs can be fit to any two benchmarks.
Also, the name is a slight misdirection. Consilience in Whewell’s sense is independent lines of evidence converging — which sounds like cross-rollout agreement, i.e. self-consistency. The actual mechanism is within-rollout temporal shape. Evocative, but it will confuse readers.
Experimental integrity: Two task families (graduate-level math, free-form code generation) with the code setting well chosen, since that is exactly where majority voting is unavailable and the method has room to matter. The claim I would press hardest is “catastrophically break down,” which demands a difficulty sweep — show me the same benchmark stratified easy-to-hard and the crossover point where aggregate confidence goes from helping to actively hurting. Without that, “catastrophic” is rhetoric. The baseline I most want to see is confidence-weighted majority voting, and better still, consilience used *as the weight in voting rather than as a hard argmax; if the authors compared only against plain best-of-N confidence variants, the comparison is soft. Also worth checking: length confounds (longer traces both explore more and have more low-confidence tokens) and whether gains persist at large N or wash out. Note that I am reading the abstract, not the tables, so treat these as the questions I would take into review rather than as findings.
Writing quality: The corner-cutting is visible from the abstract alone: “a combinatorial metric” is doing a lot of work while telling the reader nothing. The single highest-leverage rewrite would be a short, explicit section giving the formula, the window definitions, the hyperparameter values, and a sensitivity plot — that one section converts the paper from “interesting story with a heuristic” to something reproducible. Second-highest: replace the assertion of breakdown with a difficulty-stratified figure. The phenomenology is the strongest asset here and it deserves a figure, not an adjective.
Verdict: weak accept — the diagnostic insight is sharp and cheap to adopt, but the metric looks hand-shaped and the evidence base is thin relative to the strength of the claims.
Takeaways
Things that transfer:
-
Any scalar you compute over a trace is throwing away order. Mean, min, max, and perplexity are all reversal-invariant. If you are ranking agent trajectories, RL rollouts, retrieval chains, or tool-use episodes by an averaged score, you are unable to distinguish “converged” from “fell apart.” Adding head-vs-tail split features is close to free and can be bolted onto whatever scorer you already run.
-
High uniform confidence is a warning light, not a green light. This is directly usable as a monitoring signal in agentic loops: a sub-agent whose confidence never dips on a hard subtask probably never considered an alternative. Route those for re-sampling or escalation. You do not need the paper’s exact metric for this — flat-and-high is a cheap red flag.
-
Compare within-item, not across-item. The whole method only makes sense because all N rollouts share one prompt, which holds difficulty constant. This is a general recipe for making badly-calibrated internal signals usable: find a comparison set where the dominant confound is fixed, then read the residual variation.
-
Asymmetric scoring beats symmetric aggregation when the good and bad regimes have different signatures. Demanding high late confidence while penalizing high early confidence is a template you can reuse anywhere a process should start uncertain and end certain — search, calibration schedules, annealing diagnostics, curriculum monitoring.
-
For RL people: this suggests a trajectory-shape reward or filter. Preferring rollouts whose confidence rises could bias policies toward exploratory-then-decisive reasoning, which is a different target from rewarding final correctness alone. Speculative, and the paper does not do it, but it is the obvious next move.
论文: 2608.09898 作者: Lecheng Kong, Like Hui, Haitao Mao, Jun Huan 分类: cs.CL, cs.LG
缺口
测试时扩展的道理很朴素:采样 N 条 rollout,留下好的那条。全部难点都在”留下好的那条”。
有验证器的时候这几乎不是问题——编译器、单元测试、训好的 value function,直接跑一遍就知道对错。
没有验证器的时候只能找代理信号,这个方向的选项其实不多:多数投票 / self-consistency(需要能抽取、能比较的答案,所以在自由形式的代码生成上直接失效)、LLM-as-judge(每个候选多一次完整前向,而且裁判和生成者共享盲点)、以及基于置信度的打分——按平均 token 对数概率、按困惑度、按 self-certainty、或者按轨迹里最低置信度的那个窗口来排序(DeepConf 那一系)。
置信度这一支之所以受关注,是因为它几乎不花钱。logits 你本来就有,不用额外采样、不用额外模型、不用针对任务写解析逻辑,换模型换任务都能用。
这篇论文的贡献是指出这一支在哪里断掉,而且断的方式很有意思:在难题上,按聚合置信度排序不是退化成随机,而是主动去挑错答案。
原因很直接——对一道难题来说,一条从第一个 token 就一路高置信度的 rollout,说明它从头到尾没考虑过别的可能。平坦的高置信度是”探索失败”的签名,不是”能力强”的签名。
于是聚合置信度打分被系统性地拉向”自信地错”。
论文的解法是:别再把置信度当成一个标量摘要,把它当成一条有诊断意义的曲线——前期该犹豫,后期该确定。
[ 问题 ]
  测试时没有验证器
  只能靠模型内部信号从 N 条 rollout 里挑 1 条
      |
      v
[ 现有方法 ]
  score = 对全部 token 做聚合
  mean logprob / perplexity / self-certainty / 最低窗口置信度
      |
      v
[ 观察到的崩塌 ]
  难任务上胜出的是全程高置信度的 rollout
  而这些恰恰是从未分叉探索过的 rollout
  ==> 自信地错的答案被推上来
      |
      v
[ 假设 ]
  健康的认知搜索有固定的形状
  前期低置信度: 探索性分叉
  后期高置信度: 收敛到一个解
      |
      v
[ 方法: consilience ]
  把轨迹切成前段与后段
  组合式指标: 惩罚前期确定 + 严格要求后期确定
      |
      v
[ 证据 ]
  研究生级数学 + 自由形式代码生成
  优于置信度类与投票类基线
      |
      v
[ 结论 ]
  置信度里有信息量的是时间上的不对称性
  而不是它的平均值
增量
一句话: 以前的无验证器选择在问”这条 rollout 有多自信”,这篇论文改成问”这条 rollout 的自信是挣来的吗”——同样的 logits,从一个数字读成一条时间序列。
核心机制
起点和所有置信度方法一样:对一个 prompt 采 N 条 rollout,每条都有一串逐 token 的置信度 c(t),通常是所选 token 的对数概率,或者某种基于熵的 self-certainty。
现有方法把 c(t) 压成一个数:均值、最小值、或滑动窗口的最小值。
信息就死在这一步压缩上——因为均值和最小值都是与顺序无关的。一条”先犹豫后确定”和一条”先确定后崩掉”的轨迹,会拿到完全相同的分数。
Consilience 保留顺序。把轨迹切成前段(head)和后段(tail),分别聚合置信度,然后不对称地组合:后段项奖励高置信度(模型总得真的落到某个答案上),前段项对高置信度做惩罚(还没干活就已经很确定,可疑)。
摘要把它称为一个”组合式指标”,“主动惩罚初始高置信度,同时严格要求最终确定性”——可以理解成 S = g(tail) - lambda * h(head) 这类单调组合,而”严格要求”这个措辞暗示后段更接近一个硬门槛,而不是软加项。
按 S 排序取 argmax。相比朴素的 best-of-N 置信度,额外开销就是在一个你本来就有的数组上多扫一遍。
关键的结构性细节是:这个比较发生在同一道题内部。N 条 rollout 面对同一个问题,难度被固定住了。
这一点很重要。因为跨题来看,“前期低置信度”基本上只是在测量题有多难——一道简单算术题就该从第一个 token 起自信到底,惩罚它毫无道理。
而在固定题目内部,前期低置信度测量的是另一件事:这 N 次尝试里,哪一次真的先把空间打开、然后才收起来。
prompt
  +--> rollout 1 : c1 c2 c3 ... cT
  +--> rollout 2 : ...
  +--> rollout N : ...

把每条 rollout 读成一条置信度轨迹

  conf
  1.0 |                  ...._____   收敛
      |          ___/~~~~
  0.5 |     ___/
      |  __/    犹豫
  0.0 +--------------------------------> t
        好形状: 先探索后收敛

  conf
  1.0 |~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
  0.5 |
  0.0 +--------------------------------> t
        坏形状: 从未犹豫
        全程高 == 没分叉 == 难题上大概率错

  conf
  1.0 |  ___
      | /   \____                 ....
  0.5 |            \___     ..../
  0.0 +--------------------------------> t
        坏形状: 结尾还在含糊 == 没有收敛

打分:
  HEAD = c(t) 的前段
  TAIL = c(t) 的后段

  A = agg( HEAD )    "还没想就已经确定了吗"
  B = agg( TAIL )    "最后落到东西上了吗"

  S = g( B )  -  lambda * h( A )
      ^^^^^^         ^^^^^^^^^^^
      要求高          惩罚高

按 S 排序  ==>  argmax  ==>  最终答案
核喻:这是一场刑侦复核会,而复核委员会永远无法核实抓的人对不对。
每条 rollout 是一位办同一桩案子的警探。委员会没法验证结论——没有口供,没有 DNA,没有验证器。
它手上只有每位警探自己的记录:逐小时的”我此刻有多确定”。
旧规则是:谁全程平均确定度最高,就用谁的结论。
平常的小案子这么办没问题。但真正的疑难案件里,这条规则精确地选出了最糟的那位警官:进门就认定是丈夫,然后从头到尾没动摇过。
他的记录曲线一次都没掉下来,所以他的平均确定度全局最高。
那条平坦的曲线不是能力的证明,而是”他从没去问过第二个人”的证明。
Consilience 读的是曲线的形状。好警探的确定度是低开高走:一开始白板上挂着三个嫌疑人、时间线互相矛盾;最后升高,因为几条互相独立的线索指向了同一个人。
这正是这个词在 Whewell 原意里的意思——彼此独立的推断”跳到一起”。
于是委员会立两条规矩。第一,结尾还在含糊的,取消资格:一份以”大概是丈夫,也可能是他弟弟”收尾的卷宗不算破案。
第二,开头就确定的要倒扣分:疑难案件里的第一天确定,是穿着能力外衣的隧道视野。
前段项就是隧道视野罚分,后段项就是结案要求,lambda 就是委员会对”从没怀疑过”这件事有多不客气。
关键概念
-
Token 置信度: 模型每写一个 token,先产出一个覆盖全词表的概率分布。看到 “2 + 2 =” 之后给 “4” 打 0.99,就是很自信;如果前三个候选各占 0.3 左右,就是不自信。置信度就是这个数字,逐 token 记下来再做聚合。真正要内化的是它究竟在测什么:给定已写内容,下一个词有多好猜。这是一个流畅度度量,不是真值度量。一个模型沿着一条错但内部自洽的推理链往下走时,每一步都会非常自信——因为每个错步都顺滑地接在上一个错步后面。这正是平均置信度在难题上作为正确性代理会失效的原因。
-
时间不对称性: 把一条 rollout 的置信度序列前后翻转。均值不变,最小值不变,困惑度不变。主流的置信度分数全都对时间顺序视而不见——也就是说,它们把”想明白了”和”崩掉了”这个区分整个丢掉了。时间不对称性指的是任何”翻转序列后会改变”的分数。这篇论文的主张更窄也更可检验:有用的那种不对称是上升,而且必须是从低点起步的上升。具体点说,一道难的几何题上,rollout A 开头是”嗯,可能是相似三角形,也可能上坐标”(低置信度),结尾给出一个干净的数值答案(高置信度);rollout B 开头是”由对称性显然答案是 12”,然后一路平滑。旧打分选 B,consilience 选 A。
-
有验证器 vs 无验证器: 有验证器时,测试时扩展是一个叶节点带真值的搜索问题——跑测试,留下通过的。无验证器意味着你唯一的神谕就是模型自身的内部状态,而这个状态既和正确性相关,也和”熟悉度”、“模板化程度”、以及”它能多自信地错”相关。每一篇 VF-TTS 论文本质上都在论证:哪个内部统计量受这些混杂因素污染最轻。这篇论文的答案是:不是水平,是斜率。
框架转变
之前(主流置信度 VF-TTS):              之后(consilience):

  rollout: [==================]          rollout: [=====|........|=====]
                    |                              HEAD           TAIL
                    v                                |              |
        压成一个标量                                 v              v
        mean / min / perplexity                  惩罚高          要求高
        (与顺序无关)                                  \           /
                    |                                  \         /
                    v                                    v     v
        选总置信度最高的                            S = 形状匹配度
                    |                                       |
                    v                                       v
        平坦高置信度胜出                      先探索后收敛的胜出
        == 那条从没探索过的                   == 自信是挣来的那条

  置信度作为一个水平值                    置信度作为一条轨迹
一句话:从”模型有多确定”到”模型是怎么变确定的”,核心转变是把置信度的导数当作信号,而把水平值降级成它的终点。
专家评审
选题眼光: 真缺口,位置也选得好。
基于置信度挑选目前就是无验证器扩展的默认便宜旋钮,而”它在难题上会退化”是一个活的、被广泛感受到的失效。
诊断本身——把平坦高置信度识别为”缺乏探索”的标记——是个相当漂亮的观察,即使指标最后没活下来,这个观察也值一篇文章。
它还和推理模型那条线交在一个有产出的点上:那边已经把 backtracking 行为(“wait”、“alternatively”)理解成承重的了,consilience 本质上是这种行为在 logit 层面的代理。
风险在于:整篇的内核是”一个观察 + 一个启发式”,相对于它扛的框架分量,偏薄。
方法成熟度: 有巧劲,但更接近”一个挑得好的特征”而不是”一个框架”。有两点让我不安。
第一,明显更便宜的竞争者:直接数轨迹里的回溯标记词、或者算置信度方差、或者拟合一条斜率。
如果”wait 这个 token 出现了几次”就能拿回大部分收益,那 consilience 就是一种很绕的探索检测器。这个 ablation 是必须的,而从摘要看不出它在不在。
第二,“初始”怎么定义,这件事相当微妙。任何 CoT 的开头几十个 token 都是模板话——“好的,我需要求出……”——它近乎确定性生成,因此置信度近乎最高,跟后面有没有真探索完全无关。
任何把这段前言包进去的 head 窗口,测的是模板化程度,不是犹豫。
head 到底从哪开始、结果对这个选择有多敏感,才是真正承重的细节。
我同样想知道一共调了多少超参(窗口大小、lambda、聚合方式),以及调参是不是在留出任务上做的。一个带三个旋钮的形状匹配分数,可以被拟合到任意两个 benchmark 上。
另外,名字略有误导。Whewell 意义上的 consilience 是彼此独立的证据线收敛到同一结论——这听起来像是跨 rollout 的一致性,也就是 self-consistency。而真正的机制是单条 rollout 内部的时间形状。有画面感,但会让读者绕弯。
实验诚意: 两类任务(研究生级数学、自由形式代码生成),代码这个场景选得好——那正是多数投票用不上、方法有发挥空间的地方。
我最想追问的是”catastrophically break down”这个说法,它要求一条难度扫描曲线:同一个 benchmark 按难度分层,指出聚合置信度从”有帮助”翻转到”主动有害”的交叉点在哪。
没有这条曲线,“catastrophic”就只是修辞。
我最想看的基线是置信度加权的多数投票;更进一步,把 consilience 分数当作投票权重而不是硬 argmax。如果作者只跟朴素的 best-of-N 置信度变体比,这个比较就偏软。
还值得查的是长度混杂(长轨迹既探索更多、也天然含更多低置信度 token),以及收益在 N 变大时是否还在、会不会被冲掉。
需要说明:我读的是摘要,不是表格,所以以上应当看作”我会带进评审的问题”,而不是结论。
写作功力: 偷懒的地方从摘要就能看到:“a combinatorial metric”承担了很重的分量,却什么信息都没给读者。
杠杆最高的一处重写:加一节短而明确的内容,给出公式、窗口定义、超参数取值、以及一张敏感性曲线。
单靠这一节,论文就能从”有意思的故事加一个启发式”变成可复现的东西。
第二高杠杆:把”会崩掉”这个断言换成一张按难度分层的图。这篇文章最强的资产是现象学,它值一张图,而不是一个形容词。
判决: 弱接收 —— 诊断性洞见很锐利、采纳成本很低,但指标看起来是手工捏出来的,证据面相对于结论的强度偏薄。
要点总结
可迁移的东西:
-
任何在轨迹上算出的标量都丢掉了顺序信息。 均值、最小值、最大值、困惑度全都对翻转不变。如果你在用某个平均分数给 agent 轨迹、RL rollout、检索链、工具调用 episode 排序,你就无法区分”收敛了”和”崩掉了”。加上前段/后段拆分特征几乎不花钱,而且可以直接挂在你现有的打分器上。
-
均匀的高置信度是警示灯,不是绿灯。 这个可以直接当 agentic 循环里的监控信号:一个子 agent 在难子任务上置信度从头到尾不掉,很可能它从没考虑过别的路径。把这些路由去重采样或升级处理。你不需要论文里那个精确指标——“又平又高”本身就是便宜的红旗。
-
在同一题内部比,不要跨题比。 整个方法之所以成立,是因为 N 条 rollout 共享一个 prompt,难度被钉住了。这是让”标定很差的内部信号”变得可用的通用配方:找一个主要混杂因素被固定住的比较集合,然后只读剩余的变化量。
-
当好坏两种状态的签名不同时,不对称打分优于对称聚合。 “要求后期高置信、惩罚前期高置信”是一个可复用模板:任何”应当以不确定开始、以确定结束”的过程都适用——搜索、标定调度、退火诊断、课程学习监控。
-
给做 RL 的人: 这自然指向一个轨迹形状的 reward 或过滤器。偏好置信度上升的 rollout,可能把策略推向”先探索后决断”的推理风格,这和只奖励最终正确性是不同的目标。这一点是推测,论文没做,但显然是下一步。