Paper: 2605.02829 Authors: Jingze Ge, Yun Liu, Xue Geng, Wanqi Dong, Wang Zhe Mark, Min Wu, Xulei Yang Categories: cs.AI
The Gap
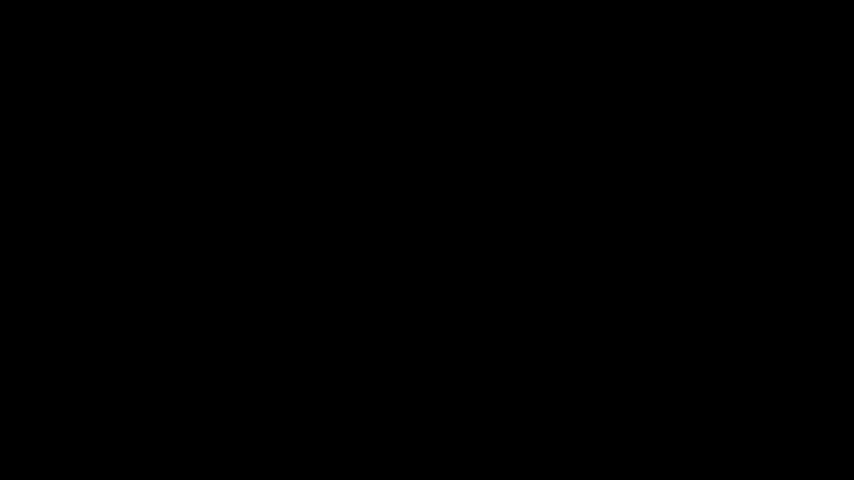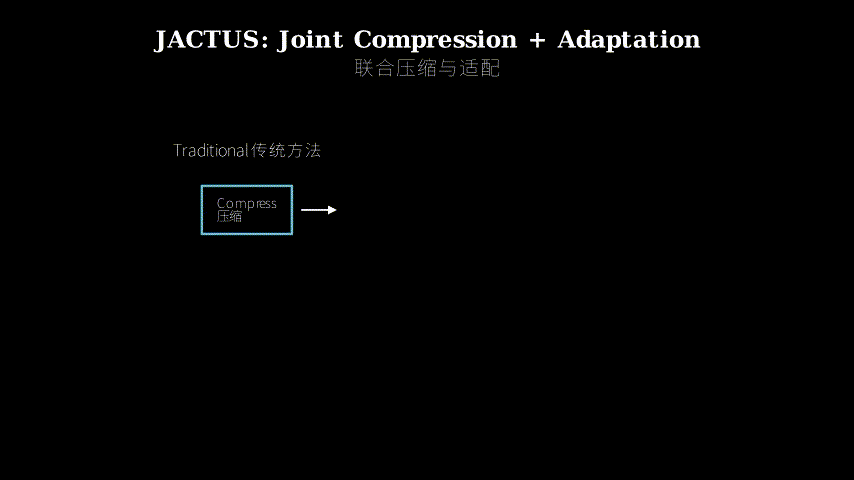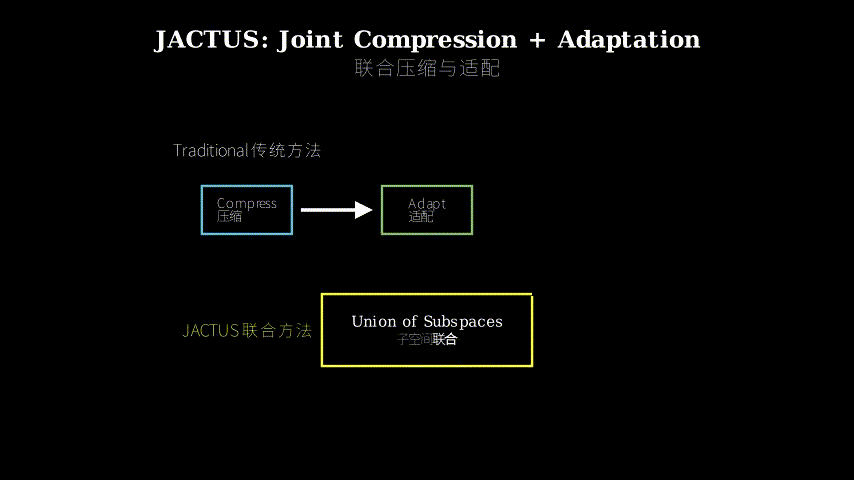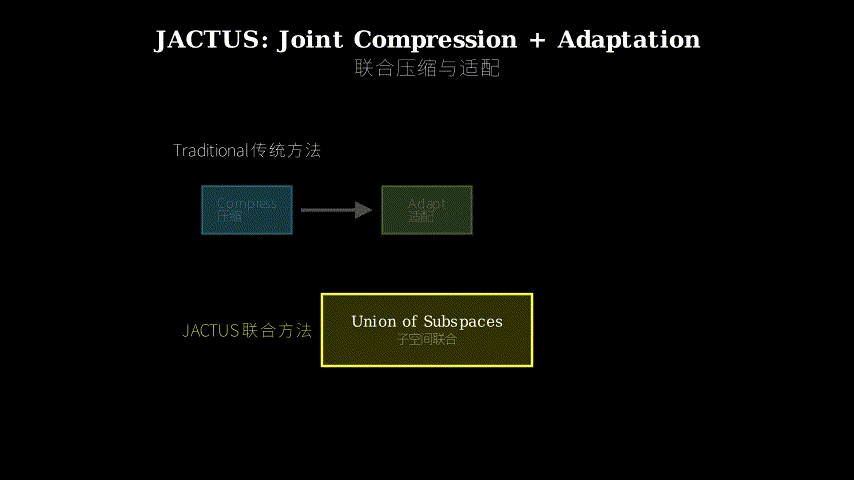
The field has two mature strategies for deploying large pretrained models: parameter-efficient fine-tuning (PEFT) keeps the full model frozen and trains small adapters, while low-rank compression reduces model size by approximating weight matrices. The standard practice chains them sequentially—compress first, then add adapters. This decoupling creates a fundamental misalignment: compression chooses directions that preserve pretrained knowledge, but adaptation needs directions aligned with downstream task gradients. The compressed subspace might discard exactly the dimensions the task needs, forcing adapters to compensate inefficiently. Worse, the parameter budget is split arbitrarily between compression and adaptation rather than allocated globally by utility.
Problem: Sequential pipeline wastes budget
   |
   v
Assumption: Compression & adaptation need overlapping but distinct subspaces
   |
   v
Method: Form union of pretrained + task subspaces, compress inside union
   |
   v
Evidence: 89.2% ViT accuracy at 80% params (vs 87.9% full PEFT baseline)
   |
   v
Conclusion: Joint optimization beats decoupled compress-then-adapt
The Increment
One sentence: Before JACTUS, you compressed blindly then adapted; after JACTUS, you peek at the task to compress only what adaptation won’t need.
Core Mechanism
JACTUS operates in three phases. First, it estimates two covariance matrices from a small calibration set: input covariances (capturing data distribution) and pre-activation gradient covariances (capturing task-relevant directions). Second, it constructs a union subspace by taking the top eigenvectors from these covariances and orthogonalizing them against the pretrained weight’s existing subspace. This union explicitly includes both what the pretrained model already knows and what the task will need. Third, it performs low-rank approximation constrained to live inside this union, allocates rank globally across all layers by marginal accuracy gain per parameter, and trains only a compact core matrix while discarding the full frozen weights.
The key insight is projection before approximation. Standard compression approximates weights in the ambient space, then hopes adapters can fix errors. JACTUS first projects into a task-aware subspace, then approximates there. This guarantees the compressed model retains capacity along task-critical directions. The global rank allocation further optimizes the parameter budget: layers that benefit more from extra rank get it, rather than uniform allocation.
Calibration Set
   |
   +---> Input Covariance ----+
   |                          |
   +---> Gradient Covariance -+
                              |
                              v
                    Union Subspace = Orthogonalize(Pretrained + Task)
                              |
                              v
                    Project Weights into Union
                              |
                              v
                    Low-Rank Approx inside Union
                              |
                              v
                    Global Rank Allocation (by marginal gain)
                              |
                              v
                    Train Core Matrix Only
Think of JACTUS as packing a suitcase for a trip. The standard approach (compress-then-adapt) is like packing your clothes without knowing the destination, then buying new outfits when you arrive and realize you brought the wrong things. JACTUS checks the weather forecast (calibration set) before packing. It identifies what you’ll actually need (task gradients), keeps those items, and only compresses the rest. The suitcase size is fixed (parameter budget), but now every item inside is chosen knowing both what you own (pretrained weights) and what you’ll use (task requirements). The global rank allocation is like giving more space to versatile items (layers with high marginal gain) rather than splitting space equally among all clothes.
Key Concepts
-
Subspace union: Imagine you have two flashlights pointing in different directions in a dark room. One illuminates the pretrained model’s knowledge (what it learned during pretraining), the other illuminates the task’s requirements (gradients from the downstream objective). Most compression methods only use the first flashlight, so they might throw away objects the second flashlight reveals as important. JACTUS turns on both flashlights simultaneously and keeps everything either light touches. Mathematically, it takes the top eigenvectors from input and gradient covariances, orthogonalizes them against the pretrained weight subspace, and forms their span. This union is the “safe zone” where compression can happen without discarding task-critical directions.
-
Projected low-rank approximation: Standard low-rank approximation (like SVD) finds the best rank-k approximation in the full ambient space. JACTUS restricts the search to the union subspace. It’s like being told “you can only rearrange furniture within this room” instead of “you can put furniture anywhere in the house.” This constraint is actually helpful because the room was chosen to contain everything important. The projection ensures the approximation error is orthogonal to task-relevant directions, so the compressed model doesn’t lose capacity where it matters.
-
Global rank allocation: Instead of giving every layer the same rank budget (e.g., rank 8 everywhere), JACTUS measures how much accuracy each layer gains per additional parameter and allocates rank accordingly. A layer that improves 2% with 1000 extra parameters gets more rank than a layer that improves 0.5% with the same budget. This is computed greedily: start with minimal rank everywhere, then iteratively give one more rank to whichever layer has the highest marginal gain, until the parameter budget is exhausted. The result is a heterogeneous rank profile tailored to the model and task.
Framework Shift
Before (compress-then-adapt):        After (JACTUS):

Pretrained Weights                   Pretrained Weights
       |                                    |
       v                                    v
  Compress (SVD)                      Calibration Set
       |                                    |
       v                                    v
  Low-Rank Model              Estimate Task Subspace
       |                                    |
   (frozen)                                 v
       |                          Union(Pretrained + Task)
       v                                    |
  Add Adapters                              v
       |                          Compress inside Union
       v                                    |
  Fine-Tune Adapters                        v
                                   Train Core (no frozen weights)
From sequential decoupling to joint optimization, the core shift is treating compression and adaptation as a single budget allocation problem rather than two independent stages.
Expert Assessment
Problem choice: This is a real gap. The compress-then-finetune pipeline is widely used in production (model serving costs matter), but the misalignment between compression objectives and task objectives is well-known and under-addressed. The problem sits at the intersection of efficiency and adaptation, both hot areas, so the timing is good.
Method maturity: The core idea—using task information to guide compression—is elegant and well-motivated. The execution is solid: covariance estimation is standard, orthogonal union is clean, global rank allocation is principled. However, the method requires a calibration set, which adds a dependency. The paper doesn’t deeply explore what happens when calibration data is scarce or mismatched. Also, the comparison against “compress-then-finetune” baselines is somewhat unfair because those baselines use 100% of parameters during finetuning (frozen weights + adapters), while JACTUS discards frozen weights. A fairer comparison would be compress-then-finetune with the same 80% total parameter budget.
Experimental integrity: The baselines are strong (DoRA, LoRA, full finetuning) and the datasets are standard (vision: CIFAR, SVHN, etc.; language: commonsense QA). The numbers are convincing: 89.2% vs 87.9% on ViT, 80.9% vs 79.7% on Llama2. However, the paper reports averages across datasets without showing per-dataset breakdowns or variance, which makes it hard to assess robustness. The ablation studies are present but shallow—no analysis of sensitivity to calibration set size or quality. The claim that JACTUS “avoids retaining full frozen weights” is a deployment advantage, but the paper doesn’t measure actual inference speedup or memory savings in practice.
Writing quality: The abstract and introduction are clear, but the method section is dense and notation-heavy. The paper would benefit from a standalone “algorithm box” summarizing the full procedure in pseudocode. The related work section conflates compression and PEFT literature without clearly delineating what JACTUS inherits from each. The experimental section front-loads tables without enough narrative to guide interpretation. Rewriting Section 4 to lead with insights (“global rank allocation matters most”) before dumping numbers would elevate the whole paper.
Verdict: weak accept — The idea is sound and results are strong, but experimental rigor and presentation need tightening before this becomes a landmark paper.
Takeaways
Practitioners can steal the global rank allocation strategy even outside this specific framework. If you’re deploying low-rank adapters (LoRA, etc.), don’t use uniform rank across layers—profile each layer’s sensitivity and allocate rank by marginal gain. This is cheap to compute (one forward pass per rank increment) and often yields 1-2% accuracy for free.
The broader lesson: when composing two optimization stages (compression + adaptation, quantization + finetuning, pruning + distillation), check if they’re fighting over the same parameter budget. If so, consider joint optimization or at least peek at the second stage’s objective when making first-stage decisions. The “union of subspaces” framing is a clean way to formalize this for linear operations.
论文: 2605.02829 作者: Jingze Ge, Yun Liu, Xue Geng, Wanqi Dong, Wang Zhe Mark, Min Wu, Xulei Yang 分类: cs.AI
缺口
该领域已有两种成熟的大模型部署策略:参数高效微调(PEFT)冻结完整模型并训练小型适配器,低秩压缩通过近似权重矩阵来减小模型尺寸。
标准做法是将它们串联——先压缩,再加适配器。
这种解耦造成了根本性的错位:压缩选择保留预训练知识的方向,但适配需要与下游任务梯度对齐的方向。
压缩后的子空间可能恰好丢弃了任务所需的维度,迫使适配器低效地补偿。
更糟的是,参数预算在压缩和适配之间被任意分割,而非按效用全局分配。
问题:串行流程浪费预算
   |
   v
假设:压缩与适配需要重叠但不同的子空间
   |
   v
方法:构造预训练+任务子空间的并集,在并集内压缩
   |
   v
证据:ViT在80%参数下达到89.2%准确率(vs 完整PEFT基线87.9%)
   |
   v
结论:联合优化胜过解耦的先压缩后适配
增量
一句话: JACTUS之前,你盲目压缩再适配;JACTUS之后,你先看任务需求,只压缩适配用不到的部分。
核心机制
JACTUS分三个阶段运作。
首先,它从小型校准集估计两个协方差矩阵:输入协方差(捕获数据分布)和预激活梯度协方差(捕获任务相关方向)。
其次,它通过提取这些协方差的顶部特征向量,并将它们与预训练权重的现有子空间正交化,构造一个并集子空间。
这个并集显式包含了预训练模型已知的内容和任务将需要的内容。
第三,它执行约束在该并集内的低秩近似,按每参数的边际准确率增益在所有层间全局分配秩,并仅训练一个紧凑的核心矩阵,同时丢弃完整的冻结权重。
关键洞察是先投影再近似。
标准压缩在环境空间中近似权重,然后希望适配器能修复误差。
JACTUS先投影到任务感知子空间,再在那里近似。
这保证了压缩模型沿任务关键方向保留容量。
全局秩分配进一步优化参数预算:从额外秩中获益更多的层得到更多秩,而非均匀分配。
校准集
   |
   +---> 输入协方差 ----+
   |                    |
   +---> 梯度协方差 ----+
                        |
                        v
              并集子空间 = 正交化(预训练 + 任务)
                        |
                        v
              将权重投影到并集
                        |
                        v
              在并集内低秩近似
                        |
                        v
              全局秩分配(按边际增益)
                        |
                        v
              仅训练核心矩阵
把JACTUS想象成为旅行打包行李箱。
标准方法(先压缩后适配)就像不知道目的地就打包衣服,到达后发现带错东西再买新衣服。
JACTUS在打包前先查天气预报(校准集)。
它识别你实际需要什么(任务梯度),保留那些物品,只压缩其余部分。
行李箱大小固定(参数预算),但现在里面的每件物品都是在知道你拥有什么(预训练权重)和你会用什么(任务需求)的情况下选择的。
全局秩分配就像给多功能物品(边际增益高的层)更多空间,而非在所有衣服间平均分配空间。
关键概念
- 子空间并集: 想象你在黑暗房间里有两个手电筒指向不同方向。
一个照亮预训练模型的知识(预训练期间学到的内容),另一个照亮任务的需求(来自下游目标的梯度)。
大多数压缩方法只用第一个手电筒,所以它们可能扔掉第二个手电筒揭示为重要的物体。
JACTUS同时打开两个手电筒,保留任一光线触及的所有东西。
数学上,它提取输入和梯度协方差的顶部特征向量,将它们与预训练权重子空间正交化,并形成它们的张成空间。
这个并集是”安全区”,压缩可以在其中进行而不丢弃任务关键方向。
- 投影低秩近似: 标准低秩近似(如SVD)在完整环境空间中找到最佳秩k近似。
JACTUS将搜索限制在并集子空间内。
这就像被告知”你只能在这个房间内重新布置家具”而非”你可以把家具放在房子的任何地方”。
这个约束实际上是有帮助的,因为房间被选择为包含所有重要的东西。
投影确保近似误差与任务相关方向正交,因此压缩模型不会在重要的地方失去容量。
- 全局秩分配: 不是给每层相同的秩预算(例如,到处都是秩8),JACTUS测量每层每增加一个参数获得多少准确率,并相应分配秩。
一个用1000个额外参数提升2%的层比用相同预算提升0.5%的层获得更多秩。
这是贪婪计算的:从所有地方的最小秩开始,然后迭代地给边际增益最高的层再多一个秩,直到参数预算耗尽。
结果是针对模型和任务定制的异构秩配置。
框架转变
之前(先压缩后适配):            之后(JACTUS):

预训练权重                        预训练权重
    |                                 |
    v                                 v
压缩(SVD)                       校准集
    |                                 |
    v                                 v
低秩模型                          估计任务子空间
    |                                 |
(冻结)                              v
    |                         并集(预训练 + 任务)
    v                                 |
添加适配器                            v
    |                         在并集内压缩
    v                                 |
微调适配器                            v
                              训练核心(无冻结权重)
从串行解耦到联合优化,核心转变是将压缩和适配视为单一预算分配问题,而非两个独立阶段。
专家评审
选题眼光: 这是真实的缺口。
先压缩后微调的流程在生产中广泛使用(模型服务成本很重要),但压缩目标与任务目标之间的错位是众所周知且未充分解决的。
问题位于效率和适配的交叉点,两者都是热门领域,所以时机很好。
方法成熟度: 核心思想——使用任务信息指导压缩——优雅且动机充分。
执行扎实:协方差估计是标准的,正交并集是干净的,全局秩分配是有原则的。
然而,该方法需要校准集,这增加了依赖性。
论文没有深入探讨当校准数据稀缺或不匹配时会发生什么。
此外,与”先压缩后微调”基线的比较有些不公平,因为那些基线在微调期间使用100%的参数(冻结权重+适配器),而JACTUS丢弃冻结权重。
更公平的比较是在相同80%总参数预算下的先压缩后微调。
实验诚意: 基线很强(DoRA、LoRA、完整微调),数据集是标准的(视觉:CIFAR、SVHN等;语言:常识问答)。
数字令人信服:ViT上89.2% vs 87.9%,Llama2上80.9% vs 79.7%。
然而,论文报告跨数据集的平均值,没有显示每个数据集的细分或方差,这使得难以评估鲁棒性。
消融研究存在但浅显——没有对校准集大小或质量敏感性的分析。
JACTUS”避免保留完整冻结权重”的声明是部署优势,但论文没有测量实际推理加速或内存节省。
写作功力: 摘要和引言清晰,但方法部分密集且符号繁重。
论文将受益于一个独立的”算法框”,用伪代码总结完整过程。
相关工作部分混淆了压缩和PEFT文献,没有清楚地描述JACTUS从每个继承了什么。
实验部分在没有足够叙述指导解释的情况下前置表格。
重写第4节,先引出洞见(“全局秩分配最重要”)再倾倒数字,将提升整篇论文。
判决: 弱接收 — 想法合理,结果强劲,但实验严谨性和呈现需要收紧,才能成为里程碑论文。
要点总结
实践者可以窃取全局秩分配策略,即使在这个特定框架之外。
如果你正在部署低秩适配器(LoRA等),不要在层间使用均匀秩——分析每层的敏感性,按边际增益分配秩。
这计算成本低(每秩增量一次前向传播),通常能免费获得1-2%的准确率。
更广泛的教训:当组合两个优化阶段(压缩+适配、量化+微调、剪枝+蒸馏)时,检查它们是否在争夺相同的参数预算。
如果是,考虑联合优化,或至少在做第一阶段决策时窥视第二阶段的目标。
“子空间并集”框架是为线性操作形式化这一点的干净方式。