Paper: 2602.24264 Authors: Arnas Uselis, Andrea Dittadi, Seong Joon Oh Categories: cs.CV, cs.LG
The Gap
Vision models like CLIP and DINO have shown remarkable empirical success, and researchers have observed that their learned representations exhibit surprisingly linear structure — concepts seem to align with directions in embedding space. But this observation has been purely descriptive. We know that linearity appears, but not why it must appear. The Linear Representation Hypothesis remains an empirical pattern without theoretical necessity.
More critically, we lack a principled understanding of what representational structure is required for compositional generalization — the ability to recognize “red car” after seeing “red ball” and “blue car” separately. Models are trained on massive datasets, yet these cover only a vanishingly small fraction of all possible concept combinations. What geometric constraints must representations satisfy to generalize beyond the training distribution?
The Increment
Before: Linear structure in neural representations was an observed regularity without theoretical justification. After: Linear, orthogonal decomposition is a mathematical necessity for compositional generalization.
The authors formalize three desiderata that any representation must satisfy to support compositional generalization: divisibility (you can isolate individual concept contributions), transferability (concept representations work across different contexts), and stability (small input changes don’t catastrophically alter the representation). From these intuitive requirements, they derive strict geometric constraints through mathematical proof.
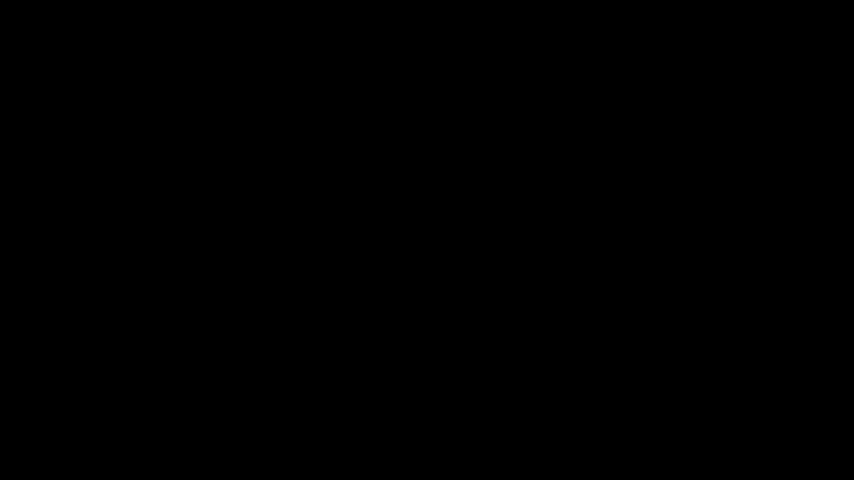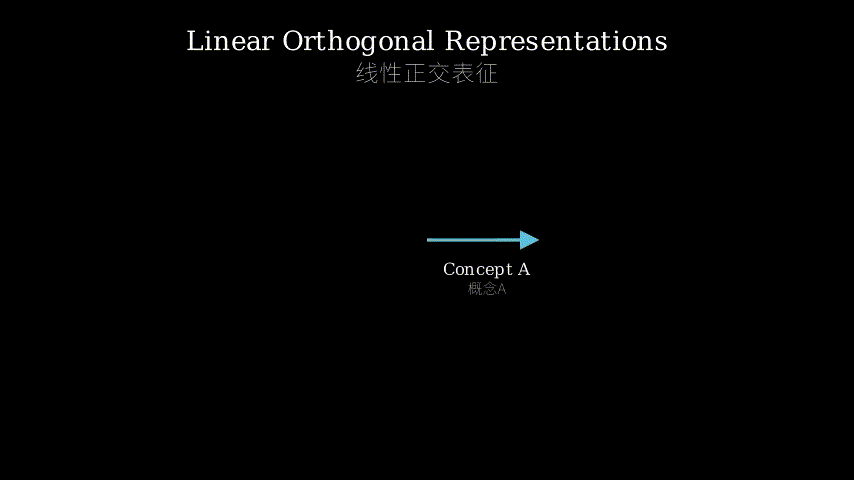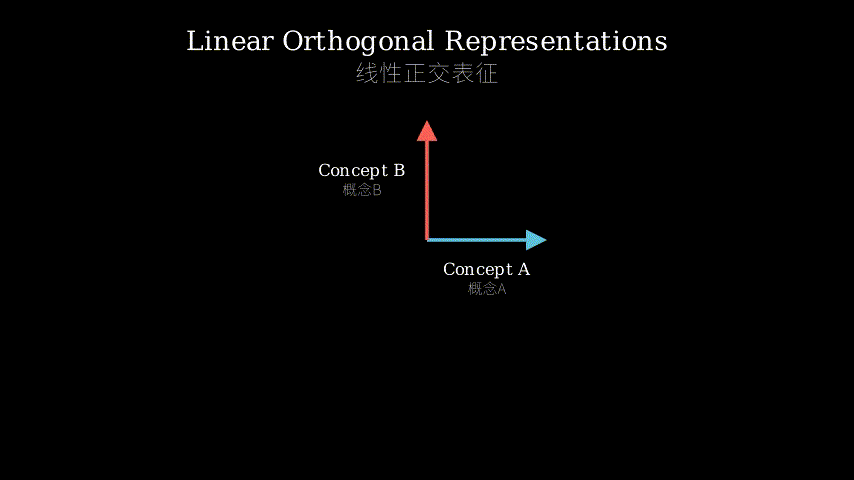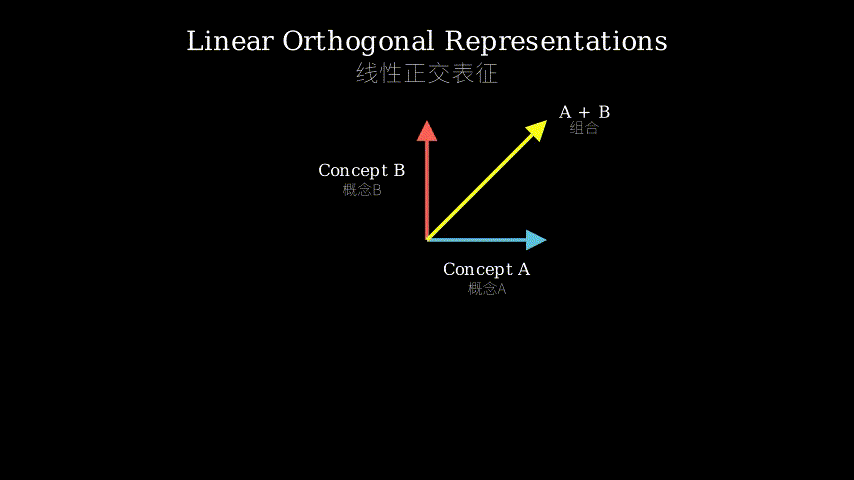
Think of it like a modular synthesizer. Each concept (color, shape, texture) is a separate oscillator module. For the system to work compositionally, each module must output a signal (representation component) that can be cleanly mixed with others. This requires two things: the signals must combine linearly (simple addition, not complex interference), and they must be orthogonal (each module occupies its own frequency band, so they don’t bleed into each other). If “redness” and “car-ness” interfere destructively, you can’t compose them reliably. The paper proves this isn’t just good engineering — it’s mathematically necessary given the desiderata.
The theoretical framework also yields dimension bounds: if you want to compose concepts, your embedding space needs at least dimensions, and the per-concept factors must be low-rank and near-orthogonal. The authors then validate these predictions empirically across CLIP, SigLIP, and DINO, finding that models exhibiting stronger linear factorization indeed generalize better to unseen combinations.
Key Concepts
Compositional Generalization
Start simple: you’ve seen dogs and you’ve seen snow. Now you see a dog in snow for the first time. Can you recognize both? That’s compositional generalization — recombining known parts in novel configurations.
For neural networks, this is hard because training data is sparse in the combinatorial space. If you have 100 colors and 100 objects, that’s 10,000 combinations. Even massive datasets might show you only 1,000 of them. The model must infer the other 9,000 from structure, not memorization.
Concretely: CLIP might see “red apple” and “green car” during training. At test time, it encounters “green apple.” Does the representation for “green apple” correctly combine the “green-ness” learned from cars with the “apple-ness” learned from red apples? This requires that “green” and “apple” are represented as separable, reusable components.
Linear Decomposition
Imagine you’re encoding the sentence “the red car is fast” as a single vector. Linear decomposition means you can write:
Each concept contributes an additive component. This is opposed to entangled representations where concepts interact nonlinearly — like (element-wise product) or some deep nonlinear function.
Why does this matter? If representations are linear, you can algebraically manipulate them. Want to remove “red” and add “blue”? Just subtract and add . This is exactly what’s needed for compositional generalization: swap out one concept for another without retraining.
The paper proves this isn’t optional. If you want divisibility (isolate individual concepts) and transferability (reuse concepts across contexts), linear decomposition is mathematically forced upon you.
Orthogonality
Two vectors are orthogonal if their dot product is zero: . Geometrically, they point in perpendicular directions.
Why does this matter for compositionality? Suppose “red” and “car” are not orthogonal — they share some overlap in representation space. When you try to compose them, the overlapping parts interfere. Extracting “car-ness” from “red car” becomes ambiguous because part of the “car” signal is contaminated by “red.”
Orthogonality ensures clean separation: each concept occupies its own subspace. When you project the embedding onto the “red” subspace, you get only the color information. Project onto “car,” you get only the object information. No crosstalk.
The paper shows this is necessary for stability: if concepts aren’t orthogonal, small perturbations in one concept can cascade into large changes in another, breaking compositional generalization.
Expert Assessment
Problem significance: This is a foundational question. Compositional generalization is arguably *the central challenge in AI — it’s what separates systems that memorize from systems that understand structure. The affected community is broad: anyone working on vision-language models, few-shot learning, systematic generalization, or interpretability. The theoretical grounding provided here could reshape how we design and evaluate models.
Method maturity: This is primarily a theoretical contribution with empirical validation, not a new training method. The proofs are elegant, but they rest on three desiderata (divisibility, transferability, stability) that are somewhat idealized. Real-world compositional generalization might require additional properties not captured here. The empirical analysis is observational — the authors measure existing models but don’t train new ones to maximize the derived constraints. A stronger validation would involve training models explicitly to satisfy these geometric conditions and demonstrating improved compositional generalization.
Experimental rigor: The experiments are solid but limited in scope. The authors test on CLIP, SigLIP, and DINO — all contrastive or self-supervised vision models. What about supervised models? Generative models? The compositional generalization benchmarks used (e.g., unseen attribute-object combinations) are reasonable but somewhat narrow. The paper would benefit from testing on more diverse compositional tasks (e.g., visual reasoning, relational understanding). The correlation between linear factorization and generalization is shown, but causality is not established — do models generalize *because they’re linear, or are both effects of some other factor?
One notable limitation: the paper assumes standard training (e.g., contrastive learning). The constraints might not hold for models trained with explicit compositional objectives or structured priors. The authors acknowledge this but don’t explore it deeply.
Verdict: weak accept — The theoretical contribution is valuable and the empirical validation is competent, but the work feels incomplete without demonstrating that enforcing these constraints during training actually improves compositional generalization.
Takeaways
Geometric constraints as design principles: The idea that functional requirements (like compositional generalization) impose geometric constraints on representations is broadly applicable. If you’re designing embeddings for any compositional domain (molecules, code, music), ask: what structure must the representation have to support the operations you care about? Then derive the geometry from first principles.
Dimension bounds for compositionality: The paper derives that composing concepts requires at least dimensions. This is a practical design constraint: if you’re building a model to handle compositional factors, your embedding dimension should scale accordingly. Underparameterized embeddings will bottleneck compositional capacity.
Orthogonality as a regularizer: If you want compositional generalization, you could add an orthogonality penalty during training: encourage per-concept factors to be orthogonal. This is actionable — you could implement it as a loss term that penalizes for distinct concepts .
Probing for compositionality: The paper’s analysis method — decomposing embeddings into per-concept factors and measuring their orthogonality — is a useful diagnostic tool. If you’re evaluating a model’s compositional capacity, don’t just test accuracy on held-out combinations. Probe the geometry: are concepts linearly separable? Are they orthogonal? This gives you a mechanistic understanding of *why the model succeeds or fails.
Limits of scaling: The paper suggests that as models scale, they may converge to representations satisfying these constraints. But this is only true if the training objective incentivizes compositional generalization. If your data distribution doesn’t require compositionality (e.g., all combinations are seen during training), scaling won’t magically produce linear, orthogonal structure. The geometry follows from the task, not the scale.
论文: 2602.24264 作者: Arnas Uselis, Andrea Dittadi, Seong Joon Oh 分类: cs.CV, cs.LG
缺口
CLIP、DINO等视觉模型在实践中表现出色,研究者观察到它们学到的表征呈现出令人惊讶的线性结构——概念似乎对应嵌入空间中的方向。但这一观察纯属描述性的。我们知道线性结构出现了,却不知道它为何必然出现。线性表征假说仍只是经验规律,缺乏理论必然性。
更关键的是,我们缺乏对组合泛化所需表征结构的原理性理解——即在分别见过”红球”和”蓝车”后识别”红车”的能力。模型在海量数据上训练,但这些数据覆盖的概念组合空间微乎其微。表征必须满足什么几何约束才能泛化到训练分布之外?
增量
之前: 神经表征中的线性结构是观察到的规律,没有理论依据。之后: 线性正交分解是组合泛化的数学必然。
作者形式化了表征支持组合泛化必须满足的三个条件:可分性(能分离单个概念的贡献)、可迁移性(概念表征在不同语境中有效)、稳定性(输入微小变化不会灾难性改变表征)。从这些直观要求出发,他们通过数学证明推导出严格的几何约束。
可以把它想象成模块化合成器。每个概念(颜色、形状、纹理)是独立的振荡器模块。要让系统组合工作,每个模块必须输出能与其他模块干净混合的信号(表征分量)。这需要两点:信号必须线性组合(简单相加,而非复杂干涉),且必须正交(每个模块占据自己的频段,互不渗透)。如果”红色性”和”汽车性”破坏性干涉,就无法可靠组合。论文证明这不只是好的工程实践——在给定条件下,这是数学必然。
理论框架还给出维度界限:要组合个概念,嵌入空间至少需要维,且每个概念的因子必须低秩且近似正交。作者随后在CLIP、SigLIP和DINO上实证验证这些预测,发现线性因子化更强的模型确实在未见组合上泛化更好。
关键概念
组合泛化
从简单的开始:你见过狗,也见过雪。现在第一次看到雪中的狗。你能同时识别两者吗?这就是组合泛化——在新配置中重组已知部分。
对神经网络来说这很难,因为训练数据在组合空间中稀疏。如果有100种颜色和100种物体,就有10000种组合。即使海量数据集也许只展示其中1000种。模型必须从结构而非记忆中推断其余9000种。
具体而言:CLIP训练时可能见过”红苹果”和”绿车”。测试时遇到”绿苹果”。“绿苹果”的表征能否正确组合从车上学到的”绿色性”和从红苹果学到的”苹果性”?这要求”绿色”和”苹果”被表征为可分离、可复用的组件。
线性分解
想象你把句子”那辆红色的车很快”编码为单个向量。线性分解意味着可以写成:
每个概念贡献一个加性分量。这与纠缠表征相对——后者中概念非线性交互,如(逐元素乘积)或某个深度非线性函数。
为何重要?如果表征是线性的,就能代数操作它们。想移除”红色”加上”蓝色”?只需减去加上。这正是组合泛化所需:替换一个概念而无需重新训练。
论文证明这不是可选项。如果想要可分性(分离单个概念)和可迁移性(跨语境复用概念),线性分解在数学上是强制的。
正交性
两个向量正交意味着点积为零:。几何上,它们指向垂直方向。
为何对组合性重要?假设”红色”和”车”不正交——它们在表征空间中有重叠。尝试组合时,重叠部分会干涉。从”红车”中提取”车性”变得模糊,因为部分”车”信号被”红色”污染。
正交性确保干净分离:每个概念占据自己的子空间。将嵌入投影到”红色”子空间,只得到颜色信息。投影到”车”,只得到物体信息。无串扰。
论文表明这对稳定性是必需的:如果概念不正交,一个概念的小扰动会级联成另一个概念的大变化,破坏组合泛化。
专家评审
问题重要性: 这是基础性问题。组合泛化可以说是AI的**核心*挑战——它区分记忆系统和理解结构的系统。受影响群体广泛:任何从事视觉-语言模型、少样本学习、系统泛化或可解释性的人。这里提供的理论基础可能重塑我们设计和评估模型的方式。
方法成熟度: 这主要是带实证验证的理论贡献,而非新训练方法。证明优雅,但依赖三个有些理想化的条件(可分性、可迁移性、稳定性)。现实世界的组合泛化可能需要这里未捕获的额外性质。实证分析是观察性的——作者测量现有模型但未训练新模型来最大化推导出的约束。更强的验证应该包括显式训练模型满足这些几何条件并展示改进的组合泛化。
实验严谨性: 实验扎实但范围有限。作者在CLIP、SigLIP和DINO上测试——都是对比或自监督视觉模型。监督模型呢?生成模型呢?使用的组合泛化基准(如未见属性-物体组合)合理但有些狭窄。论文若能在更多样的组合任务(如视觉推理、关系理解)上测试会更好。线性因子化与泛化的相关性已展示,但因果关系未建立——模型是**因为*线性才泛化,还是两者都是其他因素的结果?
一个值得注意的局限:论文假设标准训练(如对比学习)。对于用显式组合目标或结构先验训练的模型,约束可能不成立。作者承认这点但未深入探索。
判决: 弱接收——理论贡献有价值,实证验证称职,但若不展示训练时强制这些约束确实改进组合泛化,工作感觉不完整。
要点总结
几何约束作为设计原则: 功能需求(如组合泛化)施加表征几何约束这一思想广泛适用。如果你为任何组合领域(分子、代码、音乐)设计嵌入,问:表征必须有什么结构才能支持你关心的操作?然后从第一性原理推导几何。
组合性的维度界限: 论文推导出组合个概念至少需要维。这是实用设计约束:如果构建模型处理个组合因子,嵌入维度应相应扩展。参数不足的嵌入会成为组合能力的瓶颈。
正交性作为正则化器: 如果想要组合泛化,可以在训练时添加正交性惩罚:鼓励每个概念的因子正交。这是可操作的——可以实现为惩罚不同概念的的损失项。
探测组合性: 论文的分析方法——将嵌入分解为每个概念的因子并测量其正交性——是有用的诊断工具。如果评估模型的组合能力,不要只测试保留组合上的准确率。探测几何:概念线性可分吗?正交吗?这给出模型成功或失败**原因*的机制性理解。
扩展的局限: 论文暗示随着模型扩展,它们可能收敛到满足这些约束的表征。但这仅在训练目标激励组合泛化时成立。如果数据分布不需要组合性(如训练时见过所有组合),扩展不会魔法般产生线性正交结构。几何源于任务,而非规模。