Paper: 2606.06477 Authors: Noam Issachar, Dani Lischinski, Raanan Fattal Categories: cs.CV
The Gap
Diffusion models deploy the same massive network uniformly across the entire generative timeline—from pure noise to refined structure. But early timesteps (noise→rough shapes) are fundamentally easier than late timesteps (details, coherence). Using a 1-billion-parameter model to denoise random Gaussian noise is like hiring a neurosurgeon to change a bandage. Prior temporal splitting approaches either use heuristic partitions (equal time intervals) or expensive neural architecture search, ignoring the actual difficulty profile of the sampling trajectory.
Problem: Uniform capacity across variable complexity
   |
   v
Assumption: Approximation burden varies along timeline
   |
   v
Method: Partition timeline by equal complexity (not equal time)
   |
   v
Evidence: 35% FID improvement, no per-step cost increase
   |
   v
Conclusion: Matching capacity to local difficulty beats uniform allocation
The Increment
One sentence: Before—deploy full model everywhere; after—deploy model capacity proportional to local generative difficulty.
Core Mechanism
CBS operates in two phases. First, a lightweight auxiliary network estimates where along the diffusion timeline the generative dynamics are hardest to model. It computes two complexity measures: spatial complexity (Dirichlet energy of the flow field—how rapidly the denoising direction changes in space) and geometric complexity (acceleration of sampling trajectories—how much the path curves). These measures are cheap to compute and correlate strongly with approximation error.
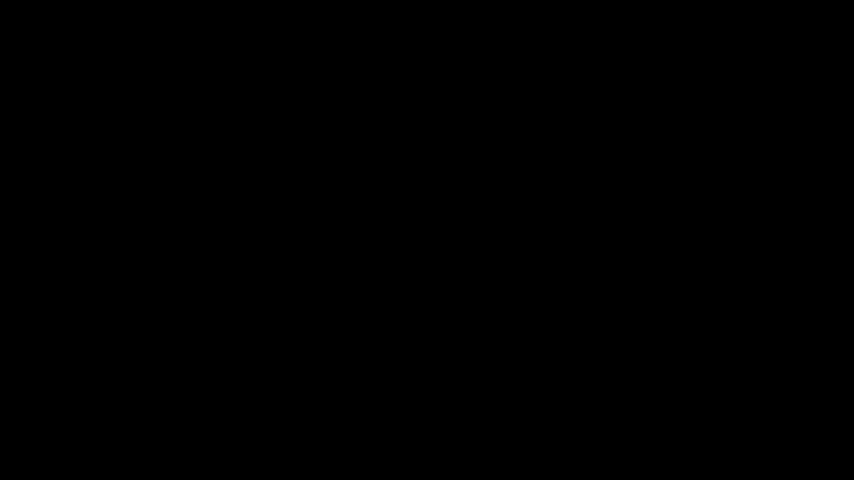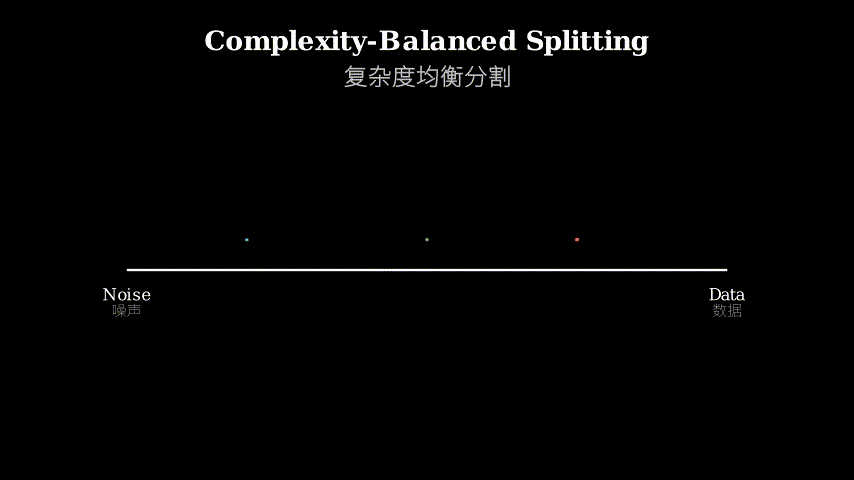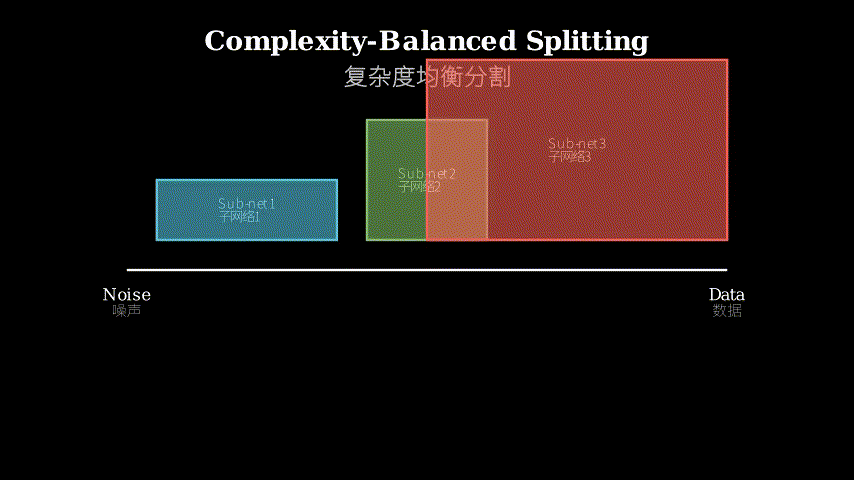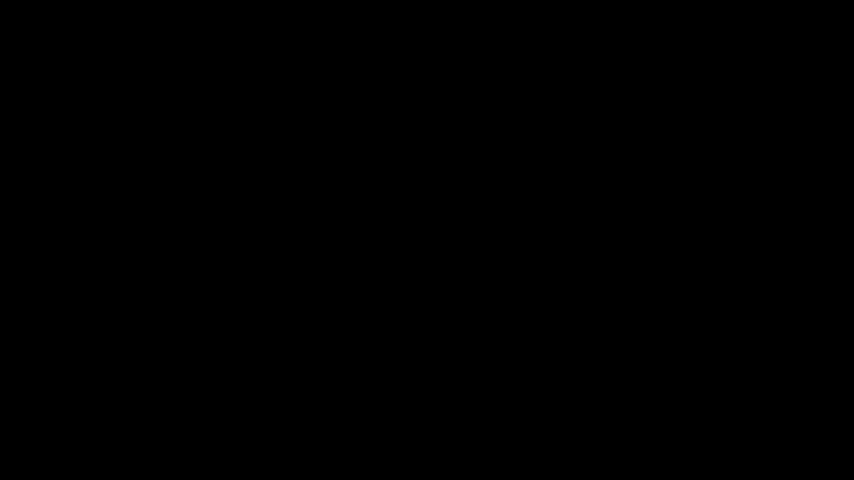
Second, CBS uses these complexity profiles to partition the timeline. Instead of dividing time into equal intervals, it applies de Boor’s equidistribution principle from numerical analysis: cut the timeline so each segment contains equal total complexity. High-complexity regions get finer temporal resolution and thus more sub-network capacity. Each sub-network is then trained only on its assigned segment.
Input trajectory (noise -> data)
   |
   v
[Auxiliary Model]----> Complexity profiles:
   |                   - Spatial (Dirichlet energy)
   |                   - Geometric (trajectory acceleration)
   v
[Equidistribution Principle]
   |
   v
Timeline segments:  [=====]  [==]  [=]  <- equal complexity, not time
   |
   v
[Sub-network 1] [Sub-network 2] [Sub-network 3]
   ^               ^               ^
   |               |               |
   Early (easy)    Mid (hard)      Late (hardest)
Think of it like staffing a hospital emergency room. You don’t assign the same number of doctors to every hour of the day—you staff based on patient load. The auxiliary model is your historical admission data; it tells you when the ER gets slammed. Equidistribution is the scheduling algorithm: divide shifts so each team handles roughly the same number of cases, even if shift lengths differ. CBS does the same for diffusion: it “staffs” the timeline based on when the generative process needs more help, not on wall-clock time.
Key Concepts
-
Dirichlet Energy: Measures how much a function wiggles. For a denoising flow, it’s the spatial variance of the velocity field—how differently neighboring pixels want to move. High Dirichlet energy means the model must output a complex, spatially varying correction, which is hard to approximate with limited capacity. Concrete example: early timesteps have low Dirichlet energy (noise → blob, simple smooth flow), late timesteps have high energy (adding fine hair strands, each pixel needs a different correction).
-
Equidistribution Principle: From numerical approximation theory. When approximating a function, place more evaluation points where the function is harder to approximate. For diffusion, the “function” is the denoising trajectory, “evaluation points” are the temporal boundaries between sub-networks, and “approximation difficulty” comes from the complexity monitors. Result: narrow segments for hard regions (more frequent network handoffs = more capacity), wide segments for easy regions.
Framework Shift
Before (monolithic):                After (CBS):

      [Single Network]              [Net-1] [Net-2] [Net-3]
           |  |  |                     |       |       |
   --------+--+--+--------     -------+-------+-+-----+-
   t=0           t=1000        t=0    t=300  t=700  t=1000
   (noise)       (data)
                               Segment size ~ 1/complexity
   Uniform allocation           Adaptive allocation
From blind uniformity to demand-responsive allocation, the core shift is matching capacity to local difficulty instead of time.
Expert Assessment
Problem choice: Real gap. Every practitioner knows diffusion models “waste” capacity on easy timesteps, but prior work either ignored it (monolithic models) or addressed it with brute-force NAS. Grounding the split in approximation theory is a meaningful upgrade from heuristics.
Method maturity: Elegant use of existing theory (de Boor’s principle, Dirichlet energy). The auxiliary model is a smart trick—lightweight profiling before heavy training. However, the paper doesn’t explore whether simpler heuristics (e.g., just using trajectory acceleration) would get 90% of the benefit. The spatial vs geometric monitors seem redundant in experiments; one might suffice.
Experimental integrity: Strong baselines (SiT, JiT, UNet), consistent gains across architectures. The 35% FID improvement is on SiT-XL with classifier-free guidance—a high-leverage setting. Ablations are thorough (different numbers of segments, monitor choices). One concern: the auxiliary model’s training cost isn’t amortized in the reported numbers. For one-off training this doesn’t matter, but for rapid iteration it might.
Writing quality: Clear motivation and clean exposition. The theory section (de Boor, function approximation) feels slightly over-engineered for what’s ultimately “put more capacity where errors are high.” The related work undersells the connection to curriculum learning and adaptive computation. Figure 3’s complexity profiles are the paper’s best asset—should be in the abstract.
Verdict: strong accept — Principled, broadly applicable, and demonstrates clear wins without architectural gimmicks or compute inflation.
Takeaways
Steal the core idea for any staged or progressive training pipeline: profile where your model struggles, then allocate capacity accordingly. The Dirichlet energy trick generalizes—use it to detect “hard” spatial regions in any flow-based model (normalizing flows, neural ODEs). The equidistribution principle applies beyond diffusion: if you’re training an autoregressive model, put more layers/capacity near positions where prediction entropy is highest. Also, the auxiliary model pattern: train a cheap profiler first, use it to guide expensive training. This is underused in deep learning.
论文: 2606.06477 作者: Noam Issachar, Dani Lischinski, Raanan Fattal 分类: cs.CV
缺口
扩散模型在整个生成时间线上统一部署同一个巨型网络——从纯噪声到精细结构。
但早期时间步(噪声→粗略形状)本质上比后期时间步(细节、连贯性)简单得多。
用10亿参数的模型去给随机高斯噪声降噪,就像请神经外科医生换绷带。
现有的时间分割方法要么使用启发式分割(等时间间隔),要么依赖昂贵的神经架构搜索,都忽略了采样轨迹的实际难度分布。
问题:统一容量应对变化复杂度
   |
   v
假设:近似负担沿时间线变化
   |
   v
方法:按等复杂度(非等时间)分割时间线
   |
   v
证据:35% FID改进,无单步成本增加
   |
   v
结论:匹配容量与局部难度优于统一分配
增量
一句话: 之前——在所有位置部署完整模型;之后——按局部生成难度比例部署模型容量。
核心机制
CBS分两阶段运行。
第一阶段,轻量级辅助网络估计扩散时间线上哪些位置的生成动力学最难建模。
它计算两种复杂度度量:空间复杂度(流场的狄利克雷能量——降噪方向在空间中的变化速率)和几何复杂度(采样轨迹的加速度——路径弯曲程度)。
这些度量计算成本低,且与近似误差强相关。
第二阶段,CBS用这些复杂度分布来分割时间线。
它不是把时间分成等间隔,而是应用数值分析中的de Boor等分布原理:切分时间线让每段包含相等的总复杂度。
高复杂度区域获得更精细的时间分辨率,因此获得更多子网络容量。
每个子网络只在其分配的片段上训练。
输入轨迹 (噪声 -> 数据)
   |
   v
[辅助模型]----> 复杂度分布:
   |            - 空间(狄利克雷能量)
   |            - 几何(轨迹加速度)
   v
[等分布原理]
   |
   v
时间线片段:  [=====]  [==]  [=]  <- 等复杂度,非等时间
   |
   v
[子网络1] [子网络2] [子网络3]
   ^         ^         ^
   |         |         |
   早期(易) 中期(难)  晚期(最难)
可以类比急诊室排班。
你不会给每个小时分配相同数量的医生——而是基于患者流量排班。
辅助模型是你的历史就诊数据;它告诉你急诊室什么时候最忙。
等分布是排班算法:分班次让每个团队处理大致相同数量的病例,即使班次长度不同。
CBS对扩散做同样的事:它根据生成过程何时需要更多帮助来”排班”时间线,而非基于时钟时间。
关键概念
- 狄利克雷能量: 衡量函数的”摆动”程度。
对于降噪流,它是速度场的空间方差——相邻像素想要移动的方向有多不同。
高狄利克雷能量意味着模型必须输出复杂的、空间变化的修正,这在有限容量下很难近似。
具体例子:早期时间步有低狄利克雷能量(噪声→团块,简单平滑流),晚期时间步有高能量(添加细发丝,每个像素需要不同修正)。
- 等分布原理: 来自数值近似理论。
近似函数时,在函数难以近似的地方放置更多求值点。
对扩散而言,“函数”是降噪轨迹,“求值点”是子网络间的时间边界,“近似难度”来自复杂度监测器。
结果:难区域的窄片段(更频繁的网络交接=更多容量),易区域的宽片段。
框架转变
之前(单体):                      之后(CBS):

      [单一网络]                [网络1] [网络2] [网络3]
           |  |  |                 |       |       |
   --------+--+--+--------     ---+-------+-+-----+-
   t=0           t=1000        t=0  t=300 t=700  t=1000
   (噪声)        (数据)
                               片段大小 ~ 1/复杂度
   统一分配                    自适应分配
从盲目统一到需求响应分配,核心转变是匹配容量与局部难度而非时间。
专家评审
选题眼光: 真缺口。
每个实践者都知道扩散模型在简单时间步上”浪费”容量,但之前工作要么忽略它(单体模型),要么用暴力NAS解决。
将分割奠基于近似理论是对启发式的有意义升级。
方法成熟度: 优雅地使用现有理论(de Boor原理、狄利克雷能量)。
辅助模型是聪明技巧——重训练前的轻量级剖析。
但论文未探索更简单的启发式(如只用轨迹加速度)能否获得90%的收益。
空间与几何监测器在实验中似乎冗余;一个可能就够。
实验诚意: 强基线(SiT、JiT、UNet),跨架构一致增益。
35% FID改进是在带分类器自由引导的SiT-XL上——高杠杆设置。
消融充分(不同片段数、监测器选择)。
一个顾虑:辅助模型的训练成本未摊销进报告数字。
对一次性训练无妨,但对快速迭代可能有影响。
写作功力: 动机清晰,阐述干净。
理论部分(de Boor、函数近似)对于本质上”在错误高的地方放更多容量”的想法略显过度工程。
相关工作低估了与课程学习、自适应计算的联系。
图3的复杂度分布是论文最佳资产——应该放进摘要。
判决: 强接收 — 有原则、广泛适用,展示了明确增益而无架构噱头或计算膨胀。
要点总结
为任何分阶段或渐进训练流水线窃取核心思想:剖析模型在哪里挣扎,然后相应分配容量。
狄利克雷能量技巧可泛化——用它检测任何基于流的模型(归一化流、神经ODE)中的”困难”空间区域。
等分布原理超越扩散:如果训练自回归模型,在预测熵最高的位置放更多层/容量。
还有辅助模型模式:先训练廉价剖析器,用它指导昂贵训练。
这在深度学习中使用不足。