Paper: 2608.07458 Authors: Gyuwan Kim, Cheoneum Park, Tao Yang Categories: cs.CL, cs.AI, cs.IR, cs.LG
The Gap
RAG serving has a well-known bottleneck: the retrieved context is long, and prefill cost grows with it. Prefix caching doesn’t help, because every query pulls a different set of documents — there is no shared prefix to cache.
The last two years produced a clean workaround, which I’ll call the chunk-cache family: TurboRAG, CacheBlend, Block-Attention, EPIC and friends. The trick is to encode each corpus chunk once, offline, in isolation, store its KV tensors, and at query time just concatenate the stored KVs instead of running a forward pass over thousands of tokens. Because the chunks never attended to each other during offline encoding, the spliced cache is an approximation of the true one, so each method adds a repair step: recompute the tokens whose KV deviates most (CacheBlend), re-apply positions and fine-tune the model to tolerate block-independent encoding (Block-Attention), etc.
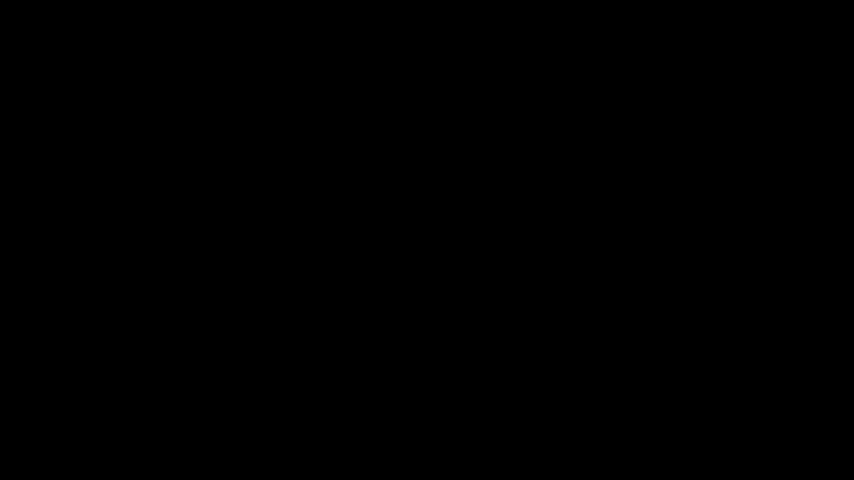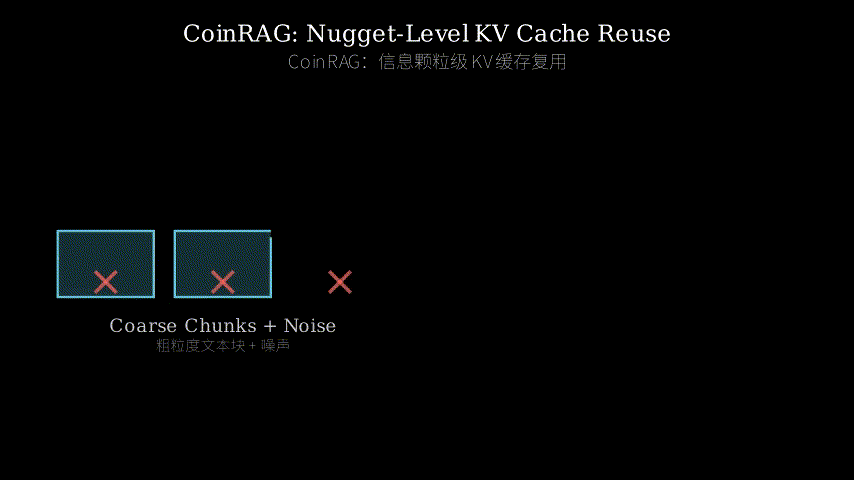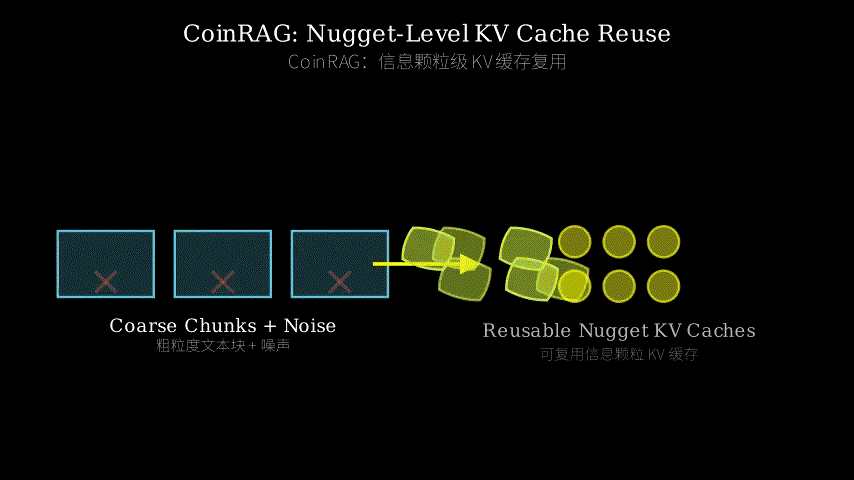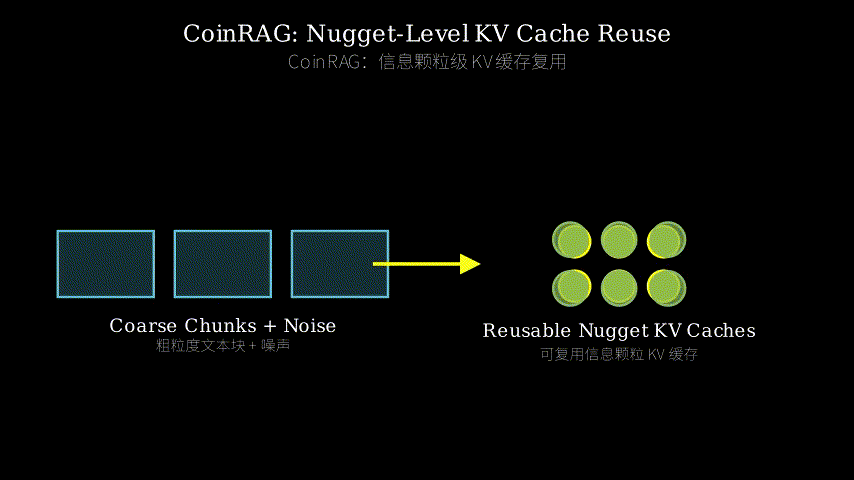
That family solves cost per token of context. It does nothing about how many tokens of context you need. You still pay for the entire chunk — boilerplate, tangents, the two paragraphs that happened to sit next to the useful sentence. In multi-hop QA the actual evidence is often a handful of sentences scattered across several documents; everything else is redundancy and distractor noise, which hurts twice: it costs latency, and it degrades answers.
CoinRAG’s bet is that granularity is the unexploited axis. Not “cache better,” but “cache the same thing and consume less of it.”
[Problem] retrieved context is long => prefill latency dominates RAG serving
     |
     v
[Prior fix] chunk-level KV reuse: TurboRAG / CacheBlend / Block-Attention
     |       precompute per-chunk KV offline, splice + repair at query time
     |
     +--> unresolved: you still consume WHOLE chunks
     |    redundancy and distractors ride along for free (but not for cheap)
     |
     v
[Assumption] (a) the evidence is a few small spans inside those chunks
             (b) a span's KV *sliced out of its own chunk cache* already
                 carries the chunk's local context, unlike a span encoded alone
     |
     v
[Method] CoinRAG = two-stage retrieval (chunk -> nugget)
                 + KV slicing from offline chunk caches
                 + chunk-level context anchor
                 + learned adaptation to the assembled cache
     |
     v
[Evidence] LongBench multi-hop QA: dominates baselines on the
           latency-vs-F1 curve; +5.3% relative F1 at a fixed
           "fast prefill" budget
     |
     v
[Conclusion] under a latency budget, selecting finer units beats
             encoding coarse ones more cleverly
The Increment
One sentence: Before, the reusable unit of KV cache was the retrieval chunk; after, it’s a sub-chunk “nugget” that can be cut out of a chunk’s precomputed cache and recombined with others, so the model reads a short, dense context instead of a long, noisy one at the same or lower prefill cost.
Core Mechanism
Offline, CoinRAG does what TurboRAG does: run each chunk through the model and store its KV. The addition is that it also segments each chunk into information nuggets — small semantic units, roughly sentence- or proposition-sized — records their token spans, and indexes them for retrieval. Crucially the KV is not recomputed per nugget. A nugget’s cache is a row-slice of its parent chunk’s cache. That’s where “contextualized” comes from: the sentence was encoded while it could attend to its neighbors, so the slice inherits that local context for free. Encoding the nugget standalone would strip exactly the coreference and topical grounding that makes a fragment interpretable.
Online, retrieval happens twice. Stage one is ordinary chunk retrieval. Stage two runs inside the surviving chunks and scores nuggets against the query, keeping only the relevant ones. Then the assembly step gathers the corresponding KV slices — memory reads, no forward pass — and concatenates them into a synthetic context, together with a chunk-level context representation that acts as an anchor so a bag of fragments still reads as coherent evidence rather than a shuffled quote list. Positions are re-indexed (RoPE re-applied at the new offsets), and a small learned/recompute pass heals the seams, which is necessary because the model never saw this particular ordering of spans during pretraining. The abstract’s phrase “learned contextual representation” implies training is involved, in the same spirit as Block-Attention’s fine-tuning; from the abstract alone I can’t tell whether it’s a fine-tune of the base model, a light adapter, or a learned selection policy.
The payoff compounds. A shorter assembled sequence means less repair compute during prefill, fewer KV rows to attend over during decode, and less distractor content for the model to be misled by. That’s why the claim is a Pareto shift rather than a pure speedup: quality goes up while latency goes down.
OFFLINE  (once per corpus)
  chunk C --> [ LLM forward ] --> KV(C) stored on disk / GPU-adjacent tier
                                  span table: n1 n2 n3 ... nk
                                  nugget embeddings --> stage-2 index

ONLINE   (per query q)

  q --> stage 1: chunk retriever --> C1  C2  C3
  q --> stage 2: nugget retriever, scoped inside C1..C3
                        |
                        v
             selected spans:  C1[n2]  C2[n1]  C2[n5]  C3[n3]
                        |
                        v
             KV SLICING (no forward pass, just reads)
             KV(C1)[rows of n2] , KV(C2)[rows of n1], ...
                        |
                        v
             ASSEMBLE
             [ sys ][ chunk-level anchor ][ n2 ][ n1 ][ n5 ][ n3 ][ q ]
               + position re-index (RoPE at new offsets)
               + small learned / recompute pass to heal seams
                        |
                        v
             DECODE over a SHORT, dense sequence
             (vs. baseline: decode over 4x longer spliced chunks)
Think of it as a film editing room. Shooting is expensive, so you shoot each scene once — that’s the offline chunk prefill, and the exposed footage is the stored KV. When a query arrives you are not re-shooting anything; you are cutting. Stage-one retrieval picks which scene reels to pull from the shelf; stage-two retrieval picks which shots inside those reels actually belong in this cut. The key editorial discipline is that you cut the shot out of the developed reel rather than re-staging the actor on a bare set: the clip keeps the lighting and the set dressing of the original scene, which is exactly what a KV slice keeps and what an independently-encoded fragment loses. The chunk-level anchor is the establishing shot you leave in so the audience knows where they are. Position re-indexing is renumbering the timecodes after the splice. And the learned repair pass is the continuity-and-color-grading pass that keeps the cuts from feeling jarring. The output is a ninety-second trailer that answers the question, not the four-hour dailies.
Key Concepts
-
KV cache reuse, and why it’s an approximation: When a transformer reads text, each token computes a key and a value vector at every layer, and later tokens attend to them. Prefill is precisely the cost of computing those vectors for the whole context. If a document is going to appear in many queries, you could compute its keys/values once and store them. The catch: attention is contextual. A key computed while the model was looking at only document A is *not the key it would have computed if documents B and C had been in front of it too. So splicing independently-computed caches gives you a context the model never actually would have produced — usually close enough, sometimes not, which is why every method in this family bolts on a repair step.
-
Information nugget: A term borrowed from IR evaluation, where a “nugget” is a minimal atomic fact that an answer must contain — TREC-style nuggetized scoring works this way. Concretely, for “which university employed the physicist who proposed the wave equation?”, the nuggets are “Schrödinger proposed the wave equation” and “Schrödinger held a chair at the University of Zurich” — two sentences, possibly from two documents, buried in maybe 4,000 tokens of retrieved biography. Nuggets are the unit of *evidence; chunks are the unit of storage. CoinRAG’s move is to stop conflating them.
-
Contextualized slicing vs. isolated encoding: Take the sentence “He was appointed there in 1921.” Encoded on its own, it is nearly useless — “he” and “there” resolve to nothing. Encoded as part of its chunk and then sliced out, its key/value vectors were already computed with the antecedents visible, so the resolved meaning is baked into the numbers even though the antecedent tokens are no longer in the sequence. This is the paper’s central lever, and also its main fragility: the resolution lives only in the vectors, and how well it survives re-positioning and truncation of the surrounding rows is an empirical question.
Framework Shift
Before (chunk-cache family)              After (CoinRAG)

  q                                        q
  |                                        |
  v                                        v
retrieve top-k chunks                    retrieve top-k chunks
  |                                        |
  v                                        v
+----------+----------+----------+       score nuggets inside them
|  KV(C1)  |  KV(C2)  |  KV(C3)  |         |
+----------+----------+----------+         v
  ^ reuse whole blocks              +--+  +-+  +---+  +-+
  |                                 |n2|  |n1| |n5 |  |n3|   slices
  |  ~4000 tokens                   +--+  +-+  +---+  +-+
  |  of which ~10% is evidence        |  ~600 tokens, mostly evidence
  v                                    v
repair seams --> decode            anchor + slices --> repair --> decode

cost: f(size of chunks)            cost: f(size of evidence)
noise: fully inherited             noise: filtered at stage 2
One sentence: from making long context cheap to encode to making the encoded context short, the core shift is decoupling the unit of caching from the unit of consumption.
Expert Assessment
Problem choice: Real gap, and well-positioned. The chunk-cache line of work and the context-compression line of work (LLMLingua, RECOMP, Provence, sentence-level rerankers) have been running in parallel with almost no contact, because compression normally forces you to re-encode the compressed text — which throws away your cache. Noticing that you can compress *in cache space, by slicing rather than re-encoding, is the kind of connection that should have been made a year ago. It sits squarely on the field’s trajectory toward treating the KV cache as a first-class, addressable data structure rather than a byproduct of a forward pass.
Method maturity: Clever, not brute force — the “slice, don’t re-encode” insight is the whole paper and it’s a good one. Two things temper my enthusiasm. First, the system is now three coupled components (chunk retriever, nugget retriever, learned repair), and papers with three knobs usually hide an ablation showing one knob does most of the work; I’d want to know whether an oracle-free stage-two retriever is really the source of the gain or whether shorter contexts alone explain it. Second, a genuinely simpler baseline exists and is easy to overlook: retrieve nuggets, then just *prefill the concatenated nugget text normally. If the context is now only ~600 tokens, plain prefill is already fast, and the entire cache-slicing apparatus may be buying less than it appears. The paper’s advantage over that baseline has to come from either latency at scale or from contextualization that raw re-encoded fragments lack — and that comparison is the one I’d read first.
Experimental integrity: I’m working from the abstract, so this is provisional. Two flags. (1) The headline is “+5.3% relative F1 under a fast prefill latency budget.” Relative F1 on LongBench multi-hop tasks means roughly 1.5–2.5 absolute points, and those datasets are noisy enough that the result needs multiple seeds and per-dataset breakdowns to be convincing. Reporting relative gains under a *chosen budget also invites cherry-picking the budget; the Pareto plot mitigates this if the curves are dense, but only if the crossing points are shown honestly. (2) The accounting boundary matters enormously. Stage-two nugget retrieval is real online work. If it’s excluded from “prefill latency” while the baselines’ entire cost sits inside prefill, the comparison flatters CoinRAG. Also worth checking: whether the learned repair component means CoinRAG got a fine-tune that CacheBlend didn’t, and what the nugget index costs in memory relative to the chunk index. Evaluating only multi-hop QA is a narrow slice — fragment-based context should be much riskier for summarization or any task needing discourse-level coherence, and silence on that is conspicuous.
Writing quality: The abstract spends a sentence and a half on the coin metaphor, which is a bad trade in a venue where reviewers are counting contributions. “Seamlessly assembles” is doing a lot of unexamined work — the seams are the hard part and the honest version of that sentence names the mechanism. The section I’d most want rewritten is the cost model: a clean, explicit budget (offline compute, storage, index size, stage-two retrieval latency, repair FLOPs, decode length) would convert this from “nice numbers” to “deployable,” and it’s exactly what an infrastructure-minded reader will look for and, I suspect, not find.
Verdict: weak accept — a genuinely good idea (compress inside cache space instead of text space) with a plausible efficiency story, held back by a narrow evaluation and an accounting boundary that needs to be shown, not asserted.
Takeaways
-
The transferable primitive: slice, don’t re-encode. Any pipeline that caches representations of text can adopt this. If you already have a precomputed representation of a whole document, extracting a sub-span from that representation preserves context that re-encoding the sub-span destroys. This applies to late-interaction retrievers, document rerankers, and any embedding cache with span-level addressability — not just KV caches.
-
Decouple the storage unit from the consumption unit. Chunk size in RAG is usually one number serving three different jobs: retrieval granularity, caching granularity, and context granularity. They have different optima. Splitting them is a cheap architectural win independent of anything else in this paper.
-
Hierarchical retrieval as a latency instrument. Two-stage retrieval is usually framed as a quality trick (recall then precision). Here it’s a *cost trick: stage two exists to shrink what the LLM reads. If you’re latency-bound, a cheap in-chunk filter may buy more than a better first-stage retriever.
-
The “anchor” pattern. Keeping one coarse-grained context representation alongside fine-grained fragments is a reusable hedge against over-aggressive pruning. Worth borrowing whenever you compress context and worry about losing the thread.
-
What I would not take on faith: that fragment assembly is safe outside short-answer multi-hop QA. Before shipping this for anything generative, test on tasks where the model must respect discourse order.
论文: 2608.07458 作者: Gyuwan Kim, Cheoneum Park, Tao Yang 分类: cs.CL, cs.AI, cs.IR, cs.LG
缺口
RAG 上线服务有个众所周知的瓶颈:检索回来的上下文很长,prefill 开销随长度线性增长。
前缀缓存在这里帮不上忙——每个查询召回的文档都不一样,根本没有可复用的公共前缀。
过去两年出现了一条干净的绕行路线,姑且叫”块缓存流派”:TurboRAG、CacheBlend、Block-Attention、EPIC 等等。
套路是:离线把每个 chunk 单独编码一次,把 KV 张量存下来;查询时直接拼接这些 KV,而不是对几千个 token 重跑一遍前向。
由于离线编码时各 chunk 互相看不见,拼出来的缓存只是真实缓存的近似,所以每种方法都要加一道修补:重算 KV 偏差最大的那部分 token(CacheBlend),或者重新施加位置编码并微调模型让它适应块独立编码(Block-Attention)。
这一流派解决的是”每个上下文 token 的单价”,完全没有触碰”你到底需要多少个上下文 token”。
你依然要为整个 chunk 付钱——模板文字、跑题段落、恰好挨着有用句子的那两段废话。
多跳问答里真正的证据往往就是散落在几篇文档中的几句话,其余全是冗余和干扰项。而干扰项伤害是双份的:既花延迟,又拉低答案质量。
CoinRAG 押的是”粒度”这条尚未开发的轴:不是”缓存得更聪明”,而是”缓存同样的东西,但只消费其中一小部分”。
[问题] 召回上下文太长 => prefill 延迟主导 RAG 服务成本
     |
     v
[已有方案] 块级 KV 复用:TurboRAG / CacheBlend / Block-Attention
     |        离线预算每块 KV,在线拼接 + 修补
     |
     +--> 未解决:你消费的仍然是"整块"
     |     冗余与干扰项免费搭车,但延迟并不免费
     |
     v
[假设] (a) 证据只是块内的少数小片段
       (b) 从"自己所属块的缓存"里切出的片段,天然携带块内上下文
           而单独编码的同一片段会把这层上下文丢掉
     |
     v
[方法] CoinRAG = 两阶段检索(块 -> 颗粒)
                + 从离线块缓存中切片 KV
                + 块级上下文锚点
                + 针对拼装缓存的学习式适配
     |
     v
[证据] LongBench 多跳问答:延迟-F1 曲线上支配基线;
       固定"快速 prefill"预算下 F1 相对提升 5.3%
     |
     v
[结论] 在延迟预算下,"选更细的单元"胜过"把粗单元编码得更巧"
增量
一句话:在这篇论文之前,KV 缓存可复用的最小单位是检索 chunk;之后,最小单位变成了块内的”信息颗粒”(nugget)——它可以从块的预计算缓存里切出来、与别的颗粒重新拼装,于是模型在同等甚至更低的 prefill 成本下,读到的是一段短而密的上下文,而不是长而嘈杂的上下文。
核心机制
离线阶段,CoinRAG 做的事和 TurboRAG 一样:把每个 chunk 过一遍模型,存下 KV。
新增的是:它同时把每个 chunk 切成信息颗粒——大致句子或命题级的语义单元——记录它们的 token 区间,并为检索建索引。
关键在于KV 不按颗粒重算:一个颗粒的缓存就是其父块缓存的行切片。
这就是”contextualized(语境化)“的来源:这句话被编码时是能看到邻居的,所以切片免费继承了块内语境。
若把颗粒单独编码,恰恰会剥掉让碎片可解释的那层指代消解与话题接地。
在线阶段,检索发生两次。第一阶段是普通的块检索;第二阶段在存活下来的块内部,用查询给颗粒打分,只留下相关的。
然后是拼装:把对应的 KV 切片取出来(纯内存读,无前向传播),连同一个块级上下文表示一起拼成一段合成上下文。
那个块级表示起锚点作用,让一堆碎片读起来仍像连贯证据,而不是被打乱顺序的引文清单。
位置需要重新编号(在新偏移量上重新施加 RoPE),再由一个小规模的学习/重算步骤去”缝合接缝”——这一步是必须的,因为模型在预训练时从未见过这种片段排列方式。
摘要里”learned contextual representation”这个措辞暗示涉及训练,思路与 Block-Attention 的微调同源;但只看摘要,我无法判断它是基座微调、轻量适配器,还是一个可学习的选择策略。
收益是复利式的:拼装后的序列更短,意味着 prefill 阶段修补计算更少、decode 阶段需要注意的 KV 行更少、模型被干扰内容带偏的机会也更少。
这就是为什么作者声称的是帕累托前沿的整体移动,而不只是加速:质量往上、延迟往下。
离线(每个语料库一次)
  chunk C --> [ LLM 前向 ] --> KV(C) 落盘 / 近显存层
                               区间表:n1 n2 n3 ... nk
                               颗粒向量 --> 二阶段索引

在线(每个查询)

  q --> 一阶段:块检索器 --> C1  C2  C3
  q --> 二阶段:颗粒检索器,范围限定在 C1..C3 内部
                        |
                        v
             选中区间: C1[n2]  C2[n1]  C2[n5]  C3[n3]
                        |
                        v
             KV 切片(无前向,只是读内存)
             KV(C1)[n2 的行] , KV(C2)[n1 的行], ...
                        |
                        v
             拼装
             [ sys ][ 块级锚点 ][ n2 ][ n1 ][ n5 ][ n3 ][ q ]
               + 位置重编号(新偏移上重施 RoPE)
               + 小规模 学习/重算 步骤缝合接缝
                        |
                        v
             在"短而密"的序列上 decode
             (对比基线:在长 4 倍的拼接块上 decode)
核喻:电影剪辑室。
拍摄很贵,所以每场戏只拍一次——这就是离线的块级 prefill,冲洗出来的胶片就是存下的 KV。
查询到来时你不重拍任何东西,你只是在剪。一阶段检索决定从架子上取哪几盘场记胶片;二阶段检索决定这盘胶片里哪几个镜头真的该进这一版剪辑。
最关键的剪辑纪律是:你从已冲洗的胶片上剪镜头,而不是把演员重新拉到空布景前补拍。
剪下来的片段保留了原场景的灯光和布景——这正是 KV 切片保留的东西,也是”独立编码的碎片”丢掉的东西。
块级锚点就是你故意留下的那个定场镜头,让观众知道自己身处何地。位置重编号就是拼接后重新排时间码。
那个学习式修补步骤,就是保证剪辑点不突兀的转场与调色环节。
最终交付的是一支九十秒的、能回答问题的预告片,而不是四小时的原始素材。
关键概念
-
KV 缓存复用,以及它为何只是近似:Transformer 读文本时,每个 token 在每一层都会算出一个 key 和一个 value 向量,后面的 token 靠注意力去读它们。prefill 的开销,本质就是为整段上下文算这些向量。如果一篇文档会在很多查询里反复出现,那就算一次存起来。问题在于注意力本身是语境相关的:只看着文档 A 时算出的 key,和 A、B、C 同时在场时算出的 key 不是同一个东西。于是拼接独立算出的缓存,得到的是一个”模型其实永远不会产生”的上下文——多数时候够用,有时候不够,这就是这一流派家家都要加修补步骤的原因。
-
信息颗粒(information nugget):这个词借自信息检索的评测传统,指答案必须包含的最小原子事实,TREC 风格的 nugget 计分就是这么做的。举个具体例子:问”提出波动方程的物理学家在哪所大学任职?“,颗粒就是”薛定谔提出了波动方程”和”薛定谔在苏黎世大学任教席”——两句话,可能来自两篇文档,埋在四千 token 的传记里。颗粒是证据的单位,chunk 是存储的单位。CoinRAG 的动作就是不再把这两者混为一谈。
-
语境化切片 vs 独立编码:看这句话:“他于 1921 年在那里被任命。“单独编码几乎毫无用处——“他”和”那里”指向虚空。但如果它作为 chunk 的一部分被编码、再切出来,它的 key/value 向量在计算时前文指代是可见的,于是即便前文 token 已不在序列里,被消解后的含义仍然烧进了数字里。这是全文最核心的杠杆,也是它最脆弱的地方:这层消解只存在于向量中,它在重新定位、周围行被截断之后还能存活多少,是纯经验问题。
框架转变
之前(块缓存流派)                      之后(CoinRAG)

  q                                      q
  |                                      |
  v                                      v
召回 top-k chunks                      召回 top-k chunks
  |                                      |
  v                                      v
+----------+----------+----------+     在块内部给颗粒打分
|  KV(C1)  |  KV(C2)  |  KV(C3)  |       |
+----------+----------+----------+       v
  ^ 整块复用                       +--+  +-+  +---+  +-+
  |                                |n2|  |n1| |n5 |  |n3|  切片
  |  约 4000 token                 +--+  +-+  +---+  +-+
  |  其中约 10% 是证据                |  约 600 token,基本都是证据
  v                                  v
缝合接缝 --> decode              锚点 + 切片 --> 缝合 --> decode

成本:f(块的大小)                成本:f(证据的大小)
噪声:全盘继承                   噪声:在二阶段被过滤
一句话:从”让长上下文编码得便宜”到”让编码的上下文本身变短”,核心转变是把缓存的单位与消费的单位解耦。
专家评审
选题眼光:真缺口,且位置站得好。
块缓存这条线和上下文压缩那条线(LLMLingua、RECOMP、Provence、句级重排)平行跑了很久却几乎没有交集,原因很实在:压缩通常要求你把压缩后的文本重新编码一遍,而那等于把缓存扔了。
注意到”可以在缓存空间里做压缩”——用切片代替重编码——是那种早一年就该有人做出来的连接。
它正好落在整个领域的大趋势上:把 KV 缓存当作一等的、可寻址的数据结构,而不是前向传播的副产品。
方法成熟度:是巧劲,不是蛮力,“切片而非重编码”这个洞见就是整篇论文的价值所在,且确实漂亮。
但有两点让我保持克制。
其一,系统现在有三个耦合组件(块检索器、颗粒检索器、学习式修补),而带三个旋钮的论文,消融实验里通常藏着”其实主要是某一个旋钮在起作用”。我很想知道:增益究竟来自二阶段检索的质量,还是仅仅来自”上下文变短了”这一件事。
其二,有个明显更简单的基线容易被忽略:检索出颗粒之后,直接把拼起来的颗粒文本正常 prefill 一遍。既然上下文已经只有约 600 token,普通 prefill 本来就够快,那整套缓存切片机制买到的东西可能比看上去少。
CoinRAG 相对这个基线的优势,只能来自规模化下的延迟,或者来自”重编码碎片拿不到的语境化信息”——这个对比是我第一个要翻的实验。
实验诚意:我手上只有摘要,以下判断是暂定的。
两个警示点。
(1)主结论是”在快速 prefill 预算下 F1 相对提升 5.3%“。LongBench 多跳任务上的相对提升 5.3%,绝对值大约 1.5–2.5 分,而这些数据集的噪声足够大,需要多个随机种子和逐数据集分解才有说服力。在一个”被选定的”预算下报告相对增益,本身也留下了挑预算的空间;帕累托曲线能缓解这一点,但前提是曲线足够密、交叉点如实呈现。
(2)成本核算的边界极其重要。二阶段颗粒检索是真实的在线开销。如果它被排除在”prefill 延迟”之外,而基线的全部开销都算在 prefill 里,那这个对比就偏向 CoinRAG。
同样要查的还有:学习式修补是否意味着 CoinRAG 拿到了 CacheBlend 没有的微调;颗粒索引相对块索引多占多少内存。
只在多跳问答上评测是很窄的切面——碎片化上下文对摘要、或任何需要篇章级连贯性的任务,风险应该大得多,对此保持沉默是显眼的。
写作功力:摘要花了一句半解释”硬币”这个比喻,在数贡献点的会场里这是笔亏本交易。
“seamlessly assembles(无缝拼装)“承担了太多未被审视的工作——接缝恰恰是最难的部分,诚实的写法是把机制点名说清。
最该重写的是成本模型那一节:一张干净、显式的预算表(离线算力、存储、索引体积、二阶段检索延迟、修补 FLOPs、decode 长度)能把这篇从”数字不错”提升到”可落地”,而这正是偏工程的读者会去找、我猜找不到的东西。
判决:弱接收 —— 一个真正好的想法(在缓存空间而非文本空间做压缩)配上可信的效率故事,但被过窄的评测和”只被断言、未被展示”的成本核算边界拖住了。
要点总结
-
可迁移的原语:切片,不要重编码。 任何缓存文本表示的流水线都能用。如果你已经有整篇文档的预计算表示,从这个表示里抽子区间,能保住重编码该子区间时必然丢掉的语境。这适用于后期交互检索器、文档重排器,以及任何支持区间寻址的向量缓存,不限于 KV 缓存。
-
把存储单位和消费单位解耦。 RAG 里的 chunk size 通常是一个数字兼三份差事:检索粒度、缓存粒度、上下文粒度。它们的最优值不同。把它们拆开是一个与本文其他部分无关的、廉价的架构收益。
-
层次化检索当作延迟工具。 两阶段检索通常被当成质量技巧(先召回后精排)。这里它是成本技巧:二阶段存在的目的是缩小 LLM 要读的东西。如果你被延迟卡住,一个便宜的块内过滤器可能比一个更好的一阶段检索器更值。
-
“锚点”模式。 在细粒度碎片旁保留一份粗粒度上下文表示,是对抗过度剪枝的可复用保险。任何时候你压缩上下文又担心丢掉线索,都值得借用。
-
不该盲信的部分:碎片拼装在”短答案多跳问答”之外是否安全。在把它用于任何生成型任务之前,先在需要模型尊重篇章顺序的任务上测一遍。