Paper: 2605.31591 Authors: Nurjahan Sultana, Moi Hoon Yap, Xinqi Fan, Wenqi Lu Categories: cs.CV
The Gap
Domain adaptation for medical imaging has focused on aligning visual distributions between source (expert dermoscopic) and target (consumer clinical) domains. Methods like adversarial alignment or self-training treat images as pixel patterns, ignoring that dermatologists reason through clinical concepts—asymmetry, border irregularity, color variation. Foundation models like MONET can now extract these concepts as dense probabilistic maps, but here’s the paradox: this metadata exists only at training time. At deployment, a real-world screening app receives just a smartphone photo. Existing methods can’t leverage concepts during training without requiring them at test time, leaving a deployment gap between what helps learning and what’s available in practice.
Problem: Expert images → Consumer images (distribution shift)
   |
   v
Prior approaches: Align pixel distributions
   |                (ignore semantic invariants)
   v
Limitation: Can't use concept metadata at test time
   |           (deployment paradox)
   v
This paper: Train with concepts, deploy image-only
   |           (privileged information distillation)
   v
Evidence: +5.8% melanoma recall vs. state-of-the-art
   |
   v
Conclusion: Semantic reasoning can be "baked" into weights
The Increment
One sentence: Before, domain adaptation either ignored clinical concepts or required them at test time; after, models learn from concepts during training but deploy as pure image classifiers.
Core Mechanism
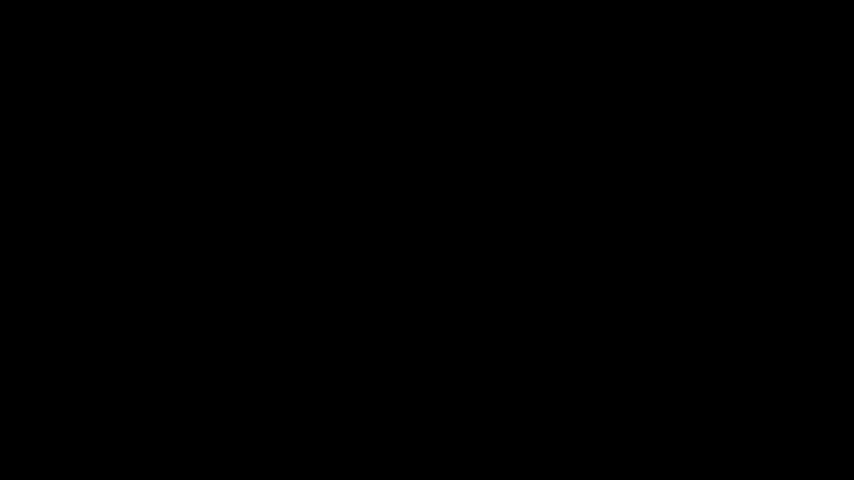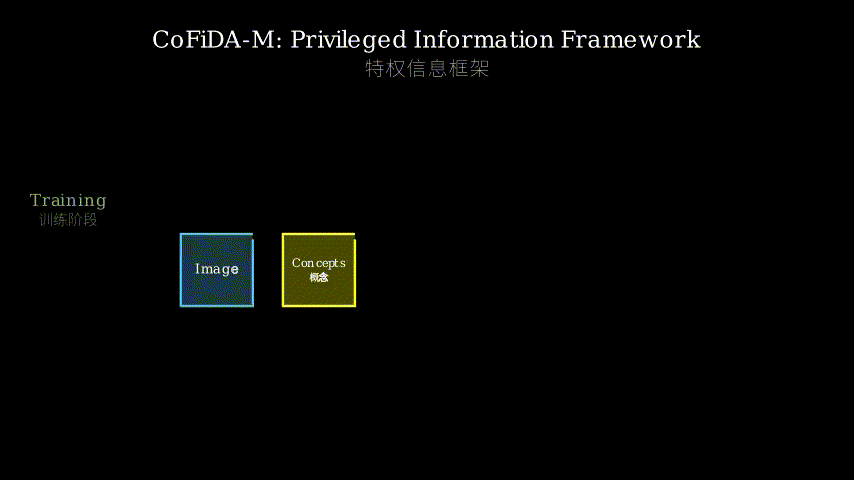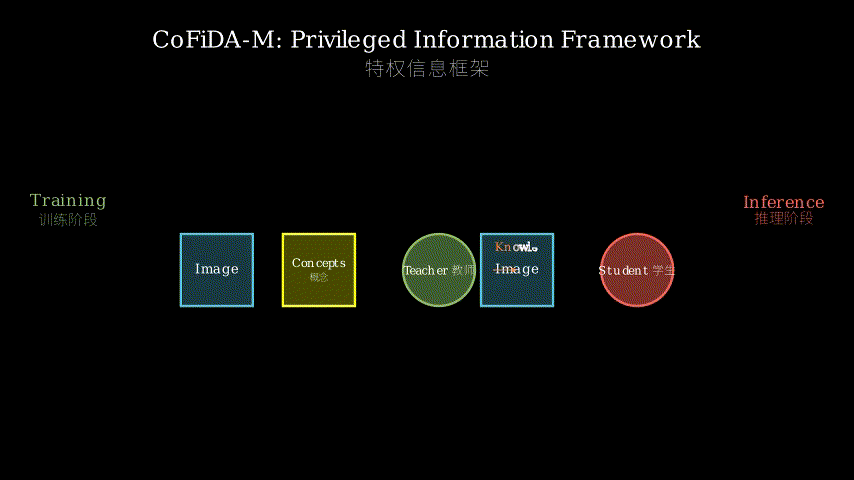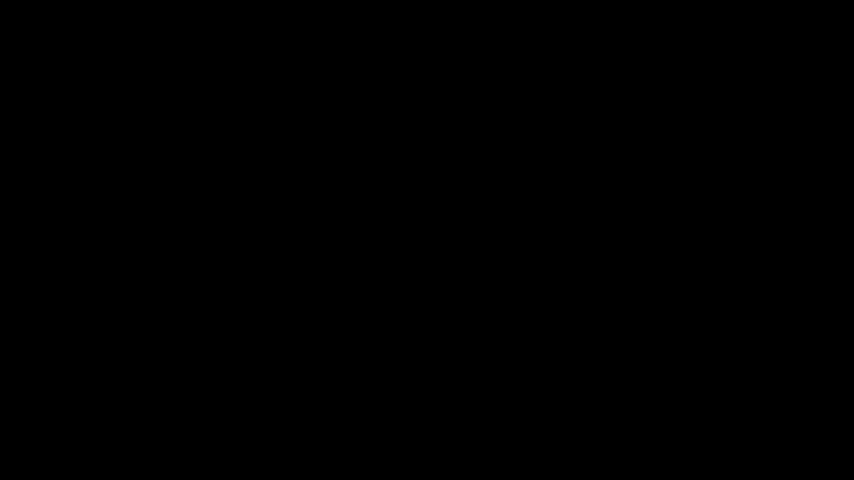
CoFiDA-M operates in two phases. First, a teacher network receives both images and MONET concept probability maps (dense spatial grids indicating likelihood of clinical features like asymmetry or irregular borders). The teacher uses FiLM (Feature-wise Linear Modulation) layers to transform visual features based on concept probabilities—essentially “editing” the feature space to emphasize semantically relevant patterns. This produces a concept-aware representation that bridges domain gaps through clinical invariants rather than pixel statistics.
Second, a lightweight student network receives only images. Instead of mimicking the teacher’s final predictions (standard knowledge distillation), the student is trained to reproduce the teacher’s edited feature representation. This forces the student to internalize the semantic transformations the teacher performed with explicit concept guidance. The student’s weights effectively encode “if I had concept maps, I would adjust features this way”—the clinical reasoning becomes implicit.
At deployment, the student runs standalone on consumer images, no metadata required. The concept-guided feature editing that required MONET at training time is now embedded in the student’s learned transformations.
Training Phase:
Image + Concepts ──> Teacher (FiLM modulator) ──> Edited Features
                                                         |
                                                         v
Image only ──────────> Student ──────────────> Mimic Edited Features
                                                         |
                                                         v
                                                   Final Prediction

Deployment Phase:
Consumer Image ──> Student (concepts baked in) ──> Prediction
Think of it like learning to cook from a master chef who uses precise thermometers and pH meters. The teacher (chef) adjusts seasoning based on exact measurements (concept probabilities). The student (apprentice) watches not just the final dish but how the chef’s hand moves when adding salt after seeing a pH reading. Through repeated observation, the apprentice learns to estimate “this needs more acid” from visual cues alone—the thermometer’s guidance is now internalized as intuition. At deployment, the apprentice cooks without instruments, but the precision training shaped their instincts. The FiLM modulator is the chef’s hand adjusting features; the student learns to make those adjustments from visual cues that correlate with concepts.
Key Concepts
-
Privileged Information: During training, you have extra data (here, concept maps from MONET) that won’t be available at test time. Instead of ignoring it or requiring it forever, you use it to guide learning, then distill that guidance into a model that doesn’t need it. It’s like training a radiologist with textbook annotations overlaid on X-rays, then deploying them to read unmarked films—the annotations shaped their perception but aren’t needed anymore. The key insight: metadata can teach without being a runtime dependency.
-
FiLM (Feature-wise Linear Modulation): A mechanism to conditionally transform neural network features based on external information. Given a feature map and a conditioning signal (here, concept probabilities), FiLM applies learned affine transformations:
output = gamma ** features + beta, where gamma and beta are predicted from the conditioning signal. It’s like a volume knob and tone control for each feature channel—concept probabilities tell the network “turn up asymmetry-sensitive features, turn down texture noise.” This lets the network dynamically re-weight what it pays attention to based on semantic context. -
Feature-Space Distillation: Traditional distillation matches a student’s output probabilities to a teacher’s. Feature-space distillation matches intermediate representations. Why? Output probabilities collapse all reasoning into a single vector; intermediate features preserve the structure of how the teacher “thinks.” By matching edited features rather than final predictions, the student learns the transformation process itself—not just the answer, but the reasoning path. It’s the difference between copying someone’s essay versus learning their outlining method.
Framework Shift
Before (mainstream approach):        After (this paper):

Source ──> Align ──> Target          Source + Concepts ──> Teacher
 (pixels)   (adversarial/           (semantic editing)      |
            self-training)                                   v
                                                      Edited Features
                                                             |
                                                             v
                                     Target (image only) ──> Student
                                                      (mimics editing)

Focus: Pixel distribution            Focus: Semantic transformation
Runtime: Image only                  Runtime: Image only
Training: Image only                 Training: Image + metadata
From aligning what images look like to aligning how models reason about them, the core shift is treating concepts as training-time scaffolding rather than runtime requirements.
Expert Assessment
Problem choice: Real and well-motivated. The deployment paradox—foundation models provide rich metadata but practical apps can’t assume it—is a genuine barrier to clinical adoption. The problem sits at the intersection of domain adaptation and practical deployment, addressing a gap that matters beyond dermatology (any field where expert annotations exist at training time but not inference).
Method maturity: Clever use of existing components (FiLM, feature distillation) rather than inventing new architectures. The insight is in the training regime, not the modules. However, the reliance on MONET as the concept source is a potential brittleness—MONET’s own errors propagate. A simpler baseline would be training the student directly on source+target with standard augmentation; the paper doesn’t deeply explore whether the concept detour is necessary or just helpful.
Experimental integrity: Baselines are reasonable (DANN, CDAN, self-training), and the multi-dataset evaluation (Derm7pt, ISIC, PAD-UFES) is stronger than single-dataset claims. Melanoma recall improvements (+5.8% over best baseline) are clinically meaningful. However, the paper doesn’t ablate the cost of the two-stage training—could a single end-to-end model with concept auxiliary losses achieve similar results? The comparison focuses on final performance, not training efficiency or model size.
Writing quality: The abstract and introduction are clear, but the method section buries the key insight (feature-space distillation vs. output distillation) in dense notation. Figure 1 tries to show the full pipeline but ends up cluttered. Rewriting Section 3.2 to lead with the cooking metaphor, then formalize, would make the contribution land faster. The related work section is thorough but could trim 30% without losing substance.
Verdict: Weak accept—the problem is real, the solution is practical, and the results are solid. The method isn’t groundbreaking but it’s a smart engineering contribution that others can build on. The writing needs tightening, and the ablations could be deeper, but the core idea holds up.
Takeaways
Privileged information as training scaffolding: If you have rich metadata at training time (annotations, auxiliary sensors, foundation model outputs) but not at test time, don’t discard it—use it to guide feature learning, then distill into a metadata-free model. This pattern transfers to any domain with training-time-only signals: video models trained with optical flow but deployed on frames alone, NLP models trained with parse trees but deployed on raw text.
Feature distillation over output distillation: When the teacher’s value is in how it processes information (not just what it predicts), match intermediate representations. This preserves the reasoning structure. Useful when the teacher has privileged information or architectural advantages the student can’t replicate.
FiLM for conditional feature editing: If you need to modulate a network’s behavior based on external signals (metadata, context, user preferences), FiLM layers are a lightweight, interpretable mechanism. They’re more parameter-efficient than concatenating signals and re-learning everything.
Concept-based domain adaptation: When domains differ in low-level statistics but share high-level semantics (expert vs. consumer medical images, synthetic vs. real robotics data), aligning through semantic invariants (concepts, object parts, scene structure) can be more robust than pixel-level alignment. Look for foundation models or auxiliary tasks that extract these invariants.
论文: 2605.31591 作者: Nurjahan Sultana, Moi Hoon Yap, Xinqi Fan, Wenqi Lu 分类: cs.CV
缺口
医学图像的域适应一直聚焦于对齐源域(专家皮肤镜图像)和目标域(消费级临床图像)之间的视觉分布。
对抗对齐或自训练等方法将图像视为像素模式,忽略了皮肤科医生通过临床概念进行推理——不对称性、边界不规则、颜色变化。
MONET等基础模型现在可以将这些概念提取为密集的概率图,但悖论在于:这些元数据只在训练时存在。
在部署时,真实的筛查应用只收到一张手机照片。
现有方法无法在训练时利用概念而不在测试时要求它们,在学习有用的东西和实践中可用的东西之间留下了部署鸿沟。
问题:专家图像 → 消费级图像(分布偏移)
   |
   v
先前方法:对齐像素分布
   |        (忽略语义不变量)
   v
局限:测试时无法使用概念元数据
   |     (部署悖论)
   v
本文:训练用概念,部署仅用图像
   |     (特权信息蒸馏)
   v
证据:黑色素瘤召回率比最优基线高5.8%
   |
   v
结论:语义推理可以"烘焙"进权重
增量
一句话: 之前,域适应要么忽略临床概念,要么在测试时需要它们;
之后,模型在训练时从概念学习,但部署为纯图像分类器。
核心机制
CoFiDA-M分两个阶段运作。
首先,教师网络接收图像和MONET概念概率图(指示不对称或不规则边界等临床特征可能性的密集空间网格)。
教师使用FiLM(特征线性调制)层根据概念概率转换视觉特征——本质上是”编辑”特征空间以强调语义相关的模式。
这产生了一个概念感知的表示,通过临床不变量而非像素统计来弥合域差距。
其次,轻量级学生网络只接收图像。
学生不是模仿教师的最终预测(标准知识蒸馏),而是被训练来重现教师的编辑特征表示。
这迫使学生内化教师用显式概念指导执行的语义转换。
学生的权重有效地编码了”如果我有概念图,我会这样调整特征”——临床推理变成了隐式的。
在部署时,学生在消费级图像上独立运行,不需要元数据。
训练时需要MONET的概念引导特征编辑现在嵌入在学生学到的转换中。
训练阶段:
图像+概念 ──> 教师(FiLM调制器)──> 编辑特征
                                        |
                                        v
仅图像 ──────────> 学生 ──────────> 模仿编辑特征
                                        |
                                        v
                                    最终预测

部署阶段:
消费级图像 ──> 学生(概念已烘焙)──> 预测
把它想象成跟大厨学做菜,大厨使用精确的温度计和pH计。
教师(大厨)根据精确测量(概念概率)调整调味。
学生(学徒)观察的不仅是最终菜品,还有大厨看到pH读数后加盐时手的动作。
通过反复观察,学徒学会仅从视觉线索估计”这需要更多酸”——温度计的指导现在内化为直觉。
在部署时,学徒不用仪器做菜,但精确训练塑造了他们的本能。
FiLM调制器是大厨调整特征的手;
学生学会从与概念相关的视觉线索做出这些调整。
关键概念
- 特权信息: 在训练期间,你有额外的数据(这里是来自MONET的概念图),这些数据在测试时不可用。
你不是忽略它或永远需要它,而是用它来指导学习,然后将该指导蒸馏到不需要它的模型中。
这就像用教科书注释叠加在X光片上训练放射科医生,然后部署他们阅读无标记的胶片——注释塑造了他们的感知,但不再需要了。
关键洞察:元数据可以教学而不成为运行时依赖。
- FiLM(特征线性调制): 一种基于外部信息有条件地转换神经网络特征的机制。
给定特征图和条件信号(这里是概念概率),FiLM应用学习的仿射变换:输出 = gamma * 特征 + beta,其中gamma和beta从条件信号预测。
它就像每个特征通道的音量旋钮和音调控制——概念概率告诉网络”调高不对称敏感特征,调低纹理噪声”。
这让网络根据语义上下文动态重新加权它关注的内容。
- 特征空间蒸馏: 传统蒸馏将学生的输出概率与教师的匹配。
特征空间蒸馏匹配中间表示。
为什么?输出概率将所有推理折叠成单个向量;
中间特征保留了教师”思考”方式的结构。
通过匹配编辑特征而非最终预测,学生学习转换过程本身——不仅是答案,还有推理路径。
这是复制某人的文章与学习他们的大纲方法之间的区别。
框架转变
之前(主流方法):              之后(本文方法):

源域 ──> 对齐 ──> 目标域        源域+概念 ──> 教师
(像素)  (对抗/              (语义编辑)    |
         自训练)                              v
                                          编辑特征
                                              |
                                              v
                                目标域(仅图像)──> 学生
                                          (模仿编辑)

焦点:像素分布                  焦点:语义转换
运行时:仅图像                  运行时:仅图像
训练:仅图像                    训练:图像+元数据
从对齐图像看起来的样子到对齐模型如何推理它们,核心转变是将概念视为训练时脚手架而非运行时需求。
专家评审
选题眼光: 真实且动机充分。
部署悖论——基础模型提供丰富元数据但实用应用无法假设它——是临床采用的真正障碍。
问题位于域适应和实际部署的交叉点,解决了一个超越皮肤病学的重要缺口(任何专家注释在训练时存在但推理时不存在的领域)。
方法成熟度: 巧妙使用现有组件(FiLM、特征蒸馏)而非发明新架构。
洞察在于训练机制,而非模块。
然而,对MONET作为概念源的依赖是潜在的脆弱性——MONET自身的错误会传播。
一个更简单的基线是直接在源域+目标域上用标准增强训练学生;
论文没有深入探讨概念绕道是必要的还是仅仅有帮助。
实验诚意: 基线合理(DANN、CDAN、自训练),多数据集评估(Derm7pt、ISIC、PAD-UFES)比单数据集声明更强。
黑色素瘤召回率改进(比最佳基线高5.8%)具有临床意义。
然而,论文没有消融两阶段训练的成本——具有概念辅助损失的单个端到端模型能否实现类似结果?比较侧重于最终性能,而非训练效率或模型大小。
写作功力: 摘要和引言清晰,但方法部分将关键洞察(特征空间蒸馏vs输出蒸馏)埋在密集的符号中。
图1试图展示完整流程但最终显得杂乱。
重写3.2节以烹饪比喻开头,然后形式化,会让贡献更快落地。
相关工作部分很全面,但可以削减30%而不失实质。
判决: 弱接收——问题真实,解决方案实用,结果扎实。
方法不是开创性的,但它是一个聪明的工程贡献,其他人可以在此基础上构建。
写作需要收紧,消融可以更深入,但核心思想站得住脚。
要点总结
特权信息作为训练脚手架: 如果你在训练时有丰富的元数据(注释、辅助传感器、基础模型输出)但测试时没有,不要丢弃它——用它来指导特征学习,然后蒸馏到无元数据模型中。
这种模式可迁移到任何具有仅训练时信号的领域:用光流训练但仅在帧上部署的视频模型,用解析树训练但在原始文本上部署的NLP模型。
特征蒸馏优于输出蒸馏: 当教师的价值在于它如何处理信息(而非它预测什么)时,匹配中间表示。
这保留了推理结构。
当教师具有学生无法复制的特权信息或架构优势时很有用。
FiLM用于条件特征编辑: 如果你需要根据外部信号(元数据、上下文、用户偏好)调制网络行为,FiLM层是一种轻量级、可解释的机制。
它们比连接信号并重新学习一切更节省参数。
基于概念的域适应: 当域在低级统计上不同但共享高级语义时(专家vs消费级医学图像、合成vs真实机器人数据),通过语义不变量(概念、对象部分、场景结构)对齐可能比像素级对齐更稳健。
寻找提取这些不变量的基础模型或辅助任务。