Paper: 2606.06492 Authors: Liliana Hotsko, Yinxi Li, Yuntian Deng, Pengyu Nie Categories: cs.SE, cs.AI, cs.CL
The Gap
Code language models need repository-level context — imports, APIs, project conventions — to generate useful completions. Two existing solutions dominate: RAG-based context injection (retrieve relevant code snippets and stuff them into the prompt) and per-repository fine-tuning (train a LoRA adapter for each repo). RAG adds hundreds or thousands of tokens per query, eating inference budget. Per-repo fine-tuning requires training on every repository and breaks when code evolves — you retrain from scratch or accept stale adapters. At scale, neither approach is economical: thousands of repositories × thousands of commits = infeasible training cost.
The gap: we lack a method that (1) injects repository knowledge without token overhead, (2) generates adapters without per-repo training, and (3) handles evolving codebases incrementally.
Problem: Code LMs need repo context
   |
   v
Existing approaches:              Limitations:
RAG (retrieve + inject)    -->    +500-2000 tokens per query
Per-repo LoRA training     -->    Training cost × num_repos
                                  Brittle to code evolution
   |
   v
Gap: Need zero-token injection + zero per-repo training + evolution support
   |
   v
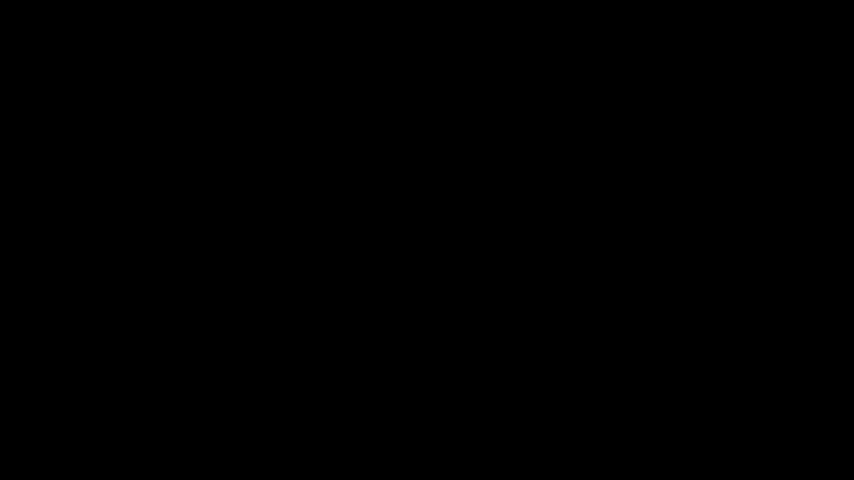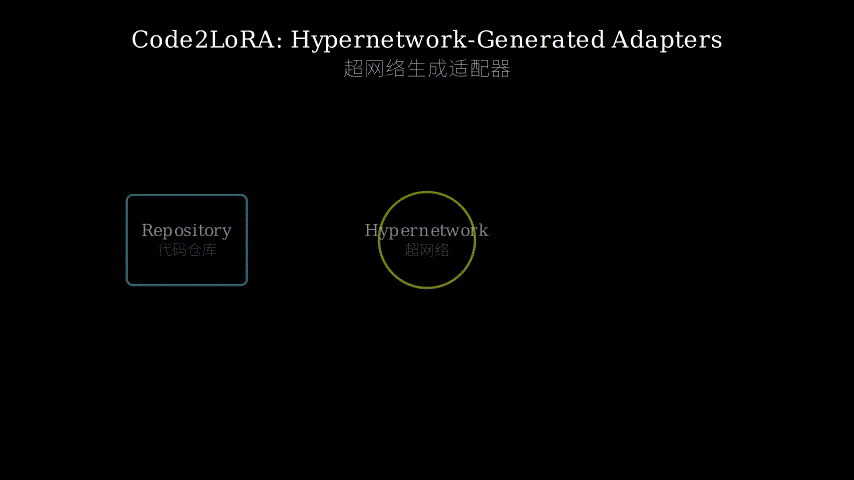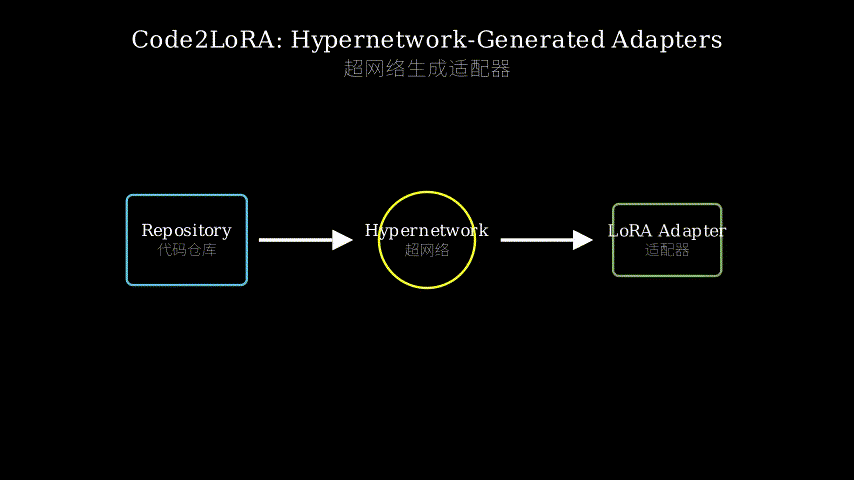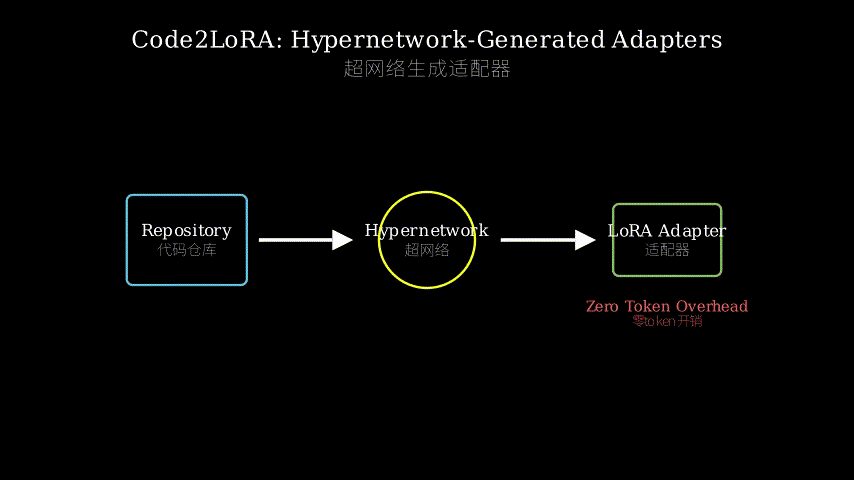
Method: Hypernetwork generates LoRA adapters from code embeddings
   |
   v
Evidence: 63.8% cross-repo EM (matches per-repo LoRA), +5.2 pp on evolution track
   |
   v
Conclusion: Hypernetworks amortize training cost, support evolution, eliminate token overhead
The Increment
One sentence: Before this paper, repository knowledge required either token-heavy retrieval or per-repository training; after, a single hypernetwork converts any repository snapshot or commit stream into a LoRA adapter with zero inference tokens.
Core Mechanism
Code2LoRA has two components: a code encoder and a hypernetwork. The code encoder (CodeBERT) converts repository code into embeddings. The hypernetwork is a neural network that takes these embeddings and outputs LoRA weight matrices — the adapter parameters that will modify a base code language model.
Two variants exist. Code2LoRA-Static processes a single repository snapshot: embed all files, aggregate embeddings (mean pooling), feed to hypernetwork, output one static LoRA adapter. Code2LoRA-Evo maintains a hidden state updated per commit: embed the diff, update a GRU hidden state, feed GRU state to hypernetwork, output an adapter that reflects the current codebase state. Each commit produces a new adapter without retraining the hypernetwork.
At inference, the generated adapter plugs into the base language model (CodeGen-350M or StarCoder2-3B). No repository code appears in the prompt. The adapter’s injected knowledge handles imports, APIs, conventions implicitly through modified attention and feedforward weights.
Code2LoRA-Static:                Code2LoRA-Evo:

Repo files                        Commit stream
   |                                 |
   v                                 v
CodeBERT encoder                  CodeBERT encoder (diff)
   |                                 |
   v                                 v
Aggregate (mean)                  GRU hidden state (updated)
   |                                 |
   v                                 v
Hypernetwork                      Hypernetwork
   |                                 |
   v                                 v
LoRA adapter W_A, W_B             LoRA adapter W_A, W_B (per commit)
   |                                 |
   +--------+------------------------+
            |
            v
   Base LM + adapter --> code completion
   (zero prompt tokens for repo context)
Think of the hypernetwork as a key duplicator. You bring your repository (the original key’s shape) to the machine. The machine scans it, then fabricates a custom adapter key (LoRA weights) that unlocks repository-specific knowledge inside the base model’s lock. The base model is unchanged; you just carry the right key.
For evolution, imagine the key duplicator has memory. Each time you bring a code diff (a modification to the key’s shape), the machine updates its internal blueprint (GRU state) and prints a new key reflecting all changes so far. You never re-scan the entire original key — just feed incremental modifications.
Key Concepts
-
LoRA (Low-Rank Adaptation): Fine-tuning a billion-parameter model is expensive. LoRA freezes the original model and injects small trainable matrices and (rank ) into each layer: output = original_output + . Training only and (a few million parameters) is cheap. For code models, a per-repository LoRA captures project-specific patterns. The problem: you need to train one LoRA per repository. If you have 10,000 repositories, you train 10,000 times.
-
Hypernetwork: Instead of training parameters directly, train a network that generates parameters. A hypernetwork takes a description (e.g., repository embeddings) and outputs weights . Once is trained on many repositories, generating weights for a new repository requires one forward pass through , not gradient descent. It’s parameter synthesis rather than parameter learning. In Code2LoRA, generates LoRA matrices: .
-
Assertion-Completion Task: The benchmark evaluates whether models can complete assertions in unit tests. Given a test function with the assertion line masked (e.g.,
assert result == ___), the model must predict the right-hand side. This task requires understanding function behavior, API contracts, and project conventions — exactly the knowledge that repository context should provide. It’s more realistic than next-token prediction on arbitrary code snippets.
Framework Shift
Before (RAG or per-repo training):        After (Code2LoRA):

Query time:                                Query time:
User prompt                                User prompt
   |                                          |
   v                                          v
Retrieve context (500-2000 tokens)         Base LM + adapter (0 tokens)
   |                                          |
   v                                          v
Base LM (prompt + context)                 Code completion
   |
   v
Code completion

Training time:                             Training time:
Per-repo gradient descent                  Train hypernetwork once
(repeat for each repo)                        |
                                              v
                                           Generate adapter per repo
                                           (one forward pass)
From retrieval-augmented generation to retrieval-free adaptation, the core shift is replacing runtime context with baked-in adapter weights.
Expert Assessment
Problem choice: Real gap. Repository context is a recognized bottleneck in code generation. RAG’s token overhead is painful in production, and per-repo fine-tuning doesn’t scale to large code hosts (GitHub has 100M+ repositories). The evolution angle is especially compelling — most code LM work assumes static codebases, but real development is incremental. The authors identified a problem that practitioners feel daily.
Method maturity: Hypernetworks are not new (introduced 2016), but applying them to LoRA generation for code is a clean fit. The GRU-based evolution mechanism is straightforward — arguably the simplest incremental update strategy. Could they have used a Transformer instead of GRU? Maybe, but GRU is cheap and the results justify it. The method feels like an obvious-in-retrospect synthesis of existing ideas rather than a deep algorithmic contribution, but sometimes that’s what moves the field forward.
Experimental integrity: The benchmark (RepoPeftBench) is purpose-built, which raises the usual concern: did they overfit to their own test set? They provide cross-repo and in-repo splits, and cross-repo results (63.8%) are only 2.4 pp below in-repo (66.2%), suggesting decent generalization. Baselines are fair: they compare against shared LoRA (one adapter for all repos) and per-repo LoRA (the upper bound). However, they don’t compare against strong RAG baselines with modern retrieval (e.g., BM25 + reranking). The RAG comparison is mentioned but not thoroughly benchmarked. The evolution track results (+5.2 pp over shared LoRA) are modest but meaningful. One red flag: the absolute numbers (60-66% exact match) are not spectacular. This suggests the task is hard or the models are small (CodeGen-350M, StarCoder2-3B). Larger base models might narrow the gap between methods.
Writing quality: The abstract and introduction are crisp. The method section is clear but could use a complexity analysis — what’s the memory overhead of storing one adapter per repository? How does hypernetwork inference time compare to per-repo LoRA training time? The evaluation section front-loads tables without enough narrative context. A paragraph walking through Table 2 (static track results) before presenting it would help. The related work section is thorough but reads like a laundry list. Cutting it by 30% and integrating key comparisons into the method section would tighten the paper.
Verdict: Weak accept — the problem is real, the method is practical, and the results are solid if unspectacular. The benchmark contribution (RepoPeftBench) adds value. However, the method’s novelty is incremental (hypernetworks applied to LoRA), and the evaluation could be more comprehensive (stronger RAG baselines, larger base models). It’s a good systems paper that makes code LMs more deployable, not a breakthrough in modeling.
Takeaways
For practitioners: If you operate code completion at scale (e.g., GitHub Copilot, Replit), this approach lets you support thousands of repositories without training thousands of adapters. Generate an adapter per repo on-demand, cache it, and swap at inference time. The zero-token overhead is a real cost saving — 1000 tokens per query × millions of queries = significant compute.
For researchers: The hypernetwork-as-parameter-generator pattern transfers to any domain where you need task-specific or user-specific adapters. Medical LMs (per-patient adapters), legal LMs (per-jurisdiction adapters), even personalized assistants (per-user adapters) could use this. The GRU-based incremental update is a template for handling any evolving context (user preferences over time, document versions, knowledge base updates).
Steal this: The assertion-completion task is a better benchmark than next-token prediction for evaluating repository-level understanding. If you’re building a code LM benchmark, consider goal-oriented tasks (write a test, fix a bug, implement a function spec) over perplexity on random code snippets.
论文: 2606.06492 作者: Liliana Hotsko, Yinxi Li, Yuntian Deng, Pengyu Nie 分类: cs.SE, cs.AI, cs.CL
缺口
代码语言模型需要仓库级上下文——导入语句、API、项目约定——才能生成有用的补全。
现有两种主流方案:基于RAG的上下文注入(检索相关代码片段并塞入提示)和每仓库微调(为每个仓库训练一个LoRA适配器)。
RAG每次查询要增加几百到上千个token,吃掉推理预算。
每仓库微调需要对每个仓库单独训练,代码演进时方法失效——你要么从头重新训练,要么接受过时的适配器。
规模化时两种方法都不经济:数千仓库 × 数千次提交 = 训练成本不可承受。
缺口在于:我们缺少一种方法能够(1)注入仓库知识但无token开销,(2)生成适配器但无需每仓库训练,(3)增量处理演进中的代码库。
问题:代码LM需要仓库上下文
   |
   v
现有方法:                        局限性:
RAG(检索+注入)           -->    每次查询+500-2000 token
每仓库LoRA训练             -->    训练成本 × 仓库数量
                                  代码演进时容易失效
   |
   v
缺口:需要零token注入 + 零每仓库训练 + 支持演进
   |
   v
方法:超网络从代码嵌入生成LoRA适配器
   |
   v
证据:63.8%跨仓库EM(匹配每仓库LoRA),演进track上+5.2 pp
   |
   v
结论:超网络摊销训练成本,支持演进,消除token开销
增量
一句话:这篇论文之前,仓库知识要么需要大量token检索,要么需要每仓库训练;
之后,单个超网络可将任何仓库快照或提交流转换为LoRA适配器,推理时零token开销。
核心机制
Code2LoRA有两个组件:代码编码器和超网络。
代码编码器(CodeBERT)将仓库代码转为嵌入向量。
超网络是一个神经网络,接收这些嵌入,输出LoRA权重矩阵——这些适配器参数会修改基础代码语言模型。
存在两个变体。
Code2LoRA-Static处理单个仓库快照:嵌入所有文件,聚合嵌入(均值池化),输入超网络,输出一个静态LoRA适配器。
Code2LoRA-Evo维护一个按提交更新的隐藏状态:嵌入diff,更新GRU隐藏状态,将GRU状态输入超网络,输出反映当前代码库状态的适配器。
每次提交产生新适配器,无需重新训练超网络。
推理时,生成的适配器接入基础语言模型(CodeGen-350M或StarCoder2-3B)。
提示中不出现仓库代码。
适配器的注入知识通过修改注意力和前馈权重隐式处理导入、API、约定。
Code2LoRA-Static:                Code2LoRA-Evo:

仓库文件                          提交流
   |                                 |
   v                                 v
CodeBERT编码器                    CodeBERT编码器(diff)
   |                                 |
   v                                 v
聚合(均值)                      GRU隐藏状态(更新)
   |                                 |
   v                                 v
超网络                            超网络
   |                                 |
   v                                 v
LoRA适配器 W_A, W_B               LoRA适配器 W_A, W_B(每次提交)
   |                                 |
   +--------+------------------------+
            |
            v
   基础LM + 适配器 --> 代码补全
   (仓库上下文零提示token)
把超网络想象成配钥匙机器。
你带着仓库(原始钥匙的形状)来到机器前。
机器扫描它,然后制作一把定制的适配器钥匙(LoRA权重),能打开基础模型锁内的仓库特定知识。
基础模型不变;
你只是带着合适的钥匙。
对于演进场景,想象配钥匙机器有记忆。
每次你带来代码diff(钥匙形状的修改),机器更新内部蓝图(GRU状态),打印一把反映迄今所有改动的新钥匙。
你不用重新扫描整把原始钥匙——只需输入增量修改。
关键概念
- LoRA(低秩适配):微调十亿参数模型很昂贵。
LoRA冻结原始模型,在每层注入小的可训练矩阵和(秩):输出 = 原始输出 + 。
只训练和(几百万参数)成本低。
对于代码模型,每仓库的LoRA捕获项目特定模式。
问题在于:你需要为每个仓库训练一个LoRA。
如果有1万个仓库,就要训练1万次。
- 超网络:不直接训练参数,而是训练一个生成参数的网络。
超网络接收描述(例如仓库嵌入),输出权重。
一旦在多个仓库上训练完成,为新仓库生成权重只需一次前向传播通过,无需梯度下降。
这是参数合成而非参数学习。
在Code2LoRA中,生成LoRA矩阵:。
- 断言补全任务:基准测试评估模型能否补全单元测试中的断言。
给定一个测试函数,断言行被遮蔽(例如assert result == ___),模型必须预测右侧。
此任务需要理解函数行为、API契约和项目约定——正是仓库上下文应该提供的知识。
比在任意代码片段上做下一token预测更真实。
框架转变
之前(RAG或每仓库训练):              之后(Code2LoRA):

查询时:                                查询时:
用户提示                                用户提示
   |                                       |
   v                                       v
检索上下文(500-2000 token)            基础LM + 适配器(0 token)
   |                                       |
   v                                       v
基础LM(提示+上下文)                   代码补全
   |
   v
代码补全

训练时:                                训练时:
每仓库梯度下降                          训练超网络一次
(每个仓库重复)                           |
                                          v
                                       每仓库生成适配器
                                       (一次前向传播)
从检索增强生成到无检索适配,核心转变是用内嵌的适配器权重替代运行时上下文。
专家评审
选题眼光:真实缺口。
仓库上下文是代码生成中公认的瓶颈。
RAG的token开销在生产环境很痛苦,每仓库微调无法扩展到大型代码托管平台(GitHub有1亿+仓库)。
演进角度尤其有说服力——大多数代码LM工作假设静态代码库,但真实开发是增量的。
作者识别出了实践者每天都能感受到的问题。
方法成熟度:超网络不是新东西(2016年引入),但将其应用于代码的LoRA生成是个干净的契合。
基于GRU的演进机制很直接——可以说是最简单的增量更新策略。
能用Transformer替代GRU吗?
也许可以,但GRU便宜且结果证明有效。
方法感觉像是现有想法的事后看来显而易见的综合,而非深层算法贡献,但有时正是这种工作推动领域前进。
实验诚意:基准(RepoPeftBench)是专门构建的,这引发常见担忧:他们是否过拟合到自己的测试集?
他们提供了跨仓库和仓库内分割,跨仓库结果(63.8%)仅比仓库内(66.2%)低2.4 pp,表明泛化能力不错。
基线公平:他们与共享LoRA(所有仓库一个适配器)和每仓库LoRA(上界)对比。
然而,他们没有与现代检索的强RAG基线对比(例如BM25+重排序)。
RAG对比有提及但未充分基准测试。
演进track结果(比共享LoRA +5.2 pp)适度但有意义。
一个警示信号:绝对数字(60-66%精确匹配)不算壮观。
这表明任务很难或模型太小(CodeGen-350M,StarCoder2-3B)。
更大的基础模型可能缩小方法间差距。
写作功力:摘要和引言简洁。
方法部分清晰但可以加入复杂度分析——每仓库存储一个适配器的内存开销是多少?
超网络推理时间与每仓库LoRA训练时间比较如何?
评估部分前置表格但缺乏足够的叙事上下文。
展示表2(静态track结果)前先用一段话解读会有帮助。
相关工作部分详尽但读起来像清单。
删减30%并将关键对比整合进方法部分会让论文更紧凑。
判决:弱接收——问题真实,方法实用,结果扎实但不算壮观。
基准贡献(RepoPeftBench)有价值。
然而,方法新颖性是增量式的(超网络应用于LoRA),评估可以更全面(更强的RAG基线,更大的基础模型)。
这是一篇让代码LM更易部署的好系统论文,不是建模上的突破。
要点总结
对于实践者:如果你大规模运营代码补全(例如GitHub Copilot、Replit),这种方法让你无需训练数千个适配器就能支持数千个仓库。
按需为每个仓库生成适配器,缓存它,推理时切换。
零token开销是真正的成本节省——每次查询1000 token × 数百万次查询 = 显著的计算量。
对于研究者:超网络作为参数生成器的模式可迁移到任何需要任务特定或用户特定适配器的领域。
医疗LM(每患者适配器)、法律LM(每司法管辖区适配器),甚至个性化助手(每用户适配器)都可以用这个。
基于GRU的增量更新是处理任何演进上下文的模板(用户偏好随时间变化、文档版本、知识库更新)。
偷这个:断言补全任务是比下一token预测更好的基准,用于评估仓库级理解。
如果你在构建代码LM基准,考虑面向目标的任务(编写测试、修复bug、实现函数规范),而非随机代码片段的困惑度。