Paper: 2605.18747 Authors: Xuying Ning, Katherine Tieu, Dongqi Fu, Tianxin Wei, Zihao Li, Yuanchen Bei, Jiaru Zou, Mengting Ai, Zhining Liu, Ting-Wei Li Categories: cs.CL, cs.AI
The Gap
Existing LLM agent research treats code as a target output—something to generate and evaluate for correctness. But as agents move from toy benchmarks to real-world deployment (GUI automation, scientific discovery, DevOps), code is increasingly the medium through which agents reason, act, maintain state, and verify outcomes. Prior work fragments this reality: some papers focus on code generation, others on tool use, still others on multi-agent coordination. No unified framework captures code’s role as the operational substrate—the harness—that makes agents executable and verifiable.
Problem: Agents need executable infrastructure
   |
   v
Observation: Code already serves this role (implicitly)
   |
   v
Gap: No unified view of "code as harness"
   |
   v
Method: Survey organizing around harness layers
   |
   v
Evidence: 100+ papers across 7 application domains
   |
   v
Conclusion: Code-as-harness is a design principle
The Increment
One sentence: Before this paper, code was an agent’s output; after, code is the agent’s skeleton—the harness that structures reasoning, action, memory, and multi-agent coordination into something you can run and verify.
Core Mechanism
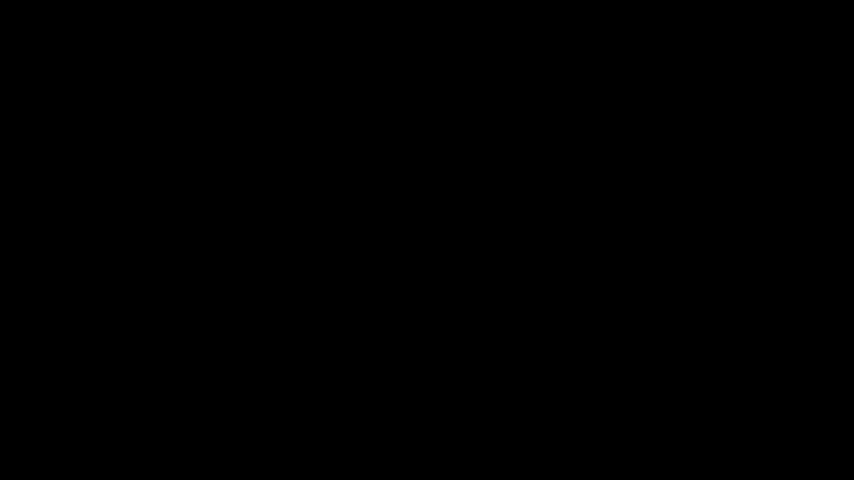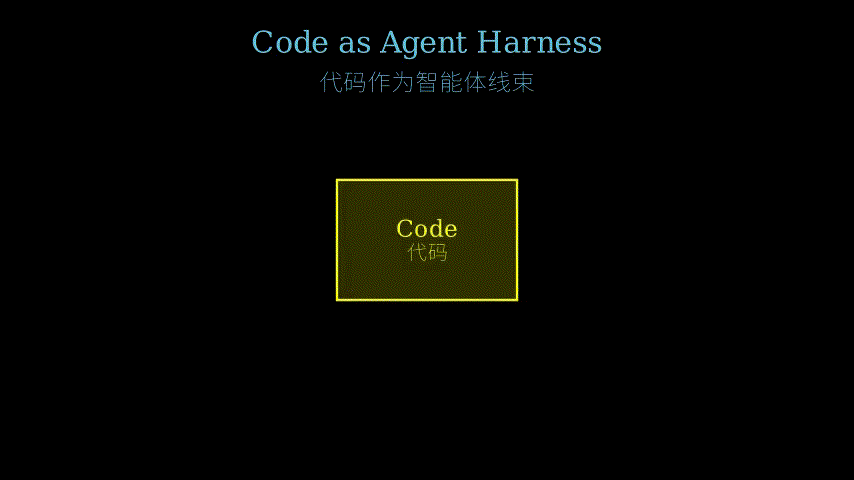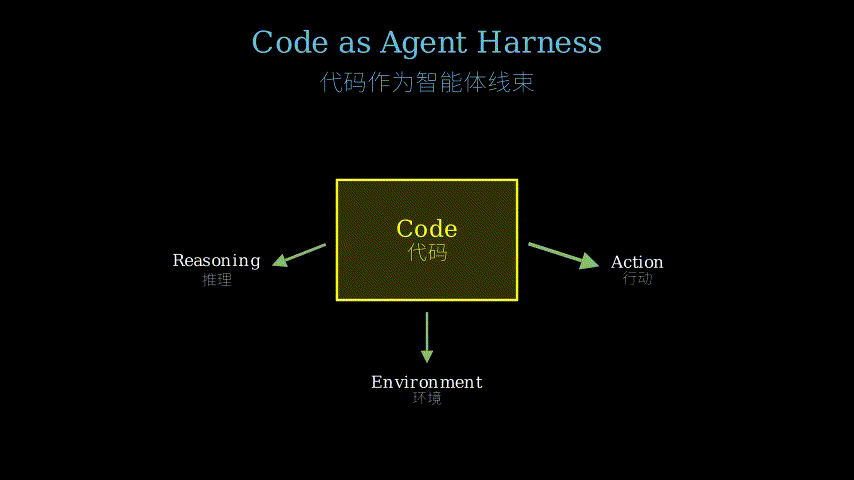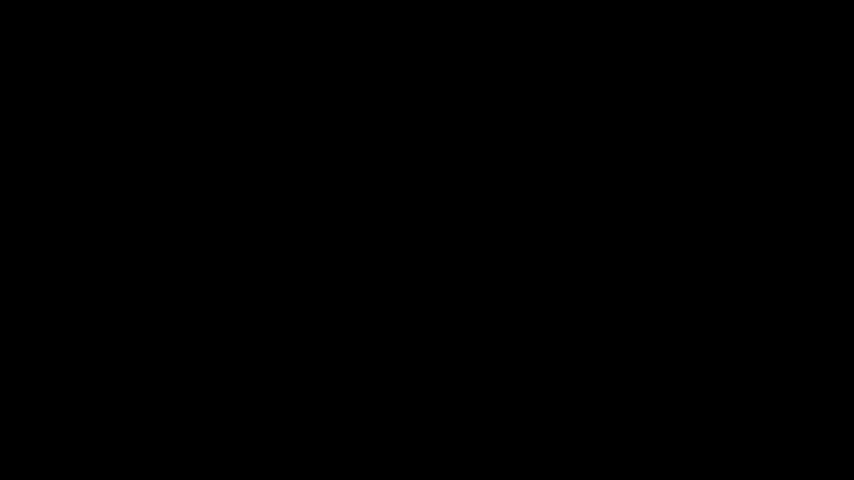
The paper doesn’t propose a new algorithm. It’s a conceptual framework organizing existing work into three layers. Layer 1 (Interface): Code connects agents to three primitives—reasoning (code as structured thought), action (code as executable commands), and environment modeling (code as state representation). Layer 2 (Mechanisms): Planning, memory, and tool use enable long-horizon tasks; feedback loops and optimization make the harness adaptive. Layer 3 (Scaling): Multi-agent systems use shared code artifacts for coordination, review, and verification.
Layer 3: Multi-Agent Scaling
   |
   +---> Shared code artifacts
   +---> Coordination protocols
   +---> Verification workflows
   |
Layer 2: Harness Mechanisms
   |
   +---> Planning (decompose tasks into code)
   +---> Memory (code as persistent state)
   +---> Tool use (code as API glue)
   +---> Feedback (execution results -> refinement)
   |
Layer 1: Harness Interface
   |
   +---> Reasoning: code as structured thought
   +---> Action: code as executable commands
   +---> Environment: code as state model
Think of it like electrical wiring in a building. Before, you had appliances (agents) that someone evaluated by plugging them into a test socket (benchmarks). Now you’re designing the entire electrical system. Layer 1 is the outlets and switches—the interface where agents connect to power (reasoning), control devices (action), and sense the environment (state). Layer 2 is the circuit breakers, timers, and smart home logic—mechanisms that route power, remember schedules, and adapt to load. Layer 3 is the grid connecting multiple buildings—shared infrastructure where agents coordinate without stepping on each other’s toes. The harness isn’t the appliance; it’s the wiring that makes appliances useful in a real building.
Key Concepts
-
Agent Harness: The infrastructure that connects an agent’s high-level intent to executable operations. In traditional robotics, a harness is the physical wiring and control logic between a brain (planner) and actuators (motors). Here, code plays that role: it translates abstract goals (“book a flight”) into concrete API calls, maintains state across steps, and provides feedback from execution. Without a harness, an agent is just a language model generating text. With a harness, it’s a system that *does things.
-
Code as Reasoning Substrate: Instead of generating natural language chains-of-thought, agents write code to think. Why? Code has syntax constraints (catches errors early), is executable (you can run it to verify), and composes (functions call functions). Example: An agent solving a math problem doesn’t write “first I’ll compute X, then Y”—it writes
x = compute_x(data); y = compute_y(x). The code *is the reasoning trace, and running it proves correctness. -
Execution-Based Verification: Traditional agents rely on human eval or model-based scoring. Code-as-harness enables a tighter loop: write code, run it, check if it crashes or produces the right output, refine. This shifts verification from subjective judgment to objective execution. Example: A coding assistant doesn’t just generate a function—it runs tests, sees failures, and iterates. The harness makes this loop fast and automatic.
Framework Shift
Before (code as output):              After (code as harness):

  User Query                            User Query
      |                                     |
      v                                     v
  LLM generates code                   LLM writes code
      |                                     |
      v                                     v
  Human evaluates                      Code executes
      |                                     |
      v                                     v
  Task done (or fails)                 Feedback loop
                                            |
                                            v
                                       Refine & retry
                                            |
                                            v
                                       Task done (verified)
From “code is the deliverable” to “code is the delivery mechanism,” the core shift is making agents executable systems rather than text generators.
Expert Assessment
Problem choice: Real and timely. The gap between “LLMs can code” and “LLMs can build reliable agents” is wide. Framing code as infrastructure rather than output is a natural next step, though not entirely novel—robotics and formal methods have long used code as operational substrate. The contribution is recognizing this pattern in LLM agents and organizing scattered work under one lens.
Method maturity: This is a survey, not a method paper, so “maturity” means conceptual clarity. The three-layer framework is clean but not groundbreaking—it’s a taxonomy, not a theory. The real value is synthesis: pulling together 100+ papers and showing they’re all variations on “code as harness.” The risk is that the framework is too broad to be falsifiable. What *wouldn’t fit under “code as harness”?
Experimental integrity: No experiments—this is a literature survey. The authors cite extensively and fairly represent prior work. One weakness: the paper doesn’t critically assess which harness designs actually work in practice. It catalogs approaches but doesn’t rank them by reliability, scalability, or failure modes. A practitioner reading this still doesn’t know *which harness to build.
Writing quality: Solid structure, but the paper tries to cover too much. The application section (coding assistants, GUI automation, embodied agents, etc.) reads like a laundry list. Cutting two domains and going deeper on the rest would strengthen the narrative. The “open challenges” section is the most valuable—it names hard problems (regression-free improvement, multi-agent state consistency) that the field hasn’t solved.
Verdict: weak accept — Useful synthesis and a clear conceptual frame, but lacks depth on what makes a harness succeed or fail in practice. Good for orienting newcomers, less useful for experts building systems.
Takeaways
Steal the three-layer mental model: When designing an agent, ask: (1) What’s my interface? (code for reasoning, action, or environment modeling?), (2) What mechanisms do I need? (planning, memory, feedback loops?), (3) Does this scale to multiple agents? (shared state, coordination protocols?). This checklist prevents ad-hoc designs.
Execution-based verification is underused: If your agent generates code, run it. Don’t just check syntax—execute it in a sandbox, capture errors, and feed them back. This loop is cheap and catches bugs that static analysis misses. The paper shows this pattern across domains (coding assistants, scientific discovery), but many production systems still rely on human review.
Multi-agent harnesses need shared state primitives: The paper flags this as an open problem, but the implication is clear: if you’re building multi-agent systems, design for state consistency from day one. Use version control for code artifacts, message queues for coordination, and formal verification for critical paths. Don’t bolt these on later.
Code as reasoning is a forcing function: Writing code to think forces precision. Natural language lets agents handwave; code doesn’t compile if the logic is broken. If your agent’s reasoning is fuzzy, try making it write executable pseudocode instead of prose. The syntax errors will tell you where the thinking is sloppy.
论文: 2605.18747 作者: Xuying Ning, Katherine Tieu, Dongqi Fu, Tianxin Wei, Zihao Li, Yuanchen Bei, Jiaru Zou, Mengting Ai, Zhining Liu, Ting-Wei Li 分类: cs.CL, cs.AI
缺口
现有的大语言模型智能体研究将代码视为目标输出——生成后评估正确性的东西。
但随着智能体从玩具基准走向实际部署(GUI 自动化、科学发现、DevOps),代码越来越成为智能体推理、行动、维护状态和验证结果的媒介。
先前工作碎片化地处理这一现实:有的论文关注代码生成,有的关注工具使用,还有的关注多智能体协调。
没有统一框架捕捉代码作为操作性基底——线束——使智能体可执行、可验证的角色。
问题:智能体需要可执行的基础设施
   |
   v
观察:代码已经(隐式地)扮演这个角色
   |
   v
缺口:缺乏"代码作为线束"的统一视角
   |
   v
方法:围绕线束层次组织综述
   |
   v
证据:跨 7 个应用领域的 100+ 篇论文
   |
   v
结论:代码作为线束是一种设计原则
增量
一句话: 这篇论文之前,代码是智能体的输出;
之后,代码是智能体的骨架——将推理、行动、记忆和多智能体协调结构化为可运行、可验证之物的线束。
核心机制
这篇论文不提出新算法。
它是一个概念框架,将现有工作组织成三层。
第一层(接口):代码连接智能体到三个原语——推理(代码作为结构化思维)、行动(代码作为可执行命令)、环境建模(代码作为状态表示)。
第二层(机制):规划、记忆和工具使用支持长时程任务;
反馈循环和优化使线束具有适应性。
第三层(扩展):多智能体系统使用共享代码工件进行协调、审查和验证。
第三层:多智能体扩展
   |
   +---> 共享代码工件
   +---> 协调协议
   +---> 验证工作流
   |
第二层:线束机制
   |
   +---> 规划(将任务分解为代码)
   +---> 记忆(代码作为持久状态)
   +---> 工具使用(代码作为 API 粘合剂)
   +---> 反馈(执行结果 -> 改进)
   |
第一层:线束接口
   |
   +---> 推理:代码作为结构化思维
   +---> 行动:代码作为可执行命令
   +---> 环境:代码作为状态模型
把它想象成建筑物里的电气布线。
以前,你有电器(智能体),有人通过插到测试插座(基准测试)来评估它们。
现在你在设计整个电气系统。
第一层是插座和开关——智能体连接到电源(推理)、控制设备(行动)、感知环境(状态)的接口。
第二层是断路器、定时器和智能家居逻辑——路由电力、记住时间表、适应负载的机制。
第三层是连接多栋建筑的电网——共享基础设施,智能体在其中协调而不互相干扰。
线束不是电器;
它是让电器在真实建筑中有用的布线。
关键概念
- 智能体线束:连接智能体高层意图与可执行操作的基础设施。
在传统机器人学中,线束是大脑(规划器)和执行器(电机)之间的物理布线和控制逻辑。
这里,代码扮演这个角色:它将抽象目标(“订机票”)翻译成具体的 API 调用,跨步骤维护状态,并提供执行反馈。
没有线束,智能体只是生成文本的语言模型。
有了线束,它是一个做事的系统。
- 代码作为推理基底:智能体不生成自然语言思维链,而是写代码来思考。
为什么?
代码有语法约束(及早捕获错误),可执行(可以运行来验证),可组合(函数调用函数)。
例子:智能体解决数学问题时不写”首先我计算 X,然后 Y”——它写 x = compute_x(data); y = compute_y(x)。
代码就是推理轨迹,运行它证明正确性。
- 基于执行的验证:传统智能体依赖人工评估或基于模型的打分。
代码作为线束实现更紧密的循环:写代码、运行它、检查是否崩溃或产生正确输出、改进。
这将验证从主观判断转向客观执行。
例子:编码助手不只是生成函数——它运行测试、看到失败、迭代。
线束使这个循环快速且自动。
框架转变
之前(代码作为输出):              之后(代码作为线束):

  用户查询                            用户查询
      |                                     |
      v                                     v
  LLM 生成代码                        LLM 编写代码
      |                                     |
      v                                     v
  人工评估                             代码执行
      |                                     |
      v                                     v
  任务完成(或失败)                   反馈循环
                                            |
                                            v
                                       改进并重试
                                            |
                                            v
                                       任务完成(已验证)
从”代码是交付物”到”代码是交付机制”,核心转变是让智能体成为可执行系统而非文本生成器。
专家评审
选题眼光:真实且及时。
“LLM 会编码”和”LLM 能构建可靠智能体”之间的鸿沟很宽。
将代码框定为基础设施而非输出是自然的下一步,尽管不完全新颖——机器人学和形式化方法长期以来将代码用作操作性基底。
贡献在于识别 LLM 智能体中的这一模式,并在一个视角下组织分散的工作。
方法成熟度:这是综述论文,不是方法论文,所以”成熟度”意味着概念清晰度。
三层框架干净但不突破——它是分类法,不是理论。
真正的价值是综合:汇集 100+ 篇论文,展示它们都是”代码作为线束”的变体。
风险是框架太宽泛而无法证伪。
什么不适合”代码作为线束”?
实验诚意:没有实验——这是文献综述。
作者广泛引用并公正地呈现先前工作。
一个弱点:论文没有批判性地评估哪些线束设计在实践中真正有效。
它编目方法但不按可靠性、可扩展性或失败模式排序。
实践者读完仍不知道该构建哪种线束。
写作功力:结构扎实,但论文试图覆盖太多。
应用部分(编码助手、GUI 自动化、具身智能体等)读起来像清单。
砍掉两个领域,在其余部分深入会强化叙事。
“开放挑战”部分最有价值——它指出该领域尚未解决的难题(无回归改进、多智能体状态一致性)。
判决:弱接收 — 有用的综合和清晰的概念框架,但缺乏关于什么使线束在实践中成功或失败的深度。
适合引导新手,对构建系统的专家用处较小。
要点总结
偷走三层心智模型:设计智能体时,问:(1)我的接口是什么?
(代码用于推理、行动还是环境建模?
),(2)我需要什么机制?
(规划、记忆、反馈循环?
),(3)这能扩展到多智能体吗?
(共享状态、协调协议?
)。
这个检查清单防止临时设计。
基于执行的验证被低估:如果你的智能体生成代码,运行它。
不只检查语法——在沙箱中执行,捕获错误,反馈回去。
这个循环成本低,能捕获静态分析遗漏的 bug。
论文展示这一模式跨领域(编码助手、科学发现),但许多生产系统仍依赖人工审查。
多智能体线束需要共享状态原语:论文将此标记为开放问题,但含义清楚:如果你在构建多智能体系统,从第一天起就为状态一致性设计。
对代码工件使用版本控制,对协调使用消息队列,对关键路径使用形式化验证。
不要事后添加这些。
代码作为推理是强制函数:写代码来思考强制精确。
自然语言让智能体含糊其辞;
代码逻辑有问题就不编译。
如果你的智能体推理模糊,试着让它写可执行伪代码而非散文。
语法错误会告诉你思维哪里松散。