Paper: 2603.13177 Authors: Eraldo Pereira Marinho, Nelson Callegari Junior, Fabricio Aparecido Breve, Caetano Mazzoni Ranieri Categories: astro-ph.EP, astro-ph.IM, cs.AI
The Gap
Celestial mechanics has a scale problem. Traditional methods like Fourier analysis and Lyapunov exponents work beautifully for analyzing individual orbits or small systems, but they choke on modern datasets with tens of thousands of simulated trajectories. When you’re studying Saturn’s satellite system with 22,300 orbital simulations, each spanning 400 timesteps, you need to identify which orbits are stable, which are in resonance, and which exhibit chaotic behavior. The old toolkit doesn’t scale—Fourier transforms become computationally prohibitive, and manual inspection is impossible.
Previous approaches: compute stability metrics per orbit, run Fourier analysis on orbital elements, manually categorize behaviors. The bottleneck: these methods don’t naturally group similar orbits or reveal emergent patterns across the entire dataset.
Problem: 22,300 orbits x 400 timesteps = too much data
   |
   v
Assumption: Temporal patterns in orbits encode stability/resonance
   |
   v
Method: MiniRocket features -> dimensionality reduction -> clustering
   |
   v
Evidence: Clusters correspond to known stability regions
   |
   v
Conclusion: ML pipeline scales where traditional methods fail
The Increment
One sentence: Before this paper, analyzing thousands of orbital simulations meant running expensive physics calculations on each trajectory individually; after, you can extract features once and let clustering algorithms reveal the structure.
Core Mechanism
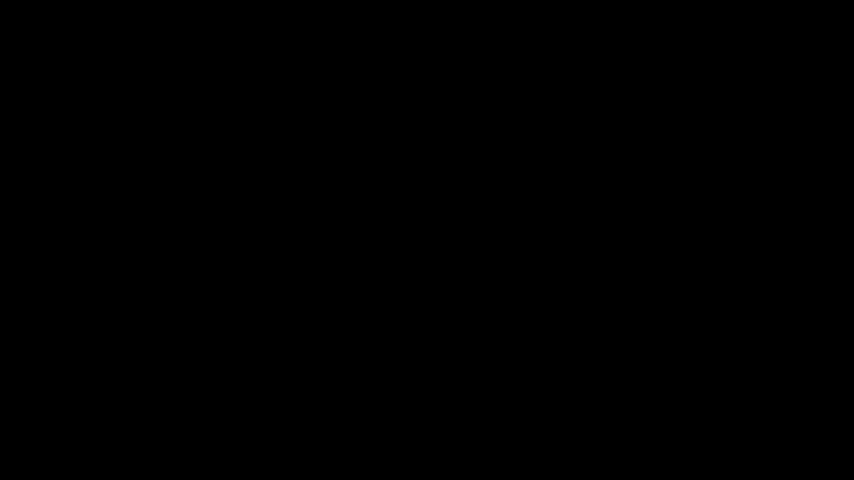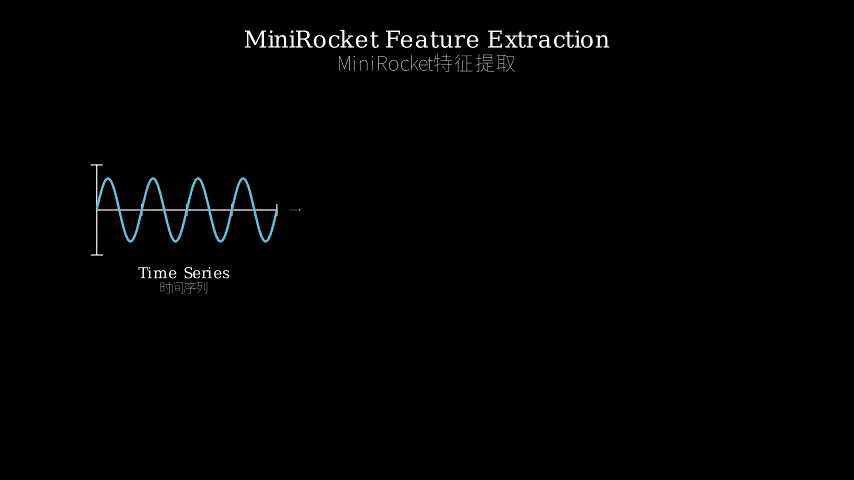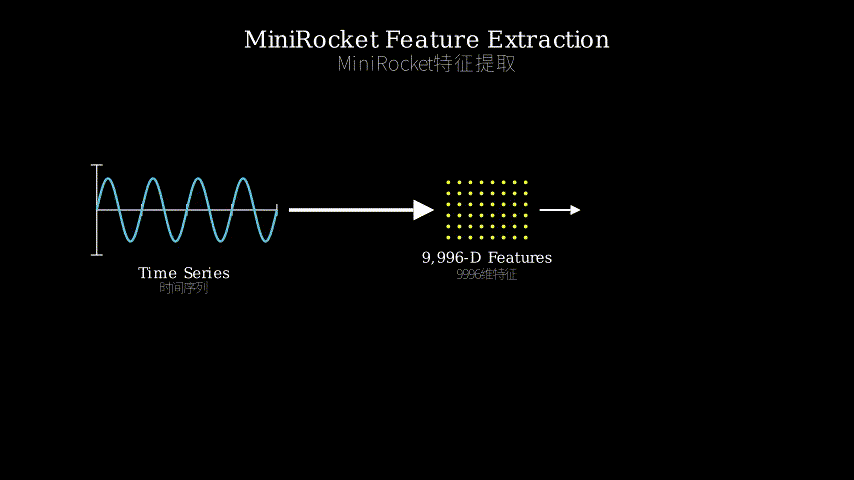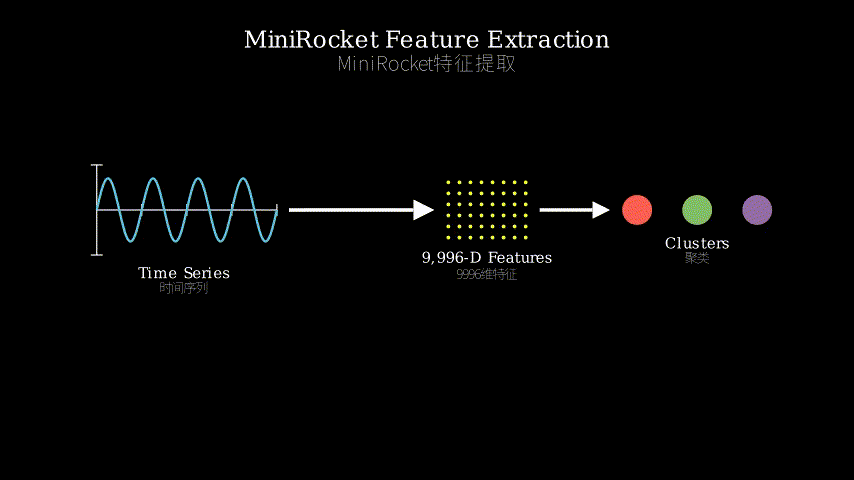
The pipeline has three stages. First, MiniRocket transforms each 400-timestep orbit into a 9,996-dimensional feature vector by convolving the time series with thousands of random kernels and extracting summary statistics. This captures temporal patterns—periodicities, trends, sudden changes—without assuming specific orbital mechanics.
Second, automated feature extraction and dimensionality reduction (the paper mentions techniques but doesn’t specify which) compress the 9,996 dimensions down to something manageable, removing redundancy while preserving the structure that distinguishes stable from chaotic orbits.
Third, clustering algorithms group the reduced features, revealing which orbits behave similarly. The clusters align with known stability regions and resonance structures in Saturn’s satellite system, validating that the features captured physically meaningful dynamics.
Raw orbit data (22,300 x 400 timesteps)
   |
   v
[MiniRocket: convolve with random kernels]
   |
   v
Feature vectors (22,300 x 9,996 dimensions)
   |
   v
[Dimensionality reduction: compress to ~10-100 dims]
   |
   v
Reduced features (22,300 x N dimensions)
   |
   v
[Clustering: group similar orbits]
   |
   v
Orbit clusters (stability regions, resonances)
Think of this like sorting a massive library. Traditional methods are like reading every book cover-to-cover and writing detailed summaries—accurate but impossibly slow. MiniRocket is like speed-reading each book and jotting down 10,000 quick impressions: “lots of dialogue,” “three plot twists,” “melancholy tone,” “circular narrative structure.” Most of these impressions are redundant or irrelevant, so dimensionality reduction is like a librarian who says, “Actually, 95% of what distinguishes books is just genre, length, and emotional arc—let’s focus on those.” Finally, clustering is arranging the books on shelves where similar ones sit together. You never needed to understand every plot detail; the quick impressions were enough to reveal the library’s structure.
Key Concepts
-
MiniRocket (Mini Random Convolutional Kernel Transform): Imagine you want to describe a song without listening to the whole thing. You sample random 3-second clips, and for each clip you note: “Is it loud? Is the pitch rising? Is there a beat?” Do this 10,000 times with different clips and different questions. The song becomes a list of 10,000 yes/no answers. MiniRocket does this for time series: it slides thousands of small random filters across your data, checks if the signal matches each filter, and records the maximum match and other statistics. It’s fast because the filters are random (no training needed) and simple (just checking if values exceed a threshold). For orbits, this captures patterns like “does the eccentricity oscillate with period ~5 timesteps?” without explicitly calculating eccentricity or running Fourier transforms.
-
Dimensionality reduction in this context: You have 9,996 features per orbit, but many are correlated—if one kernel detects a 5-timestep oscillation, nearby kernels probably detect similar oscillations. Dimensionality reduction finds the underlying “axes” that explain most variation. Think of it like describing people: instead of listing height, arm length, leg length, torso length (correlated), you could just say “overall size” and “proportions.” The paper doesn’t specify the technique (PCA? UMAP? t-SNE?), but the goal is compressing 9,996 dimensions to maybe 10-50 while keeping orbits with different dynamics far apart in the reduced space.
Framework Shift
Before (mainstream approach):        After (this paper):

Orbit 1 ---> [Physics calc] ---> Stability metric    Orbit 1 -\
Orbit 2 ---> [Physics calc] ---> Stability metric    Orbit 2 --\
Orbit 3 ---> [Physics calc] ---> Stability metric    Orbit 3 ---+--> [MiniRocket] --> [Reduce] --> [Cluster]
  ...                                ...                ...     /                         |
Orbit N ---> [Physics calc] ---> Stability metric    Orbit N -/                          v
                                                                                    Stability map
     ^                                                     ^
     |                                                     |
Per-orbit analysis                                  Batch feature extraction
(doesn't scale)                                     (scales linearly)
From physics-first to features-first, the core shift is treating orbits as time series patterns rather than solutions to differential equations.
Expert Assessment
Problem choice: Real gap. Orbital dynamics simulations routinely generate datasets too large for traditional analysis, and this isn’t just a Saturn problem—exoplanet systems, asteroid dynamics, and galactic simulations all face the same bottleneck. The authors are addressing a genuine need in computational celestial mechanics.
Method maturity: Mostly assembly of existing tools (MiniRocket is from 2020, clustering is standard), but the application is novel. The insight is recognizing that time series classification techniques can bypass expensive physics calculations. However, the paper is vague about which dimensionality reduction and clustering methods they used—this matters because different choices have different failure modes. Feels like they tried several and reported what worked, which is fine for a proof-of-concept but needs more rigor for a methods paper.
Experimental integrity: The validation is indirect—they show clusters align with known stability regions, which is good, but they don’t compare against a baseline (e.g., clustering on raw Lyapunov exponents or Fourier coefficients). How much better is this than simpler approaches? Also, 22,300 orbits is large for celestial mechanics but small for ML—would this scale to millions of orbits, or does MiniRocket’s feature space become unwieldy?
Writing quality: The abstract oversells (“advanced feature extraction” is just MiniRocket + unspecified reduction). The methods section needs to specify which dimensionality reduction and clustering algorithms were used—this is critical for reproducibility. The results section would benefit from ablation studies: what happens if you skip MiniRocket and cluster on raw data? What if you use fewer kernels?
Verdict: weak accept — Solid application of ML to a real problem in astrophysics, but the paper reads more like “we got this to work” than “here’s a robust methodology.” Needs more experimental rigor and clearer methods description.
Takeaways
If you’re working with large-scale time series data where traditional domain-specific analysis doesn’t scale, steal this pattern: use a fast feature extractor (MiniRocket or similar) to convert temporal patterns into vectors, then apply standard ML clustering. The key insight is that you don’t need to understand the physics to find structure—the temporal patterns encode the physics implicitly.
Specific technique: MiniRocket is worth knowing about. It’s embarrassingly fast (no training, just random convolutions) and works surprisingly well for time series classification. If you’re doing anything with sensor data, financial time series, or sequential measurements, it’s a good first-pass feature extractor.
Warning: The paper doesn’t address interpretability. The clusters reveal structure, but can you explain why a particular orbit ended up in cluster 3? If you need explainability (e.g., for scientific discovery rather than just classification), you’ll need additional tools to map features back to physical parameters.
论文: 2603.13177 作者: Eraldo Pereira Marinho, Nelson Callegari Junior, Fabricio Aparecido Breve, Caetano Mazzoni Ranieri 分类: astro-ph.EP, astro-ph.IM, cs.AI
缺口
天体力学遇到了规模问题。
传统方法像傅里叶分析和李雅普诺夫指数,分析单条轨道或小系统时很漂亮,但面对现代数据集里成千上万条模拟轨道就卡壳了。
当你研究土星卫星系统,有22,300条轨道模拟,每条跨越400个时间步,你需要识别哪些轨道稳定、哪些处于共振、哪些表现出混沌行为。
老工具箱扛不住——傅里叶变换计算量爆炸,人工检查不可能。
此前的方法:给每条轨道算稳定性指标,对轨道要素做傅里叶分析,手动分类行为。
瓶颈在哪:这些方法不会自然地把相似轨道分组,也揭示不了整个数据集的涌现模式。
问题:22,300条轨道 x 400时间步 = 数据太多
   |
   v
假设:轨道的时间模式编码了稳定性/共振信息
   |
   v
方法:MiniRocket特征 -> 降维 -> 聚类
   |
   v
证据:聚类簇对应已知的稳定性区域
   |
   v
结论:机器学习管线在传统方法失效的地方能扩展
增量
一句话:这篇论文之前,分析数千条轨道模拟意味着对每条轨迹单独跑昂贵的物理计算;
之后,你可以提取一次特征,让聚类算法揭示结构。
核心机制
管线分三个阶段。
第一阶段,MiniRocket把每条400时间步的轨道转换成9,996维特征向量,方法是用数千个随机卷积核与时间序列做卷积,提取汇总统计量。
这捕获了时间模式——周期性、趋势、突变——不需要假设具体的轨道力学。
第二阶段,自动特征提取和降维(论文提到了技术但没说具体用哪种)把9,996维压缩到可管理的规模,去掉冗余,同时保留区分稳定轨道和混沌轨道的结构。
第三阶段,聚类算法对降维后的特征分组,揭示哪些轨道行为相似。
聚类簇与土星卫星系统中已知的稳定性区域和共振结构对齐,验证了特征捕获到了物理上有意义的动力学。
原始轨道数据 (22,300 x 400时间步)
   |
   v
[MiniRocket: 与随机卷积核做卷积]
   |
   v
特征向量 (22,300 x 9,996维)
   |
   v
[降维: 压缩到约10-100维]
   |
   v
降维后特征 (22,300 x N维)
   |
   v
[聚类: 把相似轨道分组]
   |
   v
轨道聚类簇 (稳定性区域、共振)
把这想象成整理一个巨大的图书馆。
传统方法像是把每本书从头到尾读一遍,写详细摘要——准确但慢得不可能完成。
MiniRocket像是速读每本书,记下10,000个快速印象:“对话很多”、“三次情节转折”、“忧郁基调”、“循环叙事结构”。
这些印象大多冗余或不相关,所以降维就像图书管理员说:“其实区分书籍的95%信息就是类型、长度和情感基调——咱们就关注这些。”
最后,聚类就是把书摆上书架,相似的放一起。
你从来不需要理解每个情节细节;
快速印象就足以揭示图书馆的结构。
关键概念
- MiniRocket(迷你随机卷积核变换):想象你要描述一首歌但不想听完整首。
你随机采样3秒片段,对每个片段记录:“声音大吗?
音调在上升吗?
有节拍吗?”
用不同片段和不同问题做10,000次。
歌曲就变成了10,000个是/否答案的列表。
MiniRocket对时间序列做同样的事:它用数千个小的随机滤波器滑过你的数据,检查信号是否匹配每个滤波器,记录最大匹配值和其他统计量。
它快是因为滤波器是随机的(不需要训练)且简单(只检查值是否超过阈值)。
对轨道来说,这捕获了像”离心率是否以约5时间步的周期振荡?”
这样的模式,不需要显式计算离心率或跑傅里叶变换。
- 这个语境下的降维:每条轨道有9,996个特征,但很多是相关的——如果一个卷积核检测到5时间步振荡,附近的卷积核可能检测到类似振荡。
降维找到解释大部分变化的底层”轴”。
想象描述人:与其列出身高、臂长、腿长、躯干长(相关的),你可以只说”整体尺寸”和”比例”。
论文没说具体技术(PCA?
UMAP?
t-SNE?
),但目标是把9,996维压缩到也许10-50维,同时让动力学不同的轨道在降维空间里保持距离。
框架转变
之前(主流方法):                之后(本文方法):

轨道1 ---> [物理计算] ---> 稳定性指标    轨道1 -\
轨道2 ---> [物理计算] ---> 稳定性指标    轨道2 --\
轨道3 ---> [物理计算] ---> 稳定性指标    轨道3 ---+--> [MiniRocket] --> [降维] --> [聚类]
  ...                        ...          ...     /                       |
轨道N ---> [物理计算] ---> 稳定性指标    轨道N -/                        v
                                                                    稳定性地图
     ^                                           ^
     |                                           |
逐轨道分析                                    批量特征提取
(不可扩展)                                    (线性扩展)
从物理优先到特征优先,核心转变是把轨道当作时间序列模式而非微分方程的解。
专家评审
选题眼光:真缺口。
轨道动力学模拟常规性地生成太大而无法用传统方法分析的数据集,这不只是土星的问题——系外行星系统、小行星动力学、星系模拟都面临同样的瓶颈。
作者在解决计算天体力学中的真实需求。
方法成熟度:主要是组装现有工具(MiniRocket来自2020年,聚类是标准方法),但应用是新颖的。
洞见在于认识到时间序列分类技术可以绕过昂贵的物理计算。
但论文对用了哪种降维和聚类方法很含糊——这很重要,因为不同选择有不同的失效模式。
感觉他们试了几种,报告了有效的,这对概念验证可以,但作为方法论文需要更严谨。
实验诚意:验证是间接的——他们展示聚类簇与已知稳定性区域对齐,这不错,但没有与基线比较(比如对原始李雅普诺夫指数或傅里叶系数聚类)。
这比更简单的方法好多少?
另外,22,300条轨道对天体力学来说很大,但对机器学习来说很小——这能扩展到百万条轨道吗,还是MiniRocket的特征空间会变得笨重?
写作功力:摘要过度推销(“先进的特征提取”就是MiniRocket加未指明的降维)。
方法部分需要说明用了哪种降维和聚类算法——这对可重复性至关重要。
结果部分需要消融研究:如果跳过MiniRocket直接对原始数据聚类会怎样?
如果用更少的卷积核呢?
判决:弱接收——把机器学习扎实地应用到天体物理学的真实问题,但论文读起来更像”我们让它工作了”而非”这是一套稳健的方法论”。
需要更多实验严谨性和更清晰的方法描述。
要点总结
如果你在处理大规模时间序列数据,传统的领域特定分析不可扩展,偷这个模式:用快速特征提取器(MiniRocket或类似工具)把时间模式转换成向量,然后应用标准机器学习聚类。
关键洞见是你不需要理解物理就能找到结构——时间模式隐式地编码了物理。
具体技术:MiniRocket值得了解。
它快得离谱(不需要训练,只是随机卷积)且对时间序列分类效果出奇地好。
如果你在做传感器数据、金融时间序列或序列测量相关的任何事,它是很好的首选特征提取器。
警告:论文没解决可解释性。
聚类揭示了结构,但你能解释为什么某条特定轨道落在聚类簇3吗?
如果你需要可解释性(比如为了科学发现而非只是分类),你需要额外工具把特征映射回物理参数。