Paper: 2604.01210 Authors: Youssef Mroueh, Carlos Fonseca, Brian Belgodere, David Cox Categories: cs.LG, cs.AI
The Gap
Current LLM-guided algorithm discovery systems (like FunSearch, EoH) treat algorithms as pure code artifacts optimized solely for benchmark metrics. They lack scientific structure: no explicit theory representation, weak correctness validation, and no originality filtering. The result? High-throughput candidate generation that often produces uninterpretable or incorrect solutions that happen to score well.
The paper identifies three specific shortcomings: (1) code-only representation loses the “why” behind algorithmic choices, (2) optimization pressure alone doesn’t guarantee correctness or novelty, (3) mutation operators don’t distinguish between exploration (finding new ideas) and correction (fixing broken ones).
Problem: Code-only algorithm search
    |
    v
Assumption: Scientific discovery needs structure
    |
    +---> Theory + Code dual representation
    +---> Reviewer agents as correctness gates
    +---> Split mutation: explore vs correct
    |
    v
Method: CliffSearch (agentic co-evolution)
    |
    v
Evidence: 3 benchmarks (transformer, optimizer, ablation)
    |
    v
Conclusion: Structured artifacts + reviewer gating
               yields interpretable, correct discoveries
The Increment
One sentence: Before CliffSearch, LLM-guided algorithm search optimized code for metrics; after, it co-evolves theory and code under correctness and originality constraints.
Core Mechanism
CliffSearch implements evolutionary search where every component is an LLM agent. The population consists of “nodes” — each node is either a theory+code pair or code-only. Evolution proceeds through four agent-driven operators:
Pair selection picks two parent nodes based on fitness (benchmark score), correctness (reviewer judgment), and originality (novelty relative to population). Crossover merges ideas from both parents, creating a child that inherits concepts from each. Mutation comes in two flavors: exploration mutation imports ideas from adjacent scientific domains (e.g., bringing attention mechanisms into optimizer design), while correction mutation performs targeted repair using reviewer feedback on theory inconsistencies, code bugs, or runtime errors. Review agents evaluate each node on correctness and originality before it enters the population.
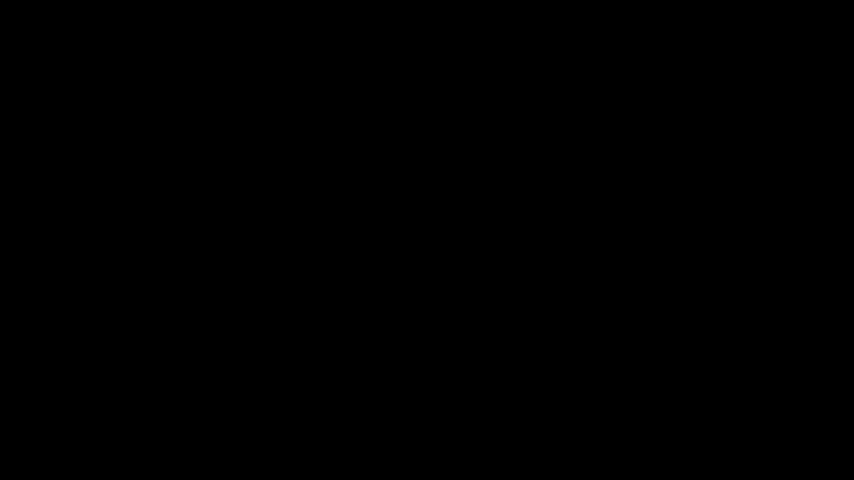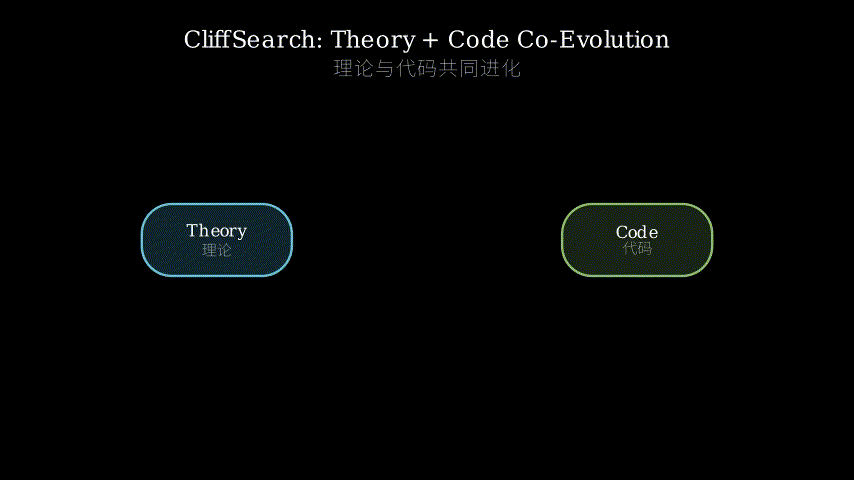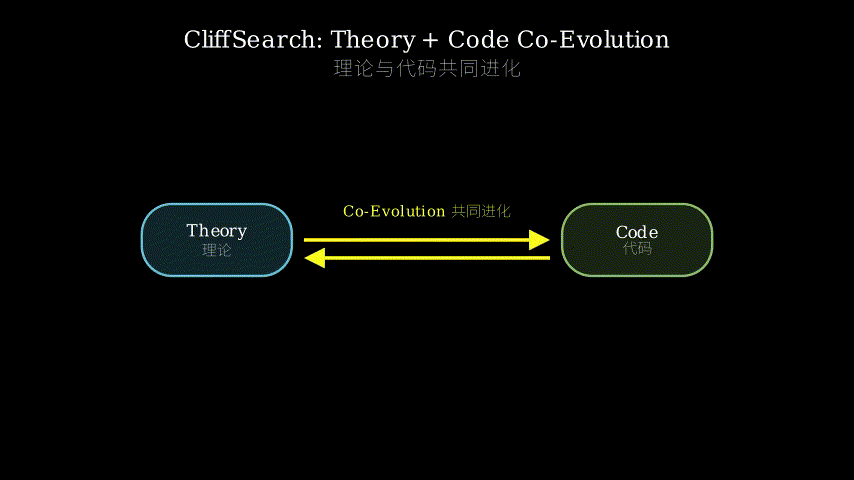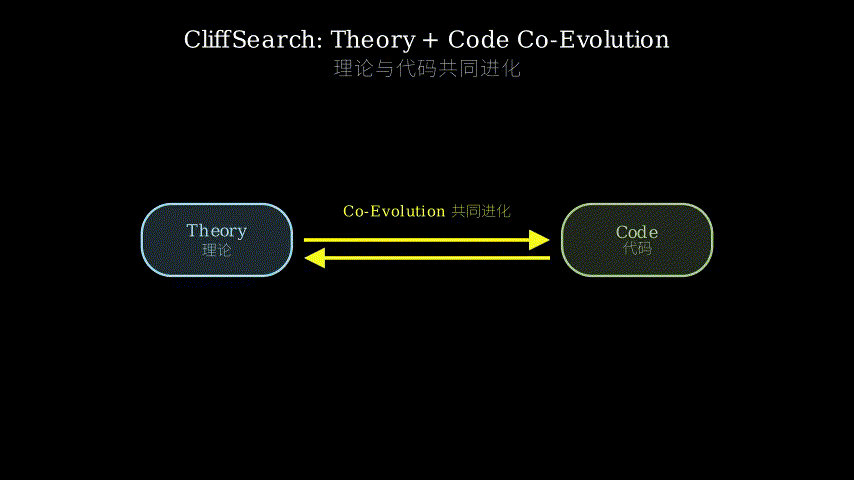
The key architectural choice: theory and code are separate but linked. Theory describes the algorithmic intuition in natural language; code implements it. Reviewers check both for consistency. When theory and code diverge, correction mutation uses the theory as a specification to fix the code, or updates the theory to match working code.
Population of Nodes
[Theory+Code] [Code-only] [Theory+Code] ...
      |            |            |
      v            v            v
  +-----------------------------------+
  |  Pair Selection (fitness+review)  |
  +-----------------------------------+
            |              |
            v              v
        Parent A      Parent B
            |              |
            +------+-------+
                   |
                   v
            +-------------+
            |  Crossover  |  <-- merge ideas
            +-------------+
                   |
                   v
              Child Node
                   |
        +----------+----------+
        |                     |
        v                     v
  Exploration Mut.      Correction Mut.
  (import ideas)        (fix errors)
        |                     |
        +----------+----------+
                   |
                   v
            +-------------+
            |   Review    |  <-- correctness + originality
            +-------------+
                   |
                   v
          Add to Population (if passes)
Think of CliffSearch as a scientific lab with rotating postdocs. Each node is a research proposal: some have detailed theory sections (the “why”), others are just working prototypes (the “what”). The lab director (pair selection) picks two promising proposals to combine. A senior researcher (crossover) merges their ideas into a new proposal. Then two things happen: an explorer (exploration mutation) goes to the library and brings back ideas from other fields, while a debugger (correction mutation) runs experiments and fixes what’s broken. Finally, a review committee (review agents) decides if the proposal is correct and novel enough to stay in the lab. The theory+code structure is like requiring proposals to have both a hypothesis section and an experimental protocol — you can’t just submit code and hope it works.
Key Concepts
-
Theory+Code Dual Representation: Instead of treating algorithms as pure code, CliffSearch represents them as a pair: natural language theory (the intuition, the “why this should work”) and executable code (the implementation). This isn’t just documentation — the theory is a first-class artifact that reviewers check for consistency with the code. When they diverge, correction mutation uses theory as a specification to repair code, or updates theory to match working implementations. Think of it like a recipe (theory) and the actual dish (code): if the dish doesn’t match the recipe, you either fix the cooking or rewrite the recipe, but you keep both in sync.
-
Reviewer-Gated Selection: Most evolutionary algorithms select based purely on fitness (does it score well?). CliffSearch adds two more gates: correctness (does it actually work as intended?) and originality (is it different from what we already have?). LLM agents act as reviewers, reading the theory, inspecting the code, checking benchmark results, and examining runtime errors. Only nodes that pass reviewer judgment enter the population. This is like peer review in science: a paper might have impressive results, but if the methodology is flawed or it’s just a minor tweak of existing work, it gets rejected.
-
Split Mutation Pathways: Traditional mutation randomly tweaks code. CliffSearch splits mutation into two operators with different goals. Exploration mutation deliberately imports ideas from adjacent domains (e.g., “what if we applied attention mechanisms to optimizer design?”) to increase novelty. Correction mutation performs targeted repair: it takes reviewer feedback about what’s wrong (theory-code mismatch, runtime error, failed test) and fixes that specific issue. It’s like having two editors: one who suggests bold new directions, and another who fixes typos and logical errors. You need both, but for different reasons.
Framework Shift
Before (code-only search):          After (CliffSearch):

  Generate Code                       Generate Theory+Code
       |                                   /        \
       v                              Theory      Code
  Benchmark Score                        |          |
       |                                 v          v
       v                            Review (correctness
  Select Best                         + originality)
       |                                   |
       v                                   v
  Mutate Randomly                    Select Reviewed
       |                                   |
       +---> repeat                   +----+----+
                                      |         |
                                 Explore    Correct
                                 (import)   (repair)
                                      |         |
                                      +----+----+
                                           |
                                           v
                                      Review Again
                                           |
                                           +---> repeat
One sentence: From blind code optimization to structured co-evolution of theory and implementation under scientific review.
Expert Assessment
Problem choice: Real gap. Existing LLM-guided search systems (FunSearch, EoH) do produce uninterpretable or incorrect solutions that score well on benchmarks. The field has been moving fast on throughput but slow on interpretability and correctness. This paper addresses a genuine need for structure in automated discovery.
Method maturity: Clever architectural choices (theory+code duality, split mutation) but heavy on LLM agent orchestration. The framework is complex — four agent types, dual representation modes, multiple review stages. There’s a simpler baseline being overlooked: what if you just added a post-hoc verification step to existing code-only search? The paper doesn’t compare against “code-only + verification” to isolate the value of theory representation during evolution vs after.
Experimental integrity: Three studies (transformer hyper-connections, optimizer discovery, ablation) show the framework works, but the baselines are weak. They compare against random search and prior work (EoH), but not against “code-only CliffSearch” (same framework, no theory). The ablation study is small (native optimizer only). Benchmark results are promising but not definitive — the discovered optimizers improve over baselines, but we don’t see head-to-head comparisons with human-designed SOTA on large-scale tasks.
Writing quality: The paper front-loads framework description and under-explains the evolutionary dynamics. Section 3 (method) is dense with agent specifications but light on intuition. The case studies (Section 4) are better but arrive late. If they rewrote Section 3 to lead with a concrete example (e.g., “here’s how one node evolves through the loop”) before the formal specification, the whole paper would click faster.
Verdict: Weak accept — the structured artifact idea is valuable and the reviewer-gating mechanism is a genuine contribution, but the experimental validation needs stronger baselines and the complexity cost isn’t fully justified.
Takeaways
Dual representation for interpretability: If you’re building LLM-guided search for any domain (not just algorithms), consider maintaining both a natural language “theory” and an executable artifact. The theory acts as a specification that reviewers (human or LLM) can check for consistency. This is directly applicable to automated theorem proving, drug discovery (hypothesis + molecule), or infrastructure-as-code generation (intent + config).
Split mutation by objective: Don’t use one mutation operator for everything. Separate exploration (deliberately import ideas from other domains to increase novelty) from correction (targeted repair based on specific failure signals). This applies to any evolutionary or iterative refinement system.
Reviewer agents as selection gates: Instead of selecting purely on task metrics, add LLM agents that evaluate correctness and originality. This is a practical pattern for any automated discovery system where you care about solution quality beyond benchmark scores.
Concrete technique: The “correction mutation with evidence” pattern is immediately usable — when an LLM-generated artifact fails, don’t just retry; pass the error message, the theory, and the code to a specialized correction agent that performs targeted repair. This beats naive retry loops.
论文: 2604.01210 作者: Youssef Mroueh, Carlos Fonseca, Brian Belgodere, David Cox 分类: cs.LG, cs.AI
缺口
当前的LLM引导算法发现系统(如FunSearch、EoH)把算法当作纯代码制品,只针对基准指标优化。
它们缺乏科学结构:没有显式的理论表示,正确性验证薄弱,也没有原创性过滤。
结果是什么?高吞吐量的候选生成,但经常产生不可解释或不正确的解决方案,只是碰巧在基准上得分高。
论文指出三个具体不足:(1)纯代码表示丢失了算法选择背后的”为什么”,(2)单纯的优化压力不能保证正确性或新颖性,(3)变异算子不区分探索(寻找新想法)和修正(修复错误)。
问题:纯代码算法搜索
    |
    v
假设:科学发现需要结构
    |
    +---> 理论+代码双重表示
    +---> 评审智能体作为正确性门槛
    +---> 分裂变异:探索 vs 修正
    |
    v
方法:CliffSearch(智能体共同进化)
    |
    v
证据:3个基准(transformer、优化器、消融)
    |
    v
结论:结构化制品+评审门槛
      产生可解释、正确的发现
增量
一句话: CliffSearch之前,LLM引导的算法搜索为指标优化代码;之后,它在正确性和原创性约束下共同进化理论和代码。
核心机制
CliffSearch实现进化搜索,其中每个组件都是LLM智能体。
种群由”节点”组成——每个节点要么是理论+代码对,要么是纯代码。
进化通过四个智能体驱动的算子进行:
配对选择根据适应度(基准分数)、正确性(评审判断)和原创性(相对种群的新颖性)挑选两个父节点。
交叉合并两个父节点的想法,创建一个继承各自概念的子节点。
变异有两种形式:探索变异从相邻科学领域导入想法(例如,将注意力机制引入优化器设计),而修正变异使用评审反馈对理论不一致、代码错误或运行时错误进行针对性修复。
评审智能体在每个节点进入种群前评估其正确性和原创性。
关键架构选择:理论和代码是分离但关联的。
理论用自然语言描述算法直觉;代码实现它。
评审者检查两者的一致性。
当理论和代码分歧时,修正变异使用理论作为规范来修复代码,或更新理论以匹配工作代码。
节点种群
[理论+代码] [纯代码] [理论+代码] ...
      |            |            |
      v            v            v
  +-----------------------------------+
  |  配对选择(适应度+评审)              |
  +-----------------------------------+
            |              |
            v              v
        父节点A        父节点B
            |              |
            +------+-------+
                   |
                   v
            +-------------+
            |    交叉     |  <-- 合并想法
            +-------------+
                   |
                   v
              子节点
                   |
        +----------+----------+
        |                     |
        v                     v
  探索变异              修正变异
  (导入想法)            (修复错误)
        |                     |
        +----------+----------+
                   |
                   v
            +-------------+
            |    评审     |  <-- 正确性+原创性
            +-------------+
                   |
                   v
          加入种群(如果通过)
把CliffSearch想象成一个有轮换博士后的科学实验室。
每个节点是一个研究提案:有些有详细的理论部分(“为什么”),其他只是工作原型(“是什么”)。
实验室主任(配对选择)挑选两个有前途的提案组合。
资深研究员(交叉)将它们的想法合并成新提案。
然后发生两件事:探索者(探索变异)去图书馆从其他领域带回想法,而调试者(修正变异)运行实验并修复损坏的部分。
最后,评审委员会(评审智能体)决定提案是否足够正确和新颖以留在实验室。
理论+代码结构就像要求提案既有假设部分又有实验协议——你不能只提交代码并希望它能工作。
关键概念
- 理论+代码双重表示: CliffSearch不把算法当作纯代码,而是表示为一对:自然语言理论(直觉,“为什么这应该有效”)和可执行代码(实现)。
这不只是文档——理论是评审者检查与代码一致性的一等制品。
当它们分歧时,修正变异使用理论作为规范修复代码,或更新理论以匹配工作实现。
想象成食谱(理论)和实际菜肴(代码):如果菜肴不匹配食谱,你要么修正烹饪要么重写食谱,但你保持两者同步。
- 评审门槛选择: 大多数进化算法纯粹基于适应度选择(得分高吗?)。
CliffSearch增加两个门槛:正确性(它真的按预期工作吗?)和原创性(它与我们已有的不同吗?)。
LLM智能体充当评审者,阅读理论、检查代码、查看基准结果、检查运行时错误。
只有通过评审判断的节点才进入种群。
这就像科学中的同行评审:一篇论文可能有令人印象深刻的结果,但如果方法有缺陷或只是现有工作的小调整,它会被拒绝。
- 分裂变异路径: 传统变异随机调整代码。
CliffSearch将变异分成两个具有不同目标的算子。
探索变异故意从相邻领域导入想法(例如,“如果我们将注意力机制应用于优化器设计会怎样?”)以增加新颖性。
修正变异执行针对性修复:它接受关于什么错误的评审反馈(理论-代码不匹配、运行时错误、测试失败)并修复那个特定问题。
这就像有两个编辑:一个建议大胆的新方向,另一个修复拼写错误和逻辑错误。
你需要两者,但出于不同原因。
框架转变
之前(纯代码搜索):              之后(CliffSearch):

  生成代码                       生成理论+代码
       |                              /        \
       v                         理论          代码
  基准分数                           |          |
       |                             v          v
       v                        评审(正确性
  选择最佳                        +原创性)
       |                             |
       v                             v
  随机变异                      选择已评审
       |                             |
       +---> 重复                +----+----+
                                |         |
                            探索        修正
                            (导入)      (修复)
                                |         |
                                +----+----+
                                     |
                                     v
                                再次评审
                                     |
                                     +---> 重复
一句话: 从盲目代码优化到科学评审下理论与实现的结构化共同进化。
专家评审
选题眼光: 真实缺口。
现有LLM引导搜索系统(FunSearch、EoH)确实产生在基准上得分高但不可解释或不正确的解决方案。
该领域在吞吐量上进展快,但在可解释性和正确性上进展慢。
这篇论文解决了自动发现中对结构的真实需求。
方法成熟度: 巧妙的架构选择(理论+代码二元性、分裂变异),但严重依赖LLM智能体编排。
框架复杂——四种智能体类型、双重表示模式、多个评审阶段。
有一个被忽略的更简单基线:如果只是在现有纯代码搜索中添加事后验证步骤会怎样?论文没有与”纯代码+验证”比较,以隔离进化期间理论表示的价值vs之后。
实验诚意: 三个研究(transformer超连接、优化器发现、消融)显示框架有效,但基线薄弱。
它们与随机搜索和先前工作(EoH)比较,但不与”纯代码CliffSearch”(相同框架,无理论)比较。
消融研究很小(仅原生优化器)。
基准结果有希望但不确定——发现的优化器改进了基线,但我们没有看到与人类设计的SOTA在大规模任务上的正面比较。
写作功力: 论文前置框架描述,对进化动力学解释不足。
第3节(方法)充满智能体规范但缺乏直觉。
案例研究(第4节)更好但来得晚。
如果他们重写第3节,在正式规范前用具体例子引导(例如,“这是一个节点如何通过循环进化的”),整篇论文会更快点击。
判决: 弱接收——结构化制品想法有价值,评审门槛机制是真正贡献,但实验验证需要更强基线,复杂性成本没有完全证明。
要点总结
可解释性的双重表示: 如果你在为任何领域(不仅是算法)构建LLM引导搜索,考虑同时维护自然语言”理论”和可执行制品。
理论充当评审者(人类或LLM)可以检查一致性的规范。
这直接适用于自动定理证明、药物发现(假设+分子)或基础设施即代码生成(意图+配置)。
按目标分裂变异: 不要对所有事情使用一个变异算子。
分离探索(故意从其他领域导入想法以增加新颖性)和修正(基于特定失败信号的针对性修复)。
这适用于任何进化或迭代细化系统。
评审智能体作为选择门槛: 不要纯粹基于任务指标选择,添加评估正确性和原创性的LLM智能体。
这是任何关心解决方案质量超越基准分数的自动发现系统的实用模式。
具体技术: “带证据的修正变异”模式可立即使用——当LLM生成的制品失败时,不要只是重试;将错误消息、理论和代码传递给执行针对性修复的专门修正智能体。
这胜过天真的重试循环。