Paper: 2604.11784 Authors: Fei Tang, Zhiqiong Lu, Boxuan Zhang, Weiming Lu, Jun Xiao, Yueting Zhuang, Yongliang Shen Categories: cs.LG, cs.AI, cs.CL, cs.CV
The Gap
GUI agents promise to control any application through visual interfaces—tapping, swiping, typing like humans do. Unlike CLI agents that need APIs, they can reach the long tail of software that never exposes programmatic hooks. The modeling capacity exists (vision-language models can see and reason), but three infrastructure gaps block progress:
- Training instability: Existing RL pipelines for GUI agents are closed-source, fragile, and can’t scale across virtual environments or real devices
- Evaluation chaos: Each paper uses different benchmarks with different protocols, making reproduction rates hover around 60-70%
- Deployment void: Trained agents stay in research repos; no path exists to put them on actual phones where users live
Prior work (AppAgent, CogAgent, AutoDroid) focuses on model architecture while assuming infrastructure exists. It doesn’t. The result: impressive demos that can’t be reproduced, trained, or shipped.
Problem: GUI agents stuck in research
   |
   v
Assumption: Infrastructure gap > modeling gap
   |
   +---> Method: ClawGUI (3-part framework)
   |        |
   |        +---> ClawGUI-RL: Stable training (virtual + physical)
   |        +---> ClawGUI-Eval: Standardized benchmarks
   |        +---> ClawGUI-Agent: Real device deployment
   |
   v
Evidence: 95.8% reproduction rate, 17.1% success on MobileWorld
   |
   v
Conclusion: Infrastructure unblocks progress (6% gain over baseline)
The Increment
One sentence: Before this paper, GUI agent research was a collection of incompatible experiments; after, there’s a single open pipeline from training to deployment that anyone can reproduce and extend.
Core Mechanism
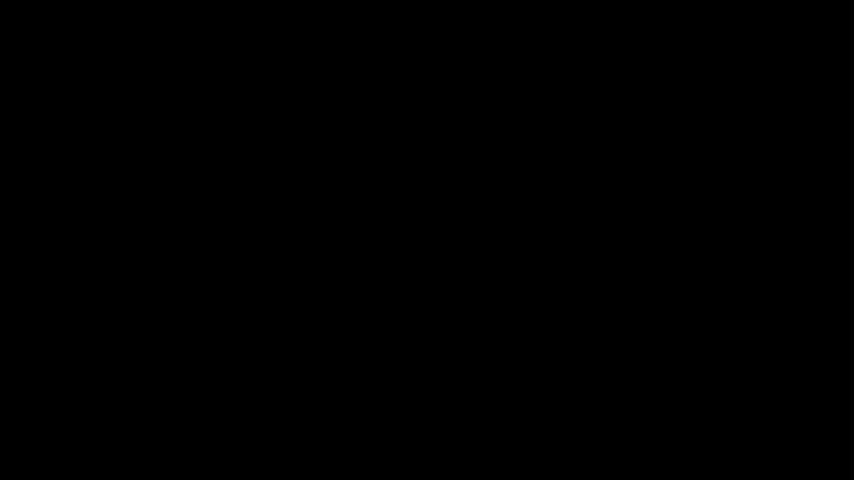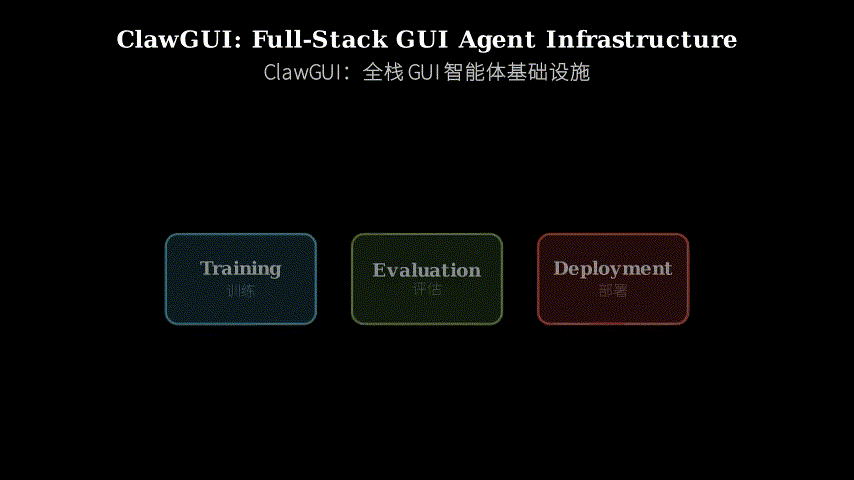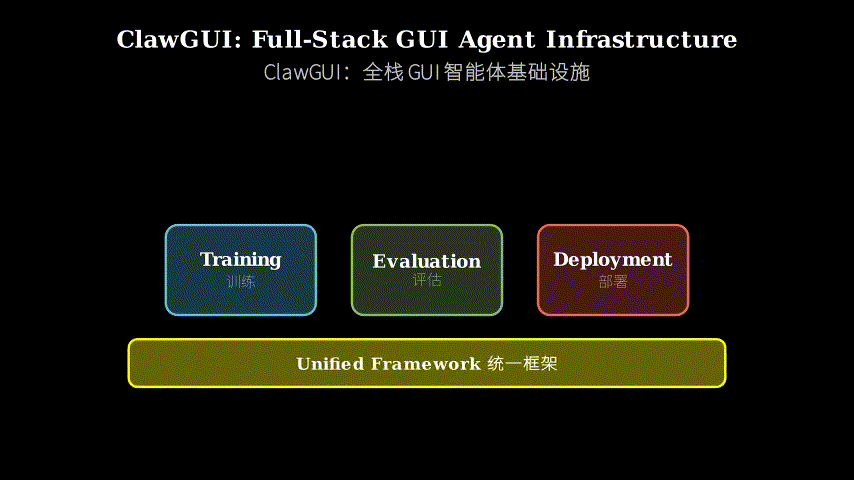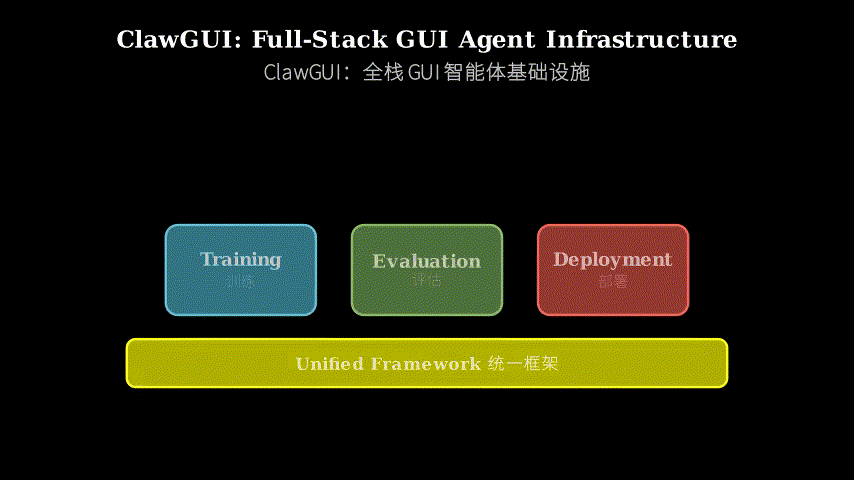
ClawGUI is a three-layer stack. At the bottom, ClawGUI-RL handles training. It wraps Android emulators and physical devices into a unified interface, so RL algorithms don’t care whether they’re talking to a virtual Pixel or a real iPhone. The training loop uses GiGPO (a policy gradient method) augmented with a Process Reward Model that scores each step, not just final outcomes—this gives dense feedback when tasks take 20+ steps.
The middle layer, ClawGUI-Eval, is a test harness. It locks down 6 benchmarks (AndroidWorld, MobileWorld, etc.) with fixed evaluation protocols: same prompts, same success criteria, same retry logic. The authors ran 11 existing models through this pipeline and hit 95.8% match against published numbers, proving the protocols are faithful.
The top layer, ClawGUI-Agent, is deployment infrastructure. It packages trained models into apps that run on Android, HarmonyOS, and iOS. Users chat with the agent through WeChat, Telegram, or 10 other platforms. The agent can execute GUI actions (tap this button) or fall back to CLI commands (adb shell) when needed. It maintains a memory graph of user preferences across sessions.
User (WeChat/Telegram/etc.)
   |
   v
ClawGUI-Agent (deployment layer)
   |
   +---> Memory: User preferences, past actions
   |
   +---> Executor: GUI (tap/swipe) + CLI (adb/shell)
   |
   v
Physical Device (Android/iOS/HarmonyOS)
   ^
   |
ClawGUI-Eval (test harness)
   |
   +---> 6 benchmarks, fixed protocols
   |
   v
ClawGUI-RL (training layer)
   |
   +---> GiGPO + Process Reward Model
   |
   +---> Parallel envs: Virtual (emulators) + Physical (real phones)
Think of ClawGUI as a restaurant kitchen. ClawGUI-RL is the cooking school where chefs (agents) learn recipes (policies) by practicing on training stations (virtual environments) and occasionally real stoves (physical devices). The Process Reward Model is the head chef tasting each step, not just the final dish. ClawGUI-Eval is the health inspector with a standardized checklist—same criteria for every kitchen, so you can compare restaurants fairly. ClawGUI-Agent is the delivery service that brings the food (trained agent) to customers’ homes (real devices via chat apps), remembering dietary preferences (personalized memory) and handling both plated meals (GUI actions) and ingredient drops (CLI commands).
Key Concepts
-
Process Reward Model (PRM): Most RL for GUI agents uses sparse rewards—you only get feedback when the task succeeds or fails at the end. If a task takes 30 steps and fails, the agent doesn’t know which of those 30 steps was wrong. A PRM scores every intermediate step. Imagine teaching someone to bake: instead of saying “the cake is bad” after an hour, you say “good job preheating the oven” (step 1), “you added too much sugar” (step 5), “perfect mixing technique” (step 8). The agent learns faster because it knows what to repeat and what to avoid at each decision point. ClawGUI’s PRM is trained on human annotations of step quality, then used to shape rewards during RL training.
-
Hybrid CLI-GUI Control: GUI agents interact through visual interfaces (tap, swipe), but sometimes that’s inefficient or impossible. Example: installing an app requires navigating app stores, agreeing to permissions, waiting for downloads—10+ GUI steps. With CLI access (adb install app.apk), it’s one command. ClawGUI-Agent decides per-action whether to use GUI (when visual context matters) or CLI (when direct system calls are faster). It’s like having both a steering wheel and autopilot—use the right tool for each situation.
-
Standardized Evaluation Protocol: Different papers test GUI agents differently: some allow retries, some don’t; some use GPT-4 to judge success, some use exact string matching; some reset the environment between tasks, some don’t. This makes comparing results meaningless. ClawGUI-Eval fixes every variable: task prompts are identical, success criteria are deterministic (no LLM judges), environments reset to the same state, retry logic is consistent. It’s like switching from “run a mile however you want” to “run a mile on this track, starting from this line, timed with this stopwatch.” Now times are comparable.
Framework Shift
Before (mainstream approach):        After (ClawGUI):

Research paper                       Research paper
   |                                    |
   v                                    v
Custom training code                 ClawGUI-RL (shared)
   |                                    |
   +---> Closed pipeline                +---> Open pipeline
   +---> Virtual envs only              +---> Virtual + Physical
   |                                    |
   v                                    v
Custom eval script                   ClawGUI-Eval (shared)
   |                                    |
   +---> Different benchmarks           +---> 6 standardized benchmarks
   +---> ~60% reproduction              +---> 95.8% reproduction
   |                                    |
   v                                    v
Demo video                           ClawGUI-Agent (shared)
   |                                    |
   +---> No deployment path             +---> 12+ chat platforms
   +---> Stays in repo                  +---> Runs on real devices
From fragmented research artifacts to a unified production pipeline, the core shift is infrastructure as a first-class research contribution.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The field has dozens of GUI agent papers with impressive claims but near-zero reproducibility. The authors correctly diagnose that the bottleneck isn’t model architecture—it’s the missing scaffolding around training, evaluation, and deployment. This is unglamorous work (building test harnesses isn’t sexy), but it’s exactly what the field needs to move from demos to systems.
Method maturity: The approach is pragmatic engineering, not algorithmic novelty. GiGPO is borrowed, the PRM is standard, the evaluation protocols are just careful bookkeeping. But that’s the point—this paper isn’t claiming a new RL algorithm; it’s claiming that infrastructure matters more than the next model tweak. The 6% improvement over MAI-UI-2B comes from better training infrastructure, not a smarter architecture. That’s a credible claim given the evidence.
Experimental integrity: The 95.8% reproduction rate is the paper’s strongest card. They ran 11 existing models through their pipeline and matched published results within 5%. That’s rare in ML and suggests the evaluation protocols are faithful. The MobileWorld results (17.1% success) are modest but honest—they’re not cherry-picking easy tasks. One concern: the paper doesn’t report variance across runs or seeds, so we don’t know if that 6% gain is statistically significant. Also, the PRM training data (human annotations) isn’t released, which limits reproducibility of that component.
Writing quality: The paper front-loads the infrastructure story well, but the technical sections (especially ClawGUI-RL) are dense and assume familiarity with RL terminology. The deployment section (ClawGUI-Agent) feels rushed—12 chat platforms are mentioned but not explained. How does memory persistence work across platforms? What’s the latency on real devices? These details matter for practitioners but are glossed over. Rewriting Section 4 (ClawGUI-Agent) with concrete examples and performance numbers would elevate the whole paper.
Verdict: Weak accept — This is infrastructure work the field needs, with strong reproducibility evidence, but the technical contribution is incremental and the writing could be tighter. It’s more valuable as an artifact (the open-source framework) than as a paper.
Takeaways
For practitioners building agents: Steal the Process Reward Model idea. If your agent takes multi-step actions, don’t wait until the end to give feedback—score intermediate steps. You don’t need fancy human annotations; even a simple heuristic (did this step move closer to the goal?) helps. The authors show a 6% gain just from denser rewards.
For researchers: The standardized evaluation protocol is the real contribution. If you’re working on GUI agents (or any embodied AI), adopt ClawGUI-Eval’s approach: lock down every variable, make success criteria deterministic, publish exact prompts and retry logic. Reproducibility isn’t a nice-to-have; it’s the difference between science and storytelling.
For deployment: The hybrid CLI-GUI control pattern transfers beyond GUI agents. Anytime you’re building an agent that interacts with a system, give it multiple interfaces—high-level (GUI/API) for common cases, low-level (CLI/system calls) for edge cases. The agent learns when to use which, and you get both flexibility and efficiency.
论文: 2604.11784 作者: Fei Tang, Zhiqiong Lu, Boxuan Zhang, Weiming Lu, Jun Xiao, Yueting Zhuang, Yongliang Shen 分类: cs.LG, cs.AI, cs.CL, cs.CV
缺口
GUI 智能体承诺通过视觉界面控制任意应用——像人类一样点击、滑动、输入。
与需要 API 的 CLI 智能体不同,它们能触及那些从不暴露编程接口的长尾软件。
建模能力已经具备(视觉-语言模型能看能推理),但三个基础设施缺口阻碍了进展:
- 训练不稳定:现有的 GUI 智能体强化学习管道是闭源的、脆弱的,无法在虚拟环境或真实设备上扩展
- 评估混乱:每篇论文使用不同的基准和不同的协议,复现率徘徊在 60-70%
- 部署空白:训练好的智能体停留在研究代码库中;没有路径将它们部署到用户实际使用的手机上
先前工作(AppAgent、CogAgent、AutoDroid)专注于模型架构,假设基础设施已经存在。
但它不存在。
结果是:令人印象深刻的演示无法复现、训练或交付。
问题:GUI 智能体困在研究阶段
   |
   v
假设:基础设施缺口 > 建模缺口
   |
   +---> 方法:ClawGUI(三部分框架)
   |        |
   |        +---> ClawGUI-RL:稳定训练(虚拟+物理)
   |        +---> ClawGUI-Eval:标准化基准
   |        +---> ClawGUI-Agent:真实设备部署
   |
   v
证据:95.8% 复现率,MobileWorld 上 17.1% 成功率
   |
   v
结论:基础设施解锁进展(比基线高 6%)
增量
一句话:这篇论文之前,GUI 智能体研究是一堆互不兼容的实验;之后,有了一条从训练到部署的单一开放管道,任何人都能复现和扩展。
核心机制
ClawGUI 是一个三层堆栈。
底层是 ClawGUI-RL,负责训练。
它将 Android 模拟器和物理设备包装成统一接口,所以强化学习算法不关心它们在跟虚拟 Pixel 还是真实 iPhone 对话。
训练循环使用 GiGPO(一种策略梯度方法),增强了过程奖励模型,该模型对每一步打分,而不仅仅是最终结果——当任务需要 20 多步时,这提供了密集反馈。
中间层是 ClawGUI-Eval,一个测试工具。
它锁定 6 个基准(AndroidWorld、MobileWorld 等),使用固定的评估协议:相同的提示、相同的成功标准、相同的重试逻辑。
作者通过这个管道运行了 11 个现有模型,与已发表数字的匹配度达到 95.8%,证明协议是忠实的。
顶层是 ClawGUI-Agent,部署基础设施。
它将训练好的模型打包成在 Android、HarmonyOS 和 iOS 上运行的应用。
用户通过微信、Telegram 或其他 10 个平台与智能体聊天。
智能体可以执行 GUI 操作(点击这个按钮)或在需要时回退到 CLI 命令(adb shell)。
它维护一个跨会话的用户偏好记忆图。
用户(微信/Telegram/等)
   |
   v
ClawGUI-Agent(部署层)
   |
   +---> 记忆:用户偏好、过去操作
   |
   +---> 执行器:GUI(点击/滑动)+ CLI(adb/shell)
   |
   v
物理设备(Android/iOS/HarmonyOS)
   ^
   |
ClawGUI-Eval(测试工具)
   |
   +---> 6 个基准,固定协议
   |
   v
ClawGUI-RL(训练层)
   |
   +---> GiGPO + 过程奖励模型
   |
   +---> 并行环境:虚拟(模拟器)+ 物理(真实手机)
把 ClawGUI 想象成一个餐厅厨房。
ClawGUI-RL 是烹饪学校,厨师(智能体)在训练站(虚拟环境)上学习食谱(策略),偶尔在真实炉灶(物理设备)上练习。
过程奖励模型是主厨品尝每一步,而不仅仅是最终菜品。
ClawGUI-Eval 是卫生检查员,拿着标准化清单——对每个厨房使用相同标准,所以你可以公平地比较餐厅。
ClawGUI-Agent 是外卖服务,将食物(训练好的智能体)送到顾客家中(通过聊天应用到真实设备),记住饮食偏好(个性化记忆),处理装盘餐食(GUI 操作)和食材配送(CLI 命令)。
关键概念
- 过程奖励模型(PRM):大多数 GUI 智能体的强化学习使用稀疏奖励——只有在任务最后成功或失败时才得到反馈。
如果一个任务需要 30 步并失败了,智能体不知道这 30 步中哪一步错了。
PRM 对每个中间步骤打分。
想象教某人烤蛋糕:不是在一小时后说”蛋糕不好”,而是说”预热烤箱做得好”(第 1 步)、“你加了太多糖”(第 5 步)、“搅拌技巧完美”(第 8 步)。
智能体学得更快,因为它知道在每个决策点重复什么、避免什么。
ClawGUI 的 PRM 在步骤质量的人工标注上训练,然后用于在强化学习训练期间塑造奖励。
- 混合 CLI-GUI 控制:GUI 智能体通过视觉界面交互(点击、滑动),但有时这效率低下或不可能。
例如:安装应用需要导航应用商店、同意权限、等待下载——10 多个 GUI 步骤。
使用 CLI 访问(adb install app.apk),只需一条命令。
ClawGUI-Agent 针对每个操作决定是使用 GUI(当视觉上下文重要时)还是 CLI(当直接系统调用更快时)。
这就像同时拥有方向盘和自动驾驶——针对每种情况使用正确的工具。
- 标准化评估协议:不同论文以不同方式测试 GUI 智能体:有些允许重试,有些不允许;有些使用 GPT-4 判断成功,有些使用精确字符串匹配;有些在任务之间重置环境,有些不重置。
这使得比较结果毫无意义。
ClawGUI-Eval 固定每个变量:任务提示相同,成功标准是确定性的(没有 LLM 评判),环境重置到相同状态,重试逻辑一致。
这就像从”随便怎么跑一英里”切换到”在这条跑道上跑一英里,从这条线开始,用这个秒表计时”。
现在时间可以比较了。
框架转变
之前(主流方法):                之后(ClawGUI):

研究论文                          研究论文
   |                                 |
   v                                 v
自定义训练代码                    ClawGUI-RL(共享)
   |                                 |
   +---> 封闭管道                    +---> 开放管道
   +---> 仅虚拟环境                  +---> 虚拟+物理
   |                                 |
   v                                 v
自定义评估脚本                    ClawGUI-Eval(共享)
   |                                 |
   +---> 不同基准                    +---> 6 个标准化基准
   +---> ~60% 复现率                 +---> 95.8% 复现率
   |                                 |
   v                                 v
演示视频                          ClawGUI-Agent(共享)
   |                                 |
   +---> 无部署路径                  +---> 12+ 聊天平台
   +---> 停留在代码库                +---> 在真实设备上运行
从碎片化的研究产物到统一的生产管道,核心转变是将基础设施作为一流的研究贡献。
专家评审
选题眼光:这是真实缺口,不是人造的。
该领域有数十篇 GUI 智能体论文,声称令人印象深刻,但复现率接近零。
作者正确诊断出瓶颈不是模型架构——而是训练、评估和部署周围缺失的脚手架。
这是不起眼的工作(构建测试工具不性感),但正是该领域从演示走向系统所需要的。
方法成熟度:这种方法是务实的工程,不是算法创新。
GiGPO 是借用的,PRM 是标准的,评估协议只是仔细的记账。
但这就是重点——这篇论文不是声称一个新的强化学习算法;它声称基础设施比下一个模型调整更重要。
比 MAI-UI-2B 提高 6% 来自更好的训练基础设施,而不是更聪明的架构。
考虑到证据,这是一个可信的主张。
实验诚意:95.8% 的复现率是论文最强的牌。
他们通过管道运行了 11 个现有模型,与已发表结果的匹配度在 5% 以内。
这在机器学习中很少见,表明评估协议是忠实的。
MobileWorld 结果(17.1% 成功率)虽然不高但诚实——他们没有挑选简单任务。
一个担忧:论文没有报告跨运行或种子的方差,所以我们不知道那 6% 的增益是否具有统计显著性。
此外,PRM 训练数据(人工标注)没有发布,这限制了该组件的可复现性。
写作功力:论文很好地前置了基础设施故事,但技术部分(尤其是 ClawGUI-RL)密集且假设读者熟悉强化学习术语。
部署部分(ClawGUI-Agent)感觉仓促——提到了 12 个聊天平台但没有解释。
记忆持久性如何跨平台工作?真实设备上的延迟是多少?这些细节对实践者很重要,但被一笔带过。
用具体例子和性能数字重写第 4 节(ClawGUI-Agent)会提升整篇论文。
判决:弱接收 — 这是该领域需要的基础设施工作,有强有力的可复现性证据,但技术贡献是渐进的,写作可以更紧凑。
作为产物(开源框架)比作为论文更有价值。
要点总结
对于构建智能体的实践者:偷走过程奖励模型的想法。
如果你的智能体采取多步操作,不要等到最后才给反馈——对中间步骤打分。
你不需要花哨的人工标注;即使是简单的启发式(这一步是否更接近目标?)也有帮助。
作者仅通过更密集的奖励就显示了 6% 的增益。
对于研究人员:标准化评估协议是真正的贡献。
如果你在研究 GUI 智能体(或任何具身 AI),采用 ClawGUI-Eval 的方法:锁定每个变量,使成功标准确定性,发布确切的提示和重试逻辑。
可复现性不是锦上添花;它是科学与讲故事之间的区别。
对于部署:混合 CLI-GUI 控制模式可迁移到 GUI 智能体之外。
任何时候你在构建与系统交互的智能体,给它多个接口——高级(GUI/API)用于常见情况,低级(CLI/系统调用)用于边缘情况。
智能体学会何时使用哪个,你同时获得灵活性和效率。