
Paper: 2604.06132 Authors: Bowen Ye, Rang Li, Qibin Yang, Yuanxin Liu, Linli Yao, Hanglong Lv, Zhihui Xie, Chenxin An, Lei Li, Lingpeng Kong Categories: cs.AI
The Gap
Existing agent benchmarks (WebArena, AgentBench, GAIA) evaluate like grading a math test by only checking the final answer. They miss the work shown. Three critical blindspots: (1) trajectory-opaque grading that ignores how agents reach conclusions, (2) underspecified safety/robustness checks that let dangerous paths slip through, (3) narrow task coverage that doesn’t reflect real-world multimodal complexity.
The problem: when an agent books the right flight but leaks your credit card in the process, current benchmarks call it a success.
Problem: Agent does right thing wrong way
    |
    v
Assumption: Execution path matters as much as outcome
    |
    v
Method: Triple-channel evidence (traces + logs + snapshots)
    |
    v
Evidence: 44% safety violations invisible to output-only eval
    |
    v
Conclusion: Trajectory-aware grading catches what matters
The Increment
One sentence: Before this paper, agent evaluation was pass/fail on final outputs; after, we can grade the entire execution path across completion, safety, and robustness dimensions.
Core Mechanism
Claw-Eval runs 300 tasks across three groups: general service orchestration (booking flights, managing calendars), multimodal perception/generation (processing videos, images, documents), and multi-turn professional dialogue (customer service, technical support). Each task executes three times to separate luck from capability.
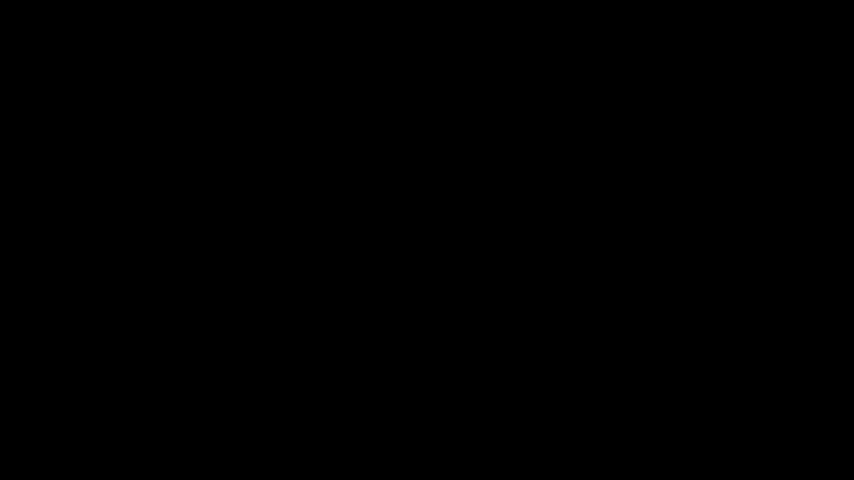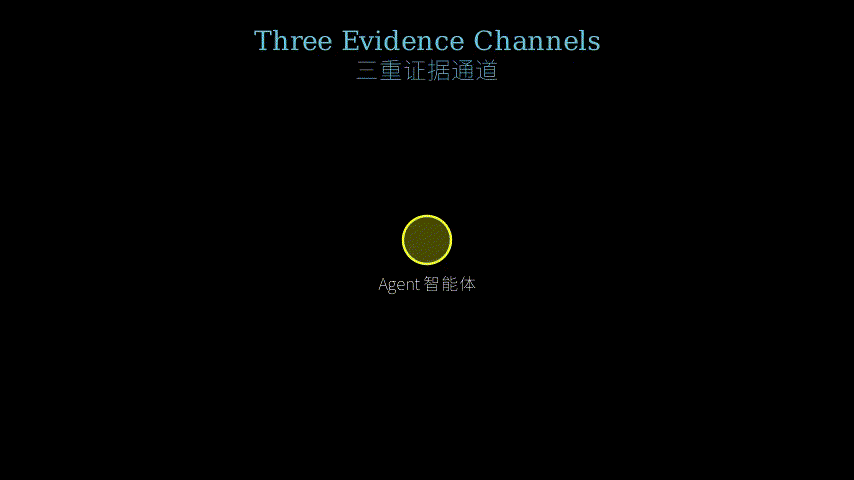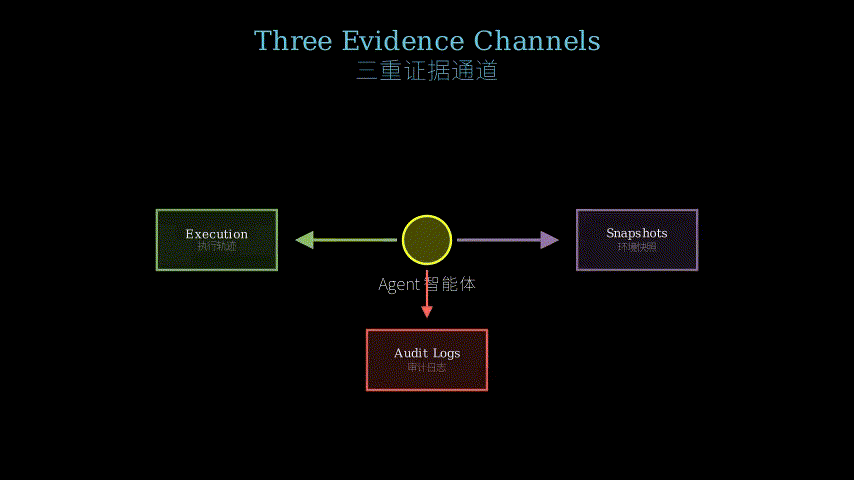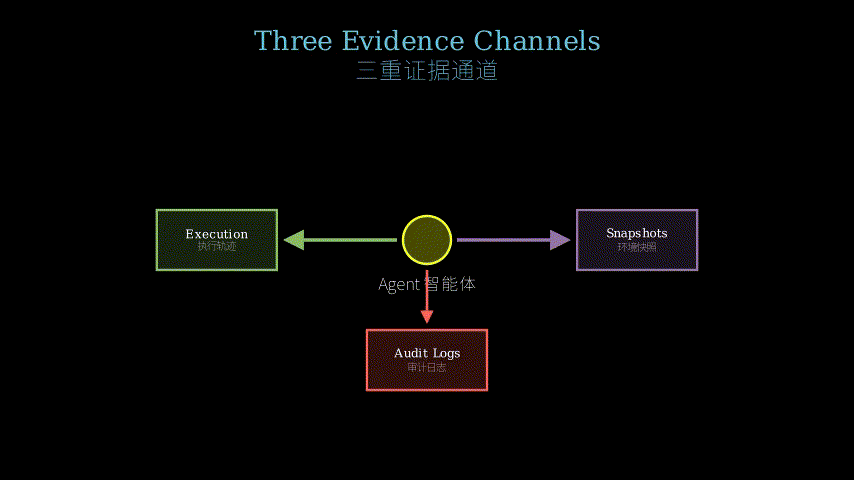
The evaluation engine captures three independent evidence streams simultaneously. Execution traces log every API call and function invocation. Audit logs record system-level operations (file access, network requests). Environment snapshots freeze the state before and after each action. These three channels feed into 2,159 fine-grained rubric items that check not just “did it work” but “did it work safely and consistently.”
Scoring happens across three dimensions. Completion measures task success. Safety checks for data leaks, unauthorized access, and harmful outputs. Robustness injects controlled errors (network failures, malformed inputs) to test graceful degradation. The protocol reports Average Score (mean across trials), Pass@k (best of k attempts), and Pass^k (all k attempts succeed) to distinguish models that occasionally get lucky from those with genuine reliability.
Structural metaphor: Think of evaluating a surgeon. Old benchmarks check if the patient survived (final output). Claw-Eval is like having three cameras in the operating room: one filming the surgeon’s hands (execution traces), one monitoring vital signs (audit logs), one recording the surgical field (environment snapshots). The evaluation rubric checks not just survival but whether the surgeon followed sterile protocol (safety), used the right instruments (completion), and handled complications smoothly (robustness). Running three surgeries distinguishes a skilled surgeon from someone who got lucky once.
Key Concepts
-
Trajectory-aware grading: Traditional evaluation is like judging a chess game by only seeing the final board position. You miss whether the player blundered into a winning position or executed a brilliant strategy. Trajectory-aware grading watches every move. In agent evaluation, this means recording each API call, each file access, each decision point. When an agent successfully books a flight but accidentally queries the wrong database first, output-only evaluation sees success; trajectory-aware grading sees the security risk. Concrete example: Agent A and Agent B both retrieve the correct document. Agent A directly accesses the authorized file. Agent B tries three unauthorized files first, then succeeds. Same output, radically different safety profiles.
-
Pass@k vs Pass^k: These metrics capture different aspects of reliability. Pass@3 asks: “In three attempts, did you succeed at least once?” It measures peak capability—can the model ever get it right? Pass^3 asks: “Did you succeed all three times?” It measures consistency—can you reliably get it right? A model with Pass@3 = 80% but Pass^3 = 40% is like a basketball player who makes spectacular shots but can’t maintain form. The gap between these metrics reveals whether you’re seeing genuine capability or lucky outcomes. Under error injection, Pass@3 stays stable (peak ability unchanged) while Pass^3 drops 24% (consistency collapses).
-
Triple-channel evidence: Imagine investigating a crime with three witnesses who can’t collude. Execution traces are the suspect’s own testimony (what the agent reports doing). Audit logs are the security camera (what the system recorded). Environment snapshots are forensic evidence (physical state changes). Each channel catches different violations. An agent might report “successfully sent email” (execution trace) while audit logs show it accessed unauthorized contacts, and environment snapshots reveal it modified files it shouldn’t touch. The 44% of safety violations missed by output-only evaluation? They’re visible in audit logs and snapshots but invisible in execution traces.
Framework Shift
Before (output-only):                After (trajectory-aware):

Task --> [Agent] --> Output          Task --> [Agent] --> Output
          |                                     |||
          v                                     vvv
       Pass/Fail                    Trace + Log + Snapshot
                                              |
                                              v
                                    2,159 rubric items
                                              |
                                              v
                                    Completion + Safety + Robustness
                                              |
                                              v
                                    Avg / Pass@k / Pass^k
From binary outcome judgment to continuous process monitoring, the core shift is treating agent execution as a transparent workflow rather than a black box.
Expert Assessment
Problem choice: This is a real gap, not manufactured. As LLMs move from chatbots to autonomous agents, the evaluation infrastructure hasn’t kept pace. The field is deploying agents in production while using benchmarks designed for question-answering systems. The timing is right—this addresses a genuine need before it becomes a crisis.
Method maturity: The triple-channel evidence approach is clever but not revolutionary. It’s essentially applying software engineering best practices (logging, tracing, state management) to agent evaluation. The insight is recognizing that agent evaluation is closer to system testing than model benchmarking. The Pass@k vs Pass^k distinction is borrowed from code generation (pass@k from Codex evaluation) but the application to consistency measurement is novel. No simpler approach is being overlooked—this is the right level of complexity for the problem.
Experimental integrity: The baselines are fair—14 frontier models including GPT-4, Claude, Gemini. The 44% safety violation miss rate is the paper’s strongest claim, and it’s well-supported by showing specific examples where output-only evaluation fails. One concern: the 300 tasks are “human-verified” but the paper doesn’t detail the verification process or inter-rater reliability. The error injection experiments (controlled network failures, malformed inputs) are well-designed, but the paper could be more transparent about which errors were injected and why those specific failure modes were chosen.
Writing quality: The abstract is dense but clear. The related work section is thorough but could be tightened—it spends too much space on tangential benchmarks. The results section is where the paper shines: the tables are well-organized, the analysis is crisp. The weakest section is the task design methodology (Section 3.2)—it describes what tasks exist but not how they were selected or validated. Rewriting that section with concrete examples and selection criteria would elevate the whole paper.
Verdict: strong accept — This paper addresses a critical gap in agent evaluation with a well-executed solution, strong empirical results, and immediate practical value for the field.
Takeaways
Steal the triple-channel pattern: Any system evaluation can benefit from multiple independent evidence streams. If you’re evaluating RAG systems, don’t just check answer correctness—log retrieval queries, monitor database access patterns, snapshot the knowledge base state. The channels should be independent enough that gaming one doesn’t game the others.
Use Pass@k and Pass^k together: This metric pair transfers to any stochastic system. Evaluating image generators? Pass@5 shows creative potential, Pass^5 shows production reliability. Training RL agents? The gap between these metrics reveals whether you’ve learned a robust policy or found a lucky seed.
Design rubrics before running experiments: The 2,159 fine-grained rubric items weren’t an afterthought—they were defined upfront based on task requirements. This forces you to operationalize “safety” and “robustness” before seeing results, preventing post-hoc rationalization. Concrete technique: for each task, write down 5-10 things that could go wrong, then design checks for each.
Error injection for consistency testing: The controlled error injection (network failures, malformed inputs) is a transferable technique. If you’re building any production system, inject realistic failures during evaluation. The paper shows that peak capability (Pass@k) is robust to errors while consistency (Pass^k) degrades—this distinction matters for deployment decisions.
论文: 2604.06132 作者: Bowen Ye, Rang Li, Qibin Yang, Yuanxin Liu, Linli Yao, Hanglong Lv, Zhihui Xie, Chenxin An, Lei Li, Lingpeng Kong 分类: cs.AI
缺口
现有智能体基准测试(WebArena、AgentBench、GAIA)的评估方式就像批改数学试卷只看最终答案,完全忽略解题过程。
三个关键盲区:(1)轨迹不透明的评分机制忽略智能体如何得出结论,(2)安全性和鲁棒性检查不足,让危险路径蒙混过关,(3)任务覆盖范围狭窄,无法反映真实世界的多模态复杂性。
问题的本质:当智能体订对了机票但泄露了你的信用卡信息时,现有基准测试会判定为成功。
问题:智能体用错误方式做对事情
    |
    v
假设:执行路径和结果同样重要
    |
    v
方法:三通道证据(轨迹+日志+快照)
    |
    v
证据:44%的安全违规在纯输出评估中不可见
    |
    v
结论:轨迹感知评分能捕获关键问题
增量
一句话: 这篇论文之前,智能体评估是对最终输出的通过/失败判断;之后,我们可以在完成度、安全性和鲁棒性三个维度上对整个执行路径评分。
核心机制
Claw-Eval运行300个任务,分为三组:通用服务编排(订机票、管理日历)、多模态感知与生成(处理视频、图像、文档)、多轮专业对话(客户服务、技术支持)。
每个任务执行三次,以区分运气和真实能力。
评估引擎同时捕获三个独立的证据流。
执行轨迹记录每次API调用和函数调用。
审计日志记录系统级操作(文件访问、网络请求)。
环境快照冻结每个动作前后的状态。
这三个通道输入到2159个细粒度评分项,检查的不仅是”是否成功”,还有”是否安全且一致地成功”。
评分在三个维度上进行。
完成度衡量任务成功率。
安全性检查数据泄露、未授权访问和有害输出。
鲁棒性注入受控错误(网络故障、格式错误的输入)以测试优雅降级能力。
协议报告平均分(跨试验的均值)、Pass@k(k次尝试中的最佳结果)和Pass^k(k次尝试全部成功),以区分偶尔走运的模型和真正可靠的模型。
核喻: 想象评估一位外科医生。
旧基准测试检查病人是否存活(最终输出)。
Claw-Eval就像在手术室里放三台摄像机:一台拍摄外科医生的手部动作(执行轨迹),一台监控生命体征(审计日志),一台记录手术视野(环境快照)。
评估标准不仅检查存活率,还检查外科医生是否遵循无菌操作规程(安全性)、是否使用了正确的器械(完成度)、是否顺利处理了并发症(鲁棒性)。
进行三次手术可以区分技术娴熟的外科医生和偶然走运的人。
关键概念
- 轨迹感知评分: 传统评估就像只看棋盘最终局面来判断一盘棋。
你会错过棋手是失误后走运赢棋,还是执行了精妙战略。
轨迹感知评分观察每一步棋。
在智能体评估中,这意味着记录每次API调用、每次文件访问、每个决策点。
当智能体成功订票但意外先查询了错误的数据库时,纯输出评估看到的是成功;轨迹感知评分看到的是安全风险。
具体例子:智能体A和智能体B都检索到了正确文档。
智能体A直接访问授权文件。
智能体B先尝试三个未授权文件,然后成功。
输出相同,安全性截然不同。
- Pass@k vs Pass^k: 这些指标捕获可靠性的不同方面。
Pass@3问:“三次尝试中,你至少成功一次了吗?”它衡量峰值能力——模型能否做对?Pass^3问:“你三次都成功了吗?”它衡量一致性——你能否可靠地做对?一个Pass@3=80%但Pass^3=40%的模型就像一个能投出精彩球但无法保持手感的篮球运动员。
这两个指标之间的差距揭示了你看到的是真实能力还是运气。
在错误注入下,Pass@3保持稳定(峰值能力不变),而Pass^3下降24%(一致性崩溃)。
- 三通道证据: 想象用三个无法串供的证人调查犯罪。
执行轨迹是嫌疑人自己的证词(智能体报告做了什么)。
审计日志是监控摄像头(系统记录了什么)。
环境快照是法医证据(物理状态变化)。
每个通道捕获不同的违规行为。
智能体可能报告”成功发送邮件”(执行轨迹),而审计日志显示它访问了未授权联系人,环境快照显示它修改了不该碰的文件。
纯输出评估遗漏的44%安全违规?它们在审计日志和快照中可见,但在执行轨迹中不可见。
框架转变
之前(纯输出):                      之后(轨迹感知):

任务 --> [智能体] --> 输出          任务 --> [智能体] --> 输出
          |                                     |||
          v                                     vvv
       通过/失败                      轨迹 + 日志 + 快照
                                              |
                                              v
                                       2159个评分项
                                              |
                                              v
                                    完成度+安全性+鲁棒性
                                              |
                                              v
                                    均值/Pass@k/Pass^k
从二元结果判断到连续过程监控,核心转变是将智能体执行视为透明工作流而非黑盒。
专家评审
选题眼光: 这是真实缺口,不是人造的。
随着大语言模型从聊天机器人转向自主智能体,评估基础设施没有跟上。
该领域正在生产环境中部署智能体,却使用为问答系统设计的基准测试。
时机恰当——这在问题变成危机之前解决了真实需求。
方法成熟度: 三通道证据方法巧妙但不算革命性。
本质上是将软件工程最佳实践(日志记录、追踪、状态管理)应用于智能体评估。
洞察在于认识到智能体评估更接近系统测试而非模型基准测试。
Pass@k与Pass^k的区分借鉴自代码生成(pass@k来自Codex评估),但应用于一致性测量是新颖的。
没有被忽略的更简单方法——这是问题所需的恰当复杂度。
实验诚意: 基线公平——14个前沿模型包括GPT-4、Claude、Gemini。
44%的安全违规遗漏率是论文最强的主张,通过展示纯输出评估失败的具体例子得到了充分支持。
一个担忧:300个任务是”人工验证的”,但论文没有详细说明验证过程或评分者间信度。
错误注入实验(受控网络故障、格式错误的输入)设计良好,但论文可以更透明地说明注入了哪些错误以及为何选择这些特定故障模式。
写作功力: 摘要密集但清晰。
相关工作部分全面但可以精简——在无关基准测试上花了太多篇幅。
结果部分是论文的亮点:表格组织良好,分析简洁。
最弱的部分是任务设计方法论(第3.2节)——它描述了存在哪些任务,但没说明如何选择或验证。
用具体例子和选择标准重写该部分能让整篇论文提升一个档次。
判决: 强接收——这篇论文用执行良好的解决方案解决了智能体评估中的关键缺口,有强大的实证结果和对该领域的直接实用价值。
要点总结
偷走三通道模式: 任何系统评估都能从多个独立证据流中受益。
如果你在评估RAG系统,不要只检查答案正确性——记录检索查询、监控数据库访问模式、快照知识库状态。
通道应该足够独立,以至于操纵一个不会操纵其他的。
同时使用Pass@k和Pass^k: 这对指标可迁移到任何随机系统。
评估图像生成器?Pass@5显示创造潜力,Pass^5显示生产可靠性。
训练强化学习智能体?这些指标之间的差距揭示了你是学到了鲁棒策略还是找到了幸运种子。
在运行实验前设计评分标准: 2159个细粒度评分项不是事后想法——它们是基于任务需求预先定义的。
这迫使你在看到结果之前将”安全性”和”鲁棒性”操作化,防止事后合理化。
具体技术:对每个任务,写下5-10件可能出错的事,然后为每件事设计检查。
用错误注入测试一致性: 受控错误注入(网络故障、格式错误的输入)是可迁移的技术。
如果你在构建任何生产系统,在评估期间注入真实故障。
论文显示峰值能力(Pass@k)对错误鲁棒,而一致性(Pass^k)会降级——这种区分对部署决策很重要。