Paper: 2604.26923 Authors: Yeheng Chen, Chaoxiang Xie, Yuling Shi, Wenhao Zeng, Yongpan Wang, Hongyu Zhang, Xiaodong Gu Categories: cs.SE, cs.CL
The Gap
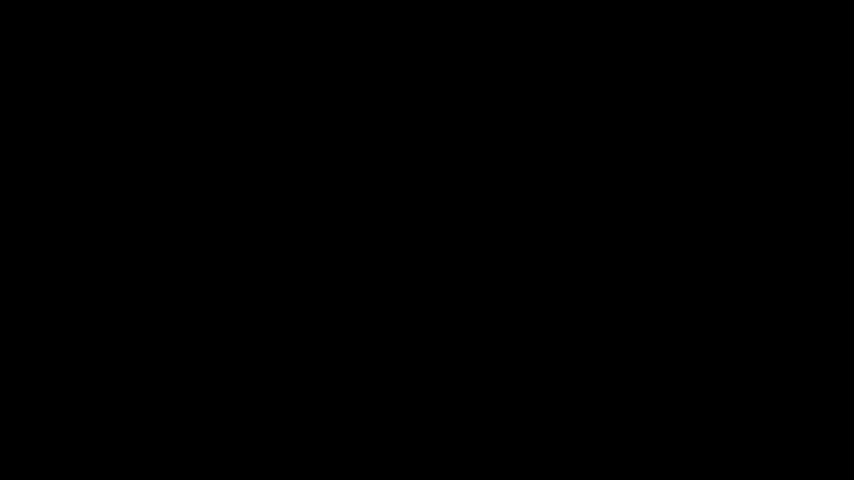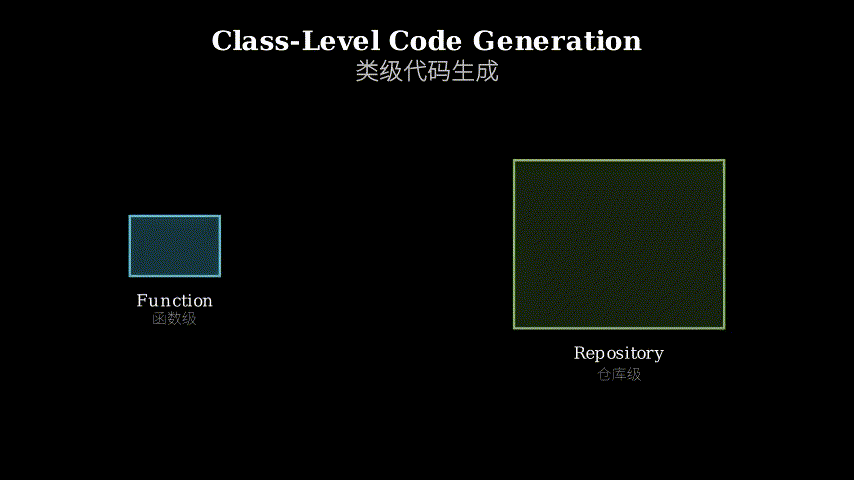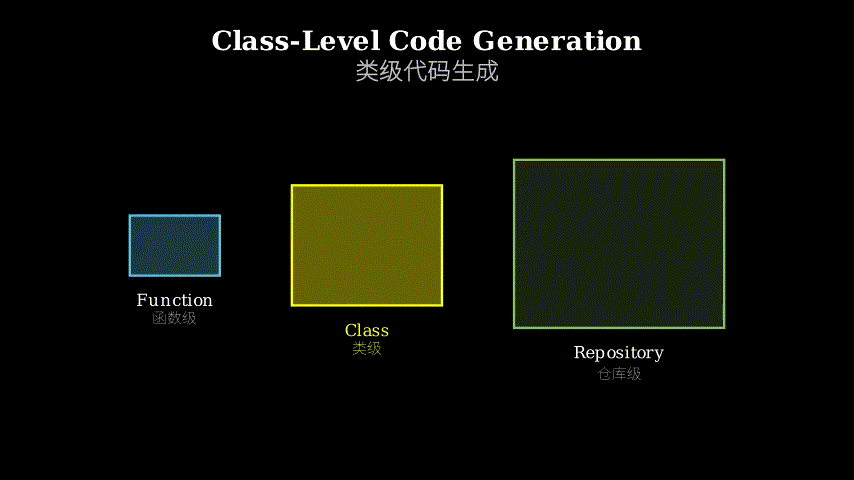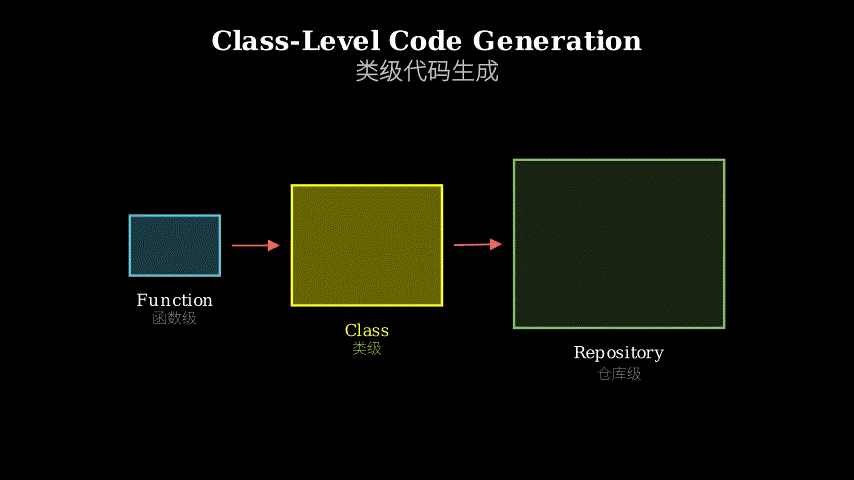
Existing code generation benchmarks cluster at two extremes: function-level tasks (HumanEval, MBPP) where models write isolated 10-20 line functions, and repository-level tasks (SWE-bench) where models edit existing codebases. Between these sits an underserved capability: compositional code creation—building a complete class from scratch with multiple interdependent methods, internal state, and cross-method coordination.
Function-level benchmarks don’t test whether models can manage state across methods or handle dependency chains. Repository-level benchmarks assume existing structure and test modification, not creation. The gap: can models architect and implement a self-contained, multi-method class where methods call each other and share state?
Prior class-level datasets (ClassEval) are small (100 tasks), manually curated (expensive to scale), and increasingly contaminated (pre-2024 data). This paper addresses all three: automated pipeline, 300 tasks across 11 domains, post-Jan-2025 GitHub code.
Problem: Function-level ----gap----> Repository-level
         (isolated logic)            (edit existing)
                    |
                    v
         Missing: Class-level composition
                    |
                    v
         Assumption: Multi-method coordination is the bottleneck
                    |
                    v
         Method: Automated pipeline + coverage validation + LLM judge
                    |
                    v
         Evidence: Best model 45.6% Pass@1, 17.7pt model gap
                   Logic errors 56.2%, dependency errors 38.0%
                    |
                    v
         Conclusion: Cross-method coordination is indeed the core challenge
The Increment
One sentence: Before this paper, we knew LLMs could write functions and edit repos but had no systematic evidence they struggle with class-level composition; after, we have a 300-task benchmark showing even frontier models fail 54% of the time, primarily on cross-method logic.
Core Mechanism
ClassEval-Pro constructs tasks through a three-stage automated pipeline. Stage 1 takes seed classes and enhances complexity by adding methods, introducing dependencies between methods, and expanding state management. Stage 2 performs cross-domain composition: it samples classes from different domains (e.g., data structures + algorithms) and merges them into hybrid classes that require coordinating logic from multiple domains. Stage 3 integrates real-world GitHub classes contributed after January 2025 to prevent contamination.
Every generated task passes through dual validation. First, an LLM Judge Ensemble (three models voting) verifies that the specification is clear, the reference solution is correct, and test cases cover edge cases. Second, automated test suite validation ensures over 90% line coverage and that tests actually exercise cross-method interactions, not just individual methods in isolation.
The benchmark evaluates models under five generation strategies: direct (one-shot class generation), step-by-step (method-by-method with reflection), bottom-up (dependencies first, then dependents), top-down (interface first, then implementation), and compositional (generate components separately, then integrate). Each strategy tests a different hypothesis about how to manage complexity.
Pipeline Flow:

Seed Classes --> [Stage 1: Complexity Enhancement] --> Enhanced Classes
                      - Add methods
                      - Introduce dependencies
                      - Expand state
                           |
                           v
                 [Stage 2: Cross-Domain Composition] --> Hybrid Classes
                      - Sample from multiple domains
                      - Merge logic patterns
                           |
                           v
                 [Stage 3: GitHub Integration] --> Final Task Set
                      - Post-Jan-2025 code
                      - Prevent contamination
                           |
                           v
                 [Dual Validation]
                      - LLM Judge Ensemble (3 models)
                      - Test Coverage >90%
                           |
                           v
                 300 Tasks x 5 Strategies x 5 Models --> Results
Think of this like building a cooking exam for chefs. Stage 1 takes simple recipes (boil pasta) and makes them complex (pasta carbonara with timing dependencies—eggs must go in after heat is off). Stage 2 creates fusion dishes (Italian-Japanese: miso carbonara) that require coordinating techniques from different cuisines. Stage 3 adds brand-new recipes from 2025 cookbooks so contestants can’t have memorized them.
The validation is like having three master chefs taste-test every exam question to confirm it’s fair, then checking that the answer key actually demonstrates all the required techniques (coverage). The five strategies are different approaches to cooking: direct (make the whole dish at once), step-by-step (one component at a time with tasting between), bottom-up (make the sauce before the pasta), top-down (plate presentation first, then fill in), compositional (prep all ingredients separately, then combine).
The key insight: class-level code isn’t just “more functions”—it’s about managing state that flows through method calls, handling dependencies where method A’s output feeds method B’s logic, and coordinating error handling across the call chain. The benchmark specifically targets these coordination challenges.
Key Concepts
-
Cross-method coordination: When a class has methods that call each other or share mutable state, the correctness of one method depends on the behavior of others. For example, a
BankAccountclass wherewithdraw()must check the balance set bydeposit(), andgetBalance()must reflect all prior transactions. This isn’t just writing multiple functions—it’s ensuring they form a coherent system. The challenge: LLMs generate each method somewhat independently, so they often miss implicit contracts (e.g.,withdraw()assumesdeposit()initializes balance to zero, but the generateddeposit()doesn’t). The paper finds 38% of failures stem from these broken dependencies. -
Compositional generation collapse: One strategy the paper tests is generating class components (methods, helper functions) separately, then integrating them. Intuition says this should work—divide and conquer. Reality: it achieves only 1.3% Pass@1 for weaker models. Why? Because when you generate methods in isolation, you lose the context of how they’ll interact. It’s like writing chapters of a novel separately without an outline—each chapter might be fine, but they don’t form a coherent story. The integration step tries to stitch together pieces that were never designed to fit, leading to mismatched assumptions about state, calling conventions, and error handling.
-
LLM Judge Ensemble: Instead of one model deciding if a task is valid, three models vote. Each judges whether the specification is unambiguous, the reference solution is correct, and test cases are comprehensive. A task passes only if at least two models agree. This catches edge cases where a single model’s biases (e.g., overly permissive on ambiguous specs) would let bad tasks through. It’s like peer review: one reviewer might miss something, but three independent reviewers rarely all miss the same flaw. The paper shows this reduces invalid tasks from ~15% (single judge) to ~3% (ensemble).
Framework Shift
Before (mainstream approach):        After (this paper):

Function-level:                      Class-level composition:
  Input: "write fibonacci"             Input: "write LRU cache class"
  Output: one function                 Output: complete class with:
  Test: does it return                   - __init__, get, put methods
        correct numbers?                 - internal dict + doubly-linked list
                                         - cross-method state updates
         +                                      +
         |                                      |
Repository-level:                              |
  Input: "fix bug in line 47"                  |
  Output: edit existing code                   |
  Test: does the bug disappear?                |
                                               |
  [Gap: no test for building          [Tests: does get() reflect put()?
   multi-method classes from                   does eviction work?
   scratch]                                    do methods coordinate?]
One sentence: From testing isolated logic (functions) or modification skills (repo edits) to testing architectural coordination—can the model design and implement a system where parts depend on each other?
Expert Assessment
Problem choice: Real gap. The jump from function-level to repo-level is too large—practitioners need models that can scaffold new modules, not just tweak existing ones. Class-level sits at the sweet spot: complex enough to test coordination, scoped enough to evaluate automatically. The timing is right: function-level benchmarks are saturated (90%+ Pass@1), so the field needs harder targets.
Method maturity: The automated pipeline is clever—cross-domain composition is a genuinely novel way to generate hard tasks without manual curation. But the LLM Judge Ensemble feels like a patch over a deeper problem: if you need three models to validate tasks, maybe the generation process is too noisy. A tighter generation algorithm (e.g., constraint-based synthesis) might produce cleaner tasks without needing ensemble validation. The five strategies are well-chosen, though “compositional” seems like a strawman—no practitioner would generate methods in total isolation.
Experimental integrity: Baselines are fair—five frontier models, consistent prompting, multiple strategies. The 90% coverage threshold is rigorous. One concern: the paper doesn’t report inter-annotator agreement for the 500 manually labeled failures. If two annotators disagree on whether an error is “logic” vs “dependency,” the 56.2% / 38.0% split might be less meaningful. Also, the post-Jan-2025 GitHub code is good for contamination, but only 100 of 300 tasks use it—the other 200 are synthetic, so contamination risk remains for models trained on similar synthetic data.
Writing quality: The method section is dense—three stages, dual validation, five strategies all crammed into two pages. A diagram showing one example task flowing through the entire pipeline would clarify more than three paragraphs of description. The error analysis (Section 5.3) is the paper’s strongest part—concrete failure modes with examples—but it’s buried at the end. Leading with “here’s what models get wrong” would hook readers better than leading with “here’s our pipeline.”
Verdict: Weak accept — Addresses a real gap with a scalable method and rigorous evaluation, but the automated pipeline’s complexity raises questions about whether simpler approaches were explored, and the writing doesn’t do justice to the strong empirical findings.
Takeaways
For benchmark designers: Cross-domain composition (merging classes from different domains) is a cheap way to generate hard tasks. You don’t need more data—you need to combine existing data in ways that force models to coordinate disparate logic patterns.
For prompt engineers: Structured strategies (bottom-up, step-by-step) help weaker models significantly (+9.4 points) but barely help strong models (+1.2 points). If you’re using a frontier model, one-shot generation is often better than elaborate scaffolding. If you’re using a smaller model, invest in dependency-aware prompting.
For model developers: The 56.2% logic error rate suggests models struggle with maintaining invariants across method calls. Training on more class-level code won’t fix this—you need data where methods explicitly depend on each other, not just collections of independent methods that happen to live in the same class. Look for codebases with high cyclomatic complexity per class, not just high method count.
For researchers: The 17.7-point gap between strongest and weakest models is unusually large for a 2026 benchmark (most recent benchmarks show 5-10 point gaps). This suggests class-level composition is still a frontier capability, not a solved problem. There’s room for architectural innovations (e.g., explicit dependency graphs in the model’s reasoning) rather than just scaling.
论文: 2604.26923 作者: Yeheng Chen, Chaoxiang Xie, Yuling Shi, Wenhao Zeng, Yongpan Wang, Hongyu Zhang, Xiaodong Gu 分类: cs.SE, cs.CL
缺口
现有代码生成基准聚集在两个极端:函数级任务(HumanEval、MBPP)让模型写10-20行的孤立函数,仓库级任务(SWE-bench)让模型编辑现有代码库。
两者之间存在一个服务不足的能力:组合式代码创建——从零开始构建完整的类,包含多个相互依赖的方法、内部状态和跨方法协调。
函数级基准不测试模型能否跨方法管理状态或处理依赖链。
仓库级基准假设已有结构,测试的是修改而非创建。
缺口在于:模型能否架构并实现一个自包含的多方法类,其中方法相互调用并共享状态?
此前的类级数据集(ClassEval)规模小(100个任务)、手工策划(扩展成本高)、且日益污染(2024年前的数据)。
本文解决了这三个问题:自动化流水线、跨11个领域的300个任务、2025年1月后的GitHub代码。
问题:函数级 ----缺口----> 仓库级
     (孤立逻辑)          (编辑现有代码)
                |
                v
     缺失:类级组合
                |
                v
     假设:多方法协调是瓶颈
                |
                v
     方法:自动化流水线 + 覆盖率验证 + LLM评审
                |
                v
     证据:最佳模型45.6% Pass@1,模型间差距17.7个百分点
          逻辑错误56.2%,依赖错误38.0%
                |
                v
     结论:跨方法协调确实是核心挑战
增量
一句话:本文之前,我们知道大模型能写函数、能编辑仓库,但没有系统证据表明它们在类级组合上挣扎;本文之后,我们有了一个300任务的基准,显示即使前沿模型也有54%的失败率,主要失败在跨方法逻辑上。
核心机制
ClassEval-Pro通过三阶段自动化流水线构建任务。
第一阶段取种子类并增强复杂度:添加方法、引入方法间依赖、扩展状态管理。
第二阶段执行跨域组合:从不同领域(如数据结构+算法)采样类,将它们合并成需要协调多领域逻辑的混合类。
第三阶段整合2025年1月后贡献的真实GitHub类,防止污染。
每个生成的任务都经过双重验证。
首先,LLM评审团(三个模型投票)验证规格说明清晰、参考解决方案正确、测试用例覆盖边界情况。
其次,自动化测试套件验证确保超过90%的行覆盖率,且测试实际演练跨方法交互,而非仅孤立测试单个方法。
基准在五种生成策略下评估模型:直接式(一次性生成整个类)、逐步式(逐方法生成并反思)、自底向上(先生成依赖项,再生成依赖者)、自顶向下(先生成接口,再生成实现)、组合式(分别生成组件,然后整合)。
每种策略测试关于如何管理复杂性的不同假设。
流水线流程:

种子类 --> [阶段1:复杂度增强] --> 增强类
                - 添加方法
                - 引入依赖
                - 扩展状态
                     |
                     v
           [阶段2:跨域组合] --> 混合类
                - 从多个领域采样
                - 合并逻辑模式
                     |
                     v
           [阶段3:GitHub整合] --> 最终任务集
                - 2025年1月后代码
                - 防止污染
                     |
                     v
           [双重验证]
                - LLM评审团(3个模型)
                - 测试覆盖率>90%
                     |
                     v
           300任务 x 5策略 x 5模型 --> 结果
把这想象成给厨师设计烹饪考试。
阶段1取简单食谱(煮意面)并使其复杂化(意式培根蛋面,有时序依赖——鸡蛋必须在关火后加入)。
阶段2创建融合菜(意日融合:味噌培根蛋面),需要协调不同菜系的技术。
阶段3添加2025年烹饪书中的全新食谱,这样参赛者不可能记住它们。
验证就像让三位大厨品尝每道考题,确认它公平,然后检查答案确实演示了所有要求的技术(覆盖率)。
五种策略是不同的烹饪方法:直接式(一次做完整道菜)、逐步式(一次做一个组件,中间品尝)、自底向上(先做酱汁再做意面)、自顶向下(先摆盘,再填充)、组合式(分别准备所有食材,然后组合)。
关键洞察:类级代码不只是”更多函数”——它关乎管理流经方法调用的状态、处理方法A的输出馈入方法B逻辑的依赖关系、协调整个调用链的错误处理。
基准专门针对这些协调挑战。
关键概念
- 跨方法协调:当一个类的方法相互调用或共享可变状态时,一个方法的正确性依赖于其他方法的行为。
例如,一个BankAccount类,其中withdraw()必须检查deposit()设置的余额,getBalance()必须反映所有先前的交易。
这不只是写多个函数——而是确保它们形成一个连贯的系统。
挑战在于:大模型在某种程度上独立生成每个方法,因此它们经常错过隐式契约(例如,withdraw()假设deposit()将余额初始化为零,但生成的deposit()没有这样做)。
论文发现38%的失败源于这些破碎的依赖关系。
- 组合式生成崩溃:论文测试的一种策略是分别生成类组件(方法、辅助函数),然后整合它们。
直觉上这应该有效——分而治之。
现实:对于较弱的模型,它只达到1.3%的Pass@1。
为什么?因为当你孤立生成方法时,你失去了它们如何交互的上下文。
这就像分别写小说的各章而没有大纲——每章可能都不错,但它们不构成连贯的故事。
整合步骤试图拼接从未设计为契合的片段,导致关于状态、调用约定和错误处理的假设不匹配。
- LLM评审团:不是一个模型决定任务是否有效,而是三个模型投票。
每个模型判断规格说明是否明确、参考解决方案是否正确、测试用例是否全面。
任务只有在至少两个模型同意时才通过。
这捕获了单个模型的偏见(例如,对模糊规格过于宽容)会放过坏任务的边界情况。
这就像同行评审:一个评审者可能会错过某些东西,但三个独立评审者很少都错过同一个缺陷。
论文显示这将无效任务从约15%(单一评审)减少到约3%(评审团)。
框架转变
之前(主流方法):                之后(本文方法):

函数级:                          类级组合:
  输入:"写斐波那契"                输入:"写LRU缓存类"
  输出:一个函数                    输出:完整的类,包含:
  测试:返回的数字                    - __init__、get、put方法
        正确吗?                      - 内部dict + 双向链表
                                      - 跨方法状态更新
         +                                  +
         |                                  |
仓库级:                                    |
  输入:"修复第47行的bug"                   |
  输出:编辑现有代码                        |
  测试:bug消失了吗?                       |
                                           |
  [缺口:没有测试从零                [测试:get()反映put()吗?
   构建多方法类]                           驱逐工作吗?
                                          方法协调吗?]
一句话:从测试孤立逻辑(函数)或修改技能(仓库编辑)到测试架构协调——模型能否设计并实现一个各部分相互依赖的系统?
专家评审
选题眼光:真实缺口。
从函数级到仓库级的跳跃太大——实践者需要能搭建新模块的模型,而不仅仅是调整现有模块。
类级处于最佳位置:足够复杂以测试协调,范围足够小以自动评估。
时机恰当:函数级基准已饱和(90%+的Pass@1),因此该领域需要更难的目标。
方法成熟度:自动化流水线很巧妙——跨域组合是一种真正新颖的方式,无需手工策划即可生成困难任务。
但LLM评审团感觉像是对更深层问题的补丁:如果你需要三个模型来验证任务,也许生成过程太嘈杂了。
更严格的生成算法(例如,基于约束的综合)可能会产生更干净的任务,而无需评审团验证。
五种策略选择得当,尽管”组合式”似乎是个稻草人——没有实践者会在完全孤立的情况下生成方法。
实验诚意:基线公平——五个前沿模型、一致的提示、多种策略。
90%覆盖率阈值很严格。
一个担忧:论文没有报告500个手动标注失败的标注者间一致性。
如果两个标注者对错误是”逻辑”还是”依赖”有分歧,56.2% / 38.0%的划分可能意义不大。
此外,2025年1月后的GitHub代码对污染有好处,但300个任务中只有100个使用它——其他200个是合成的,因此对于在类似合成数据上训练的模型,污染风险仍然存在。
写作功力:方法部分很密集——三个阶段、双重验证、五种策略都挤在两页里。
一个显示一个示例任务流经整个流水线的图表会比三段描述更清晰。
错误分析(第5.3节)是论文最强的部分——具体的失败模式和示例——但它被埋在最后。
以”这是模型出错的地方”开头会比以”这是我们的流水线”开头更能吸引读者。
判决:弱接收 — 用可扩展的方法和严格的评估解决了真实缺口,但自动化流水线的复杂性引发了关于是否探索了更简单方法的问题,写作没有充分展现强大的实证发现。
要点总结
对基准设计者:跨域组合(合并来自不同领域的类)是生成困难任务的廉价方式。
你不需要更多数据——你需要以迫使模型协调不同逻辑模式的方式组合现有数据。
对提示工程师:结构化策略(自底向上、逐步式)显著帮助较弱模型(+9.4分),但几乎不帮助强模型(+1.2分)。
如果你使用前沿模型,一次性生成通常比精心设计的脚手架更好。
如果你使用较小模型,投资于依赖感知提示。
对模型开发者:56.2%的逻辑错误率表明模型在跨方法调用维护不变量方面挣扎。
在更多类级代码上训练不会解决这个问题——你需要方法明确相互依赖的数据,而不仅仅是恰好存在于同一类中的独立方法集合。
寻找每个类具有高圈复杂度的代码库,而不仅仅是高方法数。
对研究者:最强和最弱模型之间17.7个百分点的差距对于2026年的基准来说异常大(大多数近期基准显示5-10个百分点的差距)。
这表明类级组合仍然是前沿能力,而非已解决的问题。
有架构创新的空间(例如,模型推理中的显式依赖图),而不仅仅是扩展规模。