Paper: 2605.26089 Authors: Wei Song, Tianhang Wang, Yitong Chen, Tong Zhang, Zuxuan Wu, Ming Li, Jiaqi Wang, Kaicheng Yu Categories: cs.CV, cs.AI
The Gap
Vector quantization (VQ) methods like VQGAN and VQVAE tokenize images by dividing them into spatial patches and assigning each patch a discrete code. This works, but it has two persistent problems: (1) codebook collapse — most codes never get used, even with codebooks of 8K-16K entries, wasting representational capacity; and (2) the spatial grid structure forces autoregressive models to generate images in raster scan order (left-to-right, top-to-bottom), which doesn’t match how visual content naturally decomposes into coarse-to-fine structure.
This paper asks: what if we quantize along the channel dimension instead of the spatial dimension? Instead of “this patch gets code 42,” we’d have “channel 0 gets level 3, channel 1 gets level 7,” and so on. The image becomes a stack of detail levels rather than a grid of patches.
Problem: Patch-based VQ
   |
   +---> Codebook collapse (most codes unused)
   |
   +---> Spatial generation order (raster scan)
   |
   v
Assumption: Channels encode detail levels
   |
   v
Method: CVQ (quantize each channel independently)
   |
   v
Evidence: 100% codebook use, better reconstruction
   |
   v
Conclusion: Channel-wise tokens > patch-wise tokens
The Increment
One sentence: Before this paper, image tokens were spatial patches; after this paper, image tokens can be detail channels, enabling full codebook utilization and coarse-to-fine generation.
Core Mechanism
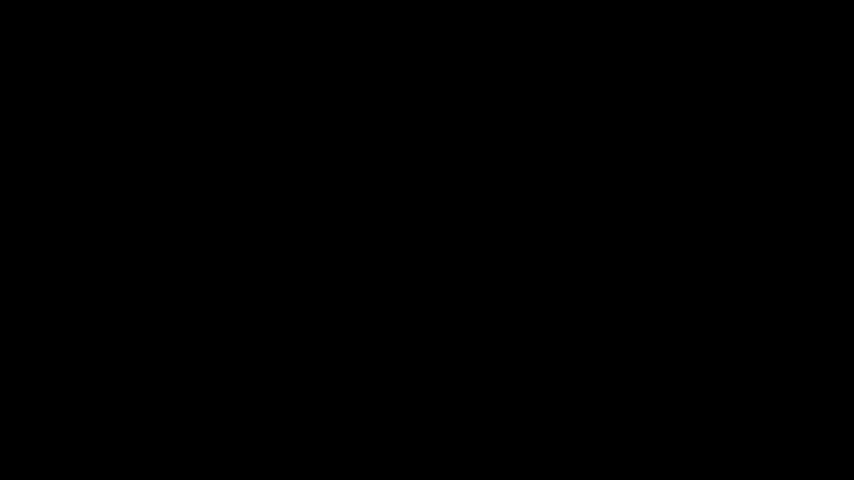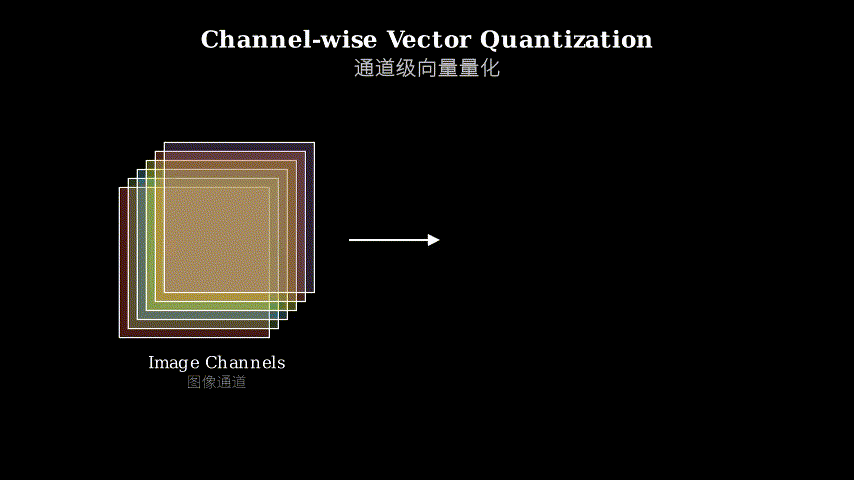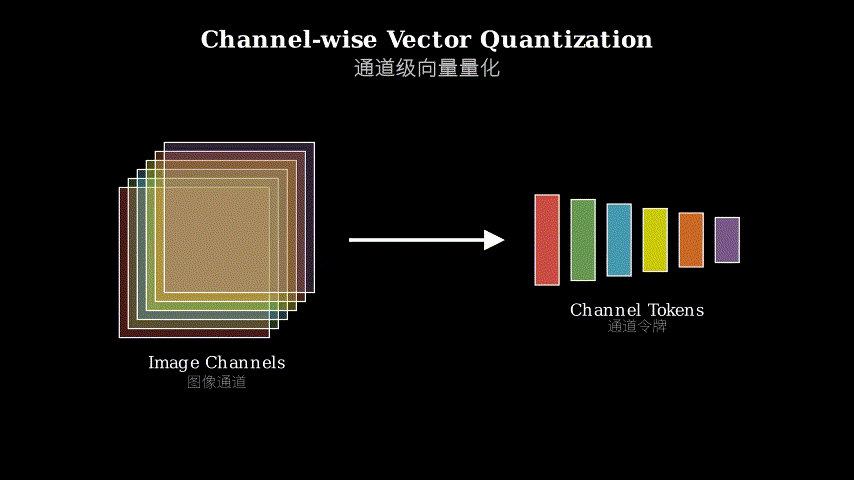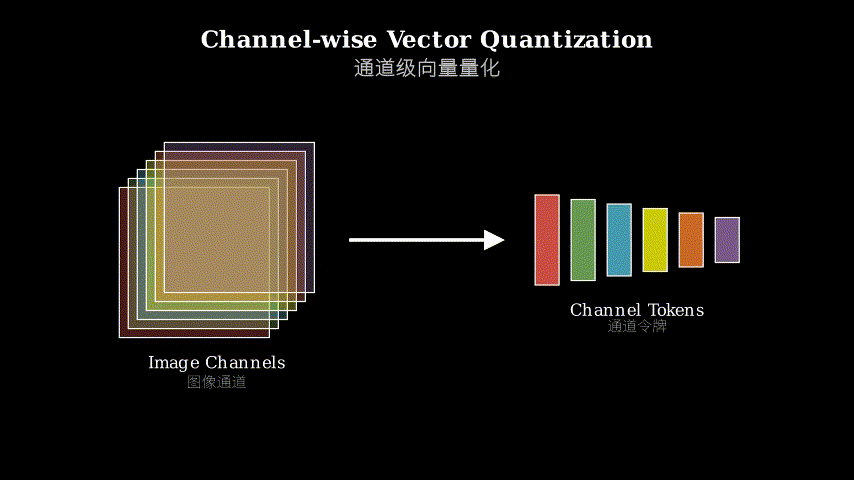
CVQ takes a feature map of shape (C, H, W) — C channels, H×W spatial resolution — and quantizes each of the C channels independently. For each channel, every spatial location gets mapped to one of K discrete levels (e.g., K=16). The result is C discrete “channel tokens” instead of (H/p)×(W/p) patch tokens.
The encoder produces the feature map, then a per-channel quantizer maps each channel’s values to discrete levels. The decoder reconstructs the image from these quantized channels. Crucially, the codebook is shared across all channels — each channel picks from the same K levels, but different channels pick different levels. This means the effective codebook size is K^C, but the model only needs to learn K embeddings.
For generation, the Channel-wise Autoregressive (CAR) model predicts channels sequentially: channel 0, then channel 1, then channel 2, and so on. Early channels capture global structure (like a sketch), later channels add fine details (like shading and texture). This mirrors how artists work: rough composition first, refinement later.
Input Image
    |
    v
Encoder --> Feature Map (C x H x W)
    |
    v
Per-Channel Quantizer
    |
    +---> Channel 0: all (H,W) locations -> level k0
    +---> Channel 1: all (H,W) locations -> level k1
    +---> ...
    +---> Channel C: all (H,W) locations -> level kC
    |
    v
C discrete tokens (one per channel)
    |
    v
Decoder --> Reconstructed Image
Think of it like painting with layers in Photoshop. Each layer (channel) has a single opacity/blend setting (the quantized level) applied uniformly across the canvas. Layer 0 might be “base color at 80% opacity,” layer 1 might be “shadow at 40%,” layer 2 might be “highlight at 60%.” You don’t paint pixel-by-pixel; you adjust each layer’s global setting. The final image is the composite of all layers. CVQ works the same way: each channel is a “layer” with a discrete setting, and the decoder composites them into the final image. The autoregressive model predicts these layer settings one at a time, starting with the most important layers (global structure) and ending with the least important (fine texture).
Key Concepts
-
Channel-wise quantization: Instead of treating each spatial patch as an independent unit to quantize, CVQ treats each channel as an independent unit. A channel is a 2D slice of the feature map — all spatial locations in that channel get quantized together. This is like saying “the entire red layer of this image gets brightness level 5” rather than “this 16×16 patch gets code 42.” The key insight: channels naturally encode different levels of visual detail (edges, textures, colors), so quantizing them independently preserves this hierarchical structure.
-
Codebook utilization: In patch-based VQ, a codebook of size 16K might only use 2K codes in practice — the other 14K sit unused (codebook collapse). CVQ achieves 100% utilization because each channel independently picks from K levels, and all K levels get used across different channels. It’s like having 16 paint colors: if you paint 256 separate patches, you might only use 3 colors (collapse). But if you paint 256 layers, each layer picking one color, you’ll use all 16 colors across the layers.
-
Next-channel prediction: Autoregressive models typically predict “next patch” in raster order. CAR predicts “next channel” instead. Channel 0 might encode the overall brightness, channel 1 the main edges, channel 2 the color tones, and so on. Predicting them in order means the model first sketches the image (early channels), then refines it (later channels). This is more natural than raster scan, which has no semantic ordering — the top-left patch isn’t inherently “earlier” than the bottom-right patch.
Framework Shift
Before (patch-based VQ):              After (CVQ):

Image                                 Image
  |                                     |
  v                                     v
Divide into patches                   Extract feature map
  |                                     |
  v                                     v
[P1][P2][P3]...[PN]                   [Ch0][Ch1][Ch2]...[ChC]
  |   |   |      |                      |    |    |       |
  v   v   v      v                      v    v    v       v
 c1  c2  c3 ... cN                     L0   L1   L2  ... LC
(N discrete codes)                    (C discrete levels)

Generation order:                     Generation order:
P1 -> P2 -> P3 -> ... -> PN          Ch0 -> Ch1 -> Ch2 -> ... -> ChC
(raster scan, no semantics)          (coarse to fine, semantic)
From spatial grid to detail stack, the core shift is representation: images as mosaics of patches → images as layers of detail.
Expert Assessment
Problem choice: Real gap. Codebook collapse has plagued VQ methods for years, and raster-order generation is a known mismatch with visual structure. This paper attacks both problems with a single idea, which is elegant. The gap sits at the intersection of representation learning and generative modeling — a high-value area.
Method maturity: Clever insight, not brute force. The idea of quantizing channels instead of patches is simple but non-obvious. The execution is clean: no complex training tricks, no auxiliary losses, just a different quantization axis. However, the paper doesn’t deeply explore *why channels encode detail levels — it’s treated as an empirical observation rather than a principled design. A stronger theoretical grounding would elevate this from “neat trick” to “fundamental principle.”
Experimental integrity: Baselines are fair (VQGAN, MaskGIT, LlamaGen). The 100% codebook utilization claim is striking and well-documented. Reconstruction quality (rFID) and generation quality (DPG, GenEval) both improve over baselines. One concern: the paper doesn’t ablate the impact of codebook size on CVQ vs patch-based VQ at the same parameter count. Does CVQ’s advantage hold if patch-based VQ uses a smaller, fully-utilized codebook? Also, the “coarse-to-fine” narrative is intuitive but not rigorously validated — do early channels actually encode global structure, or is that post-hoc interpretation?
Writing quality: The core idea is communicated clearly, but the paper front-loads motivation and back-loads technical details. Section 3 (method) is dense and would benefit from more diagrams showing data flow. The “artist workflow” analogy is evocative but not formalized — it’s unclear whether channel order is learned or imposed. The related work section is thorough but could be trimmed to make room for deeper ablations.
Verdict: weak accept — The core contribution (channel-wise quantization) is novel and the empirical results are strong, but the paper lacks theoretical depth and rigorous validation of its coarse-to-fine claims. It’s a solid incremental advance, not a paradigm shift.
Takeaways
Steal the quantization axis: If you’re working with any structured data (images, audio, video), consider whether the conventional tokenization axis is optimal. Spatial patches are intuitive but not inevitable. Could you quantize along time, frequency, or semantic dimensions instead?
Codebook utilization as a diagnostic: If your VQ model has codebook collapse, don’t just add regularization losses — question whether your tokenization granularity matches the data’s natural structure. CVQ’s 100% utilization isn’t magic; it’s a sign that the quantization axis aligns with how the data varies.
Coarse-to-fine generation: Even if you stick with patch-based tokens, you can impose a coarse-to-fine ordering. Sort patches by their importance (e.g., via attention maps or gradient magnitudes) and generate in that order instead of raster scan. This paper shows that generation order matters for quality.
论文: 2605.26089 作者: Wei Song, Tianhang Wang, Yitong Chen, Tong Zhang, Zuxuan Wu, Ming Li, Jiaqi Wang, Kaicheng Yu 分类: cs.CV, cs.AI
缺口
VQGAN 和 VQVAE 等向量量化方法将图像分割成空间块,给每个块分配一个离散码。
这种做法有效,但存在两个顽疾:(1)码本坍缩——即使码本有 8K-16K 个条目,大部分码从未被使用,浪费了表征容量;(2)空间网格结构迫使自回归模型按光栅扫描顺序(从左到右、从上到下)生成图像,这与视觉内容自然分解为由粗到细的结构不匹配。
本文提问:如果沿通道维度而非空间维度量化会怎样?
不再是”这个块得到码 42”,而是”通道 0 得到级别 3,通道 1 得到级别 7”,以此类推。
图像变成细节层次的堆叠,而非块的网格。
问题:基于块的 VQ
   |
   +---> 码本坍缩(大部分码未使用)
   |
   +---> 空间生成顺序(光栅扫描)
   |
   v
假设:通道编码细节层次
   |
   v
方法:CVQ(独立量化每个通道)
   |
   v
证据:100% 码本利用率,更好的重建质量
   |
   v
结论:通道级 token > 块级 token
增量
一句话:这篇论文之前,图像 token 是空间块;之后,图像 token 可以是细节通道,实现完全码本利用和由粗到细生成。
核心机制
CVQ 接收形状为 (C, H, W) 的特征图——C 个通道,H×W 空间分辨率——独立量化每个通道。
对每个通道,所有空间位置被映射到 K 个离散级别之一(例如 K=16)。
结果是 C 个离散”通道 token”,而非 (H/p)×(W/p) 个块 token。
编码器产生特征图,然后逐通道量化器将每个通道的值映射到离散级别。
解码器从这些量化通道重建图像。
关键在于,码本在所有通道间共享——每个通道从相同的 K 个级别中选择,但不同通道选择不同级别。
这意味着有效码本大小是 K^C,但模型只需学习 K 个嵌入。
对于生成,通道级自回归(CAR)模型顺序预测通道:通道 0,然后通道 1,然后通道 2,依此类推。
早期通道捕获全局结构(如草图),后期通道添加精细细节(如阴影和纹理)。
这反映了艺术家的工作方式:先粗略构图,后精细化。
输入图像
    |
    v
编码器 --> 特征图 (C x H x W)
    |
    v
逐通道量化器
    |
    +---> 通道 0: 所有 (H,W) 位置 -> 级别 k0
    +---> 通道 1: 所有 (H,W) 位置 -> 级别 k1
    +---> ...
    +---> 通道 C: 所有 (H,W) 位置 -> 级别 kC
    |
    v
C 个离散 token(每通道一个)
    |
    v
解码器 --> 重建图像
把它想象成 Photoshop 中的图层绘画。
每个图层(通道)有一个单一的不透明度/混合设置(量化级别)均匀应用于整个画布。
图层 0 可能是”80% 不透明度的基础色”,图层 1 可能是”40% 的阴影”,图层 2 可能是”60% 的高光”。
你不是逐像素绘画;你调整每个图层的全局设置。
最终图像是所有图层的合成。
CVQ 以同样方式工作:每个通道是一个”图层”,有一个离散设置,解码器将它们合成为最终图像。
自回归模型逐个预测这些图层设置,从最重要的图层(全局结构)开始,到最不重要的(精细纹理)结束。
关键概念
- 通道级量化:CVQ 不将每个空间块视为独立的量化单元,而是将每个通道视为独立单元。
通道是特征图的 2D 切片——该通道中的所有空间位置一起被量化。
这就像说”这张图像的整个红色层得到亮度级别 5”,而不是”这个 16×16 块得到码 42”。
关键洞察:通道自然编码不同级别的视觉细节(边缘、纹理、颜色),因此独立量化它们保留了这种层次结构。
- 码本利用率:在基于块的 VQ 中,大小为 16K 的码本实际可能只使用 2K 个码——其他 14K 个闲置(码本坍缩)。
CVQ 实现 100% 利用率,因为每个通道独立从 K 个级别中选择,所有 K 个级别在不同通道间都被使用。
这就像有 16 种颜料:如果你画 256 个独立的块,你可能只用 3 种颜色(坍缩)。
但如果你画 256 个图层,每层选一种颜色,你会在所有图层中用完全部 16 种颜色。
- 下一通道预测:自回归模型通常按光栅顺序预测”下一块”。
CAR 改为预测”下一通道”。
通道 0 可能编码整体亮度,通道 1 编码主要边缘,通道 2 编码色调,依此类推。
按顺序预测它们意味着模型首先勾勒图像(早期通道),然后精细化(后期通道)。
这比光栅扫描更自然,后者没有语义顺序——左上角的块本质上并不比右下角的块”更早”。
框架转变
之前(基于块的 VQ):              之后(CVQ):

图像                                图像
  |                                   |
  v                                   v
分割成块                            提取特征图
  |                                   |
  v                                   v
[P1][P2][P3]...[PN]                 [Ch0][Ch1][Ch2]...[ChC]
  |   |   |      |                    |    |    |       |
  v   v   v      v                    v    v    v       v
 c1  c2  c3 ... cN                   L0   L1   L2  ... LC
(N 个离散码)                      (C 个离散级别)

生成顺序:                          生成顺序:
P1 -> P2 -> P3 -> ... -> PN        Ch0 -> Ch1 -> Ch2 -> ... -> ChC
(光栅扫描,无语义)                (由粗到细,有语义)
从空间网格到细节堆叠,核心转变是表征:图像作为块的马赛克 → 图像作为细节的层次。
专家评审
选题眼光:真实缺口。
码本坍缩困扰 VQ 方法多年,光栅顺序生成与视觉结构不匹配是已知问题。
本文用单一想法同时攻击两个问题,这很优雅。
缺口位于表征学习和生成建模的交叉点——高价值领域。
方法成熟度:巧劲,非蛮力。
量化通道而非块的想法简单但非显而易见。
执行干净:无复杂训练技巧,无辅助损失,只是不同的量化轴。
然而,论文没有深入探讨为什么通道编码细节层次——这被视为经验观察而非原则性设计。
更强的理论基础会将其从”巧妙技巧”提升到”基本原理”。
实验诚意:基线公平(VQGAN、MaskGIT、LlamaGen)。
100% 码本利用率的声明引人注目且有充分记录。
重建质量(rFID)和生成质量(DPG、GenEval)都优于基线。
一个担忧:论文没有在相同参数量下消融码本大小对 CVQ 与基于块的 VQ 的影响。
如果基于块的 VQ 使用更小的、完全利用的码本,CVQ 的优势是否保持?
此外,“由粗到细”的叙述直观但未经严格验证——早期通道真的编码全局结构,还是事后解释?
写作功力:核心想法传达清晰,但论文前置动机、后置技术细节。
第 3 节(方法)密集,需要更多展示数据流的图表。
“艺术家工作流程”类比富有启发性但未形式化——通道顺序是学习的还是强加的,不清楚。
相关工作部分详尽但可以精简,为更深入的消融腾出空间。
判决:弱接收——核心贡献(通道级量化)新颖,实证结果强劲,但论文缺乏理论深度和对其由粗到细声明的严格验证。
这是扎实的增量进步,非范式转变。
要点总结
偷走量化轴:如果你在处理任何结构化数据(图像、音频、视频),考虑传统的 token 化轴是否最优。
空间块直观但非必然。
你能否沿时间、频率或语义维度量化?
码本利用率作为诊断:如果你的 VQ 模型有码本坍缩,不要只是添加正则化损失——质疑你的 token 化粒度是否匹配数据的自然结构。
CVQ 的 100% 利用率不是魔法;它是量化轴与数据变化方式对齐的标志。
由粗到细生成:即使你坚持基于块的 token,也可以强加由粗到细的顺序。
按重要性(例如通过注意力图或梯度幅度)对块排序,按该顺序生成而非光栅扫描。
本文表明生成顺序对质量很重要。