Paper: 2608.11150 Authors: Jiayu Ding, Meilu Song, Yun Chen, Wei Gao, Ge Li Categories: cs.CV
The Gap
The last two years of “language-embedded 3D Gaussian Splatting” all share one architecture. LangSplat, LEGaussians, Feature-3DGS, OpenGaussian, Gaussian Grouping: each attaches a CLIP-ish feature vector to every Gaussian (or to every instance cluster), embeds your text query into the same space, and thresholds cosine similarity. It is fast, it is elegant, and it works beautifully for “the yellow rubber duck.”
The failure mode is structural, not a matter of accuracy. A single embedding has nowhere to put a reason. Ask “which of these could I use to prop the door open,” and CLIP has to already contain a vector for door-propping-ness. Ask “the object on the shelf to the left of the sink,” and the model has to resolve a two-hop spatial chain inside a bag-of-words embedding. Ask “if the mug were removed, what would I reach for instead,” and there is nothing to compute with at all — a similarity score cannot represent a hypothetical.
The 2D world already solved its version of this: LISA and its successors put an LLM in front of SAM so the language model does the thinking and the segmenter does the pointing. Point-cloud work (Reason3D and friends) followed. 3DGS had not — largely because the field was busy on rendering quality and feature distillation, and because no benchmark existed that would penalize a method for being unable to reason. That is the double gap this paper claims: no task definition, no benchmark, no architecture.
[ PROBLEM ]
  queries that name no object:
  "something to cut bread with" / "left of the sink, on the shelf"
  "if the lamp broke, what then?"
        |
        v
[ WHY EXISTING 3DGS FAILS ]
  text -> one vector -> cosine match -> mask
  no slot for a why, no slot for a hop, no slot for a hypothetical
        |
        v
[ ASSUMPTION ]
  perception and inference are SEPARABLE
    pixels     -> structure   ( needs 3D + segmentation )
    structure  -> answer      ( needs a language model )
        |
        v
[ METHOD ]  CausalSplat
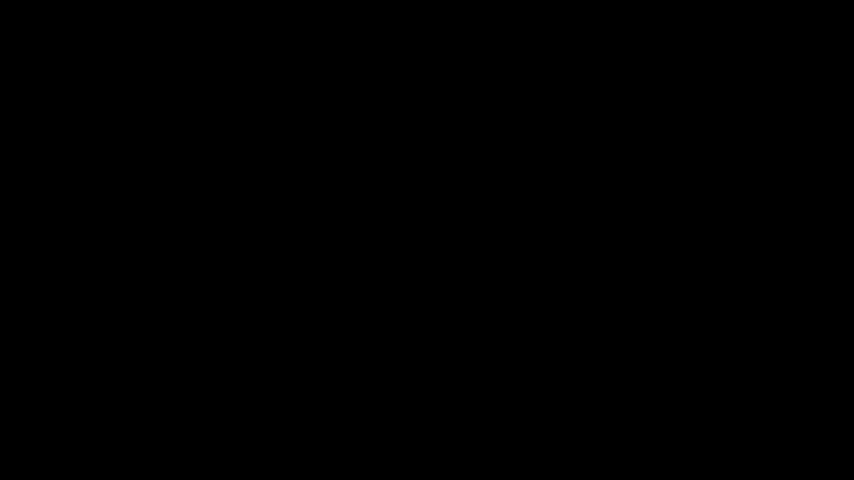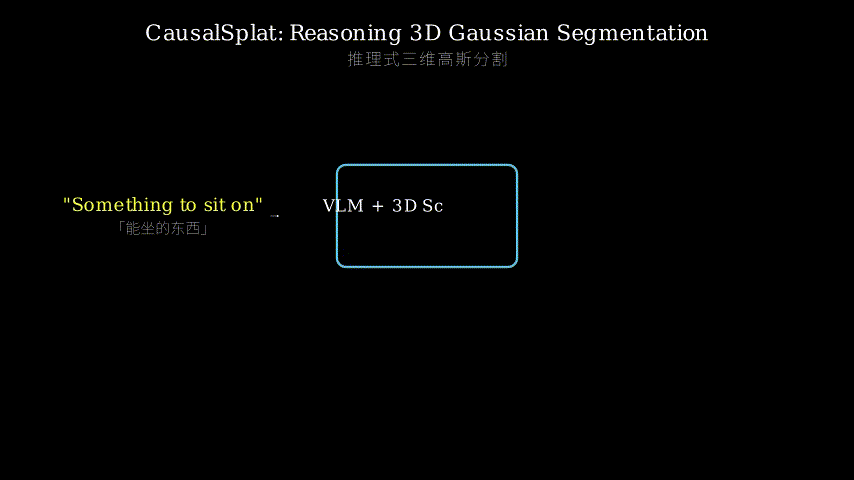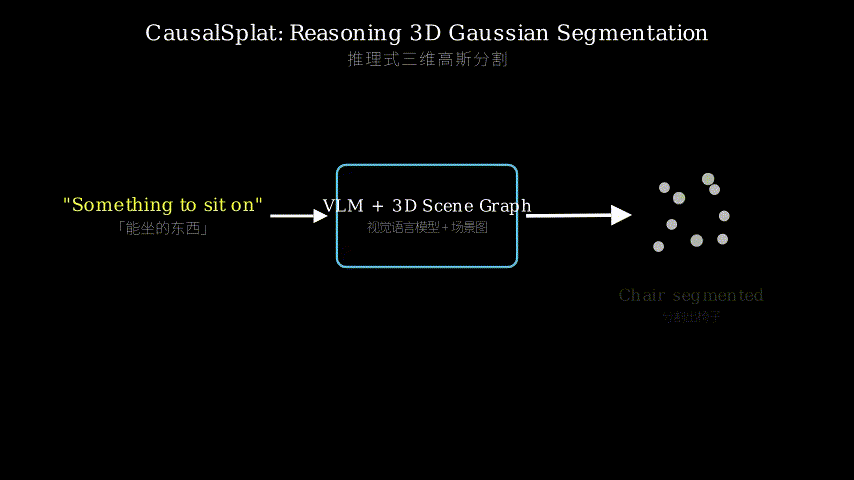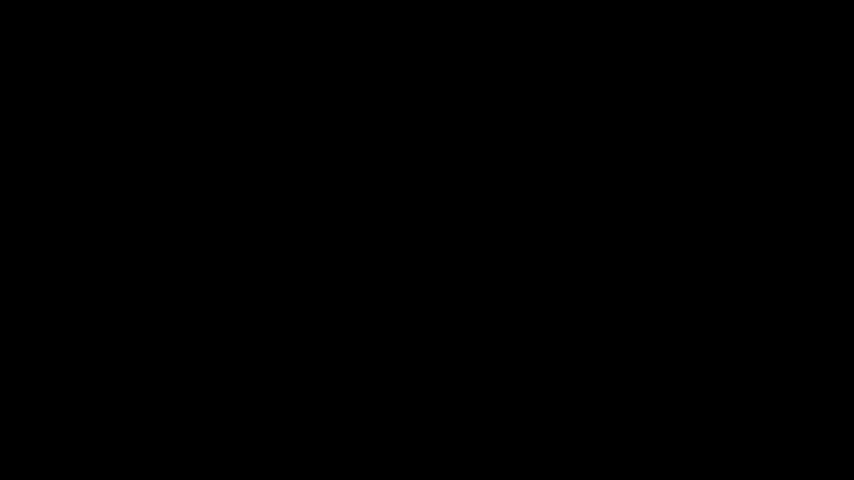
  instance Gaussians + 3D scene graph + VLM stepwise inference
        |
        v
[ EVIDENCE ]
  Causal-LERF / Causal-ScanNet : 4 reasoning axes
  prior SOTA collapses ; CausalSplat leads
  classic referring + open-vocab : no regression
        |
        v
[ CONCLUSION ]
  a symbolic graph is a sufficient bridge.
  you do not need to bake reasoning into the Gaussians.
The Increment
One sentence: Before, a 3D Gaussian scene could be *queried; after, it can be interrogated — and there are now two benchmarks that tell you whether your method can actually take a question apart.
Core Mechanism
Stage one is explicit perception, and it is mostly assembled from known parts. Posed images train the Gaussian field; a 2D segmenter (SAM-family) plus a captioner/CLIP produce per-view masks and semantics; multi-view association lifts these into instance Gaussians, so the scene stops being a soup of primitives and becomes a list of objects with identities, bounding boxes, and centroids.
Stage two is the actual contribution: those instances get promoted into a 3D scene graph. Nodes carry attributes (category, color, material, size, coordinates) and edges carry relations computed geometrically — on, inside, left_of, near, above. The graph is then *serialized into text. This is the pivot. Once the scene is a paragraph, a VLM can read it, and reasoning becomes ordinary language-model work: filter candidates by category, evaluate a spatial predicate, score affordance against commonsense, simulate the removal of an object for a counterfactual. The VLM does not output pixels or Gaussians — it outputs node IDs.
Stage three is a lookup. Node ID maps back to the exact set of Gaussian indices, which gives you a 3D mask for free and a 2D mask by rendering. Nothing differentiable connects the reasoning to the geometry, which is precisely why the design is cheap: swap in a better VLM tomorrow and the whole system improves without retraining a single Gaussian.
posed images
   |
   +--> [ 3DGS optimization ] ------> raw Gaussians ( geometry + color )
   |                                        |
   +--> [ SAM masks + CLIP / captions ]     |
              |                             |
              v                             |
     [ multi-view association ] <-----------+
              |
              v
   +--------------------------------------------+
   |  INSTANCE LAYER                            |
   |  obj_07 = ( gaussian ids, bbox, center )   |
   +--------------------------------------------+
              |
              v
   +--------------------------------------------+
   |  3D SCENE GRAPH   ( explicit / symbolic )  |
   |  node obj_07 : "ceramic mug", white,       |
   |                small, xyz = ( .. )         |
   |  edge obj_07 -on-      obj_02 ( table )    |
   |  edge obj_07 -left_of- obj_11 ( kettle )   |
   +--------------------------------------------+
              |
        serialize to text
              |
              v
  query --> [ VLM : stepwise inference ]
              |    1. narrow by category / attribute
              |    2. test spatial predicates
              |    3. score affordance vs commonsense
              |    4. run the counterfactual
              v
          node ids : ( obj_07 )
              |
              v
   [ id -> gaussian index lookup ]
              |
              +---> 3D mask
              +---> rendered 2D mask
The metaphor: this is a research library with a reference desk.
The Gaussians are the physical books on the shelves — millions of pages, spatially arranged, but you cannot ask a shelf anything. Instance lifting is binding loose pages into discrete books with spines. The scene graph is the card catalogue: one card per book, listing subject, size, and — crucially — cross-references to what sits beside it. The VLM is the reference librarian. And here is the load-bearing part: the librarian never walks the stacks. A patron says “I need something for a kid who just lost a pet,” and the librarian reasons entirely over cards, then hands you a call number. Someone else fetches the physical book.
Every property of CausalSplat falls out of that picture. Speed: reasoning over a few hundred cards is trivial compared to reasoning over millions of Gaussians. Modularity: hire a smarter librarian, no reshelving required. Counterfactuals: the librarian can say “if that book were checked out, take this one” because cards are manipulable symbols. And the failure mode is equally obvious — if the cataloguer never wrote down that a book has a torn cover, the librarian can never find “a book that needs repair.” Whatever stage one omits, stage two cannot recover. The graph is both the bridge and the bottleneck.
Key Concepts
-
Referring vs. reasoning segmentation: Referring means the query names the target — “the blue chair by the window.” A matching machine suffices. Reasoning means the query names the target only *implicitly — “somewhere I could set down a hot pan.” Nothing in that sentence is a noun you can match; you must know that trivets, stone counters, and cast-iron surfaces tolerate heat, then check which of those exist in this room. The distinction matters because a method can be state-of-the-art at the first and score near zero on the second, and no existing benchmark would have noticed.
-
The scene graph as an interface, not a representation: Most scene-graph papers treat the graph as the output — the thing you want. Here it is deliberately a *narrow waist, in the sense that IP is the narrow waist of the internet. Above it, any VLM; below it, any 3D backbone. The graph’s job is to be legible to both. That is why it is serialized to plain text rather than fed in as a learned embedding: text is the one format every language model already speaks fluently. The design cost is lossiness — the graph is a summary, and everything not in the summary is invisible upward.
-
Counterfactual query: The most interesting of the four axes. “If the glass were missing, what would you drink from?” requires holding a modified version of the scene in mind and re-answering. Similarity search cannot do this even in principle, because there is no embedding for a scene-that-isn’t. A symbolic list, on the other hand, can simply have a line deleted. This is also where the paper’s title overreaches: deleting a node and re-querying is hypothetical reasoning, not causal inference in the Pearl sense — no interventions on a structural model, no identification, no confounding. “Causal” here is branding.
Framework Shift
Before ( mainstream 3DGS + language ):

  query ---- embed ----> [ vector ]
                             |
                             |  cosine similarity
                             v
        [ millions of Gaussians carrying CLIP features ]
                             |
                             v
                           mask

  one shot. no intermediate state. nothing to inspect,
  nothing to reason over, nothing to modify.


After ( CausalSplat ):

  [ Gaussians ] --lift--> [ objects ] --relate--> [ GRAPH ]
                                                     |
                                                as plain text
                                                     |
  query -------------------------> [ VLM ] <---------+
                                      |
                                   node id
                                      |
                                      v
                            id lookup ---> mask

  two stages, with a small, human-readable symbol layer
  in the middle that you can print, debug, and edit.
From matching to deliberating: the core shift is that the query no longer touches the geometry at all — it touches a symbolic summary of the geometry, and the geometry is only consulted at the very end to convert an answer into a mask.
Expert Assessment
A caveat up front: I am working from the abstract and the architecture it implies. The abstract reports no numbers, so my remarks on experiments are about what would need to be true, not about verified results.
Problem choice: Real gap, honestly framed, but not a surprising one. The 2D lineage (LISA, 2023) and the point-cloud lineage (Reason3D and successors) both made this move already; CausalSplat is the 3DGS entry in a well-established migration. That is fine — someone has to do it, and the field genuinely lacked a benchmark that punishes non-reasoning methods. The benchmark contribution may outlast the method. Reasoning + affordance is also exactly where embodied-AI demand is heading, so the timing is right rather than early.
Method maturity: Sensible engineering more than a new idea. Every component — 3DGS, SAM, multi-view instance association, geometric relation extraction, an off-the-shelf VLM — is load-bearing but pre-existing; the contribution is the seam. The “disentangle explicit perception from implicit inference” framing is genuinely the right call, and I’d expect it to be the durable takeaway. What worries me is that the reasoning stage is likely prompt engineering rather than anything learned, which makes results a function of whichever VLM was used and hard to attribute. There is also an obvious simpler competitor: render a handful of views and hand images plus the query straight to a strong VLM, then back-project its 2D mask. That skips the graph entirely. If the paper doesn’t run that baseline, the graph’s necessity is asserted rather than demonstrated.
Experimental integrity: The structural problem is self-graded homework — the authors define the task, build both benchmarks, and win on them. That isn’t disqualifying (LISA did the same, and someone must go first), but it demands unusual care. Two specific risks. First, “current SOTA methods perform poorly” is close to tautological: LangSplat was never designed to answer “something to cut bread with,” so reporting that it fails is a category observation, not a result. The honest baseline is *query rewriting — let GPT-4 turn the implicit query into an explicit noun phrase, then feed that to LangSplat. That closes a surprising amount of the gap in the 2D literature, and if CausalSplat doesn’t beat it convincingly, the graph is decoration. Second, if the benchmark queries were LLM-generated and an LLM also solves them, there’s a circularity worth auditing; and Causal-LERF inherits LERF’s tiny scene count, so per-scene variance will be large. I’d also want the ceiling reported: accuracy given a ground-truth scene graph, which separates “reasoning is hard” from “our perception layer is lossy.”
Writing quality: The abstract is clean and the framing is crisp — “explicit structural perception vs. implicit logical inference” is a sentence reviewers will quote. The section that most likely got shortchanged is benchmark construction: who wrote the queries, how ambiguity was adjudicated, whether a question can have multiple defensible answers, and how partial credit works for counterfactuals. For a paper whose main asset may be its benchmark, that section deserves to be the longest one, and rewriting it with a full annotation protocol plus inter-annotator agreement would raise the paper a full tier. Second target: an ablation isolating the VLM’s contribution from the graph’s, so readers know what they’re actually buying.
Verdict: weak accept — a well-motivated, well-architected port of reasoning segmentation into 3DGS whose benchmark is a real service to the field, held back by modest technical novelty, self-defined evaluation, and a title that promises causality it does not deliver.
Takeaways
- Serialize structure into text as your model interface. The trick that makes this work isn’t the graph, it’s writing the graph out as plain text. Any time you need a language model to reason over non-linguistic structure — a database schema, a CAD assembly, a network topology, a codebase’s call graph — a compact text serialization is a stronger and cheaper interface than a learned projection, and it’s inspectable when things break.
- Put reasoning where it can be swapped. Because inference is decoupled from the Gaussians, upgrading the LLM upgrades the system with zero retraining. When a capability is improving fast industry-wide, architect so you can rent it rather than train it.
- Counterfactual queries are a cheap capability probe. “What if X were gone?” cannot be answered by any system that only stores similarity — it requires manipulable symbols. Use counterfactual questions as a diagnostic to reveal whether a pipeline has real structure or just embeddings, in any modality.
- The strong baseline in any reasoning-grounding task is query rewriting. Before building a reasoning module, check how far an LLM rewriting the query into your existing system’s native vocabulary gets you. Sometimes it’s most of the way, and knowing that saves months.
- The honest cost model to internalize: a summarization bottleneck buys you tractability and modularity and charges you everything the summary omitted. Decide up front what attributes your catalogue must record, because no amount of downstream intelligence recovers what was never written down.
论文: 2608.11150 作者: Jiayu Ding, Meilu Song, Yun Chen, Wei Gao, Ge Li 分类: cs.CV
缺口
过去两年「语言嵌入式 3D 高斯泼溅」的所有工作,骨架其实是同一个。 LangSplat、LEGaussians、Feature-3DGS、OpenGaussian、Gaussian Grouping:给每个高斯(或每个实例簇)挂一个 CLIP 系特征向量,把文本查询编码到同一空间,然后按余弦相似度取阈值。 快、优雅,找「黄色的小鸭子」效果极好。
但它的失效是结构性的,不是精度问题。 一个向量里没有地方安放「理由」。 你问「哪个东西能拿来抵住门」,CLIP 必须事先就把「可抵门性」编码进向量里。 你问「水槽左边那个架子上的东西」,模型得在一个近乎词袋的嵌入里解开两跳空间关系。 你问「如果杯子不在了,我会去拿什么」——这时连可计算的对象都不存在,相似度分数无法表示一个假设世界。
二维领域早就翻过这一页:LISA 及其后继把 LLM 放在 SAM 前面,语言模型负责想,分割器负责指。 点云方向(Reason3D 一路)随后跟上。 3DGS 一直没跟上,一方面因为大家在忙渲染质量和特征蒸馏,另一方面因为没有任何 benchmark 会因为「不会推理」而扣你的分。 这就是本文声称的双重缺口:没有任务定义,没有评测集,没有架构。
[ 问题 ]
  查询里根本不出现目标名词:
  "找个能切面包的" / "水槽左边、架子上那个"
  "如果台灯坏了呢?"
        |
        v
[ 现有 3DGS 为何失效 ]
  文本 -> 单个向量 -> 余弦匹配 -> mask
  没有位置放"理由",放"多跳",放"假设"
        |
        v
[ 假设 ]
  感知与推理是可分离的
    像素   -> 结构     ( 需要 3D + 分割 )
    结构   -> 答案     ( 需要语言模型 )
        |
        v
[ 方法 ]  CausalSplat
  实例化高斯 + 3D 场景图 + VLM 分步推理
        |
        v
[ 证据 ]
  Causal-LERF / Causal-ScanNet : 四个推理维度
  旧 SOTA 崩盘 ; CausalSplat 领先
  经典 referring + 开放词汇 : 不退化
        |
        v
[ 结论 ]
  一层符号图就足以做桥。
  不必把推理能力硬塞进高斯参数里。
增量
一句话:以前一个 3D 高斯场景只能被「检索」,现在它可以被「盘问」——并且终于有两个 benchmark 能告诉你,你的方法到底会不会拆解一个问题。
核心机制
第一阶段是显式感知,基本由成熟零件搭成。 带位姿的图像训练高斯场;SAM 系分割器加上 captioner/CLIP 产出每视角的掩码与语义;多视角关联把它们抬升为实例级高斯。 于是场景不再是一锅基元汤,而变成一份物体清单:每个物体有身份、包围盒、质心。
第二阶段是真正的贡献:把这些实例升格为一张 3D 场景图。
节点携带属性(类别、颜色、材质、尺寸、坐标),边携带由几何直接算出的关系——on、inside、left_of、near、above。
然后关键一步:把图序列化成文本。
一旦场景变成一段话,VLM 就能读它,推理也就退化为语言模型的日常工作:按类别筛候选、验证空间谓词、用常识给可操作性(affordance)打分、为反事实问题模拟删掉某个物体。
VLM 不输出像素,也不输出高斯,它输出节点 ID。
第三阶段只是一次查表。 节点 ID 映回精确的高斯索引集合,3D mask 白送,2D mask 渲染即得。 推理与几何之间没有任何可微连接——这恰恰是设计便宜的原因:明天换一个更强的 VLM,整个系统直接变强,一个高斯都不用重训。
带位姿图像
   |
   +--> [ 3DGS 优化 ] ---------> 原始高斯 ( 几何 + 颜色 )
   |                                  |
   +--> [ SAM 掩码 + CLIP / caption ] |
              |                       |
              v                       |
        [ 多视角关联 ] <--------------+
              |
              v
   +--------------------------------------------+
   |  实例层                                    |
   |  obj_07 = ( 高斯索引, bbox, 中心 )          |
   +--------------------------------------------+
              |
              v
   +--------------------------------------------+
   |  3D 场景图   ( 显式 / 符号 )                |
   |  node obj_07 : "陶瓷杯", 白色,              |
   |                小, xyz = ( .. )            |
   |  edge obj_07 -on-      obj_02 ( 桌子 )      |
   |  edge obj_07 -left_of- obj_11 ( 水壶 )      |
   +--------------------------------------------+
              |
        序列化为文本
              |
              v
  查询 --> [ VLM : 分步推理 ]
              |    1. 按类别 / 属性收窄
              |    2. 检验空间谓词
              |    3. 常识 + affordance 打分
              |    4. 执行反事实
              v
          节点 id : ( obj_07 )
              |
              v
   [ id -> 高斯索引 查表 ]
              |
              +---> 3D mask
              +---> 渲染 2D mask
核喻:这是一座带咨询台的研究型图书馆。
高斯是书架上的实体书:几百万页,空间上排列整齐,但你没法「问」一个书架任何问题。 实例化就是把散页装订成有书脊的一本本书。 场景图是卡片目录:一本书一张卡,写着主题、开本,最关键的是写着旁边放着什么(交叉引用)。 VLM 是咨询台的图书馆员。 承重的那一句在这里:这位馆员从不走进书库。 读者说「我想找点东西,给一个刚失去宠物的孩子」,馆员完全在卡片上完成推理,然后递给你一个索书号。 去书架上取书是另一个人的事。
CausalSplat 的每个性质都能从这张图里推出来。 速度:在几百张卡片上推理,与在几百万个高斯上推理完全不是一个量级。 模块化:换一个更聪明的馆员,书库一本都不用动。 反事实:馆员能说「那本要是被借走了,就拿这本」,因为卡片是可以操作的符号。 而失效模式同样一目了然——如果编目员当初没在卡上写「这本书封面破了」,馆员永远找不到「需要修补的书」。 第一阶段漏掉什么,第二阶段就永远补不回来。 这张图既是桥,也是瓶颈。
关键概念
-
指代分割 vs 推理分割:指代(referring)是查询里点了名的——「窗边那把蓝椅子」,匹配机器足够用。 推理(reasoning)是查询只隐含目标——「有什么地方能放这口烫锅」。 这句话里没有任何可匹配的名词,你必须先知道隔热垫、石台面、铸铁面耐热,再去检查这个房间里存在哪一种。 这个区分要紧,是因为一个方法可以在前者上做到 SOTA、在后者上接近零分,而此前没有任何 benchmark 会发现这件事。
-
场景图是接口,不是表示:多数场景图论文把图当成输出,图本身就是目的。 这里它被刻意做成一条细腰——就像 IP 是互联网的细腰。 腰之上可以插任何 VLM,腰之下可以换任何 3D 骨干,图的职责只是让两边都读得懂。 这也解释了为什么要序列化成朴素文本而不是喂一个学出来的 embedding:文本是所有语言模型天生流利的唯一格式。 代价是有损——图是摘要,凡不在摘要里的信息,对上层完全不可见。
-
反事实查询:四个维度里最有意思的一个。 「如果玻璃杯不在了,你会用什么喝水」要求在脑中持有一个被修改过的场景再作答。 相似度检索原理上做不到,因为「不存在的那个场景」没有嵌入。 而一份符号清单只需删掉一行。 这也是本文标题用力过猛之处:删节点再查询是假设性推理,不是 Pearl 意义上的因果推断——没有对结构模型做干预,没有可识别性,没有混淆处理。 这里的 “Causal” 是品牌名。
框架转变
之前 ( 主流 3DGS + 语言 ):

  查询 ---- 编码 ----> [ 向量 ]
                          |
                          |  余弦相似度
                          v
        [ 数百万个携带 CLIP 特征的高斯 ]
                          |
                          v
                        mask

  一步到位。没有中间态。没东西可看,
  没东西可推理, 没东西可修改。


之后 ( CausalSplat ):

  [ 高斯 ] --抬升--> [ 物体 ] --建关系--> [ 场景图 ]
                                              |
                                          序列化文本
                                              |
  查询 ------------------------> [ VLM ] <----+
                                    |
                                 节点 id
                                    |
                                    v
                              查表 ---> mask

  两段式, 中间夹着一层小而可读的符号层,
  可以打印、可以调试、可以手改。
一句话:从匹配到斟酌,核心转变是查询再也不碰几何——它碰的是几何的符号摘要,几何只在最后一步被调用,用来把答案换成 mask。
专家评审
先说清一件事:我读到的是摘要与它蕴含的架构。 摘要没给任何数字,所以下面关于实验的话是「什么条件必须成立」,不是对已验证结果的判断。
选题眼光:真缺口,表述也诚实,但不算意外。 二维一脉(LISA,2023)和点云一脉(Reason3D 及后继)都已经走过这一步,CausalSplat 是这场迁移在 3DGS 上的那一格。 这没什么不好,总得有人做,而且领域确实缺一个会惩罚「不会推理」的评测集。 benchmark 这份贡献很可能比方法活得更久。 推理 + affordance 也正是具身智能需求的方向,时机算合适而非过早。
方法成熟度:更像扎实的工程集成,而非新想法。 3DGS、SAM、多视角实例关联、几何关系抽取、现成 VLM——每个部件都承重,但都是既有的;贡献在接缝处。 「显式感知与隐式推理解耦」这个提法本身是对的,我认为这会是最耐久的收获。 让我不安的是推理段大概是 prompt 工程而非学出来的,于是结果强烈依赖用了哪个 VLM,功劳难以归因。 还有一个明显的更简单对手:渲染若干视角,把图像加查询直接丢给一个强 VLM,再把它的 2D mask 反投影回去——整个图都不需要。 如果论文没跑这条基线,那么「图是必要的」是断言,不是论证。
实验诚意:结构性问题是自己出题自己判卷——任务是作者定的,两个 benchmark 是作者建的,赢的也是作者。 这不构成否决(LISA 当年同样如此,总得有人先开局),但要求格外小心。 两个具体风险。 其一,「现有 SOTA 表现很差」几乎是同义反复:LangSplat 从设计上就没打算回答「找个能切面包的」,报告它失败是范畴观察,不是结果。 真正诚实的基线是查询重写——让 GPT-4 把隐式查询改写成显式名词短语,再喂给 LangSplat。 在二维文献里这一招能补掉相当大一块差距;如果 CausalSplat 不能明确胜过它,那张图就只是装饰。 其二,如果 benchmark 的问题是 LLM 生成的、解题的又是 LLM,这里的循环性需要审计;而 Causal-LERF 继承了 LERF 极少的场景数,逐场景方差会很大。 我还想看到天花板数字:给定真值场景图时的准确率,这能把「推理本身难」和「我们的感知层有损」分开。
写作功力:摘要干净,提法锋利,「explicit structural perception vs implicit logical inference」是审稿人会引用的那类句子。 最可能被省笔墨的是 benchmark 构建那一节:问题谁写的、歧义如何裁定、一个问题是否可以有多个站得住的答案、反事实题怎么给部分分。 对一篇主要资产可能就是 benchmark 的论文,这节理应是全文最长的一节;补上完整标注协议与标注者一致性,整篇能升一档。 第二个改写目标:把 VLM 的贡献和场景图的贡献拆开做消融,让读者知道自己买的到底是什么。
判决:弱接收 —— 动机清楚、架构合理地把推理分割搬进了 3DGS,benchmark 对领域是实打实的服务;但技术新意有限、评测自定自评,且标题许诺了它并未交付的因果性。
要点总结
- 把结构序列化成文本,当作模型接口。让这套东西跑起来的不是「图」,而是「把图写成纯文本」。 任何时候你需要语言模型对非语言结构做推理——数据库 schema、CAD 装配体、网络拓扑、代码调用图——一份紧凑的文本序列化比一个学出来的投影更强、更便宜,而且出问题时肉眼可查。
- 把推理放在可替换的位置。因为推理与高斯解耦,换个更强的 LLM 就等于系统升级,零重训。 当某项能力正在全行业快速变强时,架构上要让自己能「租」而不是「训」。
- 反事实问题是廉价的能力探针。「如果 X 不在了呢」是任何只存相似度的系统原理上答不出的,它要求可操作的符号。 在任何模态里,都可以用反事实提问来体检一条流水线到底有真结构还是只有嵌入。
- 任何推理式定位任务的强基线都是查询重写。在动手做推理模块之前,先量一下「让 LLM 把查询改写成现有系统母语」能走多远。 有时它能走掉大半,知道这件事能省几个月。
- 值得内化的成本模型:一个摘要式瓶颈,买给你的是可计算性与模块化,收你的是摘要漏掉的一切。 所以要在最前面就决定你的目录必须记录哪些属性——下游多聪明都救不回从未被写下来的东西。