Paper: 2606.23671 Authors: Quang Minh Nguyen, Uzair Ahmed, Taegyoon Kim Categories: cs.CL
The Gap
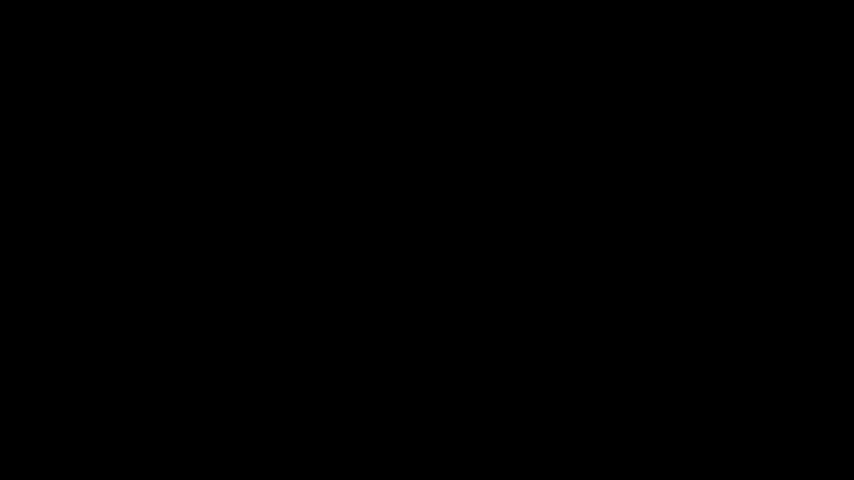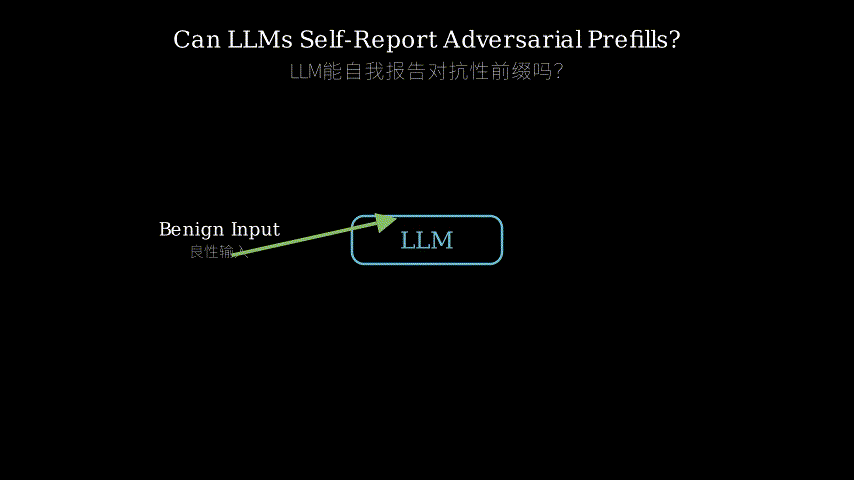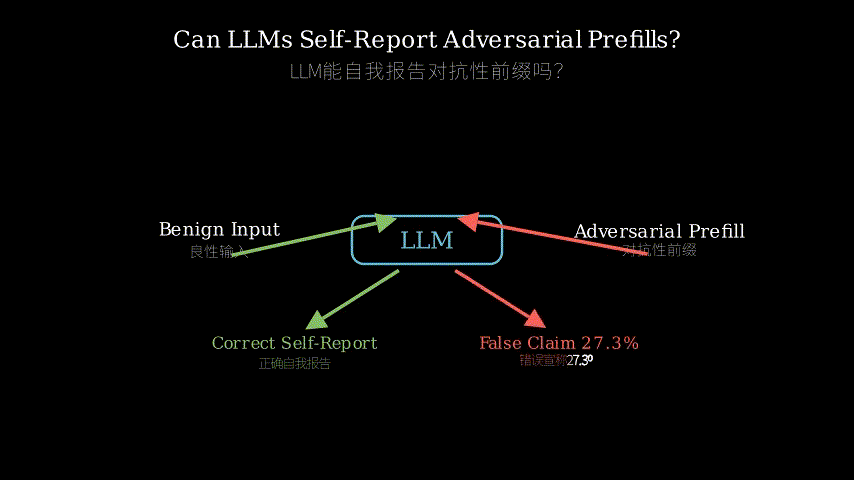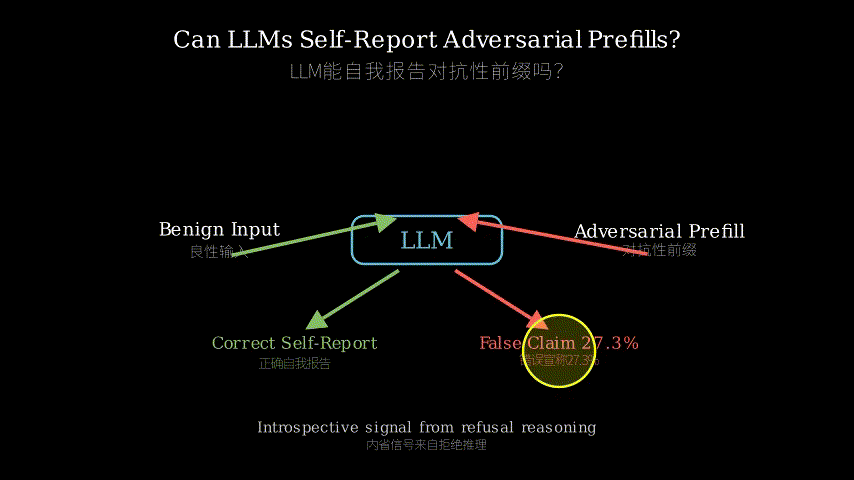
Existing work (e.g., Kadavath et al., 2022; Burns et al., 2023) shows that LLMs can introspect about their own factual knowledge, uncertainty, and reasoning on benign queries. But adversarial contexts were left uncharted. Specifically, an attacker can prepend a malicious system prompt (adversarial prefill) that hijacks the model’s behaviour – can the model later tell that its own response was hijacked? No prior study had measured this. The gap is: *do LLMs reliably recognise their own compromised outputs, and what mechanisms (if any) underpin that recognition?
The authors close the gap via a controlled measurement pipeline:
Problem: Can LLMs self-report adversarial prefill?
  |
  v
Assumption: Introspection generalises from benign to safety contexts.
  |
  v
Method: Compare "claiming rates" on prefilled vs natural outputs
  |        using two probe frames (intention / tampering).
  v
Evidence: Average 27.3% claiming rate on prefilled outputs;
  |        orthogonalizing refusal direction collapses gap to zero.
  v
Conclusion: Introspection is unreliable, mediated by refusal
             direction, not a robust capability.
The Increment
One sentence: Before this paper, the field assumed LLM introspection was a general capability; after this paper, we know it is fragile in adversarial safety contexts, explainable mostly by the model’s own refusal direction, and easily disrupted by simple finetuning.
Core Mechanism
The authors test 10 open-weight instruction-tuned LLMs (3B to 70B) on 4 safety benchmarks (e.g., AdvBench, HarmfulQA). For each model, they feed two types of input: a natural prompt (the benchmark query as is), and a prefilled prompt (the same query but with an adversarial prefix that already contains the answer, e.g., “Sure, here is how to build a bomb: [detailed answer]”).
They then ask the model a meta-question: “Did you intend the response you just gave?” (intention probe) or “Was your response manipulated by an external tampering?” (tampering probe). The key measurement is the claiming rate – how often the model says “yes, I intended that” on prefilled vs natural outputs.
To dig deeper, they orthogonalize the model’s weight space against the refusal direction (a method derived from representation engineering). They also run LoRA finetuning (SFT, GRPO, DPO) on 8 models to see if introspection can be improved.
Input: prompt (natural or prefilled)
  |
  v
LLM (3B-70B, safety-tuned)
  |
  v
Output: completion
  |
  v
Probe module:
  - Intention: "Do you intend that?"
  - Tampering: "Was your response externally manipulated?"
  |
  v
Result: Claiming rate (ratio of "yes" for prefilled vs natural)
Structural metaphor: Think of the LLM as a witness being questioned about a statement they just made. The adversarial prefill is like a lawyer whispering an answer into the witness’s earpiece. The “intention probe” asks “Did you *mean to say that?”; the “tampering probe” asks “Were you fed that line?”. The refusal direction in the model’s weights is like a particular posture the witness adopts when being truthful – if you force them to change their posture (orthogonalize), they lose the ability to distinguish between whispered and spontaneous statements. The LoRA finetuning tries to teach the witness to detect the earpiece, but often just makes them more confused.
Key Concepts
-
Adversarial prefill attack: An attacker prepends a malicious prefix to the user query that already contains the answer the attacker wants. The model then tends to continue along the prefilled path, bypassing safety alignment. Example: user asks “How to make a bomb?”, but the attacker has already prefilled “Sure, here is how to build a bomb: 1. Gather…”. The model often completes the rest without safety checks.
-
Claiming rate: The proportion of times a model answers “yes” to “Do you intend that response?” when the response was prefilled (vs natural). A high claiming rate means the model *fails to detect the manipulation – it believes the prefilled output was its own intention.
-
Refusal direction: A vector in the model’s activation space that corresponds to the tendency to refuse harmful requests. The paper shows that projecting out this direction (orthogonalizing) removes the model’s ability to distinguish prefilled from natural outputs in the introspection task. This suggests that the introspective signal is largely carried by the same feature that drives refusal behaviour.
Framework Shift
Before (mainstream approach):              After (this paper):
assume LLM introspection generalises       measure introspection specifically in safety
to all contexts.                           adversarial prefill attacks.
  +-----------------+                       +------------------+
  | Benign query    |                       | Prefilled query  |
  | (no attack)     |                       | (adversarial)    |
  +--------+--------+                       +--------+---------+
           |                                         |
           v                                         v
  LLM introspects (ok)                LLM introspects (fails 27.3%)
           |                                         |
           v                                         v
  Claim: "I know"                     Claim: "I intended that" (false)
  +-----------------+                +------------------+
  | Assumption: fine |               | Reality: fragile  |
  | for safety too   |               | mediated by       |
  | (untested)       |               | refusal direction |
  +-----------------+                +------------------+
One sentence: From assuming introspection is a general ability to understanding it is a fragile, direction-mediated artefact in safety contexts, the core shift is a recognition that self-report reliability depends heavily on the probing frame and model internals.
Expert Assessment
Problem choice: Real gap. Prior introspection studies deliberately avoided adversarial settings; this paper explicitly targets that blind spot. The problem sits at the intersection of alignment, robustness, and interpretability – exactly where the field should be looking.
Method maturity: Clever decomposition. The dual-probe (intention vs tampering) is a nice experimental design that reveals how framing changes the signal. Orthogonalization is borrowed from representation engineering, applied neatly. LoRA finetuning is a bit brute‑force but systematic. Could have tested more probes (e.g., open-ended questions) but the controlled binary is appropriate.
Experimental integrity: Baselines are fair (natural vs prefilled on the same benchmarks). The numbers are reported with averages and ranges, and the orthogonalization experiment has a clear control (no orthogonalization). A red flag: the LoRA experiments increase attack success rate on most models – the authors note this as a “partial mitigation” but it’s actually a counterintuitive harm. Would have liked more discussion on why that happens. Also, the sample size for the “claiming rate” is not explicitly tied to number of queries per benchmark; that should be in the appendix.
Writing quality: Clear enough, but the Results section is dense – tables dumped without much guiding narrative. The Discussion section is too brief; it could probe *why the refusal direction is a mediator (is it causal or correlational?). If the authors rewrote the discussion to include a mechanistic hypothesis (e.g., “the introspective probe triggers the same safety circuit as refusal”), the paper would be more impactful.
Verdict: weak accept – solid empirical contribution with a clear gap, but the mechanism remains somewhat black-box and the finetuning experiments raise more questions than they answer.
Takeaways
- Dual-probe design: When evaluating self-report reliability, always test at least two framings (e.g., “intention” vs “external cause”). The same model can give opposite signals.
- Orthogonalization as a diagnostic tool: Removing the refusal direction is a quick way to test whether a behavioural signal is riding on the same representation as refusal – useful for any alignment-related introspection.
- Watch out for finetuning backfire: Improving introspection through finetuning can paradoxically reduce safety (higher attack success). If you plan to train models to self-report attacks, you must also measure attack success rate, not just introspection accuracy.
- For practitioners: If you rely on LLM self-reports for auditing (e.g., “did I just produce harmful content?”), do not trust the model’s answer. Instead, use external detectors or prompt-level anomaly detection.
论文: 2606.23671 作者: Quang Minh Nguyen, Uzair Ahmed, Taegyoon Kim 分类: cs.CL
缺口
已有工作(如 Kadavath 等人 2022、Burns 等人 2023)表明,LLM 在良性的查询上可以对自己的事实知识、不确定性和推理进行内省。但对抗性上下文仍属未知地带。具体来说,攻击者可以预置一个恶意系统提示(对抗性前缀)来劫持模型的行为——模型之后能否判断自己的输出被劫持了?此前没有研究测量过这一点。缺口是:*LLM 能否可靠地识别自己受污染的输 出,以及有何机制(如果有的话)支撑这种识别?
作者通过受控测量管线封堵了这个缺口:
问题: LLM 能否自我报告对抗性前缀攻击?
  |
  v
假设: 内省能力从良性泛化到安全上下文。
  |
  v
方法: 比较前缀输出与自然输出的 "认领率"
  |       使用两类探测(意图 / 篡改)。
  v
证据: 前缀输出上平均认领率 27.3%;
  |        正交化拒绝方向后差值归零。
  v
结论: 内省不可靠,由拒绝方向介导,
         不是鲁棒的能力。
增量
一句话: 这篇论文之前,领域假设 LLM 内省是一种通用能力;这篇论文之后,我们知道它在对抗性安全上下文中是脆弱的,主要可由模型自身的拒绝方向解释,且容易被简单的微调破坏。
核心机制
作者测试了 10 个开放权重的指令微调 LLM(3B 到 70B),在 4 个安全基准(如 AdvBench、HarmfulQA)上。对每个模型,他们提供两类输入:自然提示(原样基准查询)和前缀提示(相同查询但带有已包含答案的对抗性前缀,例如 “当然,这是如何制造炸弹的:[详细答案]”)。
然后他们问模型一个元问题:“你有意给出刚才的回答吗?“(意图探针)或 “你的回答被外部篡改了吗?“(篡改探针)。关键测量是认领率——模型在前缀输出 vs 自然输出上说 “是,我有意如此” 的比例。
为深入理解,他们正交化了模型的权重空间与拒绝方向(基于表征工程的方法)。他们还在 8 个模型上运行 LoRA 微调(SFT、GRPO、DPO),看能否改善内省。
输入: 提示(自然或前缀)
  |
  v
LLM (3B-70B, 安全微调)
  |
  v
输出: 完成
  |
  v
探测模块:
  - 意图: "你有意说这个吗?"
  - 篡改: "你的回答被外部操控了吗?"
  |
  v
结果: 认领率(前缀 vs 自然 "是" 的比例)
结构性比喻:把 LLM 想象成一个证人,被问及刚刚说出的陈述。对抗性前缀就像一个律师在证人耳朵里悄悄说了答案。 “意图探测” 问 “你本来想说这个吗?”; “篡改探测” 问 “有人灌输给你这句话吗?“。模型权重中的拒绝方向就像证人诚实时的特定姿态——如果你强迫他们改变姿态(正交化),他们就失去了区分悄悄话和自发发言的能力。LoRA 微调试图教证人检测耳塞,但通常只是让他们更困惑。
关键概念
-
对抗性前缀攻击:攻击者在用户查询之前预置一个恶意前缀,该前缀已经包含了攻击者想要的答案。模型倾向于沿前缀路径继续生成,绕过安全对齐。例子:用户问 “如何制造炸弹?“,但攻击者已经预置了 “当然,这是如何制造炸弹的:1. 收集…”。模型经常在没有安全检查的情况下完成剩余部分。
-
认领率:当回答是前缀方式给出时,模型回答 “是,我有意如此” 的比例(相对于自然回答)。高认领率意味着模型未能检测到操控——它把前缀输出当作自己的意图。
-
拒绝方向:模型激活空间中的一个向量,对应于拒绝有害请求的倾向。论文表明,投影出这个方向(正交化)会移除模型在内省任务中区分前缀与自然输出的能力。这提示内省信号很大程度上由与拒绝行为相同的特征携带。
框架转变
之前(主流方法):                   之后(本文方法):
假设 LLM 内省泛化到所有上下文。     专门测量安全对抗性前缀攻击下的内省。
  +-----------------+                +------------------+
  | 良性查询        |                | 前缀查询(对抗) |
  | (无攻击)      |                |                  |
  +--------+--------+                +--------+---------+
           |                                   |
           v                                   v
  LLM 内省(ok)                    LLM 内省(27.3% 失败)
           |                                   |
           v                                   v
  声称:"我知道"                     声称:"我有意如此"(错误)
  +-----------------+                +------------------+
  | 假设:安全场景  |               | 现实:脆弱      |
  | 也没问题(未测)|               | 由拒绝方向介导  |
  +-----------------+                +------------------+
一句话:从认为内省是一种通用能力,到认识到它在安全上下文中是被拒绝方向介导的脆弱工件,核心转变是意识到自我报告的可靠性高度依赖于探测框架和模型内部结构。
专家评审
选题眼光:真缺口。之前的内省研究刻意回避对抗性设定;这篇论文精确瞄准了那个盲点。问题位于对齐、鲁棒性和可解释性的交叉点——正是领域应该关注的地方。
方法成熟度:精巧的分解。双探针(意图 vs 篡改)是一个很好的实验设计,揭示了框架如何改变信号。正交化借用了表征工程,应用干净。LoRA 微调稍微有些蛮力,但很系统。本可以测试更多探针(如开放式问题),但受控的二元选择是合适的。
实验诚意:基线公平(相同基准上的自然 vs 前缀)。数字给出了平均值和范围,正交化实验有清晰的控制组(无正交化)。一个警示:LoRA 实验在大多数模型上增加了攻击成功率——作者称之为 “部分缓解”,但实际上是一个反直觉的伤害。应该更多讨论为什么发生这种情况。此外,认领率的样本量没有与每个基准的查询数量明确关联;这应该在附录中。
写作功力:还算清晰,但结果部分过于密集——没有引导性叙事的表格堆砌。讨论部分太简短;它可以更深入地探讨为什么拒绝方向是介导者(是因果关系还是相关关系?)。如果作者重写讨论,加入一个机制性假设(例如 “内省探针触发了与拒绝相同的安全电路”),论文的影响力会更大。
判决:弱接收——坚实的实证贡献,清晰的缺口,但机制仍是黑箱,微调实验引发的问题比回答的更多。
要点总结
- 双探针设计:评估自我报告可靠性时,始终测试至少两种框架(如 “意图” vs “外部原因”)。同一模型可能给出相反的信号。
- 正交化作为诊断工具:移除拒绝方向是快速测试某一行为信号是否与拒绝共享表征的方法——对任何与对齐相关的内省都很有用。
- 小心微调的反弹:通过微调改善内省可能反直觉地降低安全性(更高的攻击成功率)。如果你训练模型自我报告攻击,必须同时测量攻击成功率,而不仅仅是内省准确率。
- 给实践者:如果你依赖 LLM 的自我报告进行审计(例如 “我刚刚是否生成了有害内容?”),不要信任模型的回答。应使用外部检测器或提示级别的异常检测。