Paper: 2605.22819 Authors: Jihan Yang, Zifan Zhao, Xichen Pan, Shusheng Yang, Junyi Zhang, Bingyi Kang, Hu Xu, Saining Xie Categories: cs.CV
The Gap
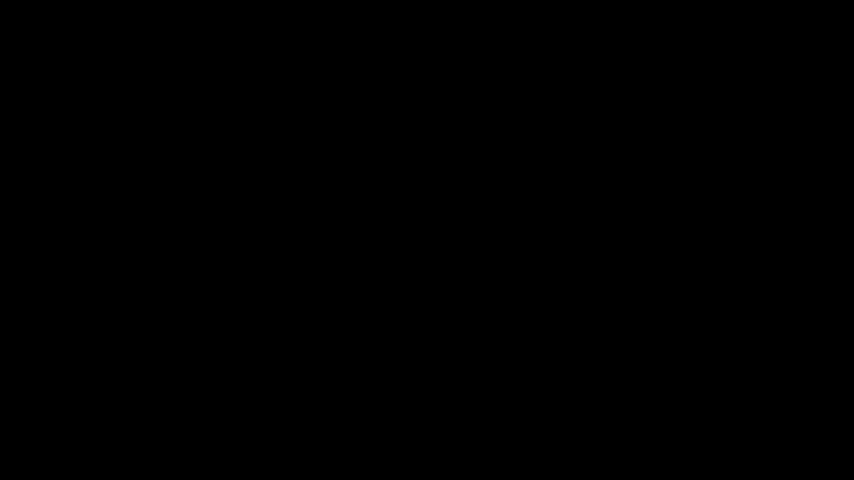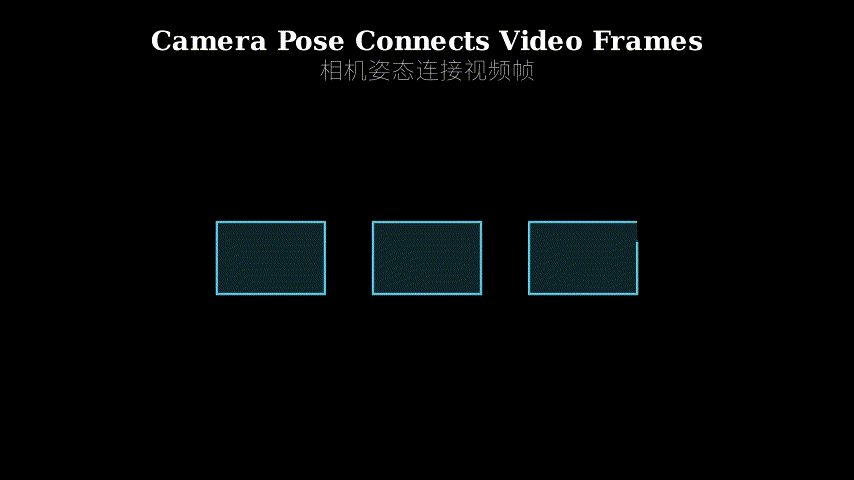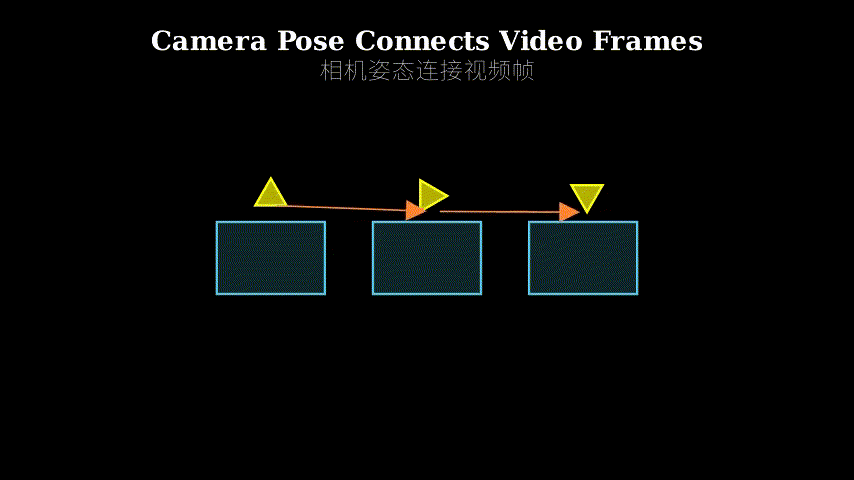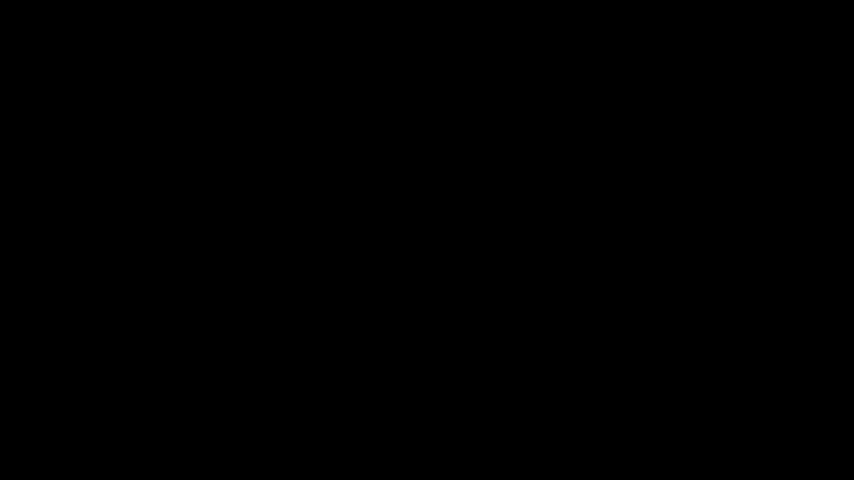
Current video MLLMs (like VideoLLaMA, Video-ChatGPT, LLaVA-Video) treat video frames as independent 2D images. They process each frame through a vision encoder, extract visual tokens, and feed them to a language model. This works for recognizing objects or actions, but fails when the question requires understanding where the camera is or how objects relate in 3D space. The models lack a shared spatial coordinate frame that ties observations together across time.
Prior work either ignores geometry entirely (pure vision-language models) or requires explicit 3D reconstruction (NeRF-based methods, which are slow and brittle). The gap: no lightweight way to inject spatial awareness into video LLMs without abandoning their end-to-end trainable architecture.
Problem: Video frames processed as isolated 2D snapshots
         |
         v
Assumption: Camera pose defines a shared 3D coordinate frame
         |
         v
Method: Add learnable camera tokens + pose regression head
         |
         v
Evidence: +4.5-6.5% on spatial reasoning, SOTA pose estimation
         |
         v
Conclusion: Pose is a fundamental signal for video understanding
The Increment
One sentence: Before this paper, video LLMs saw frames as disconnected images; after, they track where the camera is in 3D space, improving spatial reasoning and general video QA.
Core Mechanism
Cambrian-P extends a standard video MLLM (Cambrian-1) with two additions. First, for each frame, it inserts a learnable camera token into the sequence of visual tokens. This token is trained to encode the camera’s 6DoF pose (3D position + 3D orientation). Second, it attaches a pose regression head that predicts the camera’s extrinsic matrix from the camera token’s representation.
During training, the model sees video frames paired with ground-truth camera poses (from ScanNet or pseudo-labels from DROID-SLAM). The pose regression loss forces the camera token to capture geometric information. Crucially, the camera token is inserted before the language model, so pose information flows into the model’s reasoning process, not just as a side task.
The sampling scheme matters: instead of uniformly sampling frames, Cambrian-P uses pose-aware sampling that prioritizes frames with diverse viewpoints. This ensures the model sees meaningful camera motion, not redundant views.
Video frames --> Vision Encoder --> Visual tokens
                                         |
                                         v
                    [Camera token] <-- Learnable embedding
                                         |
                                         v
                    Pose regression head --> 6DoF pose
                                         |
                                         v
                    Visual tokens + Camera token --> LLM --> Answer
Think of the camera token as a GPS tracker embedded in the video stream. Imagine you’re watching a video of someone walking through a building. Each frame shows a different view, but without knowing where the camera moved, you can’t reconstruct the layout. The camera token is like a GPS device that records “I’m at position (x, y, z) facing direction (roll, pitch, yaw)” for each frame. The pose regression head is the GPS receiver that decodes this signal. The language model, seeing both the images and the GPS log, can now answer “Is the door on the left or right?” because it knows the camera turned 90 degrees between frames.
Key Concepts
-
Camera pose (6DoF): A camera’s position and orientation in 3D space, represented by 6 numbers: 3 for translation (x, y, z coordinates) and 3 for rotation (roll, pitch, yaw angles, or equivalently a rotation matrix). Example: If you’re standing in a room, your position might be (2m, 3m, 1.5m) from a corner, and you’re facing 45 degrees left of north. This 6DoF pose defines a coordinate frame that relates what you see to the room’s geometry. In video, knowing the pose of each frame lets you triangulate object positions and understand spatial relationships.
-
Learnable camera token: A trainable embedding vector inserted into the sequence of visual tokens. Unlike fixed positional encodings, this token is optimized end-to-end to encode camera pose information. Think of it as a “slot” in the input sequence reserved for geometric metadata. The model learns to fill this slot with a representation that, when passed through the pose regression head, predicts the correct 6DoF pose. Because it’s part of the input to the language model, the LLM can attend to it when reasoning about spatial questions.
-
Pose-aware sampling: A frame sampling strategy that selects frames based on camera motion, not just time. Standard uniform sampling picks every Nth frame, which often yields redundant views (e.g., 10 frames of a static scene). Pose-aware sampling measures the distance between camera poses (translation + rotation) and selects frames that maximize viewpoint diversity. This ensures the model sees meaningful geometric variation, making pose supervision more effective.
Framework Shift
Before (mainstream approach):        After (this paper):

Video --> [Frame 1] [Frame 2] ...    Video --> [Frame 1 + Pose 1] [Frame 2 + Pose 2] ...
              |          |                        |                    |
              v          v                        v                    v
          Vision     Vision                   Vision              Vision
          Encoder    Encoder                  Encoder             Encoder
              |          |                        |                    |
              v          v                        v                    v
          [Tokens]   [Tokens]                [Tokens]            [Tokens]
              |          |                        |                    |
              +----------+                        +----[Camera]----[Camera]
                    |                                  Token        Token
                    v                                      |            |
                   LLM                                     v            v
                    |                                  Pose Head    Pose Head
                    v                                      |            |
                 Answer                                    v            v
                                                       [6DoF Pose]  [6DoF Pose]
                                                            |            |
                                                            +------------+
                                                                 |
                                                                 v
                                                                LLM
                                                                 |
                                                                 v
                                                              Answer
From treating frames as isolated images to embedding each frame in a shared 3D coordinate system, the core shift is from 2D pattern matching to 3D spatial reasoning.
Expert Assessment
Problem choice: Real gap. Video LLMs genuinely struggle with spatial reasoning (e.g., “Which object is closer to the camera?”), and the field has largely ignored camera pose as a signal. The problem sits at the intersection of vision-language models and 3D vision—timely given the push toward embodied AI and robotics applications.
Method maturity: Clever insight, not brute force. Adding a learnable token and a regression head is lightweight (minimal parameter overhead) and integrates cleanly into existing architectures. The pose-aware sampling is a nice touch that shows the authors thought about data efficiency. However, the reliance on pseudo-labels from DROID-SLAM for in-the-wild video is a bit hand-wavy—SLAM can fail or drift, and the paper doesn’t deeply analyze how noisy poses affect training.
Experimental integrity: Baselines are fair (they compare against strong video LLMs like LLaVA-Video and Qwen2-VL). The 4.5-6.5% gains on VSI-Bench are substantial, and the generalization to 8 other benchmarks is convincing. The SOTA pose estimation on ScanNet is a nice byproduct that validates the learned representations. One red flag: the paper claims pose helps “beyond spatial reasoning” by improving general video QA, but the mechanism is unclear. Is the model learning better temporal representations, or is this just a regularization effect? More ablation would help.
Writing quality: The abstract and introduction are crisp. The method section is clear but could use a diagram showing the full architecture (the current figures focus on results). The related work section is thin—it mentions NeRF and SLAM but doesn’t engage with recent work on 3D-aware vision-language models (e.g., 3D-LLM, LEO). The discussion of failure cases is missing entirely. Rewriting Section 4.3 (ablations) to include failure analysis would elevate the paper.
Verdict: weak accept — Solid contribution with clear gains, but the mechanism behind generalization to non-spatial tasks needs deeper investigation, and the reliance on pseudo-labels is a potential weakness.
Takeaways
-
Learnable tokens as information channels: Instead of hardcoding metadata (like pose) into the input, use learnable tokens that the model optimizes to encode that information. This pattern transfers to other domains—e.g., adding a “lighting token” for image editing or a “speaker token” for multi-speaker audio.
-
Pose-aware sampling for video: If your task involves geometry or motion, don’t sample frames uniformly. Measure the distance in pose space (or feature space) and prioritize diversity. This applies to video captioning, action recognition, or any task where redundant frames waste compute.
-
Auxiliary tasks as regularizers: The pose regression head is nominally a side task, but it forces the model to learn better representations. This is a general trick: add a lightweight auxiliary loss that aligns with your downstream task’s structure (e.g., depth prediction for 3D reasoning, next-frame prediction for temporal modeling).
-
Pseudo-labels from classical methods: DROID-SLAM provides noisy but useful pose labels for in-the-wild video. This shows that classical geometry (SLAM, SfM) can bootstrap learning-based models. If you’re working on a task where ground-truth labels are scarce, consider whether a classical algorithm can generate pseudo-labels at scale.
论文: 2605.22819 作者: Jihan Yang, Zifan Zhao, Xichen Pan, Shusheng Yang, Junyi Zhang, Bingyi Kang, Hu Xu, Saining Xie 分类: cs.CV
缺口
当前的视频多模态大模型(如VideoLLaMA、Video-ChatGPT、LLaVA-Video)把视频帧当作独立的2D图像处理。
它们把每一帧送入视觉编码器,提取视觉token,再喂给语言模型。
这对识别物体或动作有效,但当问题需要理解”相机在哪里”或”物体在3D空间中如何关联”时就失效了。
模型缺少一个共享的空间坐标系来把不同时刻的观测联系起来。
此前的工作要么完全忽略几何(纯视觉-语言模型),要么需要显式的3D重建(基于NeRF的方法,速度慢且脆弱)。
缺口在于:没有轻量级的方法能在不放弃端到端可训练架构的前提下,向视频大模型注入空间感知能力。
问题:视频帧被当作孤立的2D快照处理
         |
         v
假设:相机姿态定义了共享的3D坐标系
         |
         v
方法:添加可学习的相机token + 姿态回归头
         |
         v
证据:空间推理+4.5-6.5%,姿态估计达到SOTA
         |
         v
结论:姿态是视频理解的基础信号
增量
一句话: 这篇论文之前,视频大模型把帧当作断开的图像;
之后,它们能追踪相机在3D空间中的位置,提升了空间推理和通用视频问答能力。
核心机制
Cambrian-P在标准视频多模态大模型(Cambrian-1)基础上做了两处扩展。
第一,对每一帧,它在视觉token序列中插入一个可学习的相机token。
这个token被训练来编码相机的6自由度姿态(3D位置 + 3D朝向)。
第二,它接上一个姿态回归头,从相机token的表示中预测相机的外参矩阵。
训练时,模型看到的是视频帧配对的真值相机姿态(来自ScanNet或DROID-SLAM的伪标签)。
姿态回归损失迫使相机token捕获几何信息。
关键在于,相机token插入在语言模型之前,所以姿态信息流入了模型的推理过程,而不只是作为副任务。
采样方案也很重要:Cambrian-P不是均匀采样帧,而是用姿态感知采样,优先选择视角多样的帧。
这确保模型看到有意义的相机运动,而非冗余视角。
视频帧 --> 视觉编码器 --> 视觉tokens
                              |
                              v
                [相机token] <-- 可学习嵌入
                              |
                              v
                姿态回归头 --> 6自由度姿态
                              |
                              v
                视觉tokens + 相机token --> 大模型 --> 答案
把相机token想象成嵌入视频流的GPS追踪器。
想象你在看一段有人走过建筑物的视频。
每一帧显示不同的视角,但如果不知道相机移动到哪里,你无法重建布局。
相机token就像一个GPS设备,为每一帧记录”我在位置(x, y, z),朝向(横滚, 俯仰, 偏航)”。
姿态回归头是解码这个信号的GPS接收器。
语言模型同时看到图像和GPS日志,现在能回答”门在左边还是右边?”
因为它知道相机在两帧之间转了90度。
关键概念
- 相机姿态(6自由度): 相机在3D空间中的位置和朝向,用6个数字表示:3个表示平移(x, y, z坐标),3个表示旋转(横滚、俯仰、偏航角,或等价的旋转矩阵)。
例子:如果你站在房间里,你的位置可能是距离墙角(2米, 3米, 1.5米),朝向是正北偏左45度。
这个6自由度姿态定义了一个坐标系,把你看到的东西和房间几何关联起来。
在视频中,知道每一帧的姿态能让你三角测量物体位置,理解空间关系。
- 可学习相机token: 插入视觉token序列的可训练嵌入向量。
不同于固定的位置编码,这个token通过端到端优化来编码相机姿态信息。
把它想象成输入序列中为几何元数据预留的”槽位”。
模型学会用一个表示填充这个槽位,当这个表示通过姿态回归头时,能预测出正确的6自由度姿态。
因为它是语言模型输入的一部分,大模型在推理空间问题时能注意到它。
- 姿态感知采样: 基于相机运动而非时间来选择帧的采样策略。
标准的均匀采样每隔N帧选一帧,常常产生冗余视角(比如静态场景的10帧)。
姿态感知采样测量相机姿态之间的距离(平移+旋转),选择能最大化视角多样性的帧。
这确保模型看到有意义的几何变化,让姿态监督更有效。
框架转变
之前(主流方法):                之后(本文方法):

视频 --> [帧1] [帧2] ...          视频 --> [帧1+姿态1] [帧2+姿态2] ...
            |      |                         |              |
            v      v                         v              v
        视觉    视觉                      视觉          视觉
        编码器  编码器                    编码器        编码器
            |      |                         |              |
            v      v                         v              v
        [Tokens] [Tokens]                [Tokens]       [Tokens]
            |      |                         |              |
            +------+                         +--[相机]--[相机]
                |                                Token    Token
                v                                  |        |
               大模型                               v        v
                |                              姿态头    姿态头
                v                                  |        |
               答案                                v        v
                                              [6DoF]   [6DoF]
                                                  |        |
                                                  +--------+
                                                      |
                                                      v
                                                     大模型
                                                      |
                                                      v
                                                     答案
从把帧当作孤立图像到把每一帧嵌入共享的3D坐标系,核心转变是从2D模式匹配到3D空间推理。
专家评审
选题眼光: 真实缺口。
视频大模型在空间推理上确实挣扎(比如”哪个物体离相机更近?”
),而该领域基本忽视了相机姿态这个信号。
问题处于视觉-语言模型和3D视觉的交叉点——考虑到具身AI和机器人应用的推进,时机恰当。
方法成熟度: 巧劲,非蛮力。
添加可学习token和回归头是轻量级的(参数开销极小),能干净地集成到现有架构中。
姿态感知采样是个好细节,显示作者考虑了数据效率。
但对野外视频依赖DROID-SLAM的伪标签有点含糊——SLAM可能失败或漂移,论文没有深入分析噪声姿态如何影响训练。
实验诚意: 基线公平(对比了LLaVA-Video和Qwen2-VL等强视频大模型)。
VSI-Bench上4.5-6.5%的提升很可观,泛化到8个其他基准也有说服力。
ScanNet上的SOTA姿态估计是个好副产品,验证了学到的表示。
一个警示:论文声称姿态”超越空间推理”地改进了通用视频问答,但机制不清楚。
模型是学到了更好的时序表示,还是只是正则化效应?
需要更多消融实验。
写作功力: 摘要和引言简洁。
方法部分清晰,但可以加一张展示完整架构的图(现有图侧重结果)。
相关工作部分单薄——提到了NeRF和SLAM,但没有讨论近期的3D感知视觉-语言模型(如3D-LLM、LEO)。
完全缺失失败案例讨论。
重写4.3节(消融实验)加入失败分析能让论文升一档。
判决: 弱接收 — 贡献扎实,提升明确,但泛化到非空间任务的机制需要更深入研究,依赖伪标签是潜在弱点。
要点总结
- 可学习token作为信息通道: 不要把元数据(如姿态)硬编码到输入中,用可学习token让模型优化来编码那些信息。
这个模式可迁移到其他领域——比如为图像编辑添加”光照token”,或为多说话人音频添加”说话人token”。
- 视频的姿态感知采样: 如果任务涉及几何或运动,不要均匀采样帧。
在姿态空间(或特征空间)测量距离,优先选择多样性。
这适用于视频字幕、动作识别,或任何冗余帧浪费算力的任务。
- 辅助任务作为正则器: 姿态回归头名义上是副任务,但它迫使模型学到更好的表示。
这是通用技巧:添加轻量级辅助损失,与下游任务的结构对齐(比如深度预测用于3D推理,下一帧预测用于时序建模)。
- 经典方法的伪标签: DROID-SLAM为野外视频提供了有噪声但有用的姿态标签。
这说明经典几何(SLAM、SfM)能引导学习型模型。
如果你做的任务真值标签稀缺,考虑经典算法能否大规模生成伪标签。