Paper: 2607.07696 Authors: Victor Giannakouris, Immanuel Trummer Categories: cs.DB, cs.AI
The Gap
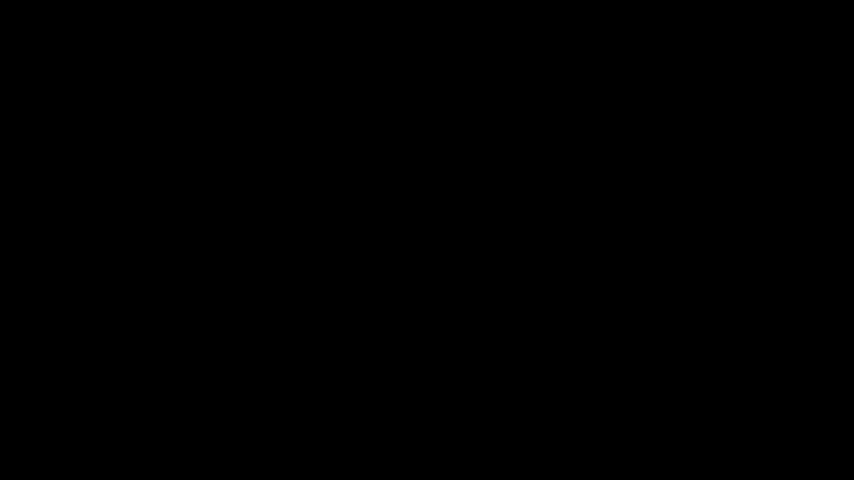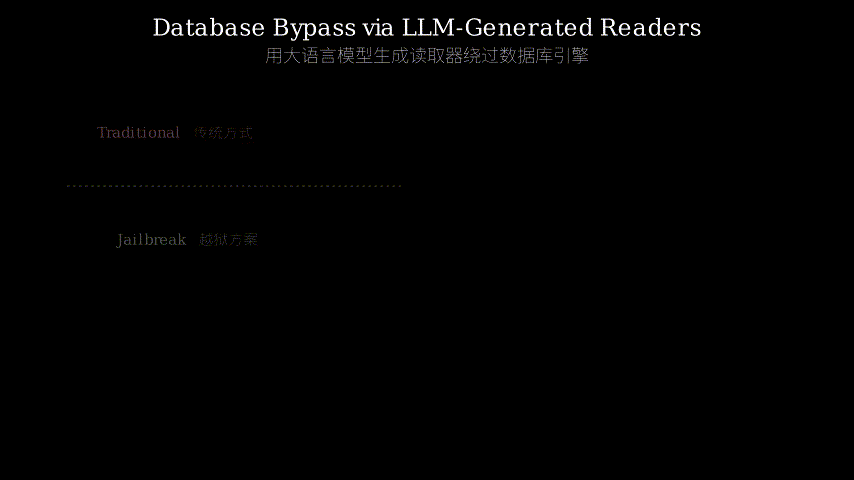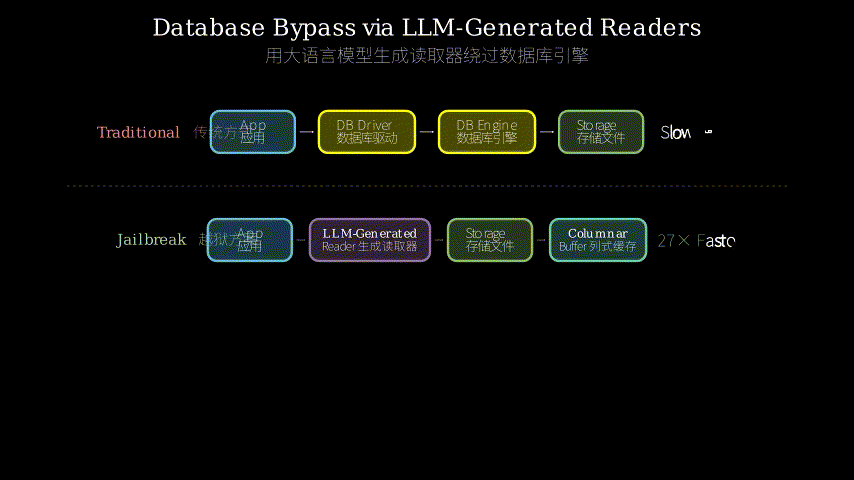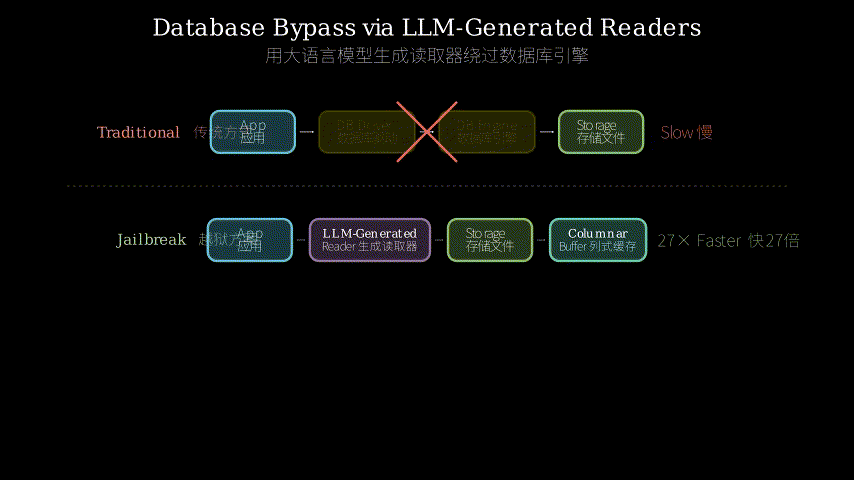
If you’re running analytical queries on data that lives inside an external database—say PostgreSQL or MySQL—you’re funneled through JDBC or ODBC drivers. These drivers were designed for transactional workloads: parse SQL, plan a query, execute it row by row, serialize results, deserialize on the client side. For bulk columnar analytics, this pipeline is a bottleneck you didn’t choose but can’t avoid. Prior work has tried to optimize within this constraint: query pushdown, connector improvements (like the Spark JDBC connector’s partition parallelism), or specialized analytical engines like DuckDB that sit outside the database but still read through the driver. Nobody has seriously asked: what if we skip the driver entirely and read the storage files ourselves?
The reason nobody tried is obvious: database file formats are notoriously complex and poorly documented. PostgreSQL’s heap format, MySQL’s InnoDB page structure—these are implementation artifacts, not specs handed out at conferences. Writing parsers by hand is a months-long engineering effort per format, and any schema change or version update breaks your code. The gap is real: we know direct file access would be faster, but the engineering cost of building and maintaining readers is prohibitive.
This paper’s logical path:
Problem: JDBC/ODBC forces bulk reads through transactional pipeline
    |
    v
Observation: File formats are complex but fully specified in source code + docs
    |
    v
Assumption: LLMs can ingest source code and docs to generate correct parsers
    |
    v
Method: LLM-assisted code synthesis produces direct storage readers
    |
    v
Evidence: TPC-H correctness verified, up to 27x throughput improvement
    |
    v
Conclusion: LLM-generated readers are viable, generalizable, and fast
The Increment
One sentence: Before this paper, bypassing the database engine for direct file access required months of manual parser engineering per format; after this paper, an LLM can generate a correct, high-performance reader from documentation alone in minutes.
Core Mechanism
Jailbreak has three stages.
First, it collects the “blueprint” for a database’s storage format: source code files (like PostgreSQL’s heapam.c or MySQL’s page0page.cc), official documentation, and any supplementary specs.
These artifacts are fed into an LLM with a carefully structured prompt that asks for a complete table-scanning reader.
The LLM doesn’t just output a spec—it outputs runnable code.
Second, the generated reader is compiled and executed against actual storage files (.mdf, .ibd, heap files, etc.).
The reader parses pages, interprets tuple headers, handles null bitmaps, reconstructs column values, and materializes everything into Apache Arrow columnar buffers.
Arrow is the lingua franca of modern analytical engines, so the output plugs directly into DuckDB, Spark, cuDF, or Spark RAPIDS without further transformation.
Third, correctness and performance are validated. Jailbreak compares query results from its direct readers against JDBC/ODBC baselines on the full TPC-H benchmark—not just row counts, but every cell of every result set must match. Performance is measured end-to-end: time from storage file to analytical result.
Stage 1: LLM Code Synthesis
+-------------------+     +-------------------+
| Database source   |     | Database docs     |
| code (.c files)   |     | (spec, wiki)      |
+-------------------+     +-------------------+
         \                       /
          \                     /
           v                   v
        +-----------------------+
        |       LLM            |
        | (code generation     |
        |  with structured     |
        |  prompting)          |
        +-----------------------+
                |
                v
        +-----------------------+
        | Generated storage    |
        | reader (C/Rust code) |
        +-----------------------+

Stage 2: Direct File Reading
+-------------------+     +-------------------+
| PostgreSQL heap   |     | MySQL InnoDB      |
| files             |     | .ibd files        |
+-------------------+     +-------------------+
         \                       /
          v                     v
        +-----------------------+
        | Generated reader     |
        | (parses pages,       |
        |  tuples, headers)    |
        +-----------------------+
                |
                v
        +-----------------------+
        | Apache Arrow         |
        | columnar buffers     |
        +-----------------------+
                |
                v
        +-----------------------+
        | DuckDB / Spark /     |
        | cuDF / RAPIDS        |
        +-----------------------+
Structural Metaphor
Think of a locked warehouse where all your data is stored on shelves. The only official entrance is a single service window (JDBC/ODBC) with a clerk who must: take your written request (SQL), walk to the shelf, pick up one item, carry it back, hand it to you through the window, then repeat. Fine for grabbing a few boxes. Disastrous when you need the entire inventory.
Previous approaches tried to make the clerk faster—add more windows, give the clerk a cart, let the clerk delegate to assistants inside. But the fundamental constraint remains: everything goes through the window.
Jailbreak does something different. It hires a specialist locksmith (the LLM) and hands them the warehouse’s blueprints—the architectural drawings and construction manuals (source code and documentation). The locksmith studies these blueprints, then cuts a custom key (the generated reader) that opens the warehouse’s loading dock directly. Now you can drive a truck in and load pallets (Arrow columnar buffers) straight off the shelves.
The key insight: you don’t need a universal lock-picking kit. You just need someone who can read this specific warehouse’s blueprints. And LLMs happen to be very good at reading blueprints—if you hand them the right ones.
The metaphor is load-bearing because each part maps precisely:
- Warehouse blueprints = database source code + docs
- Locksmith = LLM
- Custom key = generated storage reader
- Loading dock = direct file I/O
- Pallets = Arrow columnar buffers
- Service window = JDBC/ODBC bottleneck
Key Concepts
-
Columnar Buffers (Apache Arrow): Imagine you have a spreadsheet with columns: Name, Age, City. Row-oriented storage (how databases store things on disk) keeps each person’s data together: [Alice, 30, NYC], [Bob, 25, LA]. Column-oriented storage keeps each *attribute together: [Alice, Bob, …], [30, 25, …], [NYC, LA, …]. Why does this matter? When you’re computing “average age,” you only need the Age column. Columnar storage means you read exactly what you need, nothing else—and modern CPUs love this because sequential data fits in cache. Apache Arrow is the standard in-memory columnar format that almost every analytical engine understands, so once your data is in Arrow, it can flow directly to DuckDB, Spark, or GPU frameworks without copying or conversion.
-
LLM-Assisted Code Synthesis: This isn’t “ChatGPT, write me a database parser.” The method is structured: the LLM receives specific source files (not a vague prompt), is guided to produce compilable code (not pseudocode), and the output is verified against known-correct results. Think of it as the LLM acting as a translator between human-readable documentation and machine-executable parsing logic. The “assisted” part matters—there’s prompt engineering, validation, and likely iterative refinement. The contribution is showing that this translation pipeline is practical for a class of problems (storage format parsing) that previously required deep domain expertise.
-
Database Lock-in: When your data lives inside a PostgreSQL database, you can only access it through PostgreSQL’s interfaces. Even if you want to run Spark or DuckDB queries on that data, you have to go through PostgreSQL’s driver. This “lock-in” isn’t a feature—it’s an architectural accident. Your data is trapped behind an interface designed for a different purpose (transactional queries, not bulk analytics). Jailbreak’s thesis is that this lock-in is artificial: the data sits in files you could read directly, if only you knew how to decode the format.
Framework Shift
Before (mainstream approach):
                                          +------------------+
+----------+    +----------+    +-------->| Query Engine     |
| App/ETL  |--->| JDBC/    |--->| DB      | (parses, plans,  |
|          |    | ODBC     |    | Server  |  executes,       |
+----------+    +----------+    +-------->|  serializes)     |
                                          +------------------+
                                                    |
                                                    v
                                          +------------------+
                                          | Results via      |
                                          | driver (rows)    |
                                          +------------------+

After (this paper):
                                          +------------------+
+----------+    +---------------------+   | Storage files    |
| App/ETL  |--->| LLM-generated       |<--| (.mdf, .ibd,     |
|          |    | direct reader       |   |  heap files)     |
+----------+    +---------------------+   +------------------+
                         |
                         v
               +---------------------+
               | Apache Arrow        |
               | columnar buffers    |
               +---------------------+
                         |
                         v
               +---------------------+
               | DuckDB / Spark /    |
               | cuDF / RAPIDS       |
               +---------------------+
From forcing every read through a transactional query engine to reading storage files directly into analytical buffers, the core shift is treating the database’s physical storage as a first-class data source rather than an implementation detail hidden behind a driver.
Expert Assessment
Problem choice: This is a genuine gap. The tension between OLTP-designed database interfaces and OLAP workloads is real and widely felt—anyone running analytics on operational databases knows the pain. The paper situates itself well: prior work optimized within the driver paradigm (better connectors, query pushdown), while this paper asks whether the paradigm itself is necessary. It’s a natural question that surprisingly few have pursued, likely because the manual engineering cost was prohibitive. The read-replica / offline-pipeline framing is practical and realistic.
Method maturity: The core insight—LLMs can read source code to regenerate parsers—is clever and genuinely novel. It transforms a software engineering problem (months of manual parsing code) into an inference problem. However, the approach has a fragility that the paper doesn’t fully address: what happens when the LLM generates code that compiles and runs but produces subtly incorrect results for edge cases (corrupted pages, unusual null patterns, TOAST’d values in PostgreSQL)? The TPC-H validation is a good start, but TPC-H uses clean, well-structured data. Real-world databases have messy corners—partially written pages, vacuumed tuples, encoding edge cases.
There’s also a dependency on the quality and completeness of the source code/docs provided to the LLM. For PostgreSQL, which is open-source and well-documented, this works well. For proprietary or poorly documented formats, the approach may struggle. The paper acknowledges this but doesn’t quantify it.
Experimental integrity: The baselines are fair in principle—JDBC/ODBC is the actual production alternative for most users. But a stronger comparison would include optimized analytical connectors (like pg_bulkload, or direct COPY-based pipelines) rather than just vanilla JDBC. The 27x number is impressive but likely varies significantly with table size, column count, and network topology. The TPC-H correctness check is rigorous: verifying every cell of every query result is the right standard. One concern: the paper evaluates on analytical snapshot scenarios (read replicas, offline pipelines), which is the right framing, but readers should be careful not to generalize to transactional or incremental-read scenarios.
Writing quality: The abstract is crisp and well-structured. The motivation section does its job. Where the paper could improve: the LLM prompting methodology deserves more space. What exactly is in the prompt? How many iterations? What’s the failure rate on first attempt? These details matter enormously for reproducibility and for understanding the approach’s true cost. The evaluation section would also benefit from an ablation: how much of the speedup comes from bypassing the query engine vs. the columnar format vs. removing serialization overhead?
Verdict: weak accept — The idea is genuinely creative, the results are strong, and the problem is real. The main weakness is insufficient depth on failure modes, LLM prompting details, and comparison against optimized (not just vanilla) baselines. With those additions, this could be a strong accept.
Takeaways
-
LLM-as-format-translator is a transferable pattern. The core idea—feed an LLM the source code and docs for an opaque format, ask it to generate a reader—applies far beyond databases. Think: proprietary log formats, binary sensor data, legacy file formats from acquired companies. If you can find the documentation, you can potentially generate a parser.
-
Apache Arrow as the universal “pallet format” is validated again. This paper’s architecture only works because Arrow is a lingua franca. If you’re designing data pipelines, standardizing on Arrow as your interchange format is increasingly non-negotiable.
-
The bottleneck you accept is often architectural, not algorithmic. The 27x speedup doesn’t come from a better algorithm—it comes from removing layers that were never designed for your workload. Before optimizing within a paradigm, ask: is the paradigm itself the bottleneck?
-
“Can the LLM do this?” is becoming a valid research question for systems problems. This paper is part of a growing trend: using LLMs not as end-user tools but as components in systems that automate traditionally manual engineering tasks. If you’re building tools, consider where LLM code generation could replace boilerplate or domain-specific parsing logic.
论文: 2607.07696 作者: Victor Giannakouris, Immanuel Trummer 分类: cs.DB, cs.AI
缺口
做分析查询时,如果数据存在外部数据库(比如PostgreSQL或MySQL),你必须通过JDBC或ODBC驱动来读取。 这些驱动是为事务型工作负载设计的:解析SQL、规划查询、逐行执行、序列化结果、客户端反序列化。 对于批量列式分析来说,这条管道是个你没选但躲不掉的瓶颈。 此前的研究在这个约束内做优化:查询下推、连接器改进(比如Spark JDBC连接器的分区并行),或者把DuckDB这类分析引擎放在数据库外面——但仍然通过驱动读数据。 没有人认真问过一个问题:能不能直接跳过驱动,自己读存储文件?
没人尝试的原因显而易见:数据库文件格式极其复杂,文档也差。 PostgreSQL的堆格式、MySQL InnoDB的页面结构——这些是实现细节,不是会议上发的规范。 手工写解析器每个格式要花几个月,而且任何模式变更或版本升级都会让代码失效。 真正的缺口就在这里:我们知道直接读文件会更快,但构建和维护读取器的工程成本高得离谱。
本文的逻辑路径:
问题:JDBC/ODBC强制批量读取走事务型管道
    |
    v
观察:文件格式虽复杂,但源码和文档中有完整规范
    |
    v
假设:大语言模型能读懂源码和文档,生成正确的解析器
    |
    v
方法:LLM辅助代码合成,自动生成直接存储读取器
    |
    v
证据:TPC-H查询结果全部正确,吞吐量最高提升27倍
    |
    v
结论:LLM生成的读取器可行、可泛化、且高性能
增量
一句话: 这篇论文之前,绕过数据库引擎直接读文件需要每个格式投入数月手工工程;这篇论文之后,大语言模型仅凭文档就能在几分钟内生成正确且高性能的读取器。
核心机制
Jailbreak分三个阶段运行。
第一阶段,收集数据库存储格式的”蓝图”:源码文件(如PostgreSQL的heapam.c或MySQL的page0page.cc)、官方文档以及补充规范。
这些材料连同精心设计的提示词一起输入大语言模型,要求它生成一个完整的表扫描读取器。
模型输出的不是伪代码,而是可编译运行的代码。
第二阶段,生成的读取器被编译后直接对存储文件执行(.mdf、.ibd、堆文件等)。
读取器解析页面、解释元组头部、处理空值位图、重建列值,然后把一切物化为Apache Arrow列式缓冲区。
Arrow是现代分析引擎的通用格式,输出可以直接接入DuckDB、Spark、cuDF或Spark RAPIDS,无需额外转换。
第三阶段,验证正确性和性能。 Jailbreak将直接读取器的查询结果与JDBC/ODBC基线在完整TPC-H基准上进行比对——不是只比行数,而是每个结果集的每个单元格都必须完全匹配。
阶段一:LLM代码合成
+-------------------+     +-------------------+
| 数据库源码        |     | 数据库文档        |
| (.c 文件)         |     | (规范、Wiki)      |
+-------------------+     +-------------------+
         \                       /
          \                     /
           v                   v
        +-----------------------+
        |       大语言模型      |
        | (结构化提示下的       |
        |  代码生成)            |
        +-----------------------+
                |
                v
        +-----------------------+
        | 生成的存储读取器      |
        | (C/Rust 代码)         |
        +-----------------------+

阶段二:直接文件读取
+-------------------+     +-------------------+
| PostgreSQL 堆文件 |     | MySQL InnoDB      |
|                   |     | .ibd 文件         |
+-------------------+     +-------------------+
         \                       /
          v                     v
        +-----------------------+
        | 生成的读取器          |
        | (解析页面、元组、头部) |
        +-----------------------+
                |
                v
        +-----------------------+
        | Apache Arrow          |
        | 列式缓冲区            |
        +-----------------------+
                |
                v
        +-----------------------+
        | DuckDB / Spark /     |
        | cuDF / RAPIDS        |
        +-----------------------+
核喻
想象一个上锁的仓库,你的所有数据都存放在里面的货架上。 唯一的正式入口是一个服务窗口(JDBC/ODBC),工作人员必须:接过你的书面请求(SQL),走到货架前,取一件东西,搬回来,从窗口递给你,然后重复。 拿几箱货没问题。 但如果你要搬空整个仓库呢?
之前的做法是让窗口工作人员更快——多开几个窗口、给工作人员配小推车、让仓库里面的助手帮忙。 但根本限制没变:所有东西都必须经过窗口。
Jailbreak换了个思路。 它雇了一个专业锁匠(大语言模型),把仓库的建筑图纸和施工手册(源码和文档)交给他。 锁匠研究图纸,然后配了一把专用钥匙(生成的读取器),直接打开仓库的装卸口。 现在你可以开卡车进去,把托盘(Arrow列式缓冲区)直接从货架上装走。
关键洞见:你不需要万能开锁工具。 你只需要一个能读懂这座仓库图纸的人。 而大语言模型恰好擅长读图纸——前提是你把对的图纸给它。
这个比喻是承重的,每个部分都有精确映射:
- 仓库图纸 = 数据库源码 + 文档
- 锁匠 = 大语言模型
- 专用钥匙 = 生成的存储读取器
- 装卸口 = 直接文件I/O
- 托盘 = Arrow列式缓冲区
- 服务窗口 = JDBC/ODBC瓶颈
关键概念
-
列式缓冲区(Apache Arrow): 假设你有一张电子表格,列分别是姓名、年龄、城市。 行式存储(数据库在磁盘上的存储方式)把每个人的数据放在一起:[Alice, 30, NYC], [Bob, 25, LA]。 列式存储把每个属性放在一起:[Alice, Bob, …], [30, 25, …], [NYC, LA, …]。 为什么重要?当你计算”平均年龄”时,只需要年龄那一列。 列式存储意味着你只读需要的东西——而且现代CPU很喜欢这样,因为连续数据能放进缓存。 Apache Arrow是内存列式格式的事实标准,几乎所有分析引擎都认它。 数据一旦进入Arrow,就能直接流向DuckDB、Spark或GPU框架,不需要复制或转换。
-
LLM辅助代码合成: 这不是”ChatGPT,帮我写个数据库解析器”那么简单。 方法是结构化的:LLM接收特定的源文件(不是模糊的提示),被引导生成可编译代码(不是伪代码),输出还要对照已知正确结果做验证。 可以把它理解为LLM充当人类可读文档和机器可执行解析逻辑之间的”翻译器”。 “辅助”这个词很关键——里面有提示工程、验证步骤、很可能还有迭代修正。 本文的贡献是证明了:对于一类问题(存储格式解析),这条翻译管道是实用的,而这类问题过去需要深厚的领域专业知识。
-
数据库锁定: 当你的数据存在PostgreSQL里,你只能通过PostgreSQL的接口访问它。 即使你想用Spark或DuckDB跑查询,也必须走PostgreSQL的驱动。 这种”锁定”不是设计特性——是架构的副作用。 你的数据被困在一个为不同目的(事务查询而非批量分析)设计的接口后面。 Jailbreak的核心论点是:这种锁定是人为的。 数据就在文件里,你本来可以直接读——只要你懂得怎么解码格式。
框架转变
之前(主流方法):
                                    +------------------+
+----------+  +----------+  +----->| 查询引擎          |
| 应用/ETL |--| JDBC/    |--| DB   | (解析、规划、     |
|          |  | ODBC     |  | 服务 |  执行、序列化)    |
+----------+  +----------+  +----->|                  |
                                    +------------------+
                                              |
                                              v
                                    +------------------+
                                    | 通过驱动返回结果  |
                                    | (逐行)           |
                                    +------------------+

之后(本文方法):
                                    +------------------+
+----------+  +-----------------+   | 存储文件          |
| 应用/ETL |--| LLM生成的       |<--| (.mdf, .ibd,     |
|          |  | 直接读取器      |   |  堆文件)         |
+----------+  +-----------------+   +------------------+
                       |
                       v
             +-----------------+
             | Apache Arrow    |
             | 列式缓冲区      |
             +-----------------+
                       |
                       v
             +-----------------+
             | DuckDB / Spark/ |
             | cuDF / RAPIDS   |
             +-----------------+
从强制所有读取经过事务型查询引擎,到直接读取存储文件生成分析格式。 核心转变是:把数据库的物理存储视为一等数据源,而非隐藏在驱动后面的实现细节。
专家评审
选题眼光: 这是一个真实的缺口。 OLTP设计的数据库接口与OLAP工作负载之间的矛盾是实实在在的——任何在运营数据库上跑分析的人都有切肤之痛。 本文定位精准:此前的工作在驱动范式内优化(更好的连接器、查询下推),而本文问的是这个范式本身是否必要。 这个问题很自然,但很少有人追问,大概是因为手工工程成本太高了。 以读副本/离线管道为场景切入,务实且合理。
方法成熟度: 核心洞见——大语言模型能读懂源码并重新生成解析器——是真正新颖的创意。 它把一个软件工程问题(数月的解析器开发)转化成了推理问题。 但论文没有充分讨论这个方法的脆弱性:当LLM生成的代码能编译能运行,但对边界情况(损坏的页面、特殊的空值模式、PostgreSQL的TOAST值)产出微妙错误的结果时怎么办? TPC-H验证是好的开始,但TPC-H用的是干净、结构良好的数据。 真实数据库有各种脏角落——部分写入的页面、已清理的元组、编码边界情况。
还有一个依赖关系论文没有充分量化:LLM生成代码的质量和完整度取决于提供给它的源码/文档的质量。 PostgreSQL开源且文档好,所以效果好。 对于私有或文档差的格式,这个方法可能会吃力。 论文承认了这一点但没有量化。
实验诚意: 基线选择原则上是公平的——JDBC/ODBC确实是大多数用户在生产中用的方案。 但更强的对比应该包括优化过的分析连接器(如pg_bulkload、基于COPY的管道),而不是只比原生JDBC。 27倍的数字令人印象深刻,但具体倍数显然会随表大小、列数和网络拓扑而大幅变化。 TPC-H正确性验证是严格的:比对每个查询结果的每个单元格,这是正确的标准。 一个顾虑:论文在分析型快照场景(读副本、离线管道)上评估,场景选择是对的,但读者不应泛化到事务型或增量读取场景。
写作功力: 摘要写得干净利落。 动机部分完成任务。 可以改进的地方:LLM提示方法论值得更多篇幅。 提示词到底长什么样?迭代了多少次?第一次尝试的失败率是多少? 这些细节对可复现性和理解方法的真实成本至关重要。 评估部分也需要一个消融实验:加速到底有多少来自绕过查询引擎,多少来自列式格式,多少来自去掉序列化开销?
判决: 弱接收 — 想法确实有创意,结果扎实,问题也真实。 主要弱点是对失败模式、LLM提示细节、以及与优化基线(而非原生基线)的对比深度不足。 补上这些,可以升到强接收。
要点总结
-
LLM当格式翻译器是一个可迁移的模式。 核心思路——把某格式的源码和文档喂给LLM,让它生成读取器——远不止适用于数据库。 想想:私有日志格式、二进制传感器数据、收购来的遗留系统文件格式。 只要你能找到文档,就可能生成解析器。
-
Apache Arrow作为通用”托盘格式”再次被验证。 本文的架构只有在Arrow是通用交换格式的前提下才能成立。 如果你在设计数据管道,把Arrow标准化为交换格式正变得不可或缺。
-
你接受的瓶颈往往是架构性的,不是算法性的。 27倍加速不来自更好的算法——它来自移除了从未为你的工作负载设计的层。 在范式内做优化之前,先问:范式本身是不是瓶颈?
-
“LLM能不能做这个?“正在成为系统研究的合法问题。 本文属于一个增长中的趋势:把LLM当作系统组件来自动化传统上需要手工完成的工程任务。 如果你在构建工具,想想哪些地方的样板代码或领域特定解析逻辑可以用LLM代码生成替代。