Paper: 2605.28780 Authors: Thomas Vitry, Kieran Edgeworth, Stefan Wermter, Jae Hee Lee Categories: cs.CV, cs.LG
The Gap
Existing bias mitigation methods hit a wall when models are already deployed. Methods like reweighting, group DRO, or adversarial debiasing require knowing which attributes are spurious (gender, background, color) and having labels for them during training. But in production, you often discover bias after deployment, when retraining is expensive or infeasible, and you don’t know which concepts the model is exploiting. Prior post-hoc analysis tools like concept activation vectors (CAVs) still need human-annotated concept examples. The field lacks a way to audit frozen models for unknown biases using only standard class labels.
Problem: Deployed model fails on subgroups
    |
    v
Existing solutions require:
  - Spurious attribute labels (gender, background)
  - Retraining from scratch
  - Known bias concepts upfront
    |
    v
Gap: No post-hoc method for unknown biases in frozen models
    |
    v
This paper's assumption:
  Bias concepts leave gradient signatures on misclassified examples
    |
    v
Method: Decompose activations -> rank concepts by gradient interaction
    |
    v
Evidence: Recovers known spurious cues (color, background)
         Improves worst-group accuracy without retraining
    |
    v
Conclusion: Gradient probes identify actionable bias in frozen models
The Increment
One sentence: Before this paper, auditing deployed models for unknown biases required retraining or bias labels; after, you can identify and suppress spurious concepts in frozen models using only class labels.
Core Mechanism
The method operates in three stages. First, for each target class, collect image patches that the frozen model predicts as that class. Extract intermediate layer activations from these patches and apply non-negative matrix factorization (NMF) to decompose them into a bank of interpretable concept vectors—think of these as the model’s internal vocabulary for that class.
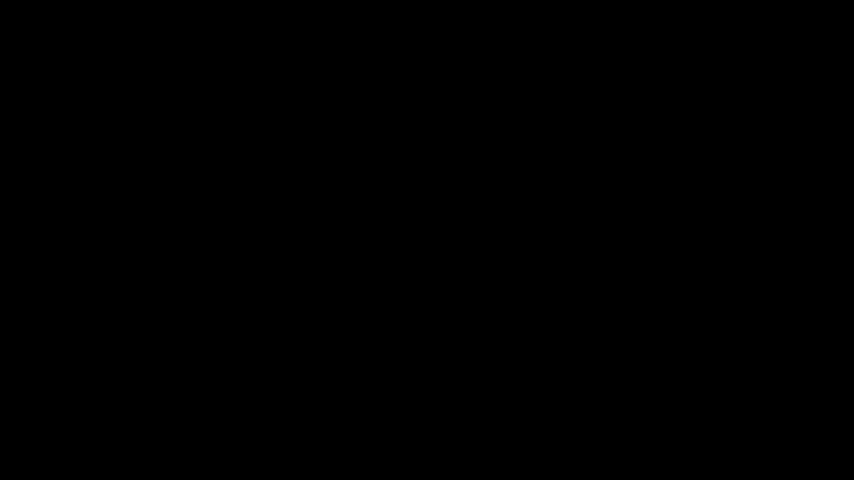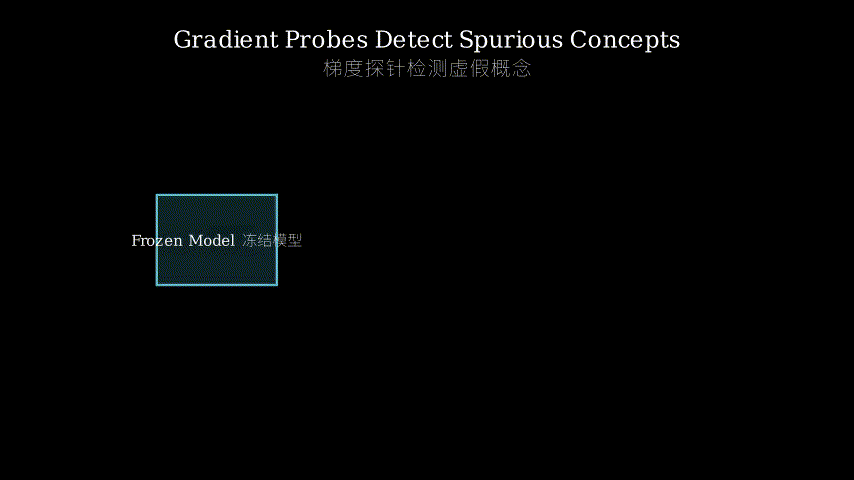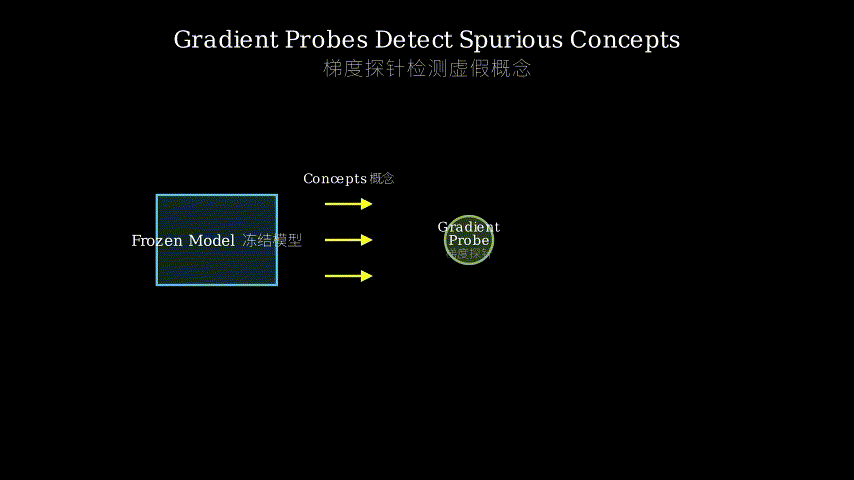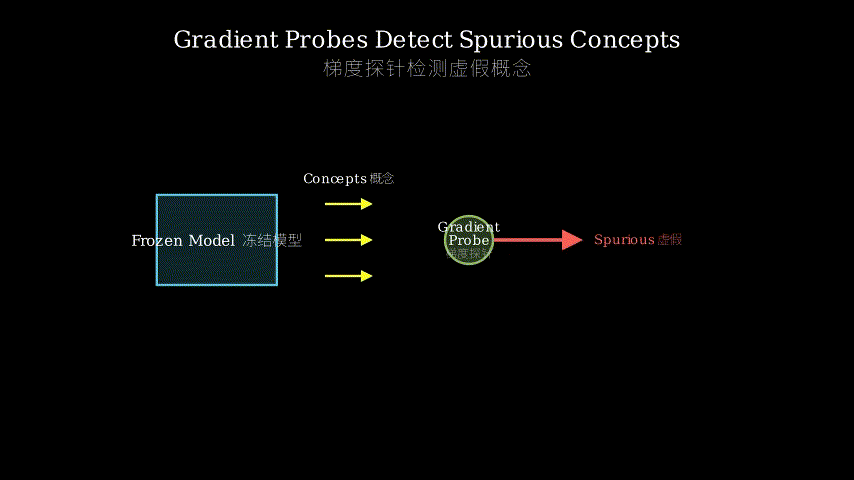
Second, identify which concepts are spurious by examining misclassified examples. For false negatives (should be class A but predicted otherwise), backpropagate gradients and measure how much each concept vector would need to be activated to correct the mistake. For false positives (predicted as class A but shouldn’t be), measure how much each concept needs to be suppressed. Bias concepts show a characteristic signature: they get strongly activated when fixing false negatives and strongly suppressed when fixing false positives.
Third, rank concepts by this gradient-based bias score. At inference time, suppress the top-ranked concepts by zeroing out their contributions in the activation space. No parameter updates, no retraining—just intervention on intermediate representations.
Input image -> Frozen model -> Intermediate activations
                                        |
                                        v
                    NMF decomposition into concept vectors
                    (one bank per class)
                                        |
                                        v
                    Misclassified examples -> Backprop gradients
                                        |
                                        v
                    Bias score = activation on FN - activation on FP
                                        |
                                        v
                    Rank concepts by bias score
                                        |
                                        v
                    Inference: Suppress top-ranked concepts
Think of the model’s intermediate layer as a mixing board with many sliders, each controlling a concept (texture, shape, color, background). NMF discovers what these sliders represent by analyzing which combinations fire for each class. Now imagine you have recordings of mistakes—songs that came out wrong. You play them backward (backpropagation) to see which sliders were set incorrectly. Bias concepts are the sliders that consistently need to be turned up when the model missed something (false negative) and turned down when it hallucinated something (false positive). Once you’ve identified the problematic sliders, you can lock them at zero during playback without rewiring the entire mixing board.
Key Concepts
-
Non-negative Matrix Factorization (NMF): Imagine you have a spreadsheet where rows are image patches and columns are neuron activations. NMF finds a small set of “basis patterns” (concept vectors) such that each patch’s activations can be written as a non-negative weighted sum of these patterns. Unlike PCA, which allows negative weights and produces abstract axes, NMF’s non-negativity constraint yields additive, part-based representations—like decomposing a face into “eyes,” “nose,” “mouth” rather than “face minus anti-face.” In this paper, NMF decomposes activations from patches of a given class into interpretable concept directions that the model uses to recognize that class.
-
Gradient-based bias estimation: When the model misclassifies an example, backpropagated gradients tell you how to adjust activations to fix the mistake. For a false negative (missed a bird), gradients point toward increasing activations that would make the model say “bird.” For a false positive (hallucinated a bird), gradients point toward decreasing those activations. A spurious concept (like “water background”) will show high positive gradients on false negatives (waterbirds the model missed) and high negative gradients on false positives (landbirds the model wrongly called waterbirds). The bias score captures this asymmetry: concepts that need to be amplified for one type of error and suppressed for the other are likely spurious shortcuts.
-
Post-hoc intervention on frozen models: Most debiasing methods retrain the model with modified objectives or data. This paper intervenes at inference time by identifying spurious concept directions in activation space and projecting them out—like noise cancellation for bias. The model’s parameters stay frozen; you’re just filtering its internal representations. This is crucial for deployed models where retraining is prohibitively expensive or when you discover new biases after deployment. The tradeoff: you can’t fundamentally change what the model learned, only suppress specific decision pathways.
Framework Shift
Before (mainstream approach):        After (this paper):

Training time:                       Training time:
  Data + bias labels                   Data + class labels only
       |                                    |
       v                                    v
  Reweight / adversarial               Train normally
       |                                    |
       v                                    v
  Debiased model                       Standard model
                                            |
                                            v
                                       Deployment
                                            |
                                            v
                                       Audit phase:
                                         Collect patches
                                         NMF -> concepts
                                         Gradient probes
                                            |
                                            v
                                       Suppress at inference

Requires: Known biases upfront       Requires: Only class labels
Flexibility: None after training     Flexibility: Iterative auditing
[One sentence: From baking bias mitigation into training to applying it as a post-deployment filter, the core shift is from preventive to detective.]
Expert Assessment
Problem choice: Real gap. The scenario—deployed model, unknown bias, no retraining budget—is common in industry but underserved in research. Most bias work assumes you know what to look for and can retrain. This paper targets the harder case.
Method maturity: The gradient-based bias score is clever but not deeply justified. Why should the asymmetry between false negatives and false positives specifically isolate spurious concepts rather than just hard-to-learn features? The paper shows it works empirically but doesn’t provide theoretical grounding. NMF for concept discovery is standard; the novelty is in the ranking criterion. The method is simple enough to be practical, which is a strength.
Experimental integrity: Baselines are fair—they compare against other post-hoc methods (CAVs, TCAV) and show their approach works without concept labels. The datasets (Colored MNIST, Waterbirds, CelebA) are standard bias benchmarks. However, the improvements are measured on worst-group accuracy, which can be gamed by sacrificing overall accuracy. The paper reports both, which is honest, but the tradeoff curves could be more prominent. One concern: the method assumes misclassified examples are available and representative of bias, which may not hold if the audit dataset is small or unbalanced.
Writing quality: The paper is clear in the method section but rushes through limitations. Section 5 (experiments) could better separate “does it find the right concepts?” from “does suppression help?” The related work section is thorough but could be trimmed. The biggest missed opportunity: no discussion of when the method fails. What if bias concepts are entangled with valid features? What if gradients are noisy? A failure mode analysis would elevate this from a technique paper to a methods paper.
Verdict: weak accept — Addresses a real problem with a practical solution, but the theoretical justification is thin and the experimental scope is narrow (three datasets, all with known ground-truth biases). Needs broader evaluation on cases where the spurious concept is truly unknown.
Takeaways
Gradient asymmetry as a bias signal: The idea that spurious concepts show opposite gradient patterns on false negatives vs. false positives is transferable. You could apply this to debug other model failures—not just bias, but any systematic error where the model overuses a feature in some contexts and underuses it in others.
NMF for interpretable decomposition: If you need human-interpretable directions in activation space, NMF’s non-negativity constraint is underused compared to PCA. It’s worth trying when you want part-based, additive concepts rather than abstract axes.
Inference-time intervention: The broader lesson is that you don’t always need to retrain. If you can identify problematic directions in representation space, you can filter them out at inference. This applies beyond bias—think adversarial robustness, domain adaptation, or removing sensitive attributes for fairness.
Audit-then-act workflow: The paper demonstrates a two-phase approach: first audit the model to discover issues, then intervene. This is more realistic than assuming you know all problems upfront. The workflow itself—collect examples, decompose, rank, suppress—is a template for post-hoc model debugging.
论文: 2605.28780 作者: Thomas Vitry, Kieran Edgeworth, Stefan Wermter, Jae Hee Lee 分类: cs.CV, cs.LG
缺口
现有的偏见缓解方法在模型已经部署后就碰壁了。
重加权、群体DRO、对抗去偏等方法都需要在训练时知道哪些属性是虚假的(性别、背景、颜色),并且有这些属性的标注。
但在生产环境中,你往往是在部署后才发现偏见,此时重新训练成本高昂或不可行,而且你不知道模型在利用哪些概念。
之前的事后分析工具如概念激活向量(CAV)仍然需要人工标注的概念样本。
该领域缺少一种方法,能够仅用标准类别标签就对冻结模型进行未知偏见审计。
问题:已部署模型在子群上失效
    |
    v
现有解决方案需要:
  - 虚假属性标注(性别、背景)
  - 从头重新训练
  - 提前知道偏见概念
    |
    v
缺口:没有针对冻结模型中未知偏见的事后方法
    |
    v
本文假设:
  偏见概念在误分类样本上留下梯度签名
    |
    v
方法:分解激活 -> 用梯度交互对概念排序
    |
    v
证据:恢复已知虚假线索(颜色、背景)
      无需重训练即提升最差组准确率
    |
    v
结论:梯度探针能识别冻结模型中的可操作偏见
增量
一句话:这篇论文之前,审计已部署模型的未知偏见需要重新训练或偏见标注; 之后,你可以仅用类别标签就识别并抑制冻结模型中的虚假概念。
核心机制
该方法分三个阶段运作。
首先,对每个目标类别,收集冻结模型预测为该类别的图像块。
从这些块中提取中间层激活,并应用非负矩阵分解(NMF)将其分解为一组可解释的概念向量——可以把这些看作模型对该类别的内部词汇表。
其次,通过检查误分类样本来识别哪些概念是虚假的。
对于假阴性(应该是类别A但预测为其他),反向传播梯度并测量每个概念向量需要被激活多少才能纠正错误。
对于假阳性(预测为类别A但不应该),测量每个概念需要被抑制多少。
偏见概念显示出特征性签名:在修正假阴性时被强烈激活,在修正假阳性时被强烈抑制。
第三,用这个基于梯度的偏见分数对概念排序。
在推理时,通过在激活空间中将排名靠前的概念的贡献归零来抑制它们。
无需参数更新,无需重新训练——只是对中间表示进行干预。
输入图像 -> 冻结模型 -> 中间激活
                              |
                              v
              NMF分解为概念向量
              (每个类别一组)
                              |
                              v
              误分类样本 -> 反向传播梯度
                              |
                              v
              偏见分数 = FN上的激活 - FP上的激活
                              |
                              v
              按偏见分数对概念排序
                              |
                              v
              推理:抑制排名靠前的概念
把模型的中间层想象成一个调音台,有很多推子,每个控制一个概念(纹理、形状、颜色、背景)。
NMF通过分析每个类别触发哪些组合来发现这些推子代表什么。
现在想象你有一些错误的录音——出错的歌曲。
你倒放它们(反向传播)来看哪些推子设置错了。
偏见概念就是那些在模型漏掉某物时(假阴性)需要调高、在模型幻觉出某物时(假阳性)需要调低的推子。
一旦识别出有问题的推子,你就可以在播放时将它们锁定在零位,而无需重新布线整个调音台。
关键概念
- 非负矩阵分解(NMF):想象你有一个电子表格,行是图像块,列是神经元激活。
NMF找到一小组”基础模式”(概念向量),使得每个块的激活可以写成这些模式的非负加权和。
与允许负权重并产生抽象轴的PCA不同,NMF的非负性约束产生加性的、基于部分的表示——就像将脸分解为”眼睛”、“鼻子”、“嘴巴”,而不是”脸减去反脸”。
在本文中,NMF将给定类别的块的激活分解为模型用来识别该类别的可解释概念方向。
- 基于梯度的偏见估计:当模型误分类一个样本时,反向传播的梯度告诉你如何调整激活来修正错误。
对于假阴性(漏掉一只鸟),梯度指向增加会让模型说”鸟”的激活。
对于假阳性(幻觉出一只鸟),梯度指向减少这些激活。
虚假概念(如”水背景”)会在假阴性上显示高正梯度(模型漏掉的水鸟),在假阳性上显示高负梯度(模型错误地称为水鸟的陆鸟)。
偏见分数捕捉这种不对称性:对一种错误需要放大、对另一种错误需要抑制的概念很可能是虚假捷径。
- 对冻结模型的事后干预:大多数去偏方法用修改的目标或数据重新训练模型。
本文在推理时通过识别激活空间中的虚假概念方向并将其投影出去来干预——就像偏见的噪声消除。
模型的参数保持冻结; 你只是过滤其内部表示。
这对于重新训练成本过高的已部署模型,或在部署后发现新偏见时至关重要。
权衡:你不能从根本上改变模型学到的东西,只能抑制特定的决策路径。
框架转变
之前(主流方法):                之后(本文方法):

训练时:                          训练时:
  数据 + 偏见标注                    数据 + 仅类别标注
       |                                  |
       v                                  v
  重加权 / 对抗                        正常训练
       |                                  |
       v                                  v
  去偏模型                             标准模型
                                          |
                                          v
                                       部署
                                          |
                                          v
                                       审计阶段:
                                         收集块
                                         NMF -> 概念
                                         梯度探针
                                          |
                                          v
                                       推理时抑制

需要:提前知道偏见                   需要:仅类别标注
灵活性:训练后无                     灵活性:迭代审计
[一句话:从将偏见缓解烘焙到训练中到将其作为部署后过滤器应用,核心转变是从预防到侦查。
]
专家评审
选题眼光:真实缺口。
场景——已部署模型、未知偏见、无重训练预算——在工业界常见但在研究中服务不足。
大多数偏见工作假设你知道要找什么并且可以重新训练。
本文针对更难的情况。
方法成熟度:基于梯度的偏见分数很巧妙但缺乏深入论证。
为什么假阴性和假阳性之间的不对称性应该专门隔离虚假概念而不仅仅是难学的特征? 论文展示了它在经验上有效,但没有提供理论基础。
用NMF进行概念发现是标准做法; 新颖之处在于排序标准。
该方法足够简单以至于实用,这是一个优势。
实验诚意:基线公平——他们与其他事后方法(CAV、TCAV)比较,并展示他们的方法在没有概念标注的情况下有效。
数据集(Colored MNIST、Waterbirds、CelebA)是标准偏见基准。
然而,改进是在最差组准确率上测量的,这可以通过牺牲整体准确率来操纵。
论文报告了两者,这是诚实的,但权衡曲线可以更突出。
一个担忧:该方法假设误分类样本可用且代表偏见,如果审计数据集很小或不平衡,这可能不成立。
写作功力:论文在方法部分很清晰,但在局限性部分匆忙。
第5节(实验)可以更好地分离”它找到正确的概念了吗? “和”抑制有帮助吗? ”。
相关工作部分很全面但可以精简。
最大的错失机会:没有讨论方法何时失败。
如果偏见概念与有效特征纠缠怎么办? 如果梯度有噪声怎么办? 失败模式分析会将这篇文章从技术论文提升到方法论文。
判决:弱接收 — 用实用解决方案解决真实问题,但理论论证薄弱,实验范围狭窄(三个数据集,都有已知的真实偏见)。
需要在虚假概念真正未知的情况下进行更广泛的评估。
要点总结
梯度不对称作为偏见信号:虚假概念在假阴性与假阳性上显示相反梯度模式的想法是可迁移的。
你可以应用这个来调试其他模型失败——不仅是偏见,还有任何系统性错误,其中模型在某些上下文中过度使用某个特征而在其他上下文中使用不足。
用于可解释分解的NMF:如果你需要激活空间中人类可解释的方向,与PCA相比,NMF的非负性约束被低估了。
当你想要基于部分的、加性的概念而不是抽象轴时,值得尝试。
推理时干预:更广泛的教训是你并不总是需要重新训练。
如果你能识别表示空间中的问题方向,你可以在推理时将它们过滤掉。
这适用于偏见之外——想想对抗鲁棒性、领域适应或为公平性移除敏感属性。
先审计后行动的工作流:论文展示了一种两阶段方法:首先审计模型以发现问题,然后干预。
这比假设你提前知道所有问题更现实。
工作流本身——收集样本、分解、排序、抑制——是事后模型调试的模板。