Paper: 2607.25993 Authors: Fengxiang Wang, Jiangnan Huang, Mingshuo Chen, Yueying Li, Yang Shi, Junwei Luo, Haoyu Wang, Yansheng Li, Jing Zhang, Haiyan Zhao Categories: cs.CV
The Gap
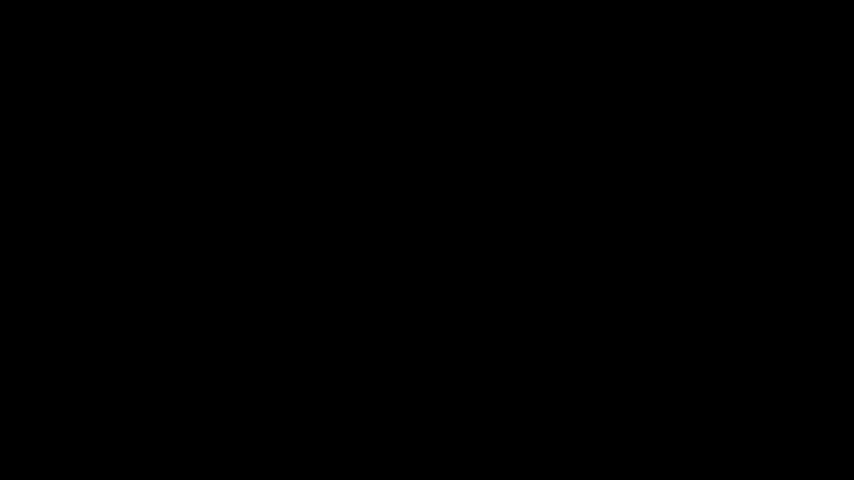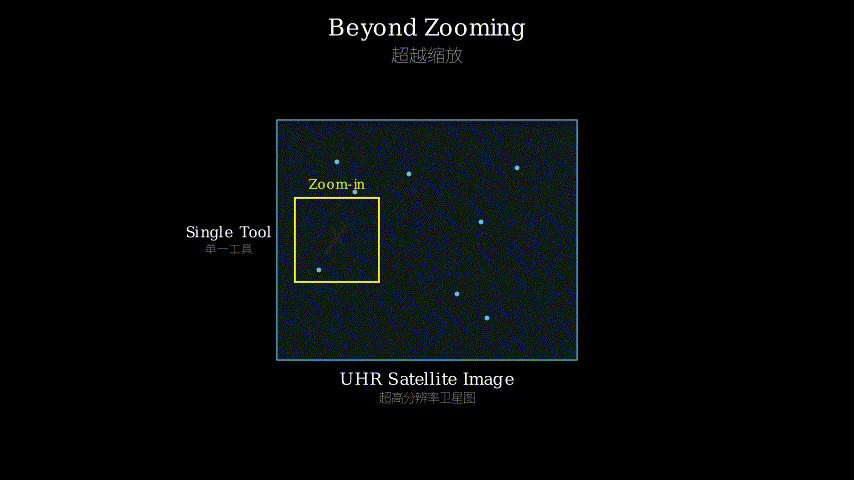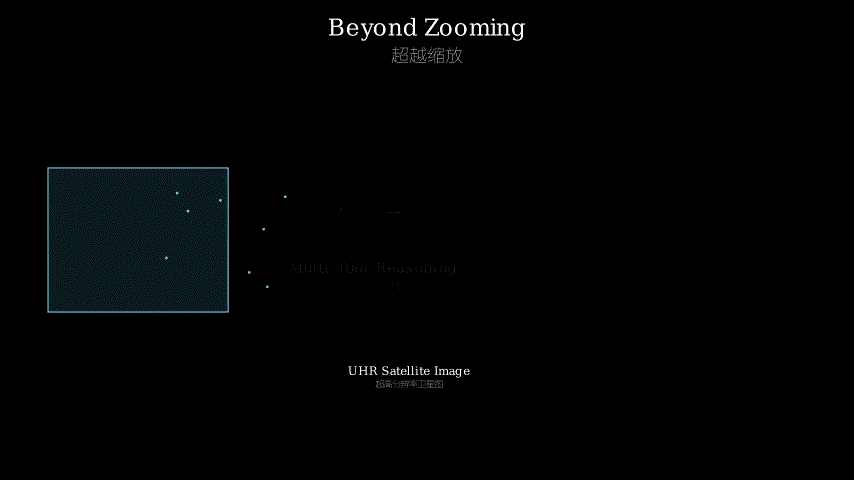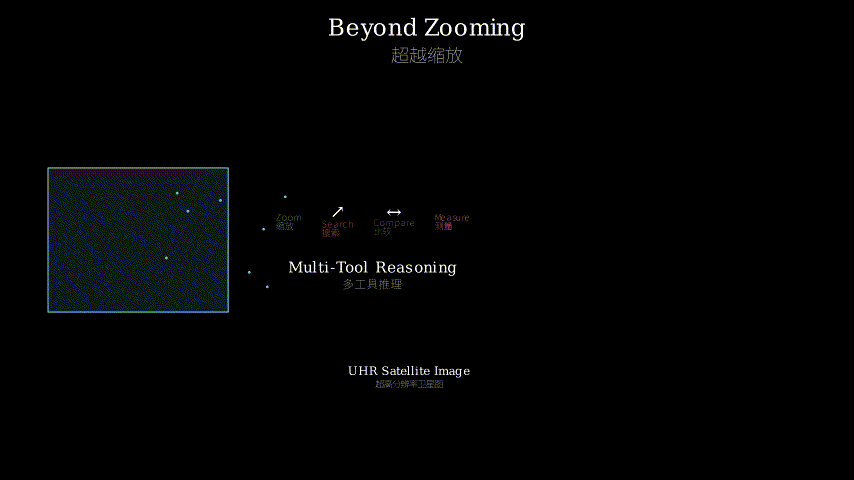
Multimodal large language models (MLLMs) have made impressive strides on visual question answering, but ultra-high-resolution (UHR) remote sensing imagery exposes a blind spot: a single satellite tile can cover a city at sub-meter resolution, and the relevant evidence is often a few pixels scattered across an enormous canvas. The natural response—equip the model with a zoom-in tool and let it inspect regions actively—works well on easy and medium tasks, as the authors demonstrate on XLRS-Bench. But zoom-in alone saturates on hard cases that demand global search, multi-region comparison, path planning, or assembling evidence from dispersed locations. Prior tool-augmented VLM work (e.g., LLaVA-based tool users) treats vision tools as monolithic “look closer” gadgets. Nobody has systematically asked: what happens when you need different tools for different sub-problems within a single question, and you need to chain them together with reasoning?
Problem: UHR images are too large for a single glance;
         relevant evidence is sparse and scattered
         |
         v
Prior assumption: a zoom-in tool is sufficient
                   for active visual inspection
         |
         v
But: hard tasks require global search, multi-region
     comparison, path planning, dispersed evidence
         |
         v
Method: multi-tool reasoning framework (GeoMTVR data
        + GeoLens model) with tool-attention RL
         |
         v
Evidence: GeoLens outperforms single-tool zoom-in on
          hard tasks by 8-15%, with shorter trajectories
         |
         v
Conclusion: MLLMs for UHR remote sensing need a
            full toolkit, not just a magnifying glass
The Increment
One sentence: Before this paper, UHR remote sensing reasoning was “zoom in and hope”; after this paper, it’s “pick the right tool for each sub-task, chain them, and learn when to stop.”
Core Mechanism
GeoLens works in three layers. First, a large-scale dataset called GeoMTVR is constructed from wide-area satellite imagery. Each of the 13K samples contains not just a question and answer, but a full interleaved reasoning trajectory: the model’s thought process, the sequence of tool calls it makes, the visual observations returned by each tool, and the final grounded answer. The tools available include zoom-in (local crop), global search (scan the whole image), object detection, measurement, and path planning.
Second, supervised fine-tuning (SFT) on GeoMTVR teaches the model the grammar of multi-tool reasoning—how to decompose a complex question into sub-problems, select appropriate tools for each, ground its answer in the returned evidence, and integrate observations across tools. Third, a reinforcement learning stage with “tool-attention-focused” optimization concentrates the reward signal on critical decision points: when to invoke a tool, which tool to select, where to apply it spatially, and how to interpret the output. This RL design avoids diluting the gradient signal across the entire response and instead highlights the moments that matter most for tool use.
User Question (over UHR image)
          |
          v
+---------------------+
| Question Decomposer | -- splits into sub-problems
+---------------------+
          |
          v
+---------------------+
| Tool Selector (RL)  | -- picks tool per sub-problem
+---------------------+
    |       |       |
    v       v       v
 [Zoom] [Search] [Detect]   <- visual tools
    |       |       |
    v       v       v
+---------------------+
| Evidence Integrator | -- combines tool outputs
+---------------------+
          |
          v
    Grounded Answer
Think of it like a field geologist dispatched to survey a city-sized plot of land. A junior geologist might walk to the center and squint (that’s the zoom-in baseline). A senior geologist instead unfolds a topographic map first (global search), identifies three candidate sites, drives to each (regional inspection), takes core samples at specific spots (object detection / zoom-in), measures distances between outcrops (measurement tool), and finally synthesizes all observations into a single report (evidence integration). The “junior” gets lucky on easy questions (“is there a river nearby?”) but fails on hard ones (“compare soil erosion patterns between the north and south banks and estimate which side needs a retaining wall first”). GeoLens trains the model to act like the senior geologist—knowing which tool to pull out when, and more importantly, when to stop surveying and start writing the report.
Key Concepts
-
Interleaved reasoning trajectories: Unlike standard VQA datasets where you get question → answer, GeoMTVR records the full chain of thought *and action. Imagine watching a chess game not just as “White wins” but move by move, with annotations explaining why each piece moved. Each sample shows: the model’s thought (“I need to compare the two buildings on the east side”), its tool call (“zoom to region [x1,y1,x2,y2]”), the tool’s visual return (the cropped image), and the model’s interpretation. This teaches the model not just what to answer but how to look.
-
Tool-attention-focused RL: Standard RL on the full answer dilutes the learning signal—you’re rewarding or penalizing everything equally, including the boilerplate text between tool calls. This paper’s insight is to identify the “attention hotspots” in the reasoning trajectory (the actual tool-call decisions) and concentrate the optimization there. It’s like grading a student’s lab report by focusing specifically on whether they chose the right experimental instruments, rather than grading every sentence equally.
Framework Shift
Before (mainstream approach):            After (this paper):

+-----------+    +---------+             +-----------+    +------------------+
| UHR Image | -> | MLLM    |             | UHR Image | -> | Question         |
+-----------+    |         |             +-----------+    | Decomposer       |
                 | zoom?   |                              +------------------+
                 | maybe   |                  |              |           |
                 +---------+                  v              v           v
                      |                   +------+      +------+   +--------+
                      v                   | Zoom |      |Search|   | Detect |
                  Answer                  +------+      +------+   +--------+
                      ^                      |              |           |
                      |                      v              v           v
                      +----------------------------------------------+
                                         |
                                         v
                                    Integrator --> Answer
From single-tool zoom-in to multi-tool orchestration, the core shift is treating UHR visual reasoning as a tool selection and sequencing problem rather than a region inspection problem.
Expert Assessment
Problem choice: This is a real gap. The remote sensing community has been hand-waving about “just zoom in” for UHR reasoning without stress-testing that assumption on genuinely hard compositional tasks. The pilot study on XLRS-Bench is convincing—showing that zoom-in saturates on hard cases before the method is even introduced is the right way to motivate a paper.
Method maturity: Clever rather than brute force. The tool-attention-focused RL idea is the intellectual contribution that distinguishes this from “just SFT on more data.” That said, the paper doesn’t deeply explore whether a simpler approach—like prompting with a tool-use scaffold and no RL—could get 80% of the gains. The RL adds complexity and training instability; an ablation that isolates its marginal contribution more sharply would strengthen the claim.
Experimental integrity: Baselines are reasonable—they compare against direct reasoning, single-tool zoom-in, and a multi-tool SFT-only variant. The gains on hard tasks (8-15%) are meaningful. However, GeoMTVR is self-constructed, and the benchmark (XLRS-Bench) appears to come from the same research group, which raises a mild independence concern. It would be more convincing to see evaluation on an external benchmark. The tool-use trajectory efficiency metrics are a nice addition—they show GeoLens solves problems with fewer tool calls, suggesting it’s learning *when not to look.
Writing quality: The paper is well-structured but the related work section is perfunctory—it could better position against the growing body of agentic VLM work (e.g., visual tool use in general domains). The GeoMTVR construction pipeline deserves its own figure with clearer detail; currently the data curation process is described somewhat opaquely. If the authors rewrote Section 3 (dataset construction) with full transparency on filtering criteria, inter-annotator agreement, and failure cases, the whole paper would gain credibility.
Verdict: weak accept — The multi-tool framing is the right direction for UHR remote sensing, and the tool-attention RL idea is a genuine contribution, but the self-constructed data and benchmark, plus the missing exploration of simpler alternatives, keep it from a strong accept.
Takeaways
Three concrete ideas to steal:
-
Tool-attention-focused RL: If you’re training an agent that uses external tools, don’t spread your RL reward uniformly across the output. Identify the decision points (tool selection, parameter choice, output interpretation) and concentrate optimization there. This applies to any agentic system—coding assistants calling APIs, robotics planners invoking subroutines, etc.
-
Question decomposition as a training signal: GeoMTVR’s interleaved trajectories (thought → tool call → observation → next thought) are a template for building datasets that teach *process, not just outcome. If you’re building training data for any multi-step reasoning task, record the full trace, not just the endpoint.
-
Pilot-study-to-motivation pipeline: The paper’s structure—run a simple baseline, find where it fails, then design a method specifically for those failure cases—is textbook good practice. If you’re writing a paper, a crisp “here’s where the obvious approach breaks” section is worth more than five pages of related work.
论文: 2607.25993 作者: Fengxiang Wang, Jiangnan Huang, Mingshuo Chen, Yueying Li, Yang Shi, Junwei Luo, Haoyu Wang, Yansheng Li, Jing Zhang, Haiyan Zhao 分类: cs.CV
缺口
多模态大语言模型(MLLM)在视觉问答上已经取得了长足进步,但超高分辨率(UHR)遥感图像暴露了一个盲区:一张卫星图可以覆盖整个城市、分辨率达到亚米级,而相关证据往往只是散布在巨大画布上的几个像素。最直觉的方案——给模型配一个放大工具,让它主动巡查局部区域——在简单和中等难度任务上确实有效,作者在 XLRS-Bench 上也验证了这一点。但仅靠”放大镜”在困难任务上已经饱和:那些需要全局搜索、多区域对比、路径规划、或从分散位置拼凑证据的题目,放大镜根本帮不上忙。此前的工具增强视觉语言模型(如基于 LLaVA 的工具调用模型)把视觉工具当作单一的”看近一点”的装置。没有人系统性地追问:当一道题内需要不同工具处理不同子问题,并且要把它们串联起来推理时,会发生什么?
问题:UHR 图像太大,一眼看不完;
     有用证据稀疏且分散
     |
     v
此前假设:一个放大工具就够用于
         主动视觉巡查
     |
     v
但是:困难任务需要全局搜索、多区域
     对比、路径规划、分散证据整合
     |
     v
方法:多工具推理框架(GeoMTVR 数据
     + GeoLens 模型)+ 工具注意力 RL
     |
     v
证据:GeoLens 在困难任务上比单工具
     放大基线高 8-15%,且轨迹更短
     |
     v
结论:UHR 遥感需要的是完整工具箱,
     不是一把放大镜
增量
一句话: 这篇论文之前,UHR 遥感推理是”放大了再说”;这篇论文之后,它变成了”针对每个子问题选对工具、串联起来、并知道何时该停”。
核心机制
GeoLens 分三层运作。第一层是大规模数据集 GeoMTVR,由宽幅卫星影像构建。13K 个样本不仅包含问答对,还包含完整的交错推理轨迹:模型的思考过程、工具调用序列、每个工具返回的视觉观测,以及最终有据可依的答案。可用工具包括放大裁剪(局部观察)、全局扫描(遍历全图)、目标检测、测量和路径规划。
第二层是在 GeoMTVR 上做监督微调(SFT),教会模型多工具推理的”语法”——如何将复杂问题拆解为子问题、为每个子问题选择合适工具、将答案锚定在返回的证据上、以及跨工具整合观测结果。第三层是”工具注意力聚焦”的强化学习阶段,将奖励信号集中在关键决策点上:何时调用工具、选择哪个工具、在哪里施加、如何解读输出。这种 RL 设计避免了梯度信号在整段回答中被稀释,而是将优化聚焦在工具使用最关键的时刻上。
用户问题(针对 UHR 图像)
          |
          v
+---------------------+
| 问题拆解器           | -- 分解为子问题
+---------------------+
          |
          v
+---------------------+
| 工具选择器 (RL)      | -- 为每个子问题选工具
+---------------------+
    |       |       |
    v       v       v
 [放大]  [扫描]  [检测]   <- 视觉工具
    |       |       |
    v       v       v
+---------------------+
| 证据整合器           | -- 汇总各工具输出
+---------------------+
          |
          v
     有据可依的回答
可以把它想象成一位被派去勘察城市级地块的资深地质学家。新手地质学家的做法是走到地块中心眯着眼看(这就是放大基线)。而资深地质学家会先展开地形图(全局搜索),圈出三个候选区域,开车到每个点(区域巡查),在特定位置取岩芯样本(目标检测/放大),测量露头之间的距离(测量工具),最后把所有观测综合成一份报告(证据整合)。新手在简单问题上能靠运气答对(“附近有河流吗?”),但在困难问题上就露馅了(“对比南北两岸的土壤侵蚀模式,判断哪边更急需建挡土墙”)。GeoLens 就是把模型训练成资深地质学家——知道什么时候该掏什么工具,更重要的是,知道什么时候该停下来写报告。
关键概念
-
交错推理轨迹: 标准 VQA 数据集只给”问题 → 答案”,GeoMTVR 记录了完整的思维**和行动链。想象看一盘棋不是只看”白方胜”,而是逐着复盘,并注解每步为什么这样走。每个样本展示:模型的思考(“我需要对比东侧两栋建筑”)、工具调用(“放大到 [x1,y1,x2,y2] 区域”)、工具返回的视觉结果(裁剪后的图像)、以及模型的解读。这教给模型的不只是答什么*,而是怎么看。
-
工具注意力聚焦 RL: 对整段回答做标准 RL 会稀释学习信号——你在平等地奖励或惩罚所有内容,包括工具调用之间的套话。本文的洞察是:识别推理轨迹中的”注意力热点”(也就是实际的工具调用决策点),将优化集中在那里。这就像批改实验报告时,重点看学生是否选对了实验仪器,而不是每句话都打分。
框架转变
之前(主流方法):                  之后(本文方法):

+-----------+   +-------+          +-----------+   +------------------+
| UHR 图像  | ->| MLLM  |          | UHR 图像  | ->| 问题拆解器        |
+-----------+   |       |          +-----------+   +------------------+
                | 放大? |              |              |           |
                | 随缘   |              v              v           v
                +-------+          +------+      +------+   +--------+
                    |               | 放大 |      | 扫描 |   | 检测   |
                    v               +------+      +------+   +--------+
                 回答                  |              |           |
                    ^                  v              v           v |
                    +----------------------------------------------+
                                         |
                                         v
                                    整合器 --> 回答
从单工具放大到多工具编排,核心转变是把 UHR 视觉推理当作一个工具选择与排序问题,而非一个区域巡查问题。
专家评审
选题眼光: 这是一个真实的缺口。遥感社区一直在用”放大就行”来处理 UHR 推理,但从未在真正困难的组合任务上严格检验过这个假设。在介绍方法之前先在 XLRS-Bench 上展示放大镜的饱和现象,是正确的问题动机引出方式。
方法成熟度: 是巧劲而非蛮力。工具注意力聚焦 RL 是区分本文和”多堆数据做 SFT”的核心学术贡献。但论文没有深入探讨更简单的方案——比如用工具使用脚手架做提示、不做 RL——能获得百分之多少的收益。RL 增加了复杂性和训练不稳定性;更清晰地隔离其边际贡献的消融实验会让论点更有力。
实验诚意: 基线选择合理——对比了直接推理、单工具放大、以及多工具纯 SFT 变体。困难任务上的增益(8-15%)是有意义的。但 GeoMTVR 是自行构建的,而评测基准(XLRS-Bench)似乎出自同一课题组,这带来轻微的独立性担忧。如果能在外部基准上看到评测结果会更有说服力。工具使用轨迹效率指标是一个亮点——它表明 GeoLens 用更少的工具调用解决问题,说明模型学会了**什么时候不该看*。
写作功力: 论文结构清晰,但相关工作部分草草了事——应该更好地与日益增长的智能体视觉语言模型工作(如通用领域的视觉工具使用)进行定位。GeoMTVR 的构建流程值得单独一图并更清晰地展示;目前数据筛选过程的描述不够透明。如果作者重写第三节(数据集构建),完全公开筛选标准、标注者一致性、和失败案例,整篇论文的可信度会更上一层楼。
判决: 弱接收 — 多工具框架是 UHR 遥感的正确方向,工具注意力 RL 也是有实质贡献的想法,但自建数据和基准、加上对更简单替代方案的探索不足,使得它够不上强接收。
要点总结
三个可以”偷”走的具体想法:
-
工具注意力聚焦 RL: 如果你在训练使用外部工具的智能体,不要把 RL 奖励均匀铺在输出上。找出决策点(工具选择、参数设定、输出解读),把优化集中在那里。这适用于任何智能体系统——调用 API 的代码助手、调用子程序的机器人规划器等。
-
问题拆解作为训练信号: GeoMTVR 的交错轨迹(思考 → 工具调用 → 观测 → 下一步思考)是构建教**过程而非结果*的数据集的模板。如果你在为任何多步推理任务建训练数据,记录完整轨迹,不要只记录终点。
-
从预实验到动机的管线: 论文的结构——跑一个简单基线、找到它的失败点、然后针对失败点设计方法——是教科书级的好做法。如果你在写论文,一段利落的”这里是直觉方案的崩溃点”比五页相关工作更有价值。