Paper: 2603.03276 Authors: Shengbang Tong, David Fan, John Nguyen, Ellis Brown, Gaoyue Zhou, Shengyi Qian, Boyang Zheng, Théophane Vallaeys, Junlin Han, Rob Fergus Categories: cs.CV
The Gap
Most multimodal models today are language models with vision bolted on. GPT-4V, Gemini, Claude — they all started as language models, then learned to “see” through additional training. This approach works, but it leaves a fundamental question unanswered: what does native multimodal pretraining look like when you don’t inherit language model biases?
The design space is opaque. We don’t know how vision and language data interact during joint training from scratch. We don’t know if they need the same model capacity, the same amount of data, or even the same training objectives. Prior work either fine-tunes pretrained language models on vision tasks or trains small-scale multimodal models without systematic ablations.
This paper strips away the confounding factors. They train everything from scratch, control for compute, and isolate what actually matters.
Problem: Multimodal models inherit language-first biases
   |
   v
Assumption: Vision and language have different scaling properties
   |
   v
Method: From-scratch pretraining + IsoFLOP analysis + MoE architecture
   |
   v
Evidence: Vision needs 10x more data; MoE harmonizes the asymmetry
   |
   v
Conclusion: Native multimodal models require architecture-level solutions
The Increment
One sentence: Before this paper, we built multimodal models by adapting language models; after, we know vision and language scale asymmetrically and need MoE to balance their different appetites.
Core Mechanism
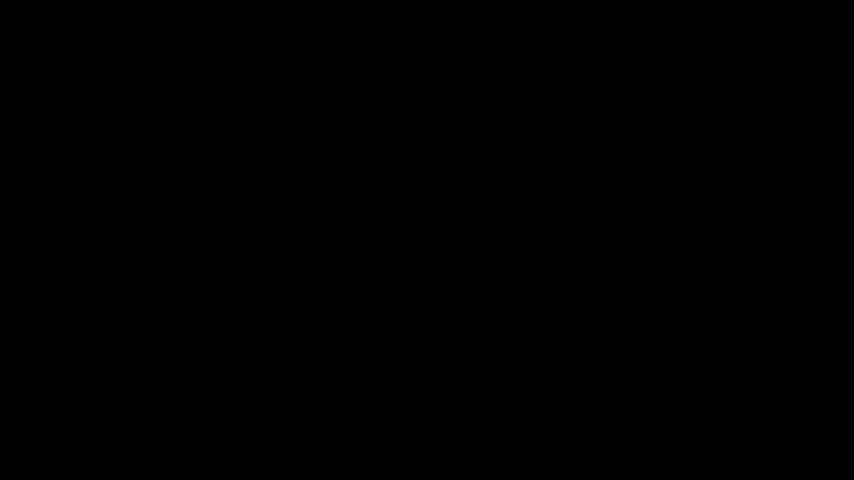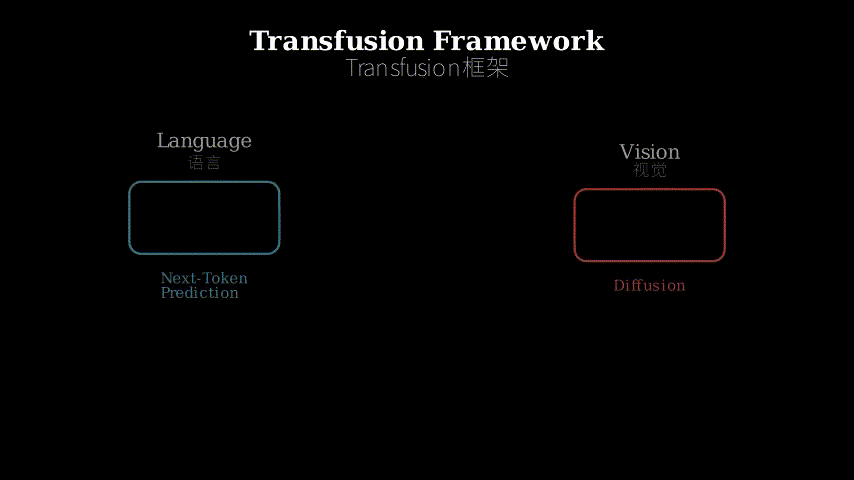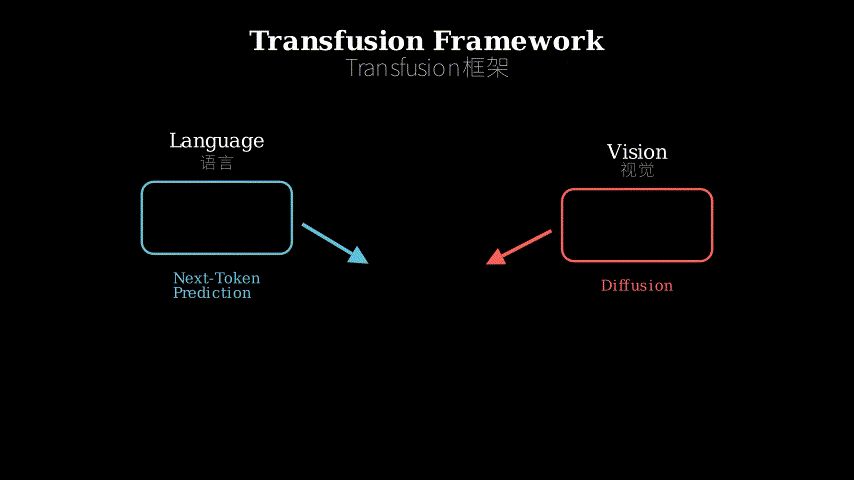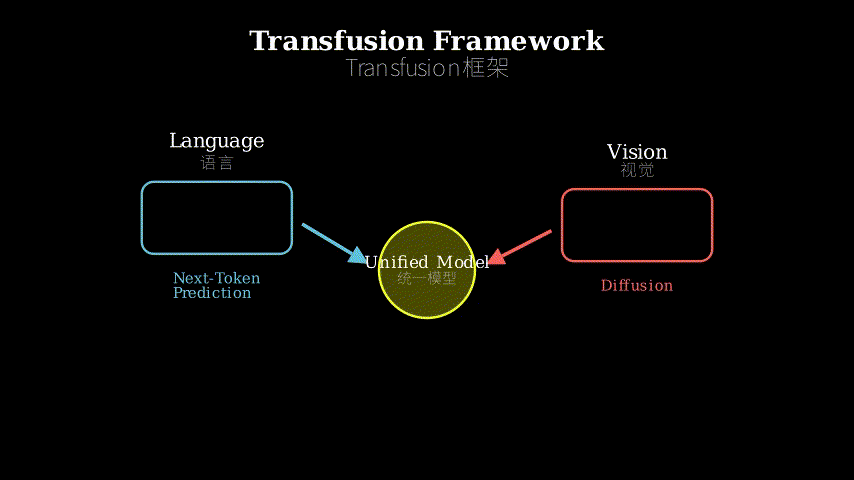
The method has three layers. First, they use Transfusion — a hybrid training framework where language uses next-token prediction (like GPT) and vision uses diffusion (like Stable Diffusion). This lets them train on text, images, videos, and image-text pairs in one unified model without forcing everything through the same objective.
Second, they introduce Representation Autoencoder (RAE) as the visual backbone. RAE compresses images into discrete tokens that work for both understanding (classification, captioning) and generation (image synthesis). Think of it as a universal translator between raw pixels and the model’s internal language.
Third, they run IsoFLOP experiments — training different model configurations with the same total compute budget. This reveals scaling laws: how performance changes as you vary data mix, model size, and architecture. The key finding: vision needs vastly more data than language to reach comparable performance.
Input Data Stream
   |
   +---> [Text] ---> Next-Token Prediction ---> Language Loss
   |
   +---> [Images/Video] ---> RAE Encoder ---> Discrete Tokens
                                |
                                v
                          Diffusion Process ---> Vision Loss
                                |
                                v
                          Combined Gradient ---> Model Update
                                |
                                v
                          [Shared Transformer + MoE Layers]
Think of this like running a restaurant with two kitchens. The language kitchen (next-token prediction) is efficient — it can serve many customers with modest ingredients. The vision kitchen (diffusion) is demanding — it needs premium ingredients in bulk to produce quality dishes. RAE is the prep station that standardizes ingredients from both suppliers. The MoE architecture is your staffing solution: you hire specialist chefs for each kitchen, but they share the dining room and back-office infrastructure. Without MoE, you’d either overstaff the language kitchen (wasting capacity) or understaff the vision kitchen (poor quality). The asymmetry isn’t a bug — it’s the nature of the cuisines.
Key Concepts
-
IsoFLOP Analysis: Imagine you have a fixed energy budget to train models. IsoFLOP means you compare different designs (bigger model with less data vs. smaller model with more data) while keeping total compute constant. It’s like comparing cars by miles-per-gallon at the same trip distance, not just top speed. This reveals true efficiency: which design extracts the most performance from the same resources? In this paper, IsoFLOP analysis exposed that vision models need to “see” 10x more examples than language models need to “read” to achieve similar capability gains.
-
Representation Autoencoder (RAE): Most vision models specialize — CLIP for understanding, diffusion models for generation. RAE does both with one representation. It compresses an image into discrete tokens (like turning a photo into a short code), then can either decode those tokens back into pixels (generation) or feed them to a classifier (understanding). The trick: the compression is learned to preserve information useful for both tasks. Concrete example: RAE encodes a cat photo into tokens [42, 891, 3, …], which can reconstruct the cat OR be classified as “cat” — same tokens, dual purpose.
-
Scaling Asymmetry: Language and vision don’t scale the same way. If you double your language data, you get predictable improvements. But vision is greedier — it needs 10x more data to get the same relative improvement. Why? Language has compositional structure (words combine systematically), while vision has exponential variation (lighting, angles, occlusion, textures). It’s like learning chess vs. learning to recognize faces: chess has finite rules you can master with moderate practice, but faces have infinite variation requiring massive exposure.
Framework Shift
Before (mainstream approach):        After (this paper):

[Pretrained LLM]                     [From-Scratch Training]
       |                                      |
       v                                      v
  Add Vision Adapter              [Transfusion Framework]
       |                            /                  \
       v                           v                    v
  Fine-tune on                [Language]            [Vision]
  Image-Text Pairs            Next-Token            Diffusion
       |                      Prediction               |
       v                           \                  /
  Multimodal Model                  v                v
  (language-centric)           [Unified Model + MoE]
                               (balanced modalities)
From bolting vision onto language models to designing architectures that respect each modality’s native scaling properties, the core shift is treating multimodality as a first-class design problem rather than an adaptation problem.
Expert Assessment
Problem choice: This is a real gap. The field has been building multimodal models pragmatically — start with what works (language models) and extend. But we’re hitting limits. Models like GPT-4V are impressive yet clearly language-biased in their reasoning. Understanding native multimodal scaling is foundational work that will age well. It sits at an inflection point where compute budgets allow from-scratch experiments that were previously prohibitive.
Method maturity: Mostly solid engineering with one clever insight (RAE for unified representation). The Transfusion framework isn’t novel — it’s borrowed from prior work. The MoE application is straightforward. The real contribution is the systematic ablation study and IsoFLOP analysis. They’re not inventing new techniques; they’re rigorously measuring what matters. That said, the 10x data asymmetry finding feels almost too clean — I’d want to see if it holds across different vision domains (medical imaging, satellite imagery) or if it’s specific to natural images.
Experimental integrity: The baselines are fair and the ablations are thorough. They control for compute, which is rare and commendable. However, the paper doesn’t deeply explore failure modes. What happens when you push MoE scaling further? Do the modality-specific experts actually specialize, or do they collapse into redundancy? The scaling laws are derived from limited compute ranges — extrapolation to GPT-4 scale is speculative. Also, they claim “world modeling” emerges naturally, but the evidence is thin — a few cherry-picked examples, not systematic evaluation.
Writing quality: The paper front-loads claims without sufficient setup. The abstract promises “four key insights” but doesn’t explain why these specific four matter. The related work section is perfunctory — it lists prior work without critically positioning this contribution. The experimental section is dense with numbers but light on intuition. If they rewrote the introduction to tell a story (why does native multimodal pretraining matter? what’s at stake?), the paper would be far more compelling. The conclusion oversells — “paving the way for truly unified multimodal models” is premature given the limited scale.
Verdict: weak accept — Solid empirical work that advances our understanding of multimodal scaling, but lacks the conceptual depth or scale to be a landmark contribution.
Takeaways
The 10x data asymmetry is the actionable insight. If you’re building a multimodal system, don’t assume vision and language need equal resources. Budget accordingly: vision needs more data, language needs more model capacity. The MoE solution is practical — you can scale modalities independently without wasting parameters.
RAE’s dual-purpose representation is worth stealing. If you’re designing any encoder, ask: can this representation serve multiple downstream tasks? Unified representations reduce engineering complexity and often improve both tasks through shared structure.
The IsoFLOP methodology transfers. Anytime you’re comparing architectures, control for total compute. It’s the only fair comparison and reveals true efficiency gains versus just throwing more resources at the problem.
One warning: the “world modeling” claim is oversold. Don’t expect emergent capabilities from general multimodal training without task-specific design. The paper shows correlation, not causation.
论文: 2603.03276 作者: Shengbang Tong, David Fan, John Nguyen, Ellis Brown, Gaoyue Zhou, Shengyi Qian, Boyang Zheng, Théophane Vallaeys, Junlin Han, Rob Fergus 分类: cs.CV
缺口
当前的多模态模型大多是语言模型加装视觉能力。 GPT-4V、Gemini、Claude——它们都先是语言模型,然后通过额外训练学会”看”。 这种方法有效,但留下了一个根本问题:当你不继承语言模型的偏见时,原生多模态预训练应该是什么样子?
设计空间是不透明的。 我们不知道视觉和语言数据在从零开始的联合训练中如何互动。 我们不知道它们是否需要相同的模型容量、相同的数据量,甚至相同的训练目标。 先前的工作要么在视觉任务上微调预训练语言模型,要么训练小规模多模态模型而没有系统性消融实验。
这篇论文剥离了混淆因素。 他们从零训练所有东西,控制计算量,隔离出真正重要的因素。
问题:多模态模型继承了语言优先的偏见
   |
   v
假设:视觉和语言有不同的缩放特性
   |
   v
方法:从零预训练 + 等算力分析 + MoE架构
   |
   v
证据:视觉需要10倍数据;MoE调和不对称性
   |
   v
结论:原生多模态模型需要架构层面的解决方案
增量
一句话: 这篇论文之前,我们通过改造语言模型来构建多模态模型; 之后,我们知道视觉和语言的缩放不对称,需要MoE来平衡它们不同的胃口。
核心机制
方法分三层。 首先,他们使用Transfusion——一个混合训练框架,语言用下一词元预测(像GPT),视觉用扩散(像Stable Diffusion)。 这让他们能在一个统一模型中训练文本、图像、视频和图文对,而不强制所有东西通过同一个目标。
其次,他们引入表示自编码器(RAE)作为视觉骨干。 RAE将图像压缩成离散词元,既能用于理解(分类、描述),也能用于生成(图像合成)。 把它想象成原始像素和模型内部语言之间的通用翻译器。
第三,他们运行等算力实验——用相同的总计算预算训练不同的模型配置。 这揭示了缩放定律:当你改变数据混合、模型大小和架构时,性能如何变化。 关键发现:视觉需要比语言多得多的数据才能达到可比的性能。
输入数据流
   |
   +---> [文本] ---> 下一词元预测 ---> 语言损失
   |
   +---> [图像/视频] ---> RAE编码器 ---> 离散词元
                                |
                                v
                          扩散过程 ---> 视觉损失
                                |
                                v
                          组合梯度 ---> 模型更新
                                |
                                v
                          [共享Transformer + MoE层]
把这想象成经营一家有两个厨房的餐厅。 语言厨房(下一词元预测)很高效——它能用适量食材服务很多顾客。 视觉厨房(扩散)很苛刻——它需要大量优质食材才能做出高质量菜品。 RAE是预处理站,标准化来自两个供应商的食材。 MoE架构是你的人员配置方案:你为每个厨房雇佣专业厨师,但他们共享餐厅和后勤基础设施。 没有MoE,你要么语言厨房人员过剩(浪费产能),要么视觉厨房人手不足(质量差)。 不对称性不是bug——这是菜系的本质。
关键概念
-
等算力分析: 想象你有固定的能量预算来训练模型。 等算力意味着你比较不同设计(更大模型配更少数据 vs 更小模型配更多数据),同时保持总计算量恒定。 这就像通过相同行程距离的每加仑英里数来比较汽车,而不只是最高速度。 这揭示了真正的效率:哪种设计从相同资源中提取最多性能? 在这篇论文中,等算力分析暴露了视觉模型需要”看”10倍多的样本,才能达到语言模型”读”相同量获得的类似能力增益。
-
表示自编码器(RAE): 大多数视觉模型专门化——CLIP用于理解,扩散模型用于生成。 RAE用一种表示做两件事。 它将图像压缩成离散词元(就像把照片变成短代码),然后可以将这些词元解码回像素(生成)或送入分类器(理解)。 诀窍:压缩是学习出来的,保留对两个任务都有用的信息。 具体例子:RAE将猫照片编码成词元[42, 891, 3, …],既能重建猫,也能被分类为”猫”——相同词元,双重用途。
-
缩放不对称性: 语言和视觉的缩放方式不同。 如果你把语言数据翻倍,你会得到可预测的改进。 但视觉更贪婪——它需要10倍数据才能获得相同的相对改进。 为什么? 语言有组合结构(词汇系统性组合),而视觉有指数级变化(光照、角度、遮挡、纹理)。 这就像学国际象棋vs学认脸:国际象棋有有限规则,你可以通过适度练习掌握,但人脸有无限变化,需要大量接触。
框架转变
之前(主流方法):                之后(本文方法):

[预训练LLM]                     [从零训练]
       |                                      |
       v                                      v
  添加视觉适配器              [Transfusion框架]
       |                            /                  \
       v                           v                    v
  在图文对上                [语言]            [视觉]
  微调                    下一词元            扩散
       |                      预测               |
       v                           \                  /
  多模态模型                  v                v
  (语言中心)           [统一模型 + MoE]
                               (平衡模态)
从把视觉嫁接到语言模型,到设计尊重每个模态原生缩放特性的架构,核心转变是将多模态视为一流设计问题而非适配问题。
专家评审
选题眼光: 这是真缺口。 该领域一直在务实地构建多模态模型——从有效的东西(语言模型)开始并扩展。 但我们正在触及极限。 像GPT-4V这样的模型令人印象深刻,但在推理中明显偏向语言。 理解原生多模态缩放是基础性工作,会经得起时间考验。 它处于一个拐点,计算预算允许以前无法承受的从零实验。
方法成熟度: 主要是扎实的工程加一个巧妙洞见(RAE用于统一表示)。 Transfusion框架不新颖——借鉴自先前工作。 MoE应用很直接。 真正的贡献是系统性消融研究和等算力分析。 他们不是发明新技术; 他们在严格测量什么重要。 话虽如此,10倍数据不对称的发现感觉几乎太干净了——我想看看它是否在不同视觉领域(医学影像、卫星图像)中成立,还是特定于自然图像。
实验诚意: 基线公平,消融彻底。 他们控制计算量,这很罕见且值得称赞。 然而,论文没有深入探讨失败模式。 当你进一步推动MoE缩放时会发生什么? 模态特定专家真的专门化了,还是坍缩成冗余? 缩放定律是从有限计算范围推导的——外推到GPT-4规模是推测性的。 此外,他们声称”世界建模”自然涌现,但证据薄弱——几个精心挑选的例子,而非系统评估。
写作功力: 论文在没有充分铺垫的情况下前置声明。 摘要承诺”四个关键洞见”,但没解释为什么这四个特别重要。 相关工作部分敷衍——列出先前工作而没有批判性定位这一贡献。 实验部分数字密集但直觉稀薄。 如果他们重写引言来讲故事(为什么原生多模态预训练重要? 利害关系是什么? ),论文会更有说服力。 结论过度推销——“为真正统一的多模态模型铺平道路”在有限规模下为时过早。
判决: 弱接收——扎实的实证工作推进了我们对多模态缩放的理解,但缺乏概念深度或规模成为里程碑式贡献。
要点总结
10倍数据不对称是可操作的洞见。 如果你在构建多模态系统,不要假设视觉和语言需要相等资源。 相应地做预算:视觉需要更多数据,语言需要更多模型容量。 MoE解决方案很实用——你可以独立缩放模态而不浪费参数。
RAE的双用途表示值得借鉴。 如果你在设计任何编码器,问:这个表示能服务多个下游任务吗? 统一表示减少工程复杂性,通常通过共享结构改进两个任务。
等算力方法论可迁移。 任何时候你在比较架构,控制总计算量。 这是唯一公平的比较,揭示真正的效率增益而非只是向问题投入更多资源。
一个警告:“世界建模”声明被过度推销。 不要期望从通用多模态训练中涌现能力而没有任务特定设计。 论文展示了相关性,而非因果关系。