Paper: 2605.12483 Authors: Yuanda Xu, Hejian Sang, Zhengze Zhou, Ran He, Zhipeng Wang, Alborz Geramifard Categories: cs.LG, cs.AI
The Gap
When you have limited labeled data for training language models, the standard move is GRPO (Group Relative Policy Optimization) directly on the model you’ll deploy. You have 1000 verified math problems? Run GRPO on your 1.7B student model. Seems efficient—no middleman, no waste.
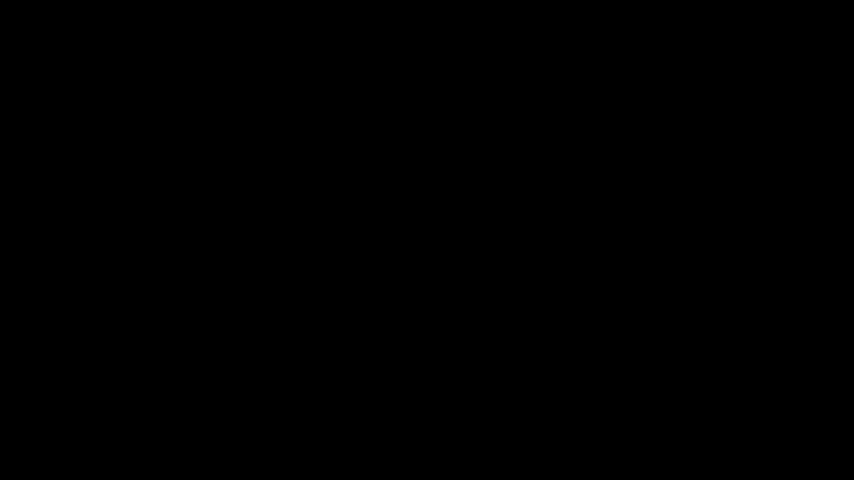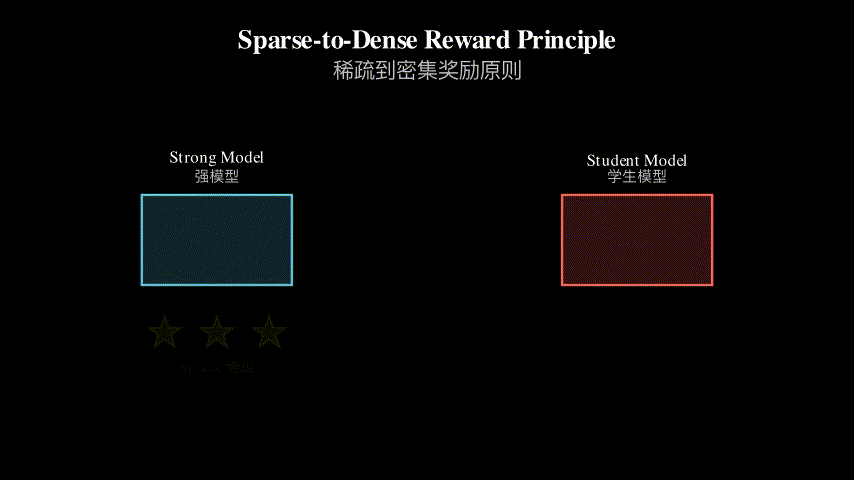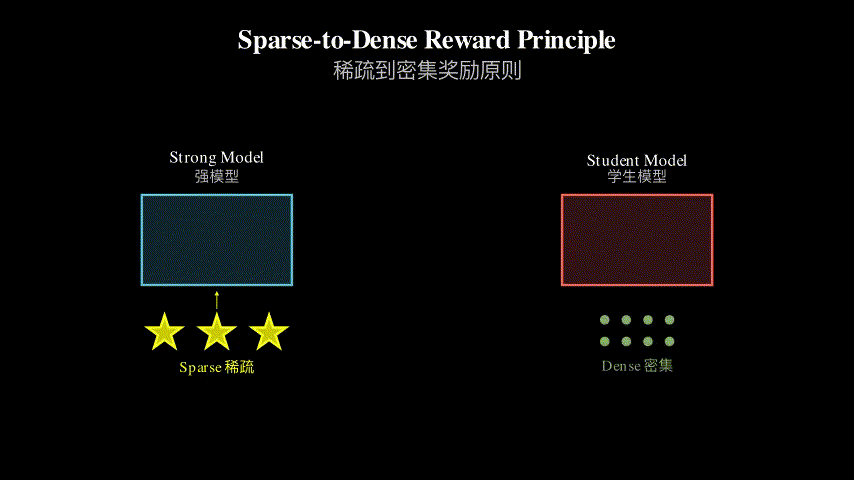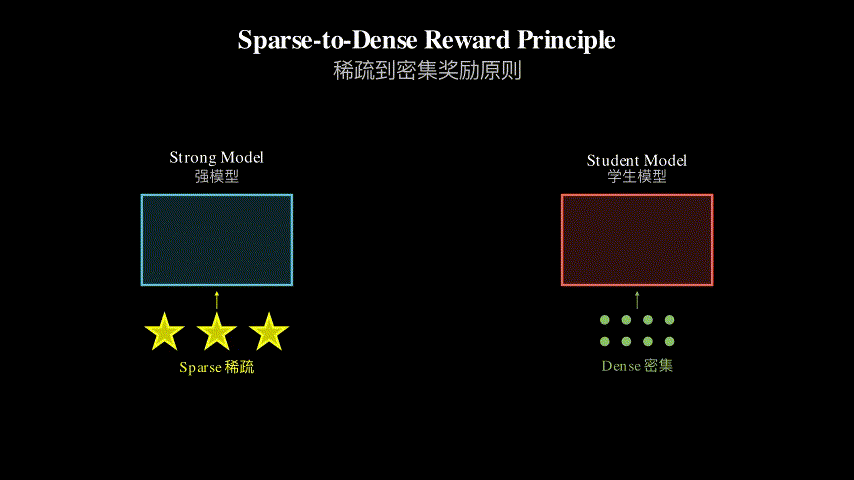
But this overlooks a resource allocation puzzle: sparse sequence-level rewards (right/wrong on a full solution) are good for exploration when the model can actually explore productively. Dense token-level rewards (teacher guidance at every step) are good for compressing existing behavior into a smaller model. The 1.7B student struggling with sparse reward is like asking a novice to learn surgery by only hearing “success” or “failure” after each operation—no intermediate feedback, no expert demonstration.
Prior work treats GRPO-style sparse RL and OPD-style (On-Policy Distillation) dense supervision as separate recipes for different scenarios. This paper argues they’re different reward-density regimes that should be sequenced: use scarce labeled data upstream on your strongest model where exploration works, then transfer that shaped behavior downstream as dense supervision.
Problem: Limited labeled data
    |
    v
Standard approach: GRPO directly on deployment student
    |
    +---> Inefficient: Small model + sparse reward = poor exploration
    |
    v
This paper's insight: Reward density should match model capacity
    |
    +---> Sparse reward (RL) ---> Large teacher (can explore)
    |                                    |
    |                                    v
    +---> Dense reward (distill) ---> Small student (compress behavior)
    |
    v
Evidence: 8B teacher + bridge + 1.7B student > direct GRPO on 1.7B
    |
    v
Conclusion: Allocate data by reward density, not just model size
The Increment
One sentence: Before this paper, you’d use scarce labeled data directly on your deployment model via sparse RL; after, you use it upstream on a large teacher, then densely distill to the student—gaining 3+ points on MATH by respecting the reward-density principle.
Core Mechanism
The method has three stages. Stage 1: Run GRPO on a large teacher model (8B or 14B) using your scarce labeled data. The teacher explores solution strategies under sparse sequence-level reward (correct/incorrect). This is where labeled data does its discovery work—the large model has capacity to try different approaches and learn from sparse feedback.
Stage 2 is the “bridge”—the paper’s key contribution. First, warm up the small student (1.7B) with forward-KL distillation on teacher rollouts. The student learns to mimic the teacher’s token distribution. Then switch to OPD: let the student generate its own rollouts, but train it using dense token-level supervision from the teacher’s policy. This two-phase bridge transfers the teacher’s shaped behavior into the student through dense reward.
Stage 3 (optional): Run GRPO on the student itself. After the bridge, the student has internalized enough structure that sparse reward becomes productive. Without the bridge, this same GRPO is weak—the student thrashes. With the bridge, GRPO lifts MATH accuracy from 75.4% to 78.5%, a 3.1-point gain.
Stage 1: Teacher RL          Stage 2: Bridge              Stage 3: Student RL

Labeled data                 Teacher rollouts             Student explores
    |                             |                            |
    v                             v                            v
[8B Teacher]                 [1.7B Student]              [1.7B Student]
    |                             |                            |
GRPO (sparse)                Forward-KL warmup           GRPO (sparse)
    |                             |                            |
    v                             v                            v
Explores solutions           Mimics teacher              Refines behavior
    |                             |                            |
    +-----> Shaped policy         v                            |
                             OPD on student rollouts          |
                                  |                            |
                                  v                            |
                             Dense token-level reward         |
                                  |                            |
                                  +----------------------------+
                                              |
                                              v
                                    Deployment-ready student
Think of it like training a chef. Stage 1: A master chef (teacher) experiments with your rare ingredients (labeled data), trying different techniques until they create excellent dishes. They work under sparse feedback—customers say “delicious” or “not good”—but the master has enough experience to explore productively.
Stage 2 (bridge): The apprentice (student) first watches the master cook (forward-KL), learning the general flow. Then the apprentice cooks while the master stands beside them, correcting every knife angle and seasoning choice in real-time (OPD with dense token-level guidance). The apprentice doesn’t waste rare ingredients exploring—they compress the master’s refined technique.
Stage 3: Now the apprentice can experiment with the rare ingredients themselves. They have enough internalized skill that sparse customer feedback (“delicious” or “not”) actually helps them improve, rather than leaving them confused.
The bridge is load-bearing: without it, the apprentice given rare ingredients and only sparse feedback produces mediocre results. The master’s exploration must be transferred densely before the apprentice’s own exploration becomes useful.
Key Concepts
-
Reward density: The granularity of feedback during training. Sparse reward gives one signal per complete sequence (e.g., “this 50-token math solution is correct/incorrect”). Dense reward gives signals at every token (e.g., “this next token should have probability 0.7 according to the teacher”). Sparse reward is cheap to collect when you have verifiable outcomes but provides little guidance during generation. Dense reward requires a teacher model but guides every decision. The paper’s core claim: match reward density to model capacity—large models can learn from sparse reward through exploration; small models need dense reward to compress existing behavior.
-
Forward-KL vs. Reverse-KL distillation: Forward-KL minimizes KL(teacher || student)—the student tries to cover all modes of the teacher’s distribution, even low-probability ones. This is “mode-covering.” Reverse-KL minimizes KL(student || teacher)—the student focuses on the teacher’s high-probability regions, ignoring low-probability modes. This is “mode-seeking.” The bridge uses forward-KL first to give the student broad coverage of the teacher’s behavior, then OPD (which is reverse-KL-like on student rollouts) to refine. Forward-KL on teacher rollouts prevents the student from collapsing to a narrow subset of the teacher’s capabilities.
-
On-Policy Distillation (OPD): Standard distillation trains the student on data sampled from the teacher. OPD trains the student on data sampled from the student itself, but uses the teacher’s token probabilities as the training target. Why does this matter? On-policy data reflects what the student will actually encounter at deployment. If you only train on teacher samples, the student may never learn to recover from its own mistakes. OPD with dense teacher reward is the paper’s “dense bridge”—the student explores its own distribution but gets token-level correction from the teacher at every step.
Framework Shift
Before (standard GRPO):                After (sparse-to-dense allocation):

Labeled data                           Labeled data
    |                                      |
    v                                      v
[1.7B Student]                         [8B Teacher]
    |                                      |
GRPO (sparse reward)                   GRPO (sparse reward)
    |                                      |
    v                                      v
Struggles to explore                   Explores productively
    |                                      |
    v                                      |
Mediocre performance                       v
                                       Teacher rollouts
                                           |
                                           v
                                       [1.7B Student]
                                           |
                                       Forward-KL + OPD
                                       (dense reward)
                                           |
                                           v
                                       Compressed behavior
                                           |
                                           v
                                       Optional student GRPO
                                           |
                                           v
                                       Strong performance
From direct sparse training on the deployment model to staged allocation by reward density, the core shift is: treat labeled data as fuel for the model that can burn it most efficiently, then transfer the refined output downstream.
Expert Assessment
Problem choice: This is a real gap. The field has been running GRPO on deployment models because it seems direct, but the implicit assumption—that the model you deploy should be the model you train with scarce data—hasn’t been questioned enough. The paper identifies a resource allocation inefficiency that practitioners face daily: small models struggle with sparse reward, but we keep feeding them sparse reward because that’s what we have. The problem sits at the intersection of RL and distillation, two areas that have been developing in parallel without much cross-pollination.
Method maturity: The insight is clever, not brute force. The three-stage pipeline isn’t novel in components—GRPO exists, OPD exists, forward-KL exists—but the sequencing and the reward-density framing are new. The bridge design (forward-KL warmup then OPD) shows careful thought: forward-KL prevents mode collapse, OPD keeps the student on-policy. However, the paper doesn’t explore simpler alternatives deeply enough. What if you just did more GRPO iterations on the teacher and skipped Stage 3? What if you used a medium-sized teacher (3B) instead of 8B? The ablations are solid but not exhaustive.
Experimental integrity: Baselines are fair. The paper compares against direct GRPO on the student, teacher-before-RL distillation (to show RL is necessary), and a replay control for Stage 3 (to show the bridge enables later RL). The numbers are consistent across Qwen and Llama families, which is reassuring. One red flag: the paper focuses heavily on MATH and AIME (math benchmarks). Does this generalize to other domains where verification is harder? The principle should hold, but the evidence is narrow. Another concern: the 8B teacher is 4.7x larger than the 1.7B student. How much of the gain is just “bigger model explores better” vs. the specific sparse-to-dense sequencing?
Writing quality: The abstract and introduction are dense—too many acronyms (GRPO, OPD, forward-KL) without enough intuition upfront. The reward-density principle is buried in the middle of the abstract when it should lead. Section 3 (method) is clear once you get there, but the path is cluttered. The ablations in Section 4 are thorough, but the paper would benefit from a single figure showing the full pipeline with data flow and reward types annotated. The related work section is perfunctory—it lists prior work but doesn’t position the contribution sharply enough. If the authors rewrote the introduction to lead with the chef metaphor (or similar), the paper would be far more accessible.
Verdict: Weak accept — The core insight (reward density should match model capacity) is valuable and the experimental evidence is solid within its scope, but the writing obscures the contribution and the evaluation is too narrow (math-only) to be fully convincing. The method works, but the paper needs clearer exposition and broader empirical validation.
Takeaways
If you’re training small models with limited labeled data, stop using that data directly on the small model. Train a larger model first—even if you won’t deploy it—because large models can explore under sparse reward. Then distill to your deployment model using dense supervision (forward-KL warmup + OPD). This isn’t just for math: any domain where you have verifiable outcomes but limited labeled examples (code generation, formal reasoning, constrained generation) should benefit.
The two-phase bridge (forward-KL then OPD) is a concrete technique you can steal. Forward-KL on teacher rollouts prevents the student from collapsing to a narrow behavior mode. OPD on student rollouts keeps the student on-policy while giving dense guidance. If you’re doing distillation, this sequence is worth trying.
The broader principle: allocate training resources by where they’re most productive, not by where they’ll be deployed. Scarce labeled data should train the model that can turn it into shaped behavior (large teacher + sparse RL). Dense supervision should train the model that needs to compress behavior (small student + distillation). This inverts the standard “train what you deploy” heuristic and suggests a staged pipeline is often more efficient.
论文: 2605.12483 作者: Yuanda Xu, Hejian Sang, Zhengze Zhou, Ran He, Zhipeng Wang, Alborz Geramifard 分类: cs.LG, cs.AI
缺口
当你手头的标注数据有限时,标准做法是直接在部署模型上跑 GRPO(群体相对策略优化)。
你有 1000 道验证过的数学题?
直接在 1.7B 的学生模型上跑 GRPO。
看起来很高效——没有中间商,没有浪费。
但这忽略了一个资源分配难题:稀疏的序列级奖励(整个解答对或错)适合在模型能有效探索时使用。
密集的词元级奖励(教师在每一步的指导)适合将已有行为压缩到更小的模型中。
让 1.7B 的学生在稀疏奖励下挣扎,就像让新手只通过每次手术后的”成功”或”失败”来学习外科手术——没有中间反馈,没有专家示范。
先前的工作把 GRPO 式的稀疏强化学习和 OPD 式(在线策略蒸馏)的密集监督当作不同场景下的独立方案。
本文认为它们是不同的奖励密度机制,应该按顺序使用:在最强的模型上用稀缺标注数据进行探索,然后将塑造好的行为作为密集监督迁移到下游。
问题:标注数据有限
    |
    v
标准方法:直接在部署学生模型上跑 GRPO
    |
    +---> 低效:小模型 + 稀疏奖励 = 探索能力差
    |
    v
本文洞察:奖励密度应匹配模型容量
    |
    +---> 稀疏奖励(强化学习)---> 大型教师(能探索)
    |                                    |
    |                                    v
    +---> 密集奖励(蒸馏)---> 小型学生(压缩行为)
    |
    v
证据:8B 教师 + 桥接 + 1.7B 学生 > 直接在 1.7B 上跑 GRPO
    |
    v
结论:按奖励密度分配数据,而非只看模型大小
增量
一句话:本文之前,你会直接在部署模型上通过稀疏强化学习使用稀缺标注数据;本文之后,你先在大型教师模型上游使用这些数据,再密集蒸馏到学生模型——通过遵循奖励密度原则,在 MATH 上获得 3 个以上百分点的提升。
核心机制
方法分三个阶段。
阶段 1:在大型教师模型(8B 或 14B)上使用稀缺标注数据跑 GRPO。
教师在稀疏的序列级奖励(正确/错误)下探索解题策略。
这是标注数据发挥发现作用的地方——大模型有能力尝试不同方法并从稀疏反馈中学习。
阶段 2 是”桥接”——本文的关键贡献。
首先,用教师的推理结果对小型学生模型(1.7B)进行前向 KL 蒸馏预热。
学生学习模仿教师的词元分布。
然后切换到 OPD:让学生生成自己的推理结果,但用教师策略的密集词元级监督来训练它。
这个两阶段桥接通过密集奖励将教师的塑造行为迁移到学生中。
阶段 3(可选):在学生自己身上跑 GRPO。
桥接之后,学生已经内化了足够的结构,稀疏奖励变得有效。
没有桥接,同样的 GRPO 很弱——学生会乱撞。
有了桥接,GRPO 将 MATH 准确率从 75.4% 提升到 78.5%,增益 3.1 个百分点。
阶段 1:教师强化学习    阶段 2:桥接              阶段 3:学生强化学习

标注数据                 教师推理结果             学生探索
    |                         |                        |
    v                         v                        v
[8B 教师]                [1.7B 学生]              [1.7B 学生]
    |                         |                        |
GRPO(稀疏)             前向 KL 预热             GRPO(稀疏)
    |                         |                        |
    v                         v                        v
探索解法                 模仿教师                 精炼行为
    |                         |                        |
    +-----> 塑造策略          v                        |
                         学生推理结果上的 OPD          |
                              |                        |
                              v                        |
                         密集词元级奖励               |
                              |                        |
                              +------------------------+
                                          |
                                          v
                                可部署的学生模型
把它想象成培训厨师。
阶段 1:大厨(教师)用你的稀有食材(标注数据)做实验,尝试不同技法直到做出优秀菜品。
他们在稀疏反馈下工作——顾客说”好吃”或”不好”——但大厨有足够经验能有效探索。
阶段 2(桥接):学徒(学生)先观察大厨做菜(前向 KL),学习大致流程。
然后学徒自己做菜,大厨站在旁边,实时纠正每个刀工角度和调味选择(带密集词元级指导的 OPD)。
学徒不会浪费稀有食材去探索——他们压缩大厨的精炼技术。
阶段 3:现在学徒可以自己用稀有食材做实验了。
他们已经内化了足够的技能,稀疏的顾客反馈(“好吃”或”不好”)真的能帮他们改进,而不是让他们困惑。
桥接是承重的:没有它,学徒拿到稀有食材和稀疏反馈只能做出平庸的结果。
大厨的探索必须先密集迁移,学徒自己的探索才会有用。
关键概念
- 奖励密度:训练期间反馈的粒度。
稀疏奖励对每个完整序列给一个信号(例如”这个 50 词元的数学解答正确/错误”)。
密集奖励在每个词元处给信号(例如”根据教师,下一个词元应该有 0.7 的概率”)。
稀疏奖励在有可验证结果时收集成本低,但在生成过程中提供的指导很少。
密集奖励需要教师模型,但指导每个决策。
本文的核心主张:奖励密度要匹配模型容量——大模型能通过探索从稀疏奖励中学习;小模型需要密集奖励来压缩已有行为。
- 前向 KL vs. 反向 KL 蒸馏:前向 KL 最小化 KL(教师 || 学生)——学生试图覆盖教师分布的所有模式,即使是低概率的。
这是”模式覆盖”。
反向 KL 最小化 KL(学生 || 教师)——学生专注于教师的高概率区域,忽略低概率模式。
这是”模式寻找”。
桥接先用前向 KL 让学生广泛覆盖教师的行为,然后用 OPD(在学生推理结果上类似反向 KL)来精炼。
教师推理结果上的前向 KL 防止学生坍缩到教师能力的狭窄子集。
- 在线策略蒸馏(OPD):标准蒸馏在从教师采样的数据上训练学生。
OPD 在从学生自己采样的数据上训练学生,但用教师的词元概率作为训练目标。
为什么这很重要?
在线策略数据反映学生在部署时实际会遇到的情况。
如果只在教师样本上训练,学生可能永远学不会从自己的错误中恢复。
带密集教师奖励的 OPD 是本文的”密集桥接”——学生探索自己的分布,但在每一步都得到教师的词元级纠正。
框架转变
之前(标准 GRPO):                之后(稀疏到密集分配):

标注数据                           标注数据
    |                                  |
    v                                  v
[1.7B 学生]                        [8B 教师]
    |                                  |
GRPO(稀疏奖励)                   GRPO(稀疏奖励)
    |                                  |
    v                                  v
探索困难                           有效探索
    |                                  |
    v                                  |
表现平庸                               v
                                   教师推理结果
                                       |
                                       v
                                   [1.7B 学生]
                                       |
                                   前向 KL + OPD
                                   (密集奖励)
                                       |
                                       v
                                   压缩行为
                                       |
                                       v
                                   可选的学生 GRPO
                                       |
                                       v
                                   强劲表现
从直接在部署模型上稀疏训练到按奖励密度分阶段分配,核心转变是:把标注数据当作燃料,给能最高效燃烧它的模型,然后将精炼输出迁移到下游。
专家评审
选题眼光:这是真缺口。
业界一直在部署模型上跑 GRPO,因为看起来直接,但隐含假设——你部署的模型应该是你用稀缺数据训练的模型——没有被充分质疑。
本文识别出实践者每天面对的资源分配低效:小模型在稀疏奖励下挣扎,但我们一直喂它们稀疏奖励,因为我们手头只有这个。
问题位于强化学习和蒸馏的交叉点,这两个领域一直在平行发展,没有太多交叉融合。
方法成熟度:洞察巧妙,不是蛮力。
三阶段流程在组件上不新颖——GRPO 存在,OPD 存在,前向 KL 存在——但排序和奖励密度框架是新的。
桥接设计(前向 KL 预热然后 OPD)显示了仔细思考:前向 KL 防止模式坍缩,OPD 保持学生在线策略。
然而,本文对更简单替代方案的探索不够深入。
如果只在教师上多跑几轮 GRPO 并跳过阶段 3 呢?
如果用中等大小的教师(3B)而不是 8B 呢?
消融实验扎实但不够详尽。
实验诚意:基线公平。
本文对比了学生上的直接 GRPO、RL 前的教师蒸馏(显示 RL 是必要的)、阶段 3 的重放控制(显示桥接使后续 RL 有效)。
数字在 Qwen 和 Llama 系列上一致,令人放心。
一个警示:本文重点关注 MATH 和 AIME(数学基准)。
这能推广到验证更难的其他领域吗?
原则应该成立,但证据狭窄。
另一个担忧:8B 教师比 1.7B 学生大 4.7 倍。
增益有多少来自”更大模型探索更好”,有多少来自特定的稀疏到密集排序?
写作功力:摘要和引言密集——太多缩写(GRPO、OPD、前向 KL),前期直觉不够。
奖励密度原则埋在摘要中间,本应领衔。
第 3 节(方法)到了那里就清楚了,但路径杂乱。
第 4 节的消融实验详尽,但本文会受益于一张显示完整流程、数据流和奖励类型标注的单一图表。
相关工作部分敷衍——列出先前工作但没有足够锐利地定位贡献。
如果作者用厨师比喻(或类似的)重写引言,本文会更易懂。
判决:弱接收 — 核心洞察(奖励密度应匹配模型容量)有价值,实验证据在其范围内扎实,但写作掩盖了贡献,评估太窄(仅数学)不够充分令人信服。
方法有效,但本文需要更清晰的阐述和更广泛的实证验证。
要点总结
如果你在用有限标注数据训练小模型,别直接在小模型上用那些数据。
先训练一个更大的模型——即使你不会部署它——因为大模型能在稀疏奖励下探索。
然后用密集监督(前向 KL 预热 + OPD)蒸馏到你的部署模型。
这不只适用于数学:任何有可验证结果但标注样本有限的领域(代码生成、形式推理、受约束生成)都应受益。
两阶段桥接(前向 KL 然后 OPD)是你能偷走的具体技术。
教师推理结果上的前向 KL 防止学生坍缩到狭窄的行为模式。
学生推理结果上的 OPD 保持学生在线策略同时给密集指导。
如果你在做蒸馏,这个序列值得尝试。
更广泛的原则:按生产力分配训练资源,而非按部署位置。
稀缺标注数据应该训练能将其转化为塑造行为的模型(大型教师 + 稀疏强化学习)。
密集监督应该训练需要压缩行为的模型(小型学生 + 蒸馏)。
这颠覆了标准的”训练你部署的”启发式,表明分阶段流程通常更高效。