Paper: 2608.11197 Authors: Nikolai Bolik, Lennart Stöpler, Artur Andrzejak Categories: cs.LG, cs.CL
The Gap
Shani et al. (2026) asked a clean question: do LLM representations carve up the world the way humans do? Their answer was half-yes. Using cosine similarity over dense embeddings, they found models broadly recover human category boundaries (a robin and a penguin are both birds, and neither is furniture) but miss typicality structure (humans strongly feel a robin is a better bird than a penguin; cosine similarity mostly shrugs).
The natural objection is that cosine similarity is a blunt instrument. It collapses a whole high-dimensional state into one scalar and gives you no handle on why two things are close. The interpretability community’s answer to exactly this complaint is sparse autoencoders: decompose the residual stream into a large dictionary of mostly-inactive, individually-nameable latents. Under that view, a concept is not a direction but a set of active features, and similarity becomes something you can read off — how many named features do these two things share?
That reframing carries a hidden assumption, and this paper’s contribution is to name it and test it. If concepts are sets of features, then composition should be roughly union-like: “red car” should activate approximately the features of “red” plus the features of “car.” Call this bag-of-features semantics. Nobody in the SAE literature quite claims this out loud, but a great deal of practice — feature-list explanations, “this neuron fires for X” write-ups, set-overlap probing — quietly depends on it.
[Shani et al. 2026]  dense cosine sim
   categories: recovered ~ typicality: missing
              |
              v
  (Assumption under test) sparse latents are named units,
      so concept == SET of active latents, and
      composition == UNION of sets
              |
              v
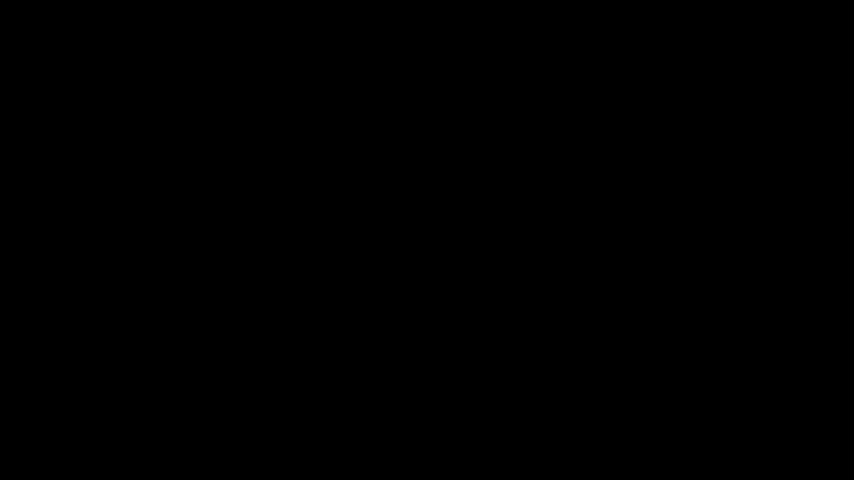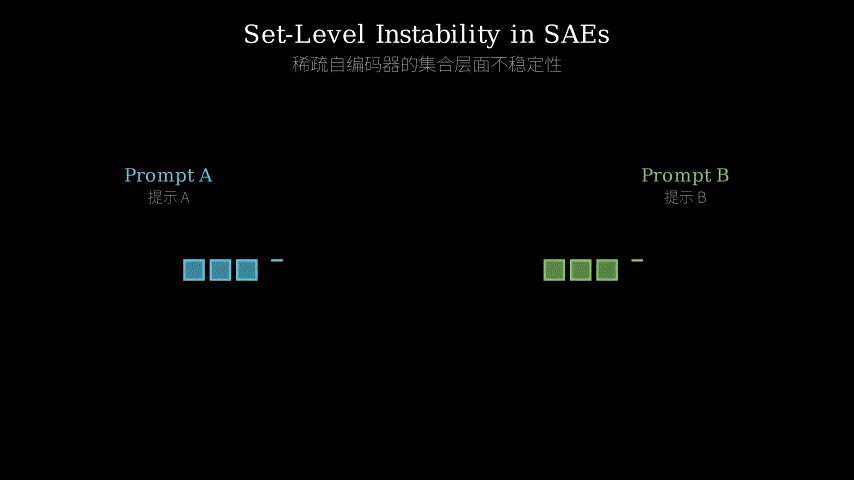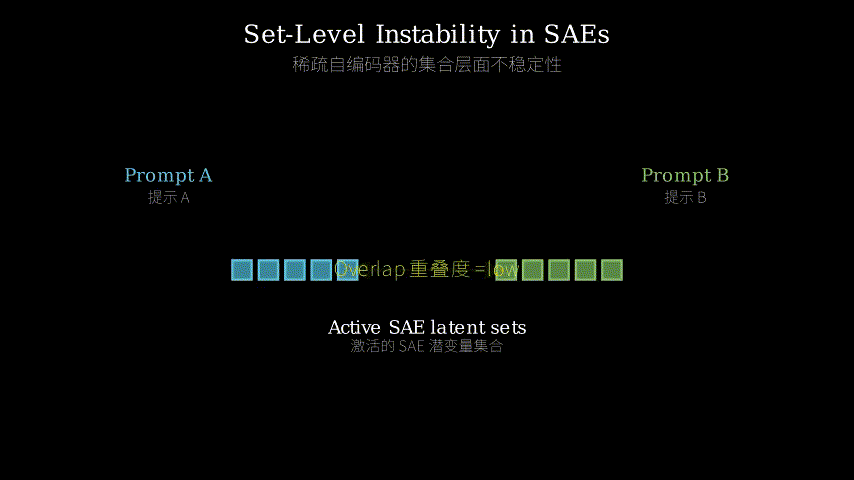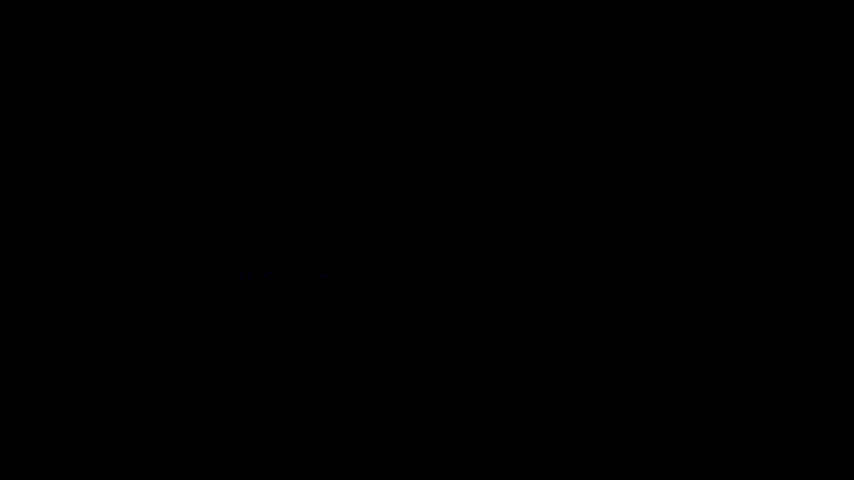
  [Method] SAE active latent sets + set-overlap similarity
              |
    +---------+-----------+--------------------+
    v                     v                    v
[E1: toy models]   [E2: human concepts]  [E3: controlled edits]
 union structure     no improvement        human-judged change
 IS recovered        over dense / resid    != set change
    |                     |                    |
    +---------+-----------+--------------------+
              v
  [Conclusion] set overlap tracks model-internal
  structure, not human structure; bag-of-features
  semantics holds only in idealised settings
The Increment
One sentence: Before, “which SAE features are active” was treated as an interpretable stand-in for “what the model means here”; after, we have evidence that the *set of active latents composes non-unionly and aligns with model-internal similarity rather than human conceptual similarity — so feature lists are not a semantics.
Core Mechanism
The machinery is deliberately simple, which is the right call for a claim like this. Take a token or text, run the LLM, grab the residual stream at some layer, push it through a trained SAE encoder. You get a sparse activation vector; throw away the magnitudes and keep the support — the identities of the latents that fired. That’s your set. Similarity between two inputs becomes a set-overlap score (Jaccard-style: shared latents over total latents). Everything downstream is a comparison of this measure against dense cosine similarity and raw residual-stream cosine similarity.
The paper’s structure is three experiments in increasing adversariality. First, a validation stage: in controlled toy models where the ground-truth generative structure is known to be compositional, do SAE latent sets actually recover union-like composition? Yes. And on natural text, do high-overlap neighborhoods look semantically coherent to a human eye? Also yes. This matters — without it, any later negative result could be dismissed as “your similarity measure was broken.”
Second, the replication-and-extension: rerun the human-concepts analysis with set overlap in place of cosine. If sparse features are the more human-aligned representational format, set overlap should recover category boundaries better and — the real prize — start picking up typicality gradients. It does neither. It tracks how the model organizes things.
Third, the diagnostic that gives the paper its title. Take an input and apply a well-controlled semantic modification — a change whose conceptual magnitude humans can rate reliably. Then measure how much the active latent set moved. If bag-of-features semantics held, small conceptual edits would swap a few features and large ones would swap many. Instead there’s substantial mismatch: the set can churn under a semantically trivial edit, or barely budge under a large one.
   input x                          input x'  (controlled edit)
      |                                 |
      v                                 v
  [ LLM layer L ]                  [ LLM layer L ]
      |  h                             |  h'
      +--> dense cos(h,h')  ......... baseline 1
      |
      v
  [ SAE encoder ]                  [ SAE encoder ]
      |  a (sparse)                    |  a'
      v                                v
   S = supp(a)                     S' = supp(a')
   (drop magnitudes)
      |                                |
      +--------------+-----------------+
                     v
        overlap(S,S') = |S n S'| / |S u S'|
                     |
      +--------------+--------------+
      v              v              v
 toy: union     human concepts:  edits: overlap
 recovered      no gain vs cos   drift != human
                                 rated change
Here’s the load-bearing analogy. Think of the SAE as a scanner that reads a dish and prints an ingredient list. The active set is the list; overlap is “what fraction of ingredients do these two dishes share.” In a salad bar — the toy model — this works perfectly: a Greek salad is the union of its ingredients, adding feta changes exactly one line on the list, and two salads sharing eight of ten ingredients really are similar dishes. That’s the validation experiment.
Now take the scanner into a real kitchen. A cake and its batter share nearly every ingredient and are not the same dish; a teaspoon of salt versus a tablespoon changes no line on the list but ruins the thing; browning the butter transforms the flavor while the receipt is identical. That’s the third experiment: the ingredient list is real, the scanner works, but the list is not the dish, because cooking is not union. And when you sort dishes by receipt overlap, you get a taxonomy that reflects the pantry’s organization — what the supplier stocks together — rather than how eaters group meals. That’s the second experiment: set overlap tracks model-internal structure.
Key Concepts
-
Active latent set: An SAE takes the model’s internal state at a point in the text and rewrites it as a mostly-zero list of thousands of numbers, where each nonzero slot is supposed to mean something nameable (“legal language,” “the letter Q,” “something is being negated”). If you ignore *how strongly each slot fired and just note which ones fired, you get a set — like a checklist of ticked boxes. Two inputs are then “similar” if their checklists overlap. The appeal is that you can read the checklist; the risk, which this paper exploits, is that ticking a box discards how hard it was ticked.
-
Typicality structure: Humans don’t experience categories as yes/no. Ask people to rate how good an example of “bird” each animal is and you get a stable gradient: robin above eagle above ostrich above penguin. Same category, graded membership. This gradient predicts real behavior — reaction times, what people list first, what children learn first. A representation that gets boundaries right but the gradient wrong knows *bird vs chair but not what birdiness feels like from the inside.
-
Bag-of-features semantics: The assumption that meaning is a set and combination is set union — that the features for “black cat” are the features for “black” plus the features for “cat,” nothing added, nothing lost. It’s the same move as bag-of-words in old-school NLP: throw away arrangement and interaction, keep presence. It’s tempting because it makes explanations trivially compositional, and it’s exactly what fails here outside idealized settings. Interaction terms and magnitudes are doing semantic work that set membership can’t see.
Framework Shift
Before (mainstream SAE practice):     After (this paper):

  h  in  R^d                            h  in  R^d
   |                                      |
   v                                      v
[ SAE ] --> \{f3, f17, f402\}           [ SAE ] --> \{f3, f17, f402\}
   |                                      |
   v                                      |  set is REAL but
"meaning = this list"                     |  not a semantics
   |                                      v
   v                              small human edit --> big set churn
compose by UNION:                 big human edit   --> tiny set churn
 \{red\} + \{car\} = \{red, car\}          |
   |                                      v
   v                              overlap ~ model-internal
explain, probe, edit              geometry, NOT human concepts
via feature lists
                                  union holds only in toy /
                                  ground-truth-compositional regimes
From geometry to combinatorics and back again: the core shift is that making similarity readable does not make it human-aligned, and set membership is the wrong abstraction level because it throws away the magnitudes and interactions where composition actually lives.
Expert Assessment
Problem choice: Real gap, well positioned. The field has spent two years scaling SAEs and building tooling on top of feature lists, with the compositional assumption mostly implicit. Papers that name a load-bearing assumption and stress-test it are worth more than another dictionary-scaling result. Riding on a very recent paper (Shani et al. 2026) is a double-edged move: it gives a ready-made benchmark and a clear comparison, but it also means the framing has a short shelf life and inherits whatever flaws the original human-concepts setup has.
Method maturity: Clever framing, deliberately unclever machinery — appropriate for a negative result, since a fancy method would just invite “your method was broken.” The toy-model and neighborhood-coherence validation before the negative claims is exactly the right discipline; skipping it is the most common way this genre of paper fails. But the paper is testing a strawman-adjacent version of the assumption, and the obvious next step is conspicuous: run the same analyses with *magnitude-weighted SAE activations. If weighted cosine over SAE activations recovers what binary set overlap loses, then the finding is “don’t binarize” rather than “features don’t compose” — a much narrower claim. From the abstract I can’t tell whether they ran this; if they didn’t, it’s the first thing a reviewer should demand. Likewise, the “controlled semantic modifications” experiment is the strongest part and deserves to be the paper’s center of gravity rather than a probe at the end.
Experimental integrity: The baseline choice is fair and non-trivial — comparing against both dense embeddings *and raw residual-stream states forecloses the easy objection that the residual stream itself was the problem. The structural risk in all SAE negative results is generalization across the SAE design space: layer choice, dictionary width, sparsity coefficient, and architecture (TopK vs JumpReLU vs gated) all change the active set substantially, and known pathologies like feature absorption and feature splitting will corrupt set overlap in ways that have nothing to do with composition. A finding that holds for one SAE at one layer of one model is a finding about that SAE. Also worth flagging: human typicality datasets are small and noisy, so “no improvement over dense” needs to be a real gap rather than a difference inside the noise floor. Note that I’m assessing from the abstract, not the full experimental section — these are the questions to check, not confirmed defects.
Writing quality: The abstract is unusually honest and well-sequenced — validate the measure, then break it — and it resists overclaiming (“outside idealised settings” is the right hedge, and rarer than it should be). The likely corner-cutting is in the toy-model section, which is easy to write as “we constructed a case where it works” without characterizing *where the boundary is between the toy regime and the real one. That’s the rewrite that would elevate the paper: don’t just show union-composition holds in toy models and fails in text — find the knob (interaction strength? feature co-occurrence density? sparsity level?) that carries you from one regime to the other. That turns a negative result into a predictive one.
Verdict: weak accept — a well-scoped, properly-validated negative result against an assumption the field genuinely relies on, held back by unclear robustness across SAE configurations and an unaddressed magnitude-weighted alternative that could substantially narrow the claim.
Takeaways
Concrete things to steal:
- Validate your interpretability measure before you use it to draw conclusions. The two-step of “recover known structure in a toy model with ground truth, then check neighborhoods are semantically coherent in the wild” is a reusable template. Any paper claiming X *doesn’t have property P needs this, or the result is unfalsifiable.
- The controlled-edit protocol transfers directly. Apply a semantic modification whose magnitude humans can rate, then measure representation drift, then correlate. This is a cheap, general test for “does my representation’s notion of distance match anyone’s,” and it works for embeddings, probes, attention patterns, or activation steering — not just SAEs.
- Binarizing is a modeling choice with teeth. Whenever you convert a continuous representation into “which units are on,” you have assumed that magnitude carries no semantics. Sometimes that’s fine. Here it isn’t, and the paper is a good reminder to ablate the binarization rather than inherit it from convention.
- Practical caution if you build on SAEs: don’t ship pipelines that assume feature-set union is composition — feature-list diffs, set-overlap retrieval, “concept = these N latents” dashboards. They will look sensible on curated examples and drift incoherently on real edits. Prefer weighted comparisons and validate against human-rated change on your own data.
- Framing to keep: interpretability and alignment-with-humans are independent axes. Making a similarity measure *readable tells you nothing about whether it measures what humans mean. Easy to conflate; expensive to conflate.
论文: 2608.11197 作者: Nikolai Bolik, Lennart Stöpler, Artur Andrzejak 分类: cs.LG, cs.CL
缺口
Shani 等人(2026)问了一个干净的问题:LLM 的表征切分世界的方式,和人类一样吗?
他们的答案是”一半是”。用稠密嵌入上的余弦相似度,他们发现模型大体上能复现人类的类别边界(知更鸟和企鹅都是鸟,都不是家具),但抓不到典型性结构(人类强烈地觉得知更鸟比企鹅更”像鸟”,而余弦相似度基本无感)。
对此最自然的质疑是:余弦相似度太钝了。
它把整个高维状态压成一个标量,而且完全不告诉你两个东西”为什么”接近。可解释性社区对这个抱怨的标准回答就是稀疏自编码器:把残差流分解成一个巨大的字典,里面大部分潜变量不激活,激活的那些据说都能单独命名。
在这个视角下,一个概念不是一个方向,而是一组激活特征;相似性于是变成可以直接读出来的东西——这两者共享了多少个有名字的特征?
这次重新表述里藏着一个假设,而本文的贡献就是把它点名并加以检验。
如果概念就是特征的集合,那么组合应该近似于并集:「红色的车」应该大致等于「红色」的特征加上「车」的特征。姑且叫它”特征袋语义”(bag-of-features semantics)。
SAE 文献里没人明说这一点,但大量实践——特征清单式解释、“这个神经元对 X 放电”的报告、集合重叠度探测——都在悄悄依赖它。
[Shani et al. 2026]  稠密余弦相似度
   类别边界: 能复现 ~ 典型性: 抓不到
              |
              v
  (待检验的假设) 稀疏潜变量是有名字的单元,
      所以 概念 == 激活潜变量的集合,
          组合 == 集合的并
              |
              v
  [方法] SAE 激活集合 + 集合重叠度作为相似性
              |
    +---------+-----------+--------------------+
    v                     v                    v
[实验1: 玩具模型]  [实验2: 人类概念]   [实验3: 受控语义改动]
 并集结构确实           相对稠密/残差       人评概念变化量
 能被复现               没有任何改进        != 集合变化量
    |                     |                    |
    +---------+-----------+--------------------+
              v
  [结论] 集合重叠度追踪的是模型内部结构,
  不是人类的概念结构; 特征袋语义只在
  理想化设定下成立
增量
一句话:在此之前,“哪些 SAE 特征被激活”被当作”模型在这里表达什么意思”的可解释替身;在此之后,我们有证据表明激活集合的组合方式并非并集,而且它对齐的是模型内部的相似性结构而不是人类的概念结构——所以特征清单不是一种语义。
核心机制
机器本身刻意做得很简单,对这类主张来说这是正确的选择。
拿一个 token 或一段文本,跑 LLM,在某一层取残差流,喂进训练好的 SAE 编码器。你得到一个稀疏激活向量;扔掉数值大小,只保留支撑集——也就是”哪些潜变量放电了”的身份。这就是你的集合。
两个输入之间的相似性于是变成集合重叠度(Jaccard 式:共享潜变量数除以总潜变量数)。后面所有工作都是把这个度量和稠密嵌入余弦、以及原始残差流余弦做对比。
论文的结构是三个逐步升级敌意的实验。
第一步是验证:在生成结构已知且确实是组合式的受控玩具模型里,SAE 激活集合真的能复现并集式组合吗?能。在自然文本上,高重叠度的邻域在人眼看来语义连贯吗?也连贯。
这一步很关键——没有它,后面任何负面结果都可以被一句”你的相似性度量本来就是坏的”打掉。
第二步是复现加扩展:把人类概念分析里的余弦换成集合重叠度重跑一遍。如果稀疏特征真是更贴近人类的表征格式,集合重叠度应该更好地复现类别边界,并且——这才是真正的奖品——开始捕捉到典型性梯度。
结果两件事都没发生。它追踪的是模型自己怎么组织事物。
第三步是给了论文标题的那个诊断实验。取一个输入,施加一个受控的语义改动——一个人类能可靠打分其”概念变化幅度”的改动。然后测量激活集合移动了多少。
如果特征袋语义成立,小的概念改动应该换掉少数几个特征,大的改动换掉很多。实际情况是严重错位:语义上微不足道的改动可能让集合大幅翻搅,而很大的改动却几乎不动。
   输入 x                            输入 x'  (受控改动)
      |                                 |
      v                                 v
  [ LLM 第 L 层 ]                  [ LLM 第 L 层 ]
      |  h                             |  h'
      +--> 稠密余弦 cos(h,h')  ....... 基线 1
      |
      v
  [ SAE 编码器 ]                   [ SAE 编码器 ]
      |  a (稀疏)                      |  a'
      v                                v
   S = supp(a)                     S' = supp(a')
   (丢弃激活强度)
      |                                |
      +--------------+-----------------+
                     v
        overlap(S,S') = |S n S'| / |S u S'|
                     |
      +--------------+--------------+
      v              v              v
 玩具: 并集      人类概念: 相对    改动: 集合漂移
 能复现          余弦无增益        != 人评变化量
下面是承重的核喻。
把 SAE 想成一台扫描仪:它读一道菜,打印出配料清单。激活集合就是这张清单;重叠度就是”两道菜共享了多少比例的配料”。
在沙拉吧里——也就是玩具模型——这套完全成立:希腊沙拉就是它配料的并集,加一块羊乳酪恰好在清单上多一行,两份沙拉共享十种配料中的八种,那它们确实是相似的菜。这就是验证实验。
现在把这台扫描仪搬进真正的厨房。
蛋糕和蛋糕糊几乎共享全部配料,却完全不是同一道菜;一茶匙盐和一汤匙盐在清单上一行都不改,但成品毁了;把黄油煎至焦化会彻底改变风味,而小票一字不变。
这就是第三个实验:配料清单是真的,扫描仪工作正常,但清单不是菜,因为烹饪不是并集运算。
而当你按小票重叠度给菜品分类时,你得到的分类反映的是食材仓库的组织方式——供应商习惯把什么放在一起——而不是吃饭的人怎么给餐食归类。这就是第二个实验:集合重叠度追踪模型内部结构。
关键概念
-
激活潜变量集合:SAE 把模型在文本某处的内部状态改写成一个绝大部分为零的、有几千个数的列表,其中每个非零位置据说都能被命名(“法律语言”、“字母 Q”、“这里在否定某件事”)。如果你不管每个位置放电得多强,只记下哪些放电了,你就得到一个集合——好比一张打了勾的清单。两个输入”相似”就等于清单重叠得多。它的吸引力在于清单可读;而本文利用的风险在于:打勾这个动作扔掉了”勾打得多重”这个信息。
-
典型性结构:人类并不把类别体验成是/否。让人们给每种动物打分”它是多好的’鸟’的例子”,你会得到一个稳定的梯度:知更鸟 > 老鹰 > 鸵鸟 > 企鹅。同一个类别,成员资格是分级的。这个梯度能预测真实行为——反应时间、人们最先列举出什么、儿童最先学会什么。一个边界对了但梯度错了的表征,知道”鸟和椅子不一样”,但不知道”鸟性”从内部感受起来是什么样。
-
特征袋语义:认为意义是一个集合、组合就是集合并——「黑猫」的特征等于「黑」的特征加「猫」的特征,不多不少。这和老派 NLP 里的词袋是同一个动作:扔掉排列和交互,只留存在与否。它诱人是因为它让解释天然可组合,而这恰恰是本文在理想化设定之外发现失效的东西。交互项和激活强度在承担真实的语义工作,而集合成员关系看不见它们。
框架转变
之前(SAE 主流实践):                 之后(本文):

  h  in  R^d                            h  in  R^d
   |                                      |
   v                                      v
[ SAE ] --> \{f3, f17, f402\}           [ SAE ] --> \{f3, f17, f402\}
   |                                      |
   v                                      |  集合是真的, 但
"意义 = 这张清单"                         |  它不是一种语义
   |                                      v
   v                              人评小改动 --> 集合大翻搅
按并集组合:                       人评大改动 --> 集合几乎不动
 \{红\} + \{车\} = \{红, 车\}              |
   |                                      v
   v                              重叠度 ~ 模型内部几何,
用特征清单去                      而非人类概念结构
解释 / 探测 / 编辑
                                  并集只在玩具 / 真值本身
                                  就是组合式的设定下成立
一句话:从几何到组合再回到几何,核心转变是让相似性变得可读并不等于让它对齐人类,而集合成员关系是错误的抽象层级——它扔掉了激活强度和交互,而组合恰恰活在那里。
专家评审
选题眼光:真缺口,位置也找得好。
这个领域花了两年时间扩大 SAE 规模、在特征清单之上堆工具,而组合性假设一直是隐含的。点名一个承重假设并对它做压力测试的论文,比再来一篇扩大字典规模的结果更有价值。
搭在一篇很新的论文(Shani et al. 2026)上是把双刃剑:好处是现成的基准和清晰的对照,坏处是框架保质期短,而且继承了原始人类概念实验设定的一切缺陷。
方法成熟度:框架聪明,机器刻意不聪明——对负面结果而言这是恰当的,因为花哨的方法只会招来”你的方法本身是坏的”。
在给出负面结论之前先做玩具模型验证和邻域连贯性检查,是完全正确的纪律;跳过这一步是这类论文最常见的死法。
但论文检验的是这个假设里偏”稻草人”的版本,而显而易见的下一步太显眼了:用带激活强度加权的 SAE 激活重跑同样的分析。
如果 SAE 激活上的加权余弦能挽回二值化集合重叠度丢掉的东西,那结论就从”特征不按并集组合”降级成”别做二值化”——一个窄得多的主张。从摘要看不出他们跑没跑;如果没跑,这是审稿人应该第一个索要的东西。
同理,“受控语义改动”那个实验是全文最强的部分,它应该成为论文的重心,而不是结尾的一个探针。
实验诚意:基线选得公平且不含水——同时对比稠密嵌入和原始残差流状态,堵住了”问题出在残差流本身”这条最容易的退路。
所有 SAE 负面结果的结构性风险都在于跨 SAE 设计空间的泛化性:层的选择、字典宽度、稀疏系数、架构(TopK / JumpReLU / gated)都会显著改变激活集合,而已知的病理现象——特征吸收(feature absorption)、特征分裂(feature splitting)——会以与组合性毫无关系的方式污染集合重叠度。
在一个模型的一层上用一个 SAE 得到的结论,是关于那个 SAE 的结论。
另外值得警惕:人类典型性评分数据集小且噪声大,所以”相对稠密没有改进”必须是真实差距,而不是落在噪声底噪里的差异。
需要说明的是,我是基于摘要而非完整实验章节做的评估——以上是应当核查的问题,不是已确认的缺陷。
写作功力:摘要罕见地诚实,顺序也编排得好——先验证度量,再打破它——而且它拒绝过度宣称(“outside idealised settings” 是恰当的限定词,而且比应有的频率更罕见)。
大概率偷懒的地方是玩具模型那节:很容易写成”我们构造了一个它成立的例子”,却不刻画玩具区域和真实区域之间的边界在哪里。
那才是能让论文升一档的重写:不要只展示并集组合在玩具模型里成立、在真实文本里失效——找到那个旋钮(交互强度?特征共现密度?稀疏度水平?),它能把你从一个区域带到另一个区域。
那样负面结果就变成了有预测力的结果。
判决:弱接收 —— 一个范围清晰、验证做得规范的负面结果,打的是领域真正依赖的假设;但被两点拖住:跨 SAE 配置的稳健性不明,以及一个未被处理的”带强度加权”替代方案可能会大幅收窄结论。
要点总结
可以具体”偷”走的东西:
- 在用一个可解释性度量下结论之前,先验证这个度量。 “先在有真值的玩具模型里复现已知结构,再检查真实数据上的邻域语义是否连贯”这个两步法是可复用的模板。任何声称 X 不具有性质 P 的论文都需要它,否则结论是不可反驳的。
- 受控改动协议可以直接迁移。 施加一个人类能给变化幅度打分的语义改动,测量表征漂移,然后做相关。这是一个便宜且通用的检验,用来回答”我的表征所谓的距离和任何人的直觉对得上吗”——适用于嵌入、探针、注意力模式、激活引导,不只是 SAE。
- 二值化是一个有后果的建模选择。 每当你把连续表征转成”哪些单元开着”,你就假设了激活强度不携带语义。有时这没问题。这里就有问题,而本文是一个很好的提醒:把二值化当作可消融项来测,而不是照惯例继承下来。
- 如果你在 SAE 上做工程,务实的警告:不要交付那些假设”特征集合的并就是组合”的流水线——特征清单 diff、集合重叠度检索、“概念 = 这 N 个潜变量”的仪表盘。它们在精挑的例子上看起来很合理,在真实改动下会不连贯地漂移。优先用带权比较,并在你自己的数据上对着人评变化量做验证。
- 值得保留的思维框架:可解释性和人类对齐是两条独立的轴。把一个相似性度量做得可读,完全不告诉你它是否测的是人类所指的东西。这两件事很容易混为一谈,而混淆的代价很高。