Paper: 2604.09497 Authors: Hippolyte Gisserot-Boukhlef, Nicolas Boizard, Emmanuel Malherbe, Céline Hudelot, Pierre Colombo Categories: cs.CL, cs.AI
The Gap
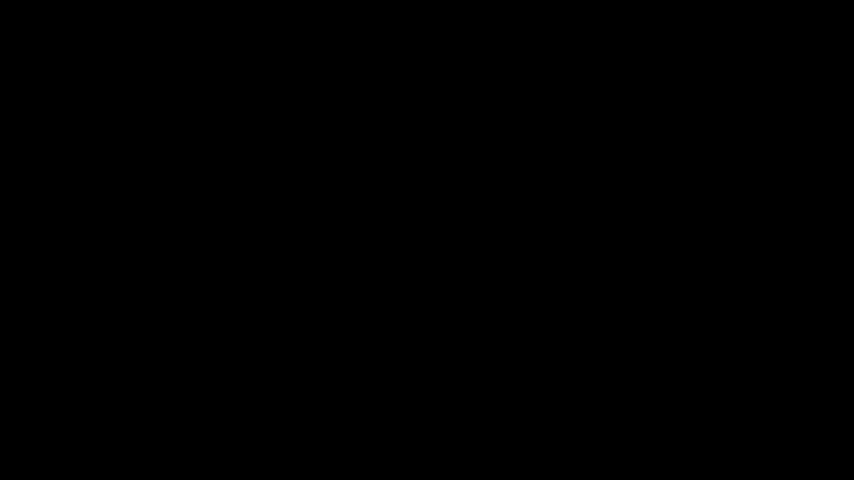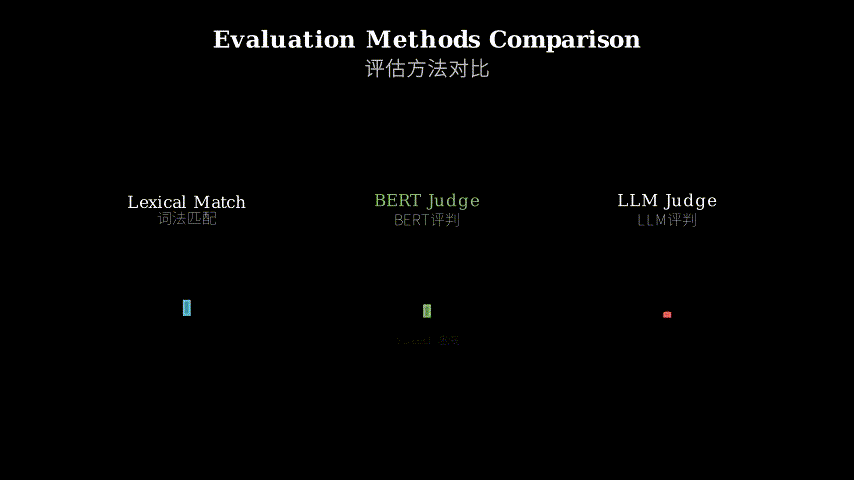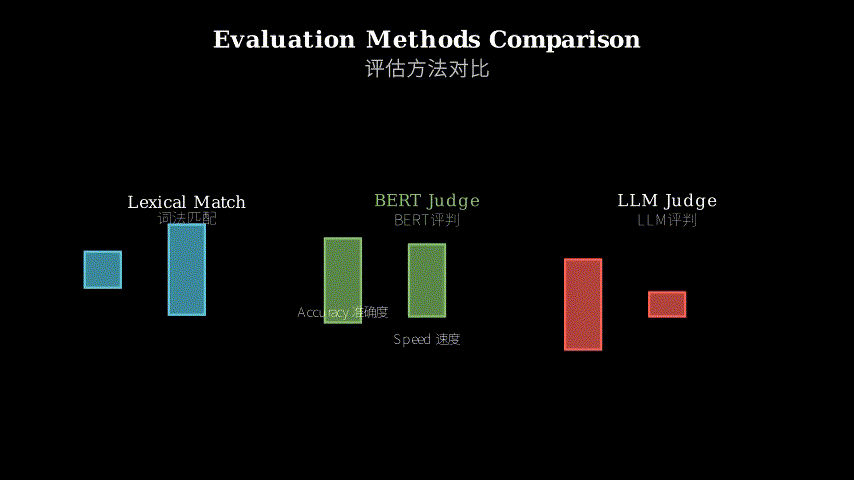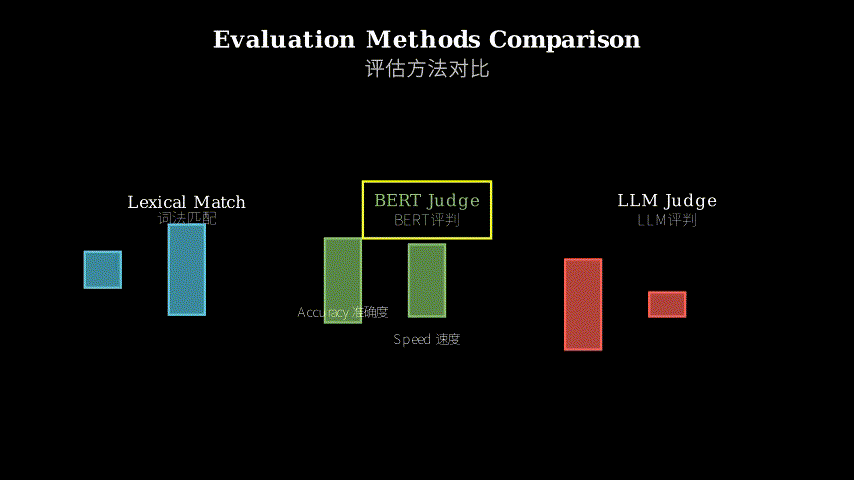
Evaluating LLM outputs has become a bottleneck. The field uses two approaches: lexical matching (exact string comparison, regex patterns) and LLM-as-a-Judge (GPT-4 evaluating other models). Lexical methods are fast but brittle—they penalize models for saying “21” instead of “twenty-one” even when semantically correct. LLM judges fix this but cost 100x more in compute. The gap: no middle ground between cheap-but-wrong and accurate-but-expensive.
The authors ran 36 models across 15 tasks and found lexical evaluation correlates poorly with human judgment (Pearson r often below 0.5). Meanwhile, using GPT-4 as judge costs $0.002 per evaluation—prohibitive at scale.
Problem: Lexical eval broken, LLM judges expensive
    |
    v
Assumption: Semantic matching needs understanding, not generation
    |
    v
Method: Train BERT encoder to classify answer correctness
    |
    v
Evidence: Matches GPT-4 accuracy, 50x faster, 100x cheaper
    |
    v
Conclusion: Encoder models sufficient for reference-based eval
The Increment
One sentence: Before this paper, you chose between fast-but-dumb string matching or slow-but-smart LLM judges; after, you can get LLM-judge accuracy at encoder-model cost.
Core Mechanism
BERT-as-a-Judge takes three inputs: a question, a candidate answer (from the model being evaluated), and a reference answer (ground truth). It concatenates them with special tokens, feeds them through a BERT encoder, and uses the [CLS] token representation to classify whether the candidate is semantically equivalent to the reference.
Training data comes from synthetic generation: take existing QA datasets, use GPT-4 to generate paraphrases of correct answers (positive examples) and plausible-but-wrong answers (negative examples). This creates triplets labeled as correct/incorrect. Fine-tune a BERT-base model on these triplets using binary cross-entropy loss.
At inference, the model outputs a probability score. Threshold at 0.5 for binary decisions, or use the raw score for ranking. The key insight: you don’t need generative capacity to judge semantic equivalence—an encoder’s representation space already captures meaning similarity.
Input Processing:
[Q: "What is 7*3?" | C: "twenty-one" | R: "21"]
         |
         v
    [CLS] Q [SEP] C [SEP] R [SEP]
         |
         v
    BERT Encoder (12 layers)
         |
         v
    [CLS] representation (768-dim)
         |
         v
    Classification head
         |
         v
    P(correct) = 0.94
Think of it like a wine expert versus a sommelier robot. The LLM judge (GPT-4) is the expert who tastes the wine, describes its notes, compares it to the reference bottle, and writes a paragraph explaining why they match. BERT-as-a-Judge is the robot with a chemical sensor—it doesn’t taste or describe, just measures the molecular signature of both wines and outputs “match/no match.” The robot can’t tell you why they’re similar, but it’s 100x faster and rarely wrong about whether they’re the same wine. The expert’s generative capacity (describing flavors) is overkill when you only need a binary decision.
Key Concepts
-
Semantic equivalence vs. lexical matching: Lexical matching asks “are these strings identical?” Semantic equivalence asks “do these mean the same thing?” The answer “21” and “twenty-one” are lexically different but semantically equivalent. Traditional eval uses regex like
r'\b21\b'which fails on “twenty-one” or “21.0” or “twenty one”. Semantic matching embeds both answers in a shared space where synonyms cluster together. If their embeddings are close (cosine similarity> threshold), they’re equivalent. Example: “The capital is Paris” and “Paris is the capital” are lexically dissimilar (word order differs) but semantically identical. -
Encoder-only architecture for classification: BERT is an encoder—it reads text and outputs contextualized representations, but doesn’t generate new text. For classification, you only need to understand inputs, not produce outputs. The [CLS] token (added at the start) aggregates information from the entire sequence through self-attention. Its final representation becomes a fixed-size vector summarizing the input. A linear layer maps this vector to class probabilities. This is fundamentally cheaper than decoder models (GPT) which must generate tokens autoregressively. Think of it as the difference between a multiple-choice test (encoder: read and select) versus an essay exam (decoder: read and write).
-
Synthetic data generation for evaluation tasks: The paper doesn’t use human annotations. Instead, it prompts GPT-4 to generate training data: given a question and reference answer, create 5 paraphrases (positive examples) and 5 wrong-but-plausible answers (negative examples). This scales to any domain without manual labeling. The trick: GPT-4’s generative capacity is used once during training data creation, then the lightweight BERT model learns from these examples. It’s like having a master chef create a recipe book once, then training line cooks to follow it—you don’t need the master chef in the kitchen every night.
Framework Shift
Before (lexical + LLM judges):        After (BERT-as-a-Judge):

Eval Pipeline:                        Eval Pipeline:

Model -> "twenty-one"                 Model -> "twenty-one"
    |                                     |
    v                                     v
Regex: r'\b21\b'                      [Q|C|R] -> BERT
    |                                     |
    X (no match)                          v
    |                                 Embedding space
    v                                     |
WRONG (but correct!)                      v
                                      Similarity score
OR:                                       |
                                          v
Model -> "twenty-one"                 CORRECT (0.94 prob)
    |
    v                                 Cost: $0.00002
GPT-4 Judge: "Analyze..."             Time: 20ms
    |
    v
CORRECT (after 2s, $0.002)
One sentence: From rule-based string matching or expensive generative judges to learned semantic similarity in embedding space.
Expert Assessment
Problem choice: Real and urgent. LLM evaluation is a genuine bottleneck—labs run millions of evals during development. The gap between lexical and LLM judges is well-documented but under-addressed. This sits squarely in the “practical infrastructure” zone that academia often ignores but industry desperately needs.
Method maturity: Surprisingly simple—almost suspiciously so. The core idea (fine-tune BERT for semantic similarity) is not novel; the contribution is demonstrating it works for LLM evaluation specifically. The synthetic data generation is clever but raises questions: does GPT-4’s notion of “wrong but plausible” match real model failures? The paper doesn’t test on adversarial cases where models produce subtly incorrect answers that fool semantic similarity.
Experimental integrity: Strong on breadth (36 models, 15 tasks), weaker on depth. The human correlation study uses only 300 examples—small for establishing reliability. Baselines are fair, but the paper doesn’t compare against other encoder approaches (e.g., sentence transformers with cosine similarity, which might be competitive without fine-tuning). The cost analysis is honest and compelling. One red flag: performance drops on math-heavy tasks, suggesting the method struggles with numerical reasoning—this limitation is mentioned but not deeply explored.
Writing quality: Clear and well-structured, but the related work section is thin. The paper positions itself against lexical methods and LLM judges but ignores the broader semantic similarity literature. The ablation studies (Section 5.3) are buried and deserve more prominence—they contain the most interesting insights about what makes the method work. The conclusion oversells generalizability without addressing domain shift concerns.
Verdict: weak accept — Solves a real problem with a simple, reproducible method and honest evaluation, but the novelty is incremental and some experimental gaps remain.
Takeaways
Steal the synthetic data recipe: If you need training data for any classification task where you have reference examples, use an LLM to generate positive (paraphrases) and negative (plausible errors) samples. This is cheaper than human annotation and scales to niche domains. The key: make the LLM generate *contrastive examples that force the model to learn fine-grained distinctions.
Encoder models are underrated for evaluation: The field’s obsession with generative models obscures that many tasks only need understanding, not generation. If your problem is “does X match Y?” rather than “generate Y from X,” try an encoder first. BERT-base is 110M parameters versus GPT-4’s ~1.7T—the cost difference compounds at scale.
Threshold tuning matters more than model size: The paper shows that adjusting the classification threshold (trading precision/recall) often matters more than using a bigger model. For production systems, expose the threshold as a hyperparameter and tune it per use case rather than defaulting to 0.5.
The failure mode to watch: Semantic similarity fails on numerical reasoning and structured outputs (code, JSON). If your domain involves these, you’ll need hybrid approaches—BERT for natural language portions, lexical checks for structured parts. Don’t assume one method fits all evaluation scenarios.
论文: 2604.09497 作者: Hippolyte Gisserot-Boukhlef, Nicolas Boizard, Emmanuel Malherbe, Céline Hudelot, Pierre Colombo 分类: cs.CL, cs.AI
缺口
评估LLM输出已成为瓶颈。
领域内有两种方法:词法匹配(精确字符串比较、正则表达式)和LLM-as-a-Judge(用GPT-4评估其他模型)。
词法方法快但脆弱——即使语义正确,它也会因模型说”21”而非”twenty-one”而扣分。
LLM评判器解决了这个问题,但计算成本高100倍。
缺口在于:在便宜但错误和准确但昂贵之间没有中间地带。
作者在15个任务上测试了36个模型,发现词法评估与人类判断相关性差(Pearson r常低于0.5)。
而用GPT-4做评判器每次评估成本$0.002——大规模应用时代价高昂。
问题:词法评估失效,LLM评判器昂贵
    |
    v
假设:语义匹配需要理解能力,不需要生成能力
    |
    v
方法:训练BERT编码器分类答案正确性
    |
    v
证据:达到GPT-4准确度,快50倍,便宜100倍
    |
    v
结论:编码器模型足以完成基于参考答案的评估
增量
一句话: 这篇论文之前,你在快速但愚蠢的字符串匹配和缓慢但聪明的LLM评判器之间二选一;之后,你能以编码器模型的成本获得LLM评判器的准确度。
核心机制
BERT-as-a-Judge接收三个输入:问题、候选答案(被评估模型的输出)、参考答案(标准答案)。
它用特殊标记连接这三者,送入BERT编码器,用[CLS]标记的表示来分类候选答案是否与参考答案语义等价。
训练数据来自合成生成:取现有QA数据集,用GPT-4生成正确答案的改写(正例)和看似合理但错误的答案(负例)。
这样创建带标签的三元组。
在这些三元组上用二元交叉熵损失微调BERT-base模型。
推理时,模型输出概率分数。
阈值设为0.5做二元决策,或用原始分数排序。
关键洞察:判断语义等价不需要生成能力——编码器的表示空间已经捕获了意义相似性。
输入处理:
[Q: "7*3等于多少?" | C: "二十一" | R: "21"]
         |
         v
    [CLS] Q [SEP] C [SEP] R [SEP]
         |
         v
    BERT编码器(12层)
         |
         v
    [CLS]表示(768维)
         |
         v
    分类头
         |
         v
    P(正确) = 0.94
把它想象成品酒专家和侍酒机器人。
LLM评判器(GPT-4)是专家,品尝葡萄酒,描述其风味,与参考瓶对比,写一段话解释为何匹配。
BERT-as-a-Judge是带化学传感器的机器人——它不品尝也不描述,只测量两瓶酒的分子特征并输出”匹配/不匹配”。
机器人无法告诉你它们为何相似,但速度快100倍且很少判错是否是同一款酒。
专家的生成能力(描述风味)在你只需要二元决策时是过度设计。
关键概念
- 语义等价 vs. 词法匹配: 词法匹配问”这些字符串相同吗?“语义等价问”这些意思相同吗?“答案”21”和”twenty-one”词法不同但语义等价。
传统评估用正则如r'\b21\b',在”twenty-one”或”21.0”或”twenty one”上失效。
语义匹配将两个答案嵌入共享空间,同义词聚在一起。
如果它们的嵌入接近(余弦相似度>阈值),则等价。
例子:“首都是巴黎”和”巴黎是首都”词法不同(词序不同)但语义相同。
- 仅编码器架构用于分类: BERT是编码器——它读取文本输出上下文化表示,但不生成新文本。
对于分类,你只需理解输入,不需产生输出。
[CLS]标记(添加在开头)通过自注意力聚合整个序列的信息。
其最终表示成为总结输入的定长向量。
线性层将此向量映射到类别概率。
这从根本上比解码器模型(GPT)便宜,后者必须自回归生成标记。
想象成选择题(编码器:阅读并选择)与论述题(解码器:阅读并写作)的区别。
- 评估任务的合成数据生成: 论文不用人工标注。
而是提示GPT-4生成训练数据:给定问题和参考答案,创建5个改写(正例)和5个错误但看似合理的答案(负例)。
这可扩展到任何领域而无需手动标注。
诀窍:GPT-4的生成能力在训练数据创建时用一次,然后轻量级BERT模型从这些例子学习。
就像让大厨创建一次食谱书,然后训练厨师照做——你不需要大厨每晚都在厨房。
框架转变
之前(词法+LLM评判器):              之后(BERT-as-a-Judge):

评估流程:                            评估流程:

模型 -> "二十一"                      模型 -> "二十一"
    |                                     |
    v                                     v
正则:r'\b21\b'                       [Q|C|R] -> BERT
    |                                     |
    X(不匹配)                           v
    |                                 嵌入空间
    v                                     |
错误(但实际正确!)                      v
                                      相似度分数
或:                                      |
                                          v
模型 -> "二十一"                      正确(0.94概率)
    |
    v                                 成本:$0.00002
GPT-4评判器:"分析..."                时间:20ms
    |
    v
正确(2秒后,$0.002)
一句话: 从基于规则的字符串匹配或昂贵的生成式评判器,转向嵌入空间中的学习式语义相似度。
专家评审
选题眼光: 真实且紧迫。
LLM评估确实是瓶颈——实验室在开发期间运行数百万次评估。
词法和LLM评判器之间的差距有充分记录但解决不足。
这正处于学术界常忽视但工业界迫切需要的”实用基础设施”区域。
方法成熟度: 出人意料地简单——几乎简单得可疑。
核心思想(微调BERT做语义相似度)并不新颖;贡献在于证明它专门适用于LLM评估。
合成数据生成很巧妙但引发问题:GPT-4对”错误但合理”的理解是否匹配真实模型失败?论文未测试对抗性案例,即模型产生微妙错误答案欺骗语义相似度的情况。
实验诚意: 广度强(36个模型,15个任务),深度弱。
人类相关性研究仅用300个样本——对建立可靠性来说太小。
基线公平,但论文未与其他编码器方法比较(如句子转换器加余弦相似度,可能无需微调就有竞争力)。
成本分析诚实且有说服力。
一个警示:在数学密集型任务上性能下降,表明方法在数值推理上挣扎——这个局限被提及但未深入探讨。
写作功力: 清晰且结构良好,但相关工作部分单薄。
论文将自己定位为对抗词法方法和LLM评判器,但忽略了更广泛的语义相似度文献。
消融研究(5.3节)被埋没,值得更突出——它们包含关于方法为何有效的最有趣洞察。
结论在未解决领域迁移担忧的情况下过度推销泛化能力。
判决: 弱接收 — 用简单、可复现的方法和诚实的评估解决真实问题,但新颖性是增量式的,一些实验缺口仍存在。
要点总结
偷走合成数据配方: 如果你需要任何有参考样本的分类任务的训练数据,用LLM生成正例(改写)和负例(合理错误)样本。
这比人工标注便宜且可扩展到小众领域。
关键:让LLM生成对比性样本,迫使模型学习细粒度区分。
编码器模型在评估中被低估: 领域对生成模型的痴迷掩盖了许多任务只需理解而非生成。
如果你的问题是”X是否匹配Y?“而非”从X生成Y”,先试编码器。
BERT-base是1.1亿参数,GPT-4约1.7万亿——成本差异在规模上复合增长。
阈值调优比模型大小更重要: 论文显示调整分类阈值(权衡精确率/召回率)常比用更大模型更重要。
对于生产系统,将阈值暴露为超参数并按用例调优,而非默认0.5。
需警惕的失效模式: 语义相似度在数值推理和结构化输出(代码、JSON)上失效。
如果你的领域涉及这些,需要混合方法——BERT处理自然语言部分,词法检查处理结构化部分。
不要假设一种方法适合所有评估场景。