Paper: 2608.06329 Authors: Noam Koren, Roy Bar-Haim, Abigail Goldsteen Categories: cs.AI, cs.CL
The Gap
Here’s the awkward situation the field has walked into. Task-oriented conversational agents — the customer-service, booking, retail-refund kind — are now evaluated on benchmarks like MultiWOZ, ABCD, and the newer policy-driven suites in the τ-bench lineage. Those benchmarks pair a domain policy document (the rules the agent must obey), a set of tasks (a user persona plus a goal), and an expected outcome used for grading. Because hand-writing hundreds of such tasks is expensive, a large fraction of new benchmarks are now generated by LLMs, sometimes with light human filtering, sometimes with none.
The measurement instrument, in other words, became a model output. And nobody calibrated it.
Prior work does attack neighboring problems. There’s a whole literature on LLM-as-a-judge reliability, i.e. is the grader trustworthy. There’s data-quality work on synthetic instruction data (dedup, difficulty scoring, contamination checks). There are audits that manually re-annotate a specific benchmark and report an error rate — valuable, but one-off, expensive, and non-transferable. And there’s the growing “agentic benchmarks are broken” genre that catalogs failure modes anecdotally. What’s missing is a reusable, reference-free way to score a conversational-agent benchmark before you spend GPU hours ranking agents on it — no gold-standard benchmark to compare against, because if you had one you wouldn’t need this.
The specific defects this paper targets are three: tasks that are internally inconsistent (the user goal contradicts the domain policy, or the expected outcome doesn’t follow from the goal), scenarios that are trivially simple (one turn, one tool call, no branching, so every decent agent saturates), and policy documents whose rules are never exercised by any task at all (you wrote 40 rules; 12 are tested).
PROBLEM: agent scores are trusted but the ruler itself is unchecked
         and increasingly the ruler is LLM-generated
   |
   v
ASSUMPTION: benchmark quality decomposes into axes that can be
            scored WITHOUT a gold reference benchmark
   +-- consistency      (goal vs policy vs answer key)
   +-- complexity       (turns / tools / branch points)
   +-- policy coverage  (rules exercised / rules written)
   |
   v
METHOD: LLM judges score each axis and emit per-item diagnostics
        pointing at the specific broken task or untested rule
   |
   v
EVIDENCE
   +-- [1] agreement with independent human annotation
   +-- [2] benchmarks from stronger generator LLMs score higher
   +-- [3] controlled quality-degrading perturbations are detected
   +-- [4] ordering is stable across domains and across judge models
   |
   v
CONCLUSION: reference-free meta-evaluation works on synthetic
            benchmarks AND transfers to hand-curated ones
The Increment
One sentence: Before, “is this benchmark any good?” was answered by a human reading a sample and forming an opinion; after, it’s answered by three reference-free scores plus a list of which tasks are broken and which policy rules nobody tests.
Core Mechanism
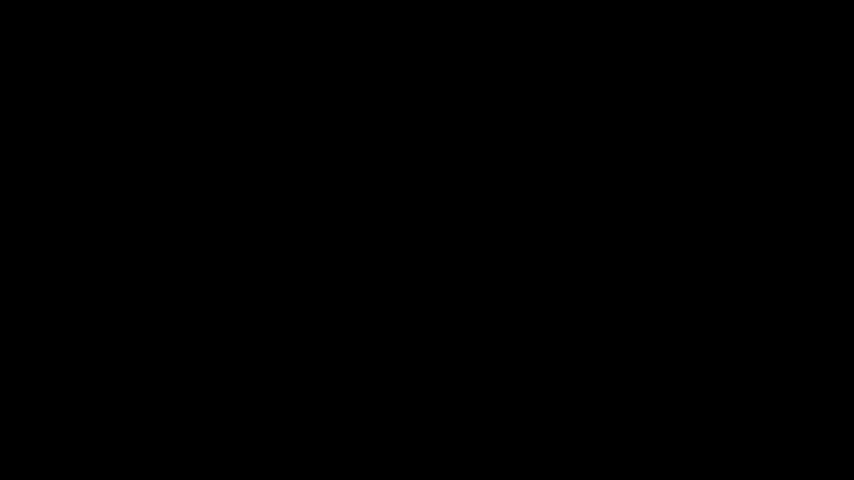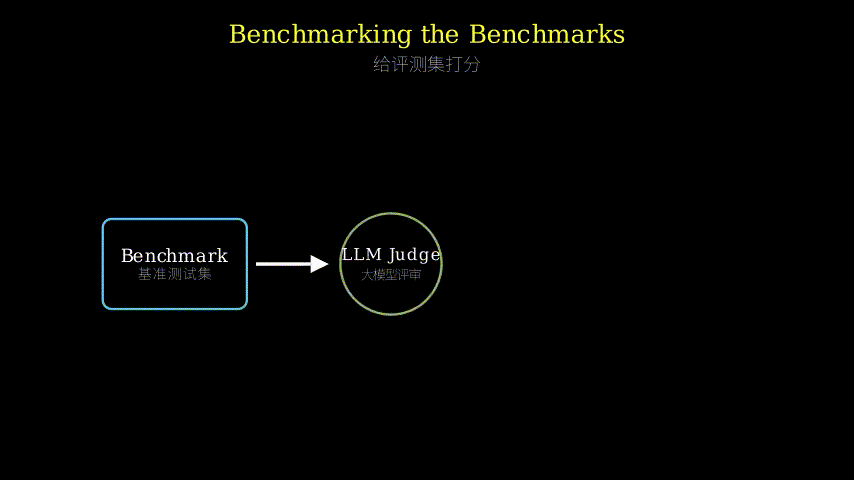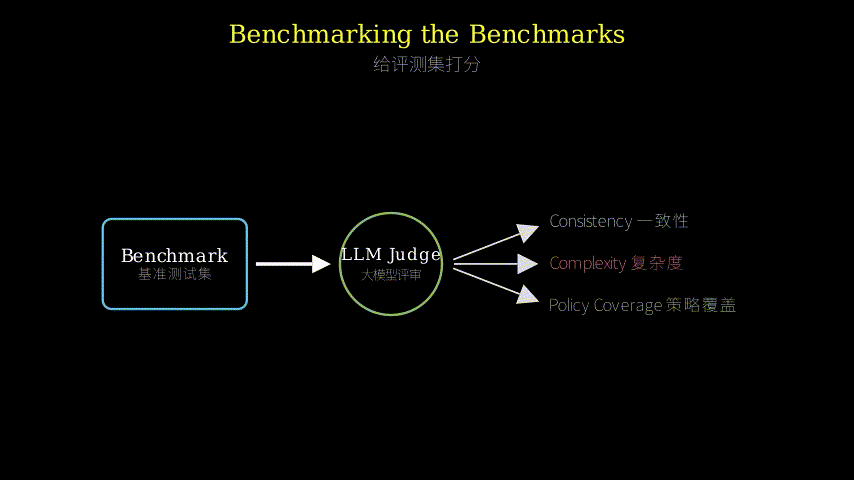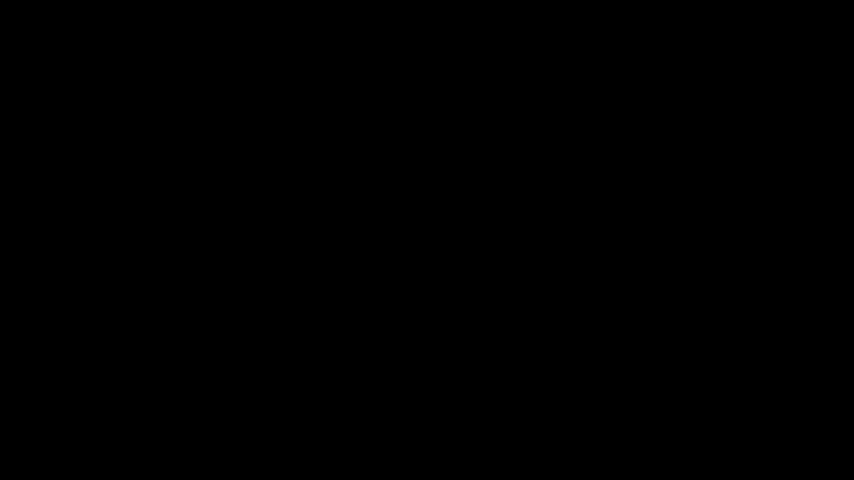
The framework takes a benchmark as a structured object rather than a blob. Input is the triple: the domain policy document, the task set (each task = persona + goal + any seeded database state), and the expected outcomes or reference actions used for grading. Three judge pipelines then run over this, each asking a different question, and — this is the part that matters operationally — each producing output at the granularity you can act on.
The consistency judge works per task. It reads the task alongside the policy document and the expected outcome, and looks for contradictions: does the user’s goal ask for something the policy forbids while the answer key says the agent should comply? Is the goal underspecified such that multiple outcomes are equally correct but only one is marked right? Is the seeded database state incompatible with the goal? Output is a flag plus a reason, per item.
The complexity judge also works per task, but it’s estimating demand rather than validity: how many reasoning hops, tool calls, information-gathering turns, and decision branches does this task require of an agent? A task like “cancel order 12345” is a single lookup; “the customer wants a refund on a delivered item bought 40 days ago with a partially used gift card” forces the agent to walk multiple policy clauses and negotiate. The policy coverage judge is the one that changes shape: instead of scoring tasks, it first decomposes the policy document into atomic rules, then builds a rule-to-task incidence map — which tasks, if any, force the agent to apply rule *k. Coverage is the fraction of rules with at least one task, and the diagnostic is the list of orphaned rules.
Validation is the other half of the contribution, and it’s structured as three independent pressure tests: agreement with human annotators who never saw the judge outputs; a known-ordering test where benchmarks generated by weak, mid, and strong LLMs should come out ranked accordingly; and an injected-defect test where a clean benchmark is deliberately corrupted (contradictions inserted, tasks simplified, coverage narrowed) and the metrics must drop in the right axis.
 INPUT (the benchmark under test)
 +--------------------------------------------+
 | domain policy document                     |
 | task set: persona + goal + seed state      |
 | expected outcomes / reference actions      |
 +--------------------------------------------+
        |                |                |
        v                v                v
 [ JUDGE: CONSISTENCY ]  [ JUDGE: COMPLEXITY ]  [ JUDGE: COVERAGE ]
 goal vs policy vs       hops / tools /         split policy into
 answer key              turns / branches       atomic rules then
 contradiction check     demand estimate        map rule -> tasks
        |                |                |
        v                v                v
 per-task flag +    per-task demand    rule-level hit map
 reason string      score              + orphan rule list
        |                |                |
        +--------+-------+-------+--------+
                          v
        +--------------------------------------------+
        | AXIS SCORES  consistency . complexity .    |
        |              coverage                      |
        | DIAGNOSTICS  task 17 contradicts rule 4    |
        |              rules 9 11 23 never tested    |
        +--------------------------------------------+
                          |
                          v
              repair / regenerate / accept
                          |
   VALIDATION ============+============
   +-- vs human annotation        (does it agree with us)
   +-- vs generator model tier    (does it order known-good/bad)
   +-- vs injected perturbation   (does it catch damage on the right axis)
   +-- across domains and judges  (is it stable)
The metaphor: this is an exam board reviewing a final exam before it’s administered.
The domain policy document is the syllabus. The task set is the question paper. The expected outcomes are the answer key. The agent under test is the student — and today’s practice is to hand the student a paper that a junior TA generated overnight, grade it, and publish the class ranking without anyone checking the paper.
The three judges are three reviewers on the exam board. Reviewer one cross-checks each question against the syllabus and the answer key: is the marked answer actually correct given the rules, and is the question unambiguous? That’s consistency. Reviewer two asks whether the paper is too easy — all questions from chapter one, all single-step — because an exam every student aces tells you nothing about who’s better. That’s complexity. Reviewer three works the other direction: she goes down the syllabus line by line and asks which question tests this. Chapters 9, 11, and 23 are on the syllabus but appear nowhere on the paper. That’s policy coverage, and note how it’s structurally different from the other two: it iterates over the syllabus, not over the questions.
The report they hand back isn’t a grade, it’s a marked-up paper: question 17 contradicts the refund rule, questions 3–8 are all single-step, chapter 11 is untested. That’s what “actionable diagnostics” buys you over a single quality number — you can fix the paper.
And how do you know the exam board is competent? You don’t trust their say-so. You (a) check their verdicts against independent expert readers, (b) hand them papers written by a first-year TA, a senior TA, and a professor and see if they rank them correctly, and (c) slip them a paper you personally sabotaged and check that they flag exactly the sabotage you inserted. Three tests, three different ways of being wrong.
Key Concepts
-
Reference-free evaluation: Normally to score something you compare it to a right answer. Benchmark quality has no right answer — there is no canonical “perfect MultiWOZ” to diff against, and if someone built one, you’d just use it instead. Reference-free means the score comes from *internal relations only: the task must be consistent with the policy in the same file, the coverage is computed against the policy shipped with the benchmark. It’s like proofreading a contract for self-contradiction versus checking it against a master template — you can catch a lot without any external ground truth, and the paper’s validation exists precisely because “no reference” also means “no obvious way to know if you’re right.”
-
Policy coverage: Think of the domain policy as a list of
ifconditions the agent must respect: *no refunds after 30 days, escalate if the order is flagged fraudulent, never reveal another customer’s address. A task “covers” a rule if solving it correctly requires triggering that rule. A benchmark of 200 tasks can have terrible coverage if 190 of them are order lookups — the count looks impressive while whole branches of behavior go untested. This is exactly the code-coverage idea, transplanted: line count is not test coverage, and task count is not policy coverage. -
Discriminative validity via known ordering: The trick used to validate the metrics without ground truth. You can’t verify “benchmark A scores 0.71” in isolation, but you *can manufacture situations where the true ordering is known by construction — a benchmark written by a weak model should be worse than one written by a strong model; a benchmark you just injected contradictions into is definitely worse than its clean original. If the metric reproduces every ordering you already know, you gain confidence in the orderings you don’t. This is the standard move for validating any unreferenced measure, and it’s worth stealing.
Framework Shift
Before (mainstream approach):          After (this paper):

[ benchmark ]                          [ benchmark ]
     ||                                     |
  assumed                                   v
   valid                        +--------------------------+
     ||                         | meta-eval: 3 axes        |
     vv                         | + item-level diagnostics |
[ agent runs ]                  +--------------------------+
     |                                      |
     v                        +-------------+-------------+
  score                       |                           |
     |                   quality low                 quality ok
     v                        |                           |
 leaderboard              repair the                      v
 (error bars              benchmark                  [ agent runs ]
  unknown)                    |                           |
                              +------> back up             v
   quality audit =                                  score you can
   one human reading                                actually reason
   20 samples once                                  about
One sentence: from *the benchmark is the ground truth to the benchmark is an artifact with a measurable defect profile, the core shift is treating your evaluation set as code that needs its own test suite rather than as a fixed reference.
Expert Assessment
Problem choice: Real gap, and well-timed rather than manufactured. The field’s trajectory is unambiguous — as agent benchmarks get generated at scale by LLMs, the variance in benchmark quality starts to dominate the variance in agent quality, and we’ve already seen high-profile agentic suites turn out to contain unsolvable or mis-keyed tasks. The framing choice is also good: they didn’t try to build “the correct benchmark,” they built an inspector. Inspectors compose with everything; canonical benchmarks age out. My one complaint about scoping is that the three axes are the *easy three. The defect that has burned the community hardest is unsolvability / ungradeability — tasks where no agent can succeed because the required information isn’t in the environment, or where the grader can’t distinguish success from failure. Consistency partly touches this, but a dedicated solvability axis (ideally with an actual agent rollout, not just a judge reading text) is the obvious missing fourth column.
Method maturity: Honestly, this is clever assembly rather than a new mechanism. LLM-as-judge with rubric prompts is off-the-shelf; the increment is *which three things to ask about and how to validate the asking. The genuinely nice bit is policy coverage, because it inverts the iteration direction — decomposing the policy into atomic rules and building an incidence map is more than a rubric score, and it’s the part that yields a to-do list rather than an opinion. Simpler alternatives are absolutely being under-credited: complexity has cheap structural proxies (reference-solution length, number of tool calls, number of policy clauses touched, dialogue turns), and coverage could be approximated with embedding-based rule-to-task retrieval at a fraction of the cost. A paper this practical should include the “do you actually need an LLM here?” ablation for each axis, and I’d bet the LLM earns its keep on consistency and coverage but not on complexity.
Experimental integrity: The three-pronged validation design is the strongest part of the paper — human agreement, generator-tier ordering, and perturbation detection fail in different ways, so passing all three is meaningful, and testing across domains *and judge models heads off the “you tuned prompts for GPT-flavor-X” objection. Two things to keep your skepticism about. First, perturbation-based validation is partly self-fulfilling: you choose the corruptions, so it demonstrates sensitivity to the defects you imagined, not coverage of the defect space that exists in the wild. It’s a necessary test, not a sufficient one. Second, and more fundamental, there’s a circularity risk — LLM judges evaluating LLM-generated benchmarks share training distributions and therefore share blind spots, and a same-family generator/judge pair will happily agree on something a human would reject. The human-agreement experiment is the only defense, which puts enormous weight on its design; look hard at annotator count, inter-annotator agreement, and whether the human sample was stratified or convenience-sampled, because if agreement was computed on a small unstratified sample the whole edifice is resting on it. The one experiment I most want and doubt is there: does benchmark quality score predict downstream evaluation behavior — do low-complexity benchmarks actually show ceiling effects and compressed agent rankings, do low-consistency benchmarks produce unstable agent orderings across reruns? That would convert “the judges agree with humans” into “the metric predicts the thing you care about,” and it’s the difference between a useful tool and a load-bearing result.
Writing quality: Judging from how these papers usually get built, the corners are cut in two predictable places. The prompt and rubric appendix is where the reproducibility actually lives — score granularity, whether judges see one task or the whole set, how the policy is decomposed into atomic rules and how sensitive coverage is to that decomposition — and it tends to arrive as a raw prompt dump with no ablations. And the human-annotation subsection is usually two sentences where it needs a page. Rewriting the validation section to lead with the *predictive claim about downstream agent evaluation, with the perturbation study demoted to a sanity check rather than headline evidence, would elevate the whole paper a full tier.
Verdict: weak accept — a genuinely useful, well-validated instrument built from standard parts, held back by modest methodological novelty, an unresolved judge/generator circularity, and no demonstration that the scores predict downstream evaluation reliability.
Takeaways
Things worth stealing regardless of whether you work on conversational agents:
-
Coverage should iterate over the spec, not over the tests. The policy-coverage construction — decompose the requirements document into atomic rules, then map rules to test items, then report the orphans — transfers directly to RAG eval sets, safety red-team suites, API test suites, and compliance checklists. Any time you have a document of requirements and a pile of test cases, you can compute this, and the orphan list is immediately actionable. Most teams count test cases instead, which is the same mistake as counting lines of code.
-
Validate an unreferenced metric by manufacturing known orderings. Generator-tier ordering plus controlled sabotage plus human spot-check is a reusable recipe for any “quality score” you invent where ground truth doesn’t exist. Adopt it as a template: one test against human judgment, one against a construction-guaranteed ranking, one against injected damage.
-
Make eval-quality output diagnostics, not scores. A benchmark scoring 0.68 is useless; “task 17 contradicts rule 4, rules 9/11/23 are untested” gets fixed on Friday afternoon. Design any quality checker so its output is a work queue.
-
Treat your eval set as code with its own CI. Concretely: run a consistency and coverage check on your eval set every time you regenerate or extend it, and gate merges on it. This is cheap to implement today with the axes described here and catches synthetic-data rot before it silently reshapes your leaderboard.
-
The healthy skepticism to carry forward: judging LLM output with LLM judges from the same family is a correlated-error problem, not an independent one. If you adopt this framework, use a judge from a different family than your generator, and keep a small stratified human audit alive as a tripwire.
论文: 2608.06329 作者: Noam Koren, Roy Bar-Haim, Abigail Goldsteen 分类: cs.AI, cs.CL
缺口
先说这个领域走进的尴尬处境。
任务型对话智能体——客服、订票、退货那一类——现在靠 MultiWOZ、ABCD 以及 τ-bench 一脉的策略驱动基准来评测。 这类基准的结构是三件套:一份领域政策文档(智能体必须遵守的规则)、一批任务(用户人设 + 目标 + 初始数据库状态)、以及用于判分的期望结果。
问题在于,手写几百条这样的任务太贵,所以现在大量新基准是 LLM 生成的,有的经过轻量人工筛选,有的干脆没有。
换句话说,量具本身变成了模型输出。而没人校准过它。
已有工作确实在攻打邻近的问题。 LLM-as-a-judge 的可靠性研究是一大块,但那问的是打分器靠不靠谱,不是题目靠不靠谱。 合成指令数据的质量研究有去重、难度打分、污染检测那一套,但对象是单条指令,不是一个带政策文档的基准整体。 还有一类是人工重标某个具体基准、报告错误率的审计——很有价值,但一次性、昂贵、不可迁移。 最近还兴起了”智能体基准全是坑”的经验之谈,罗列失败模式却停在案例层面。
缺的是一个可复用、无参考的方法:在你花掉 GPU 小时去给智能体排名之前,先给这个基准本身打个分。 所谓无参考,是因为你手上没有一个”标准正确的基准”可以对比——真有的话你直接用它就好了。
这篇针对的具体缺陷是三类:任务内部自相矛盾(用户目标与政策冲突,或者期望结果推不出来)、场景过于简单(一轮对话一次工具调用没有分支,所有像样的智能体都满分)、政策文档里的规则根本没有任务去触发(你写了 40 条规则,只有 12 条被测到)。
PROBLEM: 智能体分数被当真 但尺子本身没被检查
         而且尺子越来越多是 LLM 生成的
   |
   v
ASSUMPTION: 基准质量可以分解成若干轴
            且这些轴不需要标准答案基准就能打分
   +-- consistency      (目标 vs 政策 vs 答案键)
   +-- complexity       (轮次 / 工具 / 分支点)
   +-- policy coverage  (被触发规则 / 已写规则)
   |
   v
METHOD: LLM 评判分别给三个轴打分
        并输出条目级诊断 指出哪条任务坏了 哪条规则没测
   |
   v
EVIDENCE
   +-- [1] 与独立人工标注一致
   +-- [2] 更强生成模型产出的基准得分更高
   +-- [3] 人为注入的质量退化被检出
   +-- [4] 跨领域 跨评判模型排序稳定
   |
   v
CONCLUSION: 无参考元评测在合成基准上可用
            并能迁移到人工精编基准
增量
一句话:以前”这个基准好不好”的答案是某个人抽读二十条然后给个印象;以后是三个无参考分数,加上一份”哪些任务是坏的、哪些政策规则没人测”的清单。
核心机制
框架把基准当成结构化对象而不是一团文本来处理。 输入是三元组:领域政策文档、任务集(每条任务 = 人设 + 目标 + 种子数据状态)、以及用于判分的期望结果或参考动作。 三条评判流水线在这上面跑,各问一个不同的问题——而运营上真正关键的是,每条都输出你能动手改的粒度。
一致性评判逐任务工作。 它把任务、政策文档、期望结果放在一起读,找矛盾:用户目标要求的事情是不是政策明令禁止、而答案键却写着智能体应该照办?目标是不是欠定义到有多个同样正确的结果、却只有一个被判对?种子数据状态跟目标是不是互斥?输出是逐条的标记加理由。
复杂度评判也是逐任务,但估的是需求而非有效性:这条任务要求智能体做多少次推理跳转、工具调用、信息收集轮次和决策分支?“取消订单 12345”是一次查表;“客户想退 40 天前买的已签收商品,且部分用了礼品卡”就迫使智能体串起好几条政策条款并做协商。
政策覆盖率评判的形状不一样。 它不是给任务打分,而是先把政策文档拆成原子规则,再建一张规则到任务的关联表——哪些任务(如果有的话)会迫使智能体应用第 k 条规则。 覆盖率是至少有一条任务的规则占比,诊断输出则是那份”孤儿规则”名单。
验证是贡献的另一半,结构是三条互相独立的压力测试:与没看过评判输出的人工标注比对;已知排序测试,弱、中、强三档 LLM 生成的基准应该被排出对应次序;注入缺陷测试,把干净基准故意破坏(插入矛盾、简化任务、收窄覆盖),指标必须在对应的那个轴上下降。
 INPUT (待检基准)
 +--------------------------------------------+
 | 领域政策文档                                |
 | 任务集: 人设 + 目标 + 种子状态              |
 | 期望结果 / 参考动作                         |
 +--------------------------------------------+
        |                |                |
        v                v                v
 [ JUDGE: 一致性 ]    [ JUDGE: 复杂度 ]   [ JUDGE: 覆盖率 ]
 目标 vs 政策 vs      跳转 / 工具 /       政策拆成原子规则
 答案键               轮次 / 分支         再建 规则 -> 任务
 找矛盾               估计需求量          关联表
        |                |                |
        v                v                v
 逐任务标记+理由     逐任务需求分       规则级命中表
                                        + 孤儿规则名单
        |                |                |
        +--------+-------+-------+--------+
                          v
        +--------------------------------------------+
        | 轴分数  一致性 . 复杂度 . 覆盖率            |
        | 诊断    任务 17 与规则 4 冲突               |
        |         规则 9 11 23 从未被测试             |
        +--------------------------------------------+
                          |
                          v
                  修复 / 重生成 / 接收
                          |
   VALIDATION ============+============
   +-- 对照人工标注         (跟人判断一致吗)
   +-- 对照生成模型档位     (已知好坏能排对吗)
   +-- 对照注入的扰动       (能打中被破坏的那个轴吗)
   +-- 跨领域跨评判模型     (稳定吗)
核喻:这是考试命题审核委员会在开考前审卷。
领域政策文档是考纲。 任务集是试卷。 期望结果是答案标准。 被测智能体是学生——而今天的做法是,把一个助教通宵生成的卷子发给学生,判分,然后公布班级排名,中间没人审过这张卷。
三个评判就是审核委员会的三位审卷人。 第一位逐题对照考纲和答案标准:给出的标准答案在规则下真的成立吗,题目有没有歧义?这是一致性。 第二位问这张卷是不是太简单了——所有题都出自第一章、都是一步题——因为一张人人满分的卷子分辨不出谁更强。这是复杂度。 第三位反方向工作:她拿着考纲一行一行往下过,问”这一条由哪道题来考”。考纲第 9、11、23 章在纲上,卷面上一道都没有。这就是政策覆盖率——注意它和前两位结构不同:它遍历的是考纲,不是题目。
他们交回来的不是一个分数,而是一张批注过的卷子:第 17 题与退款规则冲突,第 3 到 8 题全是一步题,第 11 章没考。 这就是”可操作诊断”比单一质量分多出来的东西——你能真的去修这张卷。
那你凭什么信这个审核委员会有本事?不能听他们自己说。 你 (a) 拿独立专家读者的判断去核对他们的结论,(b) 把大一助教、资深助教、教授三个人写的卷子交给他们,看排序对不对,(c) 塞一张你亲手做过手脚的卷子,看他们是否正好标出你动的那处。 三个测试,对应三种不同的出错方式。
关键概念
-
无参考评测(reference-free):通常打分要跟正确答案比。 基准质量没有正确答案——不存在一个”完美版 MultiWOZ”供你 diff,真有人做出来了你也直接用它了。 无参考意味着分数只来自内部关系:任务必须与同一份文件里的政策自洽,覆盖率是对着基准自带的政策算的。 这就像校对一份合同看它有没有自相矛盾,而不是拿它去比对一份母版模板——没有外部真值也能抓出很多问题。 而这篇论文之所以要花半篇做验证,恰恰因为”没有参考”同时意味着”没有明显办法知道你判得对不对”。
-
政策覆盖率:把领域政策想成一串智能体必须遵守的
if条件:*超过 30 天不退款、订单被标记欺诈则升级人工、绝不透露其他客户地址。 一条任务”覆盖”某条规则,是指正确解出它必须触发那条规则。 一个 200 条任务的基准可能覆盖率极差——如果其中 190 条都是查订单,数量看着漂亮,整片行为分支却完全没测。 这就是代码覆盖率那个思路的移植:行数不等于测试覆盖,任务数也不等于政策覆盖。 -
靠已知排序做区分效度验证:这是在没有真值的情况下验证指标的手法。 你没法孤立地核实”基准 A 得 0.71”,但你可以制造出真值排序由构造保证的情形——弱模型写的基准应该差于强模型写的;刚被你注入矛盾的基准一定差于它的干净原版。 如果指标能复现你已经知道的每一个排序,你对它在未知情形下的排序才有信心。 这是验证任何无参考度量的标准动作,值得直接学走。
框架转变
之前(主流方法):                    之后(本文方法):

[ 基准 ]                              [ 基准 ]
   ||                                     |
 默认                                     v
 有效                        +--------------------------+
   ||                        | 元评测: 3 个轴           |
   vv                        | + 条目级诊断             |
[ 跑智能体 ]                 +--------------------------+
   |                                      |
   v                       +--------------+-------------+
 分数                      |                            |
   |                    质量不足                    质量合格
   v                       |                            |
 排行榜                 修复基准                        v
 (误差范围                 |                       [ 跑智能体 ]
  未知)                    +------> 回到顶部            |
                                                       v
 质量审计 =                                       可以据以推理
 某人抽读 20 条                                   的分数
 一次
一句话:从**基准即真值到基准是一个带可测缺陷画像的人造物*,核心转变是把评测集当成需要自带测试套件的代码,而不是当成一把固定的尺。
专家评审
选题眼光:真缺口,而且时机对,不是硬造的。 领域的走向很明确——当智能体基准开始被 LLM 大规模生成,基准质量的方差就会盖过智能体质量的方差;我们已经见过知名智能体测试集里被查出无解任务和错标答案。 框架化的选择也聪明:他们没去建”那个正确的基准”,而是建了一个检验员。 检验员能跟一切组合,标杆基准则会过时。
我对选题范围唯一的不满是:这三个轴是最容易的三个。 真正把社区烧得最疼的缺陷是不可解 / 不可判分——环境里根本没有所需信息导致任何智能体都做不成,或者判分器分不出成功失败。 一致性部分沾到了这一点,但一个专门的可解性轴(理想上要有真实的智能体 rollout,而不只是评判读文本)是明摆着缺的第四列。
方法成熟度:坦白说这是巧妙的组装,不是新机制。 带 rubric 提示的 LLM-as-judge 是现成货,增量在于该问哪三件事以及怎么验证这个问法。 真正好的部分是政策覆盖率,因为它把遍历方向反了过来——把政策拆成原子规则再建关联表,这不只是一个 rubric 分数,而且它产出的是待办清单而非意见。
更简单的替代方案明显被低估了:复杂度有很便宜的结构代理(参考解长度、工具调用次数、涉及的政策条款数、对话轮数),覆盖率也可以用嵌入检索做规则到任务的近似匹配,成本只是零头。 这么务实的一篇论文,应该对每个轴都做一次”这里真的需要 LLM 吗”的消融。 我打赌 LLM 在一致性和覆盖率上值这个钱,在复杂度上不值。
实验诚意:三路验证的设计是这篇最强的地方——人工一致性、生成模型档位排序、扰动检出,三者的失效方式不同,所以同时通过是有意义的;跨领域且跨评判模型也提前挡掉了”你只是针对某家模型调了提示”这一质疑。
但有两点要保持怀疑。 第一,扰动验证有自我实现的成分:扰动是你自己选的,所以它证明的是对你想得到的缺陷敏感,而不是覆盖了野生环境里真实存在的缺陷空间。这是必要测试,不是充分测试。 第二,也更根本,存在循环风险——LLM 评判去评 LLM 生成的基准,两者共享训练分布因而共享盲区;同家族的生成器/评判对会愉快地在人类会否决的事情上达成一致。 唯一的防线就是人工一致性实验,这让它的设计承担了极大的重量:仔细看标注人数、标注者间一致度、以及人工样本是分层抽的还是顺手抽的——如果一致度是在一个小的非分层样本上算的,整座楼就撑在这根柱子上。
我最想看、又最怀疑没有的实验是:基准质量分数能不能预测下游评测行为——低复杂度基准是不是真的出现天花板效应和被压缩的智能体排名,低一致性基准是不是导致重复运行间智能体排序不稳。 这会把”评判和人类看法一致”升级成”这个指标能预测你真正关心的东西”,也是一个好用工具和一个承重结论之间的差别。
写作功力:按这类论文通常的搭法,偷懒会出现在两个可预测的地方。 提示与 rubric 附录才是复现性真正的所在——打分粒度、评判是看单条任务还是看全集、政策怎么拆成原子规则、覆盖率对这个拆法有多敏感——而它往往是一堆原始提示的堆砌,没有任何消融。 人工标注那一小节通常是两句话,而它需要一页。 如果把验证章节重写成以”能预测下游智能体评测”这个论断领头、把扰动实验降级为 sanity check 而不是头条证据,整篇能升一个档。
判决:弱接收 —— 用标准零件搭出来的、验证做得扎实的实用量具;受限于方法新意有限、评判与生成器的循环性没解决、以及没有证明这些分数能预测下游评测的可靠性。
要点总结
不管你做不做对话智能体,下面这些值得偷走:
-
覆盖率应该遍历规格,而不是遍历测试。 政策覆盖率的构造——把需求文档拆成原子规则、再把规则映射到测试条目、再报告孤儿——可以直接迁到 RAG 评测集、安全红队套件、API 测试套件、合规检查表上。 只要你有一份需求文档加一堆测试用例,就能算这个数,而那份孤儿名单是立刻可执行的。 多数团队改成数测试用例的数量,这和数代码行数是同一个错误。
-
验证无参考指标的办法是制造已知排序。 生成模型档位排序 + 受控破坏 + 人工抽检,是任何”你自己发明的质量分”在没有真值时都能复用的配方。 当模板用:一个对人类判断、一个对构造保证的排名、一个对注入的损伤。
-
让评测质量的产出是诊断,不是分数。 一个基准得 0.68 毫无用处;“任务 17 与规则 4 冲突,规则 9/11/23 未被测试”周五下午就能改完。 设计任何质量检查器时,让它的输出是一个工作队列。
-
把评测集当成带 CI 的代码。 具体做法:每次重生成或扩充评测集时跑一遍一致性和覆盖率检查,并把它设成合并门槛。 用本文这几个轴今天就能便宜实现,能在合成数据腐化悄悄改写你的排行榜之前把它抓住。
-
要带走的那份健康怀疑:用同家族的 LLM 评判去审 LLM 的产出,这是相关误差问题,不是独立误差问题。 如果你采用这个框架,评判模型请用与生成器不同家族的,并保留一小份分层人工审计当绊线。