Paper: 2603.08683 Authors: Phillip Long, Zachary Novack, Chris Donahue Categories: cs.SD, cs.AI, cs.LG, eess.AS
The Gap
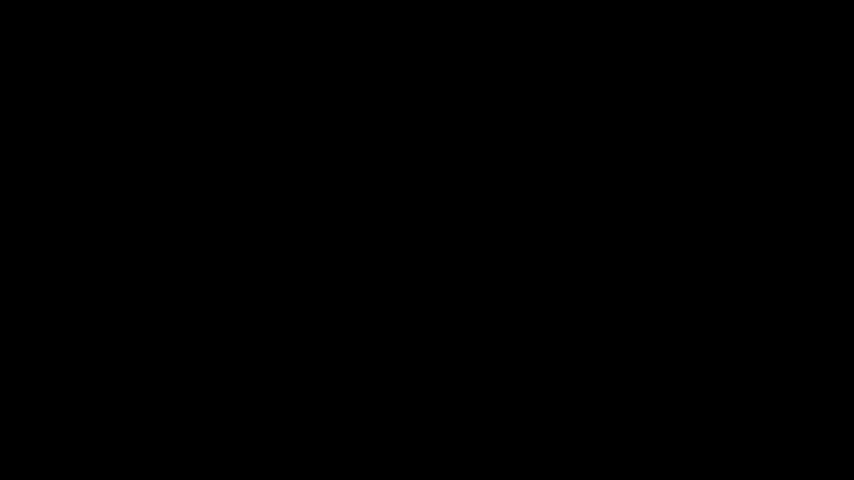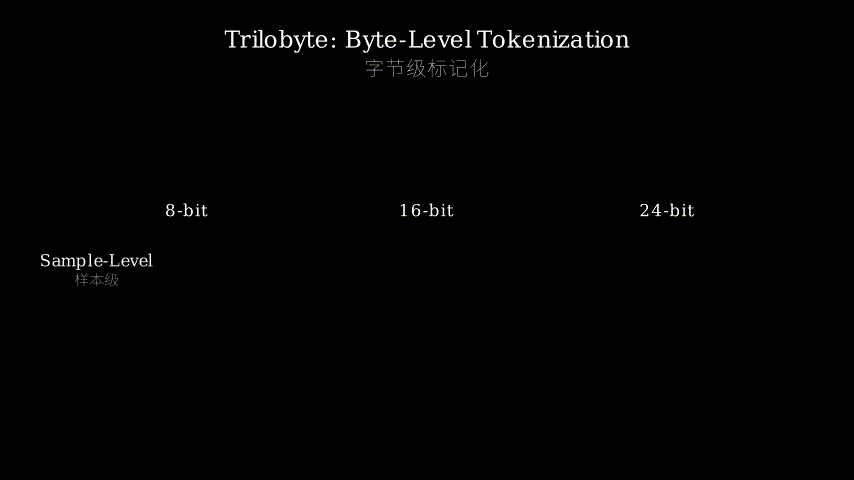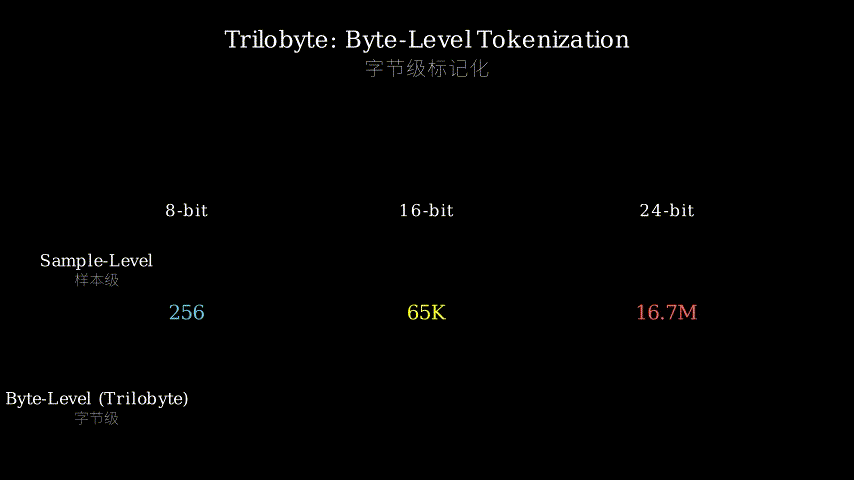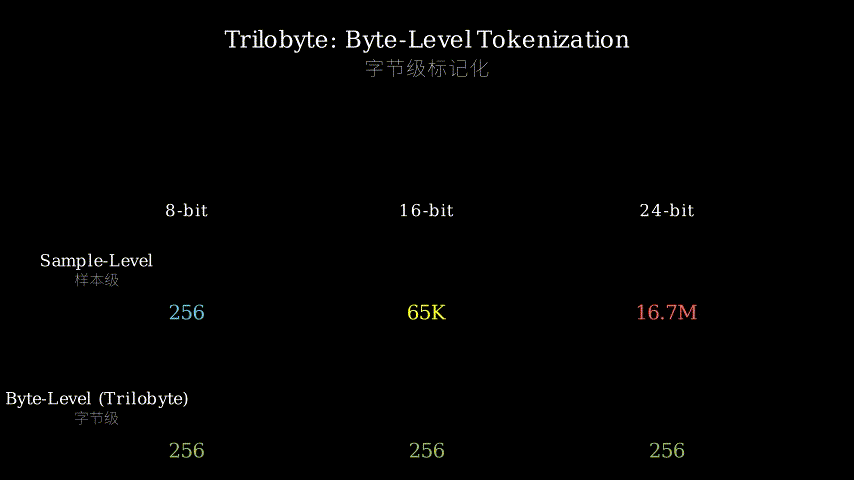
Prior work showed that autoregressive language models trained on raw audio waveforms can compress audio losslessly, but these experiments stopped at 8-bit audio—the quality of a 1980s telephone. Professional audio lives at 16-bit (CD quality) or 24-bit (studio quality), and nobody knew if neural compression could scale there. The vocabulary explosion is the killer: 8-bit needs 256 tokens, 16-bit needs 65,536, and 24-bit needs 16.7 million. Training a language model with a 16-million-token vocabulary is computationally absurd.
Problem: LM-based compression stuck at 8-bit
   |
   v
Assumption: Sample-level tokenization (one token per sample value)
   |
   v
Method: Byte-level tokenization (Trilobyte) - O(1) vocab instead of O(2^b)
   |
   v
Evidence: Benchmark across 8/16/24-bit, multiple domains, beats FLAC at 8/16-bit
   |
   v
Conclusion: LMs work for professional audio, but gains diminish at higher bit depths
The Increment
One sentence: Before this paper, neural audio compression was a toy demo on 8-bit audio; after, it’s a viable alternative to FLAC for professional 16/24-bit recordings with state-of-the-art compression ratios.
Core Mechanism
The method treats audio compression as next-token prediction, but instead of predicting entire sample values (which would require millions of tokens for 24-bit), it predicts bytes. A 24-bit audio sample is three bytes. The model sees the first byte, predicts the second, then sees both and predicts the third. This sequential byte prediction turns an intractable vocabulary problem into a manageable one—you only need 256 tokens regardless of bit depth.
The architecture is a standard autoregressive transformer. Audio samples flow in as byte sequences, the model builds context across time, and outputs probability distributions over the next byte. During compression, you encode the actual byte using arithmetic coding based on the model’s predicted probabilities. During decompression, you sample from those probabilities to reconstruct the original bytes perfectly.
Audio Sample (24-bit):  [byte1][byte2][byte3]
                           |      |      |
                           v      v      v
Transformer:          context -> P(byte2|byte1) -> P(byte3|byte1,byte2)
                           |      |      |
                           v      v      v
Arithmetic Coder:      encode actual bytes using predicted probabilities
                           |
                           v
Compressed Bitstream:  [bits representing byte sequence]
Think of this like a translator working with an unfamiliar alphabet. Instead of memorizing 16 million unique symbols (sample-level), they learn 256 letters (byte-level) and spell out each word letter-by-letter. A 24-bit sample is a three-letter word. The translator reads the first letter, guesses the second based on patterns they’ve learned, then reads both and guesses the third. If their guesses are good (high probability on the correct letter), the word compresses well. The arithmetic coder is the shorthand system that writes down only the surprising parts—if the translator was 99% sure about a letter, you barely need any ink to record it.
Key Concepts
-
Arithmetic Coding: Imagine you’re encoding a message where some letters are very predictable and others aren’t. Instead of using fixed-length codes (like ASCII’s 8 bits per character), arithmetic coding uses fewer bits for probable outcomes and more for improbable ones. If your model predicts the next byte is 0x42 with 90% confidence and it actually is 0x42, you only need about 0.15 bits to encode it (log₂(1/0.9)). If the model is surprised (predicted 1% probability), you need about 6.6 bits. The better your predictions, the smaller your compressed file. It’s the mathematical formalization of “don’t waste space stating the obvious.”
-
Byte-Level Tokenization: Standard language models treat each possible value as a distinct token—for 24-bit audio, that’s 16.7 million tokens, each needing its own embedding vector and output weight. Byte-level tokenization breaks each sample into its constituent bytes (3 bytes for 24-bit) and predicts them sequentially. The vocabulary stays at 256 tokens regardless of bit depth. The tradeoff: you predict 3 times per sample instead of once, but your model is 65,000x smaller in vocabulary size. It’s like switching from a dictionary with every possible three-letter combination to one with just the 26 letters of the alphabet.
-
Lossless Compression: Unlike MP3 or AAC which throw away information humans supposedly can’t hear, lossless compression preserves every bit of the original audio. You can decompress and get bit-for-bit identical data. The challenge is that audio has complex structure—nearby samples are correlated, but the patterns vary wildly between a symphony, a podcast, and a bird call. Traditional codecs like FLAC use hand-crafted predictors and entropy coding. Language models learn the patterns from data, potentially capturing structure that hand-crafted rules miss.
Framework Shift
Before (FLAC/traditional):           After (Trilobyte/LM-based):

Audio -> Hand-crafted -> Entropy     Audio -> Byte -> Transformer -> Arithmetic
         Predictor       Coder                Split   (learned       Coder
         (linear)        (fixed)                      predictor)     (adaptive)
            |               |                            |               |
            v               v                            v               v
      Fixed rules      Compress                   Learned patterns  Compress
      (domain-agnostic)                          (domain-adaptive)
From hand-crafted prediction rules to learned prediction models, the core shift is replacing domain-agnostic linear predictors with domain-adaptive neural networks that discover compression-relevant patterns from data.
Expert Assessment
Problem choice: This is a real gap with practical stakes. The 8-bit limitation in prior work made neural audio compression a curiosity, not a tool. Professional audio is 16/24-bit, and showing whether neural methods scale there matters for both ML research and audio engineering. The problem sits at the intersection of two mature fields (compression and language modeling), which is often where interesting things happen.
Method maturity: Trilobyte is clever but not revolutionary—byte-level tokenization is borrowed from text LMs handling Unicode. The insight is recognizing that audio samples are just multi-byte integers, so the same trick applies. The execution is solid: they benchmark properly across domains, bit depths, and sampling rates. No simpler approach is being overlooked; this is the natural next step after prior 8-bit work hit the vocabulary wall.
Experimental integrity: Baselines are fair—they compare against FLAC, the industry standard, and include ablations on tokenization schemes. The numbers are credible: LMs beat FLAC at 8/16-bit but gains shrink at 24-bit, which makes sense (higher bit depth means less redundancy to exploit). One minor flag: they don’t report training costs or inference speed, which matters for practical adoption. Compression ratio alone doesn’t tell you if this is deployable.
Writing quality: The paper is clear and well-structured. The weakness is in the discussion section—they observe diminishing returns at higher bit depths but don’t deeply explore why. Is it fundamental (less structure to model) or contingent (model capacity, training data)? A paragraph of speculation with follow-up experiments would strengthen the contribution. The related work section is thorough but could be trimmed.
Verdict: weak accept — Solid empirical work that answers an open question (do LMs scale to professional audio?) with a practical solution (byte-level tokenization), but the contribution is incremental rather than paradigm-shifting.
Takeaways
The byte-level tokenization trick transfers directly to any domain with multi-byte data: high-resolution images, scientific sensor data, genomic sequences. If you’re hitting vocabulary explosion with sample-level tokenization, break samples into bytes and predict sequentially. The tradeoff is always the same: smaller vocabulary, more prediction steps, but tractable training.
The diminishing returns at higher bit depths is a useful negative result. It suggests neural compression’s advantage comes from modeling structure in the high-order bits (which carry most of the signal), not from squeezing out the last bit of entropy in the low-order bits (which are nearly random). If you’re working on compression for high-precision data, focus your model capacity on the structured parts.
The benchmark itself is valuable infrastructure. They tested across music, speech, and bioacoustics at multiple sampling rates and bit depths. If you’re developing a new compression method, this gives you a standardized evaluation protocol to compare against.
论文: 2603.08683 作者: Phillip Long, Zachary Novack, Chris Donahue 分类: cs.SD, cs.AI, cs.LG, eess.AS
缺口
此前的研究表明,在原始音频波形上训练的自回归语言模型可以无损压缩音频,但这些实验止步于 8 位音频——相当于 1980 年代电话的音质。
专业音频使用 16 位(CD 音质)或 24 位(录音室音质),没人知道神经压缩能否扩展到这个级别。
词汇表爆炸是致命问题:8 位需要 256 个词元,16 位需要 65,536 个,24 位需要 1670 万个。
训练一个拥有 1600 万词元词汇表的语言模型在计算上是荒谬的。
问题:基于语言模型的压缩困在 8 位
   |
   v
假设:样本级分词(每个样本值一个词元)
   |
   v
方法:字节级分词(Trilobyte)- O(1) 词汇表而非 O(2^b)
   |
   v
证据:跨 8/16/24 位基准测试,多个领域,在 8/16 位击败 FLAC
   |
   v
结论:语言模型适用于专业音频,但在更高位深度收益递减
增量
一句话: 这篇论文之前,神经音频压缩是 8 位音频上的玩具演示;之后,它成为专业 16/24 位录音的 FLAC 可行替代方案,具有最先进的压缩比。
核心机制
该方法将音频压缩视为下一词元预测,但不是预测整个样本值(对于 24 位需要数百万词元),而是预测字节。
一个 24 位音频样本是三个字节。
模型看到第一个字节,预测第二个,然后看到两个字节并预测第三个。
这种顺序字节预测将难以处理的词汇表问题转化为可管理的问题——无论位深度如何,你只需要 256 个词元。
架构是标准的自回归 Transformer。
音频样本以字节序列形式流入,模型跨时间构建上下文,并输出下一个字节的概率分布。
在压缩期间,你使用算术编码根据模型预测的概率对实际字节进行编码。
在解压缩期间,你从这些概率中采样以完美重建原始字节。
音频样本(24 位):  [字节1][字节2][字节3]
                        |      |      |
                        v      v      v
Transformer:       上下文 -> P(字节2|字节1) -> P(字节3|字节1,字节2)
                        |      |      |
                        v      v      v
算术编码器:        使用预测概率编码实际字节
                        |
                        v
压缩比特流:        [表示字节序列的比特]
把这想象成一个翻译在处理陌生字母表。
他们不是记住 1600 万个独特符号(样本级),而是学习 256 个字母(字节级)并逐字母拼出每个单词。
一个 24 位样本是一个三字母单词。
翻译读第一个字母,根据学到的模式猜第二个,然后读两个字母并猜第三个。
如果他们的猜测很好(对正确字母的高概率),单词就压缩得好。
算术编码器是速记系统,只写下令人惊讶的部分——如果翻译对某个字母有 99% 的把握,你几乎不需要任何墨水来记录它。
关键概念
- 算术编码: 想象你在编码一条消息,其中一些字母非常可预测,而另一些则不然。
算术编码不使用固定长度代码(如 ASCII 的每字符 8 位),而是对可能的结果使用更少的比特,对不可能的结果使用更多比特。
如果你的模型以 90% 的置信度预测下一个字节是 0x42,而它确实是 0x42,你只需要大约 0.15 比特来编码它(log₂(1/0.9))。
如果模型感到惊讶(预测 1% 概率),你需要大约 6.6 比特。
预测越好,压缩文件越小。
这是”不要浪费空间陈述显而易见的事”的数学形式化。
- 字节级分词: 标准语言模型将每个可能的值视为不同的词元——对于 24 位音频,这是 1670 万个词元,每个都需要自己的嵌入向量和输出权重。
字节级分词将每个样本分解为其组成字节(24 位为 3 个字节)并顺序预测它们。
无论位深度如何,词汇表保持在 256 个词元。
权衡:你每个样本预测 3 次而不是 1 次,但你的模型在词汇表大小上小 65,000 倍。
这就像从包含每个可能的三字母组合的字典切换到只有 26 个字母的字典。
- 无损压缩: 与 MP3 或 AAC 丢弃人类据称听不到的信息不同,无损压缩保留原始音频的每一位。
你可以解压缩并获得逐位相同的数据。
挑战在于音频具有复杂的结构——相邻样本是相关的,但模式在交响乐、播客和鸟鸣之间差异很大。
传统编解码器如 FLAC 使用手工制作的预测器和熵编码。
语言模型从数据中学习模式,可能捕获手工制作规则遗漏的结构。
框架转变
之前(FLAC/传统):              之后(Trilobyte/基于语言模型):

音频 -> 手工制作 -> 熵编码      音频 -> 字节 -> Transformer -> 算术
        预测器      (固定)             拆分    (学习的        编码
        (线性)                                 预测器)       (自适应)
           |           |                           |               |
           v           v                           v               v
      固定规则    压缩                        学习的模式      压缩
      (领域无关)                           (领域自适应)
从手工制作的预测规则到学习的预测模型,核心转变是用从数据中发现压缩相关模式的领域自适应神经网络替换领域无关的线性预测器。
专家评审
选题眼光: 这是一个具有实际意义的真实缺口。
先前工作中的 8 位限制使神经音频压缩成为好奇心,而非工具。
专业音频是 16/24 位,展示神经方法是否能扩展到那里对机器学习研究和音频工程都很重要。
该问题位于两个成熟领域(压缩和语言建模)的交叉点,这通常是有趣事情发生的地方。
方法成熟度: Trilobyte 很巧妙但不是革命性的——字节级分词是从处理 Unicode 的文本语言模型借来的。
洞察在于认识到音频样本只是多字节整数,因此同样的技巧适用。
执行很扎实:他们在领域、位深度和采样率上进行了适当的基准测试。
没有被忽视的更简单方法;这是先前 8 位工作遇到词汇表墙后的自然下一步。
实验诚意: 基线是公平的——他们与行业标准 FLAC 进行比较,并包括分词方案的消融实验。
数字是可信的:语言模型在 8/16 位击败 FLAC,但在 24 位收益缩小,这是有道理的(更高的位深度意味着更少的冗余可利用)。
一个小问题:他们没有报告训练成本或推理速度,这对实际采用很重要。
仅压缩比不能告诉你这是否可部署。
写作功力: 论文清晰且结构良好。
弱点在讨论部分——他们观察到在更高位深度收益递减,但没有深入探讨原因。
这是根本性的(更少的结构可建模)还是偶然的(模型容量、训练数据)?一段带有后续实验的推测会加强贡献。
相关工作部分很全面但可以精简。
判决: 弱接收 — 扎实的实证工作,用实用解决方案(字节级分词)回答了一个开放问题(语言模型能否扩展到专业音频?),但贡献是渐进的而非范式转变。
要点总结
字节级分词技巧直接迁移到任何具有多字节数据的领域:高分辨率图像、科学传感器数据、基因组序列。
如果你在样本级分词中遇到词汇表爆炸,将样本分解为字节并顺序预测。
权衡总是相同的:更小的词汇表,更多的预测步骤,但可处理的训练。
在更高位深度的收益递减是一个有用的负面结果。
它表明神经压缩的优势来自对高阶位(携带大部分信号)中结构的建模,而不是从低阶位(几乎是随机的)中挤出最后一点熵。
如果你在为高精度数据开发压缩,将模型容量集中在结构化部分。
基准测试本身是有价值的基础设施。
他们在多个采样率和位深度下测试了音乐、语音和生物声学。
如果你正在开发新的压缩方法,这为你提供了一个标准化的评估协议来进行比较。