Paper: 2608.06312 Authors: Tao Wang, Qihao Yang, Rongjiao Liang, Lianghong Lin, Haitao Wang, Xinyu Cao, Tianyong Hao Categories: cs.CL
The Gap
Almost every “can LLMs do professional work?” benchmark asks the model to know something: legal QA (LegalBench, LexGLUE), medical exams (MedQA, MMLU subsets), financial reasoning (FinBen). The task shape is always the same — question in, answer out, graded against a key. A second family tests long-context retrieval: needle-in-a-haystack, summarization, “find the clause about X.”
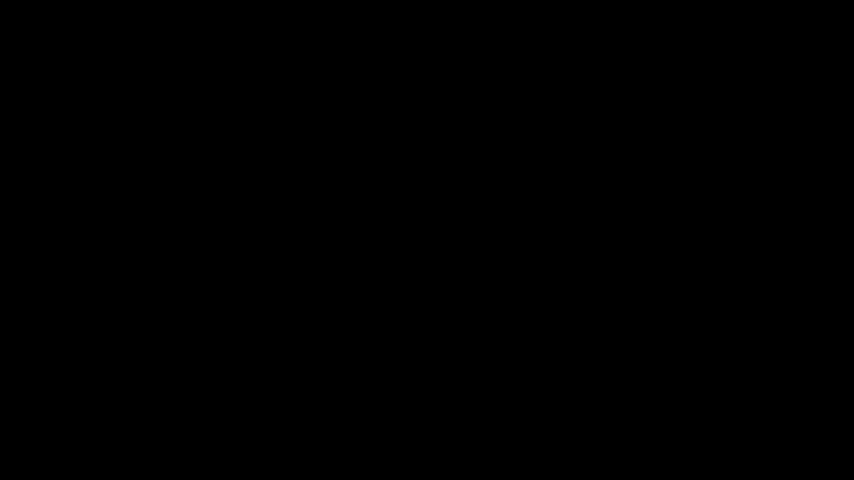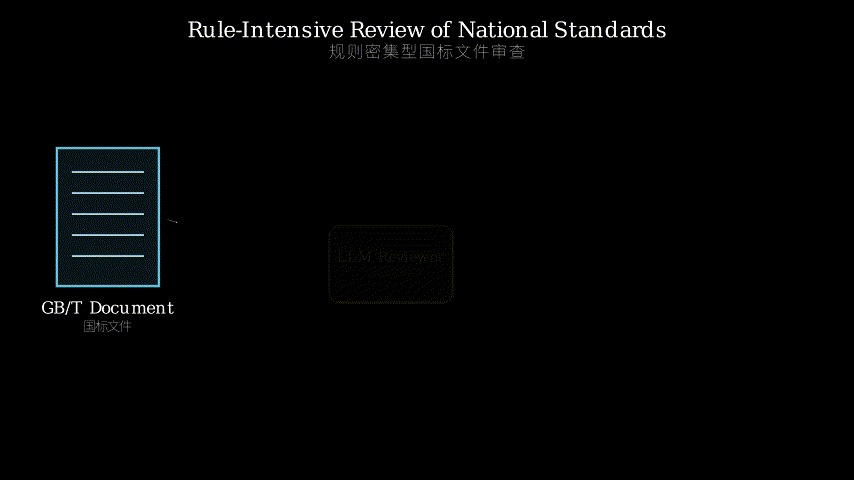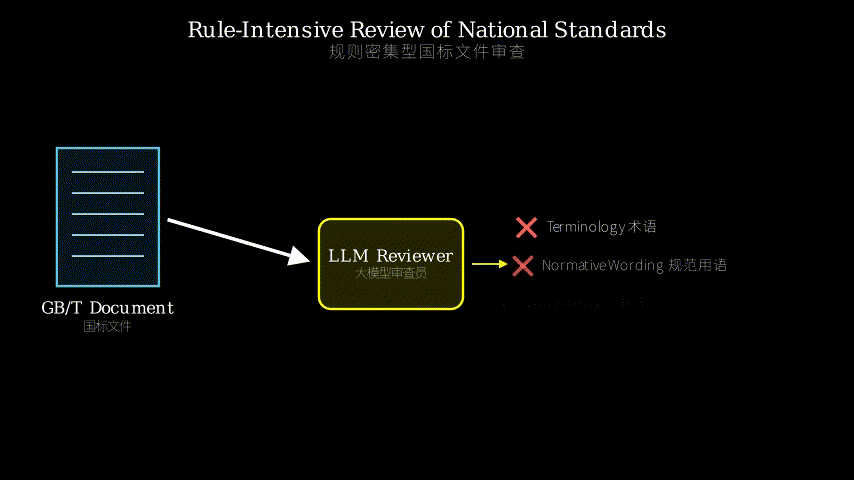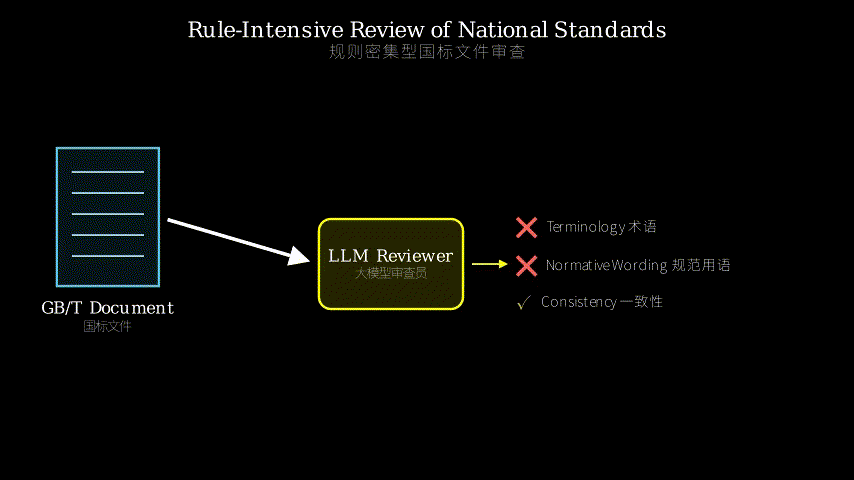
Neither shape covers what a standards body actually pays humans to do. A GB/T reviewer doesn’t answer questions about a document; they audit the document against itself and against a rulebook. Does the scope clause match what the body of the text actually covers? Is “shall” used where a requirement is meant and “should” where a recommendation is? Is the same term defined once and used consistently across forty pages? Do the normative references exist and are they cited correctly? This is intrinsic quality review, and it has no answer key — the “answer” is a list of defects with locations.
So the gap is concrete: no dataset, no taxonomy, and no metric for document review as a task. Which means the field has no idea whether current models are at 10% or 90% of expert performance, and no way to measure progress. The paper’s move is to manufacture ground truth by breaking documents on purpose.
[Problem]  rule-intensive review is expert-only, costly, unscalable
     |
     v
[Gap]      benchmarks test domain QA and retrieval,
           not intrinsic quality review (no labels exist)
     |
     v
[Assumption] review skill == (locate) + (name dimension) + (name type)
             over a finite, enumerable error space
     |
     v
[Method]   1. taxonomy: 5 dimensions / 25 error types
           2. seed errors into 488 clean docs -> 7306 instances
           3. metric: exact triple match + doc-level coverage
           4. GB/T-Reviewer: 4 coordinated agents
     |
     v
[Evidence] 14 LLMs, best CMCS = 0.3280 ; human experts = 0.6640
           GB/T-Reviewer lifts best to 0.5094
     |
     v
[Conclusion] monolithic prompting is not the bottleneck-free path;
             structured skill decomposition buys ~+0.18 CMCS,
             and a human gap of ~0.15 remains
The Increment
One sentence: Before, “can a model review a standard?” was an anecdote you argued about; after, it’s a number with a known human ceiling, plus a recipe showing that decomposing review into named skills beats asking one model to eyeball the whole thing.
Core Mechanism
There are two machines here, and it’s worth keeping them separate. The first is a label factory. Start with 488 published GB/T standards, which are presumed clean. Then apply a controllable counterexample generator: deterministic rules handle the mechanical mutations (swap a normative verb, break a clause numbering sequence, drop a reference from the reference list, misalign a heading level), while constrained LLM rewriting handles the semantic ones (paraphrase a defined term inconsistently in one section, widen the scope statement so it no longer matches the body). The critical design choice is that every mutation writes a receipt: which span was touched, which review dimension it violates, which of the 25 error types it instantiates. 488 documents become 7,306 instances whose ground truth is exact by construction, not by annotation.
The second machine is the evaluation protocol, and it’s stricter than it first looks. A model gets credit only when it nails the full triple — location, dimension, type. Saying “there’s a terminology problem somewhere in section 4” earns nothing. On top of instance-level scoring sits document-level coverage: did you find all the seeded defects in this document, or just the easy one? This is what makes the reported numbers so low; a looser fuzzy-match metric would have inflated everything.
The third piece, GB/T-Reviewer, is the response. Instead of one prompt over a 40-page document, review knowledge is compiled into four specialized roles that pass structured state to each other. Global inspection builds a structural map and flags suspicious regions. Targeted diagnosis zooms into each region and commits to a dimension and error type. Rule scanning runs deterministic sweeps that don’t need judgment at all — enumerate every modal verb, build the term-usage table, diff the reference list against citations. Verification is the skeptic: it drops claims the evidence doesn’t support and merges duplicates. The last stage matters more than it sounds, because under exact-match scoring, a confident wrong triple is pure cost.
   PART A -- LABEL FACTORY
   488 clean GB/T documents
        |
        v
   +--------------------------------------+
   | counterexample generator             |
   |  (a) deterministic rules             | shall <-> should, renumber,
   |  (b) constrained LLM rewriting       | drop ref, drift a term,
   +--------------------------------------+ widen scope
        |
        |  each edit emits a receipt:
        |  ( span , dimension , error_type )
        v
   7306 traceable error instances
        |
        v
   +--------------------------------------+
   | scoring: exact triple match          |
   |          + document-level coverage   |
   +--------------------------------------+


   PART B -- GB/T-Reviewer
   document in
        |
        v
   [ global inspection ]  ..... structure map, suspect regions
        |
        v
   [ targeted diagnosis ]  .... commit ( span, dim, type )
        |            ^
        v            |
   [ rule scanning ]  ........ modal-verb sweep, term table,
        |                       reference diff  (no judgment)
        v
   [ verification ]  ......... drop unsupported, dedupe, rank
        |
        v
   report = list of ( location , dimension , error_type )
The load-bearing metaphor: this is mutation testing, applied to prose. In software, you can’t directly measure how good a test suite is, so you deliberately inject bugs into working code — flip a < to a <=, delete a return statement — and count how many your suite catches. The mutation score *is the test suite’s grade.
Map it piece by piece. The 488 clean standards are the passing codebase. The deterministic rules and constrained rewrites are the mutation operators, and the taxonomy of 25 error types is the operator catalogue. The receipts are the mutant registry — you know exactly which line you broke and how. The LLM under evaluation is the test suite. CMCS is the mutation score. And the exact-triple requirement is the difference between a test that merely goes red and a test that tells you which assertion failed and why — the whole point of review is actionable output, so a test that just screams “something’s wrong” is nearly worthless.
The metaphor also predicts the paper’s main weakness, which is the same one mutation testing has always had: your score measures survival against your operators. If human standard drafters make mistakes that no operator in your catalogue produces, a perfect score means little. Mutation testers call these equivalent mutants and unrepresentative faults; here you’d call it distribution shift between seeded and naturally occurring errors.
For GB/T-Reviewer, extend the analogy one step: it’s not a smarter test suite, it’s a proper CI pipeline. The linter (rule scanning) catches the mechanical stuff cheaply, the human-style reviewer (targeted diagnosis) handles judgment calls, the architecture check (global inspection) runs first to decide where to look, and the approver (verification) refuses to merge findings that lack evidence.
Key Concepts
-
Normative modality: In standards writing, the auxiliary verbs are load-bearing law, not style. “Shall” means a requirement you must meet to claim conformance. “Should” is a recommendation. “May” is permission. “Can” is a statement of possibility. Swap one and the legal meaning of the document changes: “the enclosure shall be grounded” is a testable obligation; “the enclosure should be grounded” is advice a manufacturer can ignore while still claiming compliance. This is why the taxonomy treats modality as its own review dimension — it’s a class of error that is invisible to fluency-based judgment (both sentences read perfectly) and catastrophic in effect. It’s also the easiest dimension for a rule scanner and a genuinely hard one for a semantic reasoner, because deciding whether *this clause should be a requirement or a recommendation needs the document’s intent.
-
Diagnosis-oriented exact match: Most generation benchmarks reward partial credit through overlap metrics — ROUGE, embedding similarity, LLM-as-judge on a 1-5 scale. This paper refuses. You must return the right span, the right dimension, and the right type, or you score zero on that instance. The reasoning is operational: a review report that says “possible inconsistency in Chapter 3” doesn’t save an expert any time, because they still have to read Chapter 3. Only a report that says “term ‘nominal load’ is defined in 3.2 but used with a different meaning in 5.4.1 — terminology consistency, type T-07” is a labor saving. Concretely, this is why the ceiling is 0.6640 for humans rather than 0.95: even experts disagree about which of 25 labels a given defect belongs to.
-
Controllable counterexample generation: The trick that makes the whole benchmark possible. Getting humans to annotate defects in real draft standards is expensive and produces low agreement. So instead: take documents that are already correct, and run a generator that introduces exactly one known defect at a time. “Controllable” means the generator picks the dimension and type in advance and constrains the LLM’s rewrite so it can’t accidentally introduce a second, unlabelled error or fix the first one. You’ve traded annotation cost for a distributional assumption — cheap, scalable, and only as good as your operator design.
Framework Shift
   Before (mainstream)                 After (this paper)
   ===================                 ==================

   +---------------------+             clean docs
   |  40-page document   |                  |
   +---------------------+                  v
             |                        [ mutate w/ receipts ]
             v                               |
     "review this / answer                   v
      this question"                  labeled defect set
             |                               |
             v                    +----------+-----------+
      one model, one pass         |                      |
             |                    v                      v
             v              [ global ]--> [ diagnose ] <--+
      free-form prose             |             ^         |
             |                    v             |         |
             v              [ rule scan ] -----+   [ verify ]
      graded by similarity        |                      |
      or QA accuracy              +----------+-----------+
                                             |
                                             v
                                  ( loc , dim , type ) triples
                                             |
                                             v
                                  exact match vs receipts
From asking a model what it knows about a domain to auditing whether a model can find planted defects and name them precisely, the core shift is treating professional review as a diagnosis task with a mutation-tested ground truth, rather than a generation task judged by resemblance.
Framework Shift, in one line
Benchmarks stopped asking “does the model know the rules?” and started asking “can the model apply the rules to a specific line and say which rule broke?”
Expert Assessment
A caveat before I start: I’m working primarily from the abstract-level claims here, so my read on experimental details is provisional. The concerns below are the ones I’d raise in review and would want the paper to answer.
Problem choice: Real gap, well chosen, slightly unglamorous — which is usually a good sign. The QA-benchmark genre is saturated and everyone knows it doesn’t predict deployment value. Intrinsic document review is exactly the kind of task where LLMs are being sold aggressively and evaluated barely, and standards documents are a smart testbed precisely because the rules are written down and largely mechanical, so ground truth is arguable-but-not-hopeless. The choice also sits well in the field’s trajectory: as models get long-context-capable, the interesting question shifts from “can you retrieve from 40 pages” to “can you cross-check 40 pages against a rulebook.” My one reservation is scope: GB/T-specific taxonomies won’t transfer verbatim, and the paper’s framing as a template for “other high-stakes document domains” is an aspiration, not a demonstration.
Method maturity: The benchmark construction is the clever part; the framework is the conventional part. Seeded-defect generation with receipts is a genuinely good answer to the annotation problem, and separating deterministic mutations from constrained LLM rewrites is the right factorization — you get mechanical errors for free and spend model calls only where semantics are needed. GB/T-Reviewer, by contrast, is a fairly standard four-role agent pipeline; the specific insight is that some review dimensions (modality, references, term usage) are better served by deterministic scanning than by reasoning, which is a small but real point. What’s missing is an obvious simpler baseline: dimension-by-dimension prompting with the same rule checklists, no multi-agent orchestration, matched token budget. I’d bet that recovers a large share of the 0.328 to 0.509 gain, and the paper’s claim about “structured skill coordination” would look weaker.
Experimental integrity: Fourteen models and a human reference is respectable, and reporting a human ceiling of 0.6640 rather than assuming 1.0 shows honesty — but that number is also the most interesting problem in the paper. If experts only score 0.66 on defects that were mechanically seeded and thus have unambiguous ground truth by construction, then either the taxonomy’s 25 types are not cleanly separable, or the exact-match protocol is punishing legitimate alternative labelings, or the seeded errors don’t look like the errors experts are trained to hunt. All three are worth knowing about, and the answer changes how you read every other number. Two more flags. First, contamination cuts in an unusual direction: published GB/T standards are plausibly in pretraining data, so a model might detect a seeded defect by diffing against memorized text rather than by applying any rule — the paper needs a held-out set of recent or unpublished standards to rule this out, and if it doesn’t have one, the absolute numbers are suspect even though the human comparison probably survives. Second, GB/T-Reviewer makes many more model calls than a single-pass baseline; without cost-matched comparison (self-consistency, best-of-n, or simply a longer single prompt), part of the improvement is just compute.
Writing quality: The abstract asserts CMCS as if the reader knows it, which is the tell for where the corner was cut — a composite metric that carries every headline claim needs its definition and its sensitivity analysis in the main text, not a table caption. The section I’d rewrite is taxonomy construction and validation. Right now the 25 error types read as given; I want to know where they came from (GB/T 1.1 drafting rules? review checklists from a standards body? inductive coding of real review comments?), what the inter-annotator agreement is on assigning them, and how the coverage of real-world defects was checked. That section is the foundation of the entire contribution, and strengthening it would move the paper from “useful resource” to “the reference benchmark for this task.”
Verdict: weak accept — a genuinely needed benchmark with a smart construction trick and an honest human baseline, held back by synthetic-only evaluation, a possibly compute-explained framework gain, and an unexamined human ceiling that hints at taxonomy noise.
Takeaways
Three things transfer cleanly out of the standards domain:
Mutation testing as a benchmark generator. Whenever you need labeled defects and annotation is expensive, invert the problem: start from known-good artifacts and break them with operators that log what they did. This works for code review, contract review, config auditing, medical record consistency, API documentation, financial filings — anywhere “correct examples” are abundant and “labeled errors” are scarce. The engineering discipline that makes it work is the receipt: every mutation must emit a machine-readable record of location, category, and type, and the generator must be constrained so it introduces exactly one labeled defect and nothing else.
Design your metric around whether it saves the human time. The exact-triple requirement is the most portable idea here. Overlap and similarity metrics let systems score well by being vaguely gesturally correct, which is worthless in a review setting because a vague finding costs the expert the same reading time as no finding at all. Ask: what is the minimum output that lets the downstream human act without re-doing the work? Then score that, exactly, and accept that your numbers will look bad.
Route by determinism, not by difficulty. GB/T-Reviewer’s rule-scanning agent is the quiet lesson. Some checks in any rule-intensive task are pure enumeration — build a table, diff two lists, count occurrences of a closed vocabulary. Those should never touch an LLM’s judgment; they should be code, with the model only handling the residue that needs intent. Before building an agent crew, partition your rulebook into “decidable by script” and “needs reading comprehension,” and you’ll usually find the first bucket is bigger than you assumed.
And one negative takeaway worth internalizing: always report a human ceiling on your own benchmark. This paper’s most valuable single number is 0.6640, because it converts a scary-sounding 0.3280 into “half of expert performance” and quietly warns you that the task’s labels are noisier than the construction method suggests.
论文: 2608.06312 作者: Tao Wang, Qihao Yang, Rongjiao Liang, Lianghong Lin, Haitao Wang, Xinyu Cao, Tianyong Hao 分类: cs.CL
缺口
现在几乎所有”大模型能不能干专业活”的评测,问的都是”你知不知道”:法律问答、医学考试、金融推理,题型永远是”给问题、出答案、对标准答案”。
另一类是长文本检索:大海捞针、摘要、“找出关于 X 的那一条”。
但这两类都没覆盖标准化机构真正花钱雇人做的事。
国标审查员不是回答关于文档的问题,而是拿文档跟它自己、跟一本规则手册对账。
范围条款声明的适用范围,跟正文实际写的内容对得上吗?该写”应”的地方写了”应”,该写”宜”的地方没误用”应”吗?同一个术语是不是只定义了一次、并且在四十页里用法一致?规范性引用文件是否存在、标注是否正确?
这叫内在质量审查,它没有标准答案——它的”答案”是一份带位置的缺陷清单。
所以缺口很具体:没有数据集、没有错误分类体系、没有把”文档审查”当成一个任务来度量的指标。
结果就是整个领域说不清当前模型是专家水平的 10% 还是 90%,也没法衡量进步。
这篇论文的破局方式很直接:故意把好文档改坏,从而人造出真值。
[问题]   规则密集型审查只能靠专家, 成本高, 无法规模化
     |
     v
[缺口]   现有评测测领域问答与检索,
         不测内在质量审查 (根本没有标注)
     |
     v
[假设]   审查能力 == (定位) + (说出维度) + (说出错误类型)
         错误空间是有限可枚举的
     |
     v
[方法]   1. 分类体系: 5 个维度 / 25 种错误类型
         2. 向 488 份干净文档植入错误 -> 7306 个实例
         3. 指标: 三元组精确匹配 + 文档级覆盖率
         4. GB/T-Reviewer: 4 个协同智能体
     |
     v
[证据]   14 个模型, 最好 CMCS = 0.3280 ; 人类专家 = 0.6640
         GB/T-Reviewer 把最好成绩提到 0.5094
     |
     v
[结论]   单体提示不是通路;
         技能分解带来约 +0.18 CMCS,
         但离人类仍差约 0.15
增量
一句话:以前”模型能不能审国标”是一场靠轶事互相说服的争论,现在它是一个带已知人类上限的数字,外加一份配方——把审查拆成有名字的技能,胜过让一个模型盯着整篇文档硬看。
核心机制
这里其实有两台机器,必须分开看。
第一台是标注工厂。
起点是 488 份已发布的 GB/T 标准,假定它们是干净的。
然后跑一个可控反例生成器:确定性规则负责机械型改动(互换规范性助动词、打乱条款编号、从引用列表里删掉一条、把标题层级弄错),受约束的大模型重写负责语义型改动(在某一节里把已定义术语换成不一致的表述、把范围声明放宽到与正文脱节)。
最关键的设计是:每一次改动都会留下一张”收据”——动了哪个片段、违反了哪个审查维度、属于 25 种错误类型里的哪一种。
488 份文档变成 7306 个实例,其真值是”构造出来的精确”,而不是”标注出来的近似”。
第二台是评测协议,比初看更严格。
模型只有把整个三元组都说对——位置、维度、类型——才算得分。
“第 4 章某处可能有术语问题”这种回答,零分。
在实例级评分之上还有文档级覆盖率:这篇文档里植入的缺陷你是全找出来了,还是只挑了最容易的那个?
这就是报告数字如此之低的原因;换成模糊匹配指标,所有数值都会被吹高一大截。
第三块是GB/T-Reviewer,也就是应对方案。
它不再对四十页文档下一个提示,而是把审查知识编译成四个互相传递结构化状态的专职角色。
全局巡检先建结构图、标出可疑区域;靶向诊断钻进每个区域,落定维度和错误类型;规则扫描跑那些完全不需要判断力的确定性遍历——枚举全部模态动词、建术语使用表、把引用列表和正文标注做差集;结果校验是那个唱反调的角色,它删掉证据不足的判断、合并重复项。
最后一步比听起来重要得多,因为在精确匹配的评分下,一个自信但错误的三元组是纯粹的负担。
   第一部分 -- 标注工厂
   488 份干净国标文档
        |
        v
   +--------------------------------------+
   | 反例生成器                            |
   |  (a) 确定性规则                       | 应 <-> 宜, 重编号,
   |  (b) 受约束的大模型重写                | 删引用, 术语漂移,
   +--------------------------------------+ 范围放宽
        |
        |  每次改动生成一张收据:
        |  ( 片段 , 维度 , 错误类型 )
        v
   7306 个可追溯错误实例
        |
        v
   +--------------------------------------+
   | 评分: 三元组精确匹配                   |
   |       + 文档级覆盖率                   |
   +--------------------------------------+


   第二部分 -- GB/T-Reviewer
   文档输入
        |
        v
   [ 全局巡检 ]  ..... 结构图, 可疑区域
        |
        v
   [ 靶向诊断 ]  ..... 落定 ( 片段, 维度, 类型 )
        |            ^
        v            |
   [ 规则扫描 ]  ----+  模态动词遍历, 术语表,
        |               引用差集  (无需判断)
        v
   [ 结果校验 ]  ..... 删证据不足, 去重, 排序
        |
        v
   报告 = ( 位置 , 维度 , 错误类型 ) 列表
承重核喻:这是把变异测试搬到了自然语言文本上。
软件工程里,你没法直接度量一套测试的好坏,于是故意往能跑通的代码里注入 bug——把 < 改成 <=、删掉一句 return——再数你的测试抓住了几个。
变异得分就是这套测试的成绩单。
逐个对照:488 份干净标准是那份全绿的代码库;确定性规则和受约束重写是变异算子,25 种错误类型的分类体系就是算子目录;那些”收据”是变异体登记表,你精确知道自己弄坏了哪一行、怎么弄坏的;被评测的大模型是测试套件;CMCS 就是变异得分。
而”必须三元组全对”这条要求,对应的是”测试只是变红”和”测试告诉你哪个断言失败、为什么失败”之间的差别——审查的意义在于输出可执行,一个只会喊”这里有问题”的测试几乎没有价值。
这个核喻还能预测论文的主要弱点,而且正是变异测试自诞生就背着的那个:你的分数衡量的是对抗你自己那套算子的存活率。
如果真实的国标起草人会犯的错误,你的算子目录里根本生成不出来,那满分也说明不了多少。
变异测试圈把这叫等价变异体和不具代表性的故障;在这里你会叫它”植入错误与自然错误之间的分布偏移”。
至于 GB/T-Reviewer,把类比再推一步:它不是一套更聪明的测试,而是一条完整的 CI 流水线。
Linter(规则扫描)廉价地抓机械问题,人类式评审者(靶向诊断)处理需要判断的部分,架构检查(全局巡检)先跑一遍决定该看哪里,而合并审批人(结果校验)拒绝放行缺乏证据的发现。
关键概念
-
规范性助动词(normative modality):在标准写作里,助动词是承重的法律条文,不是文风。“应”表示要求,不满足就不能声称符合标准;“宜”是推荐;“可”是许可;“能”是可能性陈述。改一个字,文档的法律含义就变了:“外壳应接地”是一条可检验的义务,“外壳宜接地”是厂家可以无视却仍宣称合规的建议。这就是为什么分类体系把它单列为一个审查维度——这类错误对”流畅度判断”完全隐形(两句话读起来都毫无问题),后果却极其严重。它同时是规则扫描器最擅长、语义推理最吃力的维度,因为判断”这一条到底该是要求还是推荐”,需要理解整篇文档的意图。
-
面向诊断的精确匹配:大多数生成类评测通过重叠度给部分分——ROUGE、向量相似度、大模型当裁判打 1 到 5 分。这篇论文拒绝这么做。你必须给出正确的片段、正确的维度、正确的类型,否则这个实例零分。理由是纯操作性的:一份写着”第 3 章可能有不一致”的审查报告不省专家任何时间,因为他还是得把第 3 章读一遍。只有”术语’额定负载’在 3.2 定义,但在 5.4.1 以不同含义使用——术语一致性,类型 T-07”这样的报告才算省了人力。具体后果就是:人类上限是 0.6640 而不是 0.95,因为连专家之间也会对”这个缺陷该归到 25 类中的哪一类”产生分歧。
-
可控反例生成:让整个基准成为可能的那个巧招。找专家去真实草案里标缺陷,既贵又一致性低。于是反过来:拿已经正确的文档,用生成器一次只植入一个已知缺陷。“可控”的意思是生成器预先指定维度和类型,并约束大模型的改写,使它不会顺手引入第二个未标注的错误、也不会把第一个错误改回去。你用”分布假设”换掉了”标注成本”——便宜、可扩展,但上限完全取决于算子设计得好不好。
框架转变
   之前 (主流做法)                      之后 (本文做法)
   ===============                      ===============

   +---------------------+             干净文档
   |   四十页文档         |                  |
   +---------------------+                  v
             |                        [ 植入 + 留收据 ]
             v                               |
      "审一下 / 回答这个                       v
       问题"                          带标注的缺陷集
             |                               |
             v                    +----------+-----------+
      一个模型, 一遍过              |                      |
             |                    v                      v
             v              [ 全局 ]--> [ 诊断 ] <--------+
      自由散文式回答               |          ^            |
             |                    v          |            |
             v              [ 规则扫描 ] ----+      [ 校验 ]
      按相似度或问答                |                      |
      正确率打分                    +----------+-----------+
                                             |
                                             v
                                  ( 位置 , 维度 , 类型 ) 三元组
                                             |
                                             v
                                     与收据做精确匹配
一句话:从”考模型对某个领域知道多少”,到”审模型能不能找出被植入的缺陷并精确命名”,核心转变是把专业审查当成一个带变异测试真值的诊断任务,而不是一个用相似度评判的生成任务。
专家评审
先说一句:我主要基于摘要层面的论断来读,所以对实验细节的判断是暂定的。下面提的是我作为评审会追问的问题。
选题眼光:真缺口,选得好,而且略显不性感——通常是好兆头。
问答类评测早已饱和,所有人都知道它预测不了落地价值。
内在文档审查恰恰是那种”大模型被猛烈推销、却几乎没被认真评估”的任务,而标准文档是个聪明的试验场,正因为它的规则是写下来的、大部分是机械的,真值虽有争议但不至于无望。
这个选题也很契合领域趋势:当模型都具备长上下文能力后,有意思的问题就从”你能不能从四十页里检索”变成”你能不能拿四十页跟一本规则手册对账”。
我唯一的保留意见是适用范围:GB/T 特定的分类体系不可能原样迁移,论文把自己框定为”其他高风险文档领域的模板”,那是愿景,不是证明。
方法成熟度:基准构造是巧劲,框架是常规操作。
带收据的植入式缺陷生成,是对标注难题的一个真正好答案;把确定性变异和受约束大模型重写分开,也是正确的分解——机械错误零成本拿到,模型调用只花在需要语义的地方。
相比之下 GB/T-Reviewer 是一套挺标准的四角色智能体流水线;它真正的洞见是”某些审查维度(助动词、引用、术语用法)交给确定性扫描比交给推理更划算”,这一点小但真实。
缺的是一个显而易见的简单基线:按维度逐个提示、附上同样的规则清单、不做多智能体编排、token 预算对齐。
我打赌这能收回 0.328 到 0.509 里的很大一块,那么”结构化技能协同”这个论断就会显得单薄不少。
实验诚意:14 个模型加一条人类参考线是够体面的,报告 0.6640 的人类上限而不是默认 1.0 也显示了诚实——但这个数字同时是全文最有意思的问题。
如果专家在”机械植入、因而按构造就有无歧义真值”的缺陷上也只拿到 0.66,那么要么这 25 个类型并不能干净地互斥,要么精确匹配协议在惩罚合理的替代性标注,要么植入的错误跟专家受训去猎捕的错误长得不一样。
三种可能都值得知道,而答案会改变你对其余每个数字的读法。
还有两点警惕。
第一,数据污染在这里的作用方向很反常:已发布的国标很可能在预训练数据里,于是模型可能靠”跟记住的原文做 diff”而不是”应用规则”来发现植入缺陷——论文需要一批留出的新近或未公开标准来排除这一点;如果没有,绝对数值就可疑,尽管人机对比大概仍站得住。
第二,GB/T-Reviewer 的模型调用次数远多于单遍基线;没有成本对齐的对比(自一致性、best-of-n,或干脆一个更长的单提示),这部分提升里有一块只是算力。
写作功力:摘要里把 CMCS 当读者已知的东西直接抛出来,这就是偷懒的痕迹——一个承载全部头条结论的复合指标,它的定义和敏感性分析该在正文里,而不是藏在表格脚注里。
我最想重写的是分类体系的构建与验证那一节。
现在这 25 种错误类型是”天降”的;我想知道它们从哪来(GB/T 1.1 起草规则?标准化机构的审查清单?对真实审查意见做归纳编码?),指派类型时的标注者一致性是多少,以及对真实世界缺陷的覆盖度是怎么核验的。
这一节是整个贡献的地基,把它做扎实,论文就能从”有用的资源”升级为”这个任务的参考基准”。
判决:弱接收 —— 一个真正需要的基准,构造思路巧妙,人类基线报告诚实;但纯合成评测、可能由算力解释的框架增益、以及一个未被追问的人类上限(它暗示分类体系比构造方法所显示的更嘈杂),拖住了它的分量。
要点总结
有三样东西能干净地从标准化领域搬走:
把变异测试当基准生成器。
任何时候你需要带标注的缺陷、而标注又很贵,就把问题反过来:从已知正确的产物出发,用会记录自身行为的算子把它弄坏。
这套路适用于代码审查、合同审查、配置审计、病历一致性、API 文档、财报——凡是”正确样本充足、错误标注稀缺”的场合都行。
让它真正跑起来的工程纪律是那张收据:每次变异必须输出机器可读的位置、类别、类型记录,而生成器必须被约束到”只引入一个被标注的缺陷,别的什么都不引入”。
围绕”是否真的省了人力”来设计指标。
三元组精确匹配是这里最可迁移的想法。
重叠度和相似度指标允许系统靠”大致方向对”拿高分,而这在审查场景里毫无价值,因为一个含糊的发现让专家付出的阅读时间和没有发现是一样的。
该问的是:让下游的人能直接行动、不必重做一遍工作,最小输出是什么?
然后精确地度量那个东西,并接受你的数字会很难看。
按”是否确定性”来路由,而不是按难度。
GB/T-Reviewer 的规则扫描智能体是那个安静的教训。
任何规则密集型任务里,总有一部分检查是纯枚举——建一张表、对两个列表做差集、统计一个封闭词表的出现次数。
这些永远不该碰大模型的判断力,它们该是代码,模型只处理真正需要理解意图的残余部分。
在搭智能体班子之前,先把你的规则手册切成”脚本可判定”和”需要阅读理解”两堆,你通常会发现前一堆比你以为的大。
还有一个值得内化的反向要点:永远在自己的基准上报告人类上限。
这篇论文最有价值的单个数字是 0.6640,因为它把听起来很吓人的 0.3280 换算成了”专家水平的一半”,同时悄悄提醒你:这个任务的标注比它的构造方式所暗示的更嘈杂。