Paper: 2604.02322
Authors: Bangji Yang, Hongbo Ma, Jiajun Fan, Ge Liu
Categories: cs.LG, cs.AI, cs.CL
The Gap
Reasoning LLMs got good partly by learning to “show their work,” but that created a cost problem: chain-of-thought often sprawls far beyond what is needed for correctness. The field has already tried three broad ways to fix this.
First, explicit length penalties: directly reward short outputs or penalize extra tokens. The issue is that this changes the optimization target in an adversarial way. The model can learn to stop early, omit key steps, or game the reward rather than genuinely becoming concise. The paper claims these setups are unstable and can even collapse.
Second, difficulty estimation / routing: try to predict whether a problem needs long reasoning and allocate compute accordingly. This can work, but it requires extra components, calibration, and often a brittle decision boundary. You now have a controller problem on top of the reasoning problem.
Third, multi-stage or curriculum pipelines: train in several phases, often starting with ordinary reasoning and later compressing or refining it. These systems can be effective, but they are operationally messy. More stages mean more knobs, more failure modes, and less clarity about what actually caused the gain.
So the gap is pretty precise: is there a single-stage, structurally simple way to induce shorter reasoning without explicitly supervising length and without paying the engineering tax of routing or curricula?
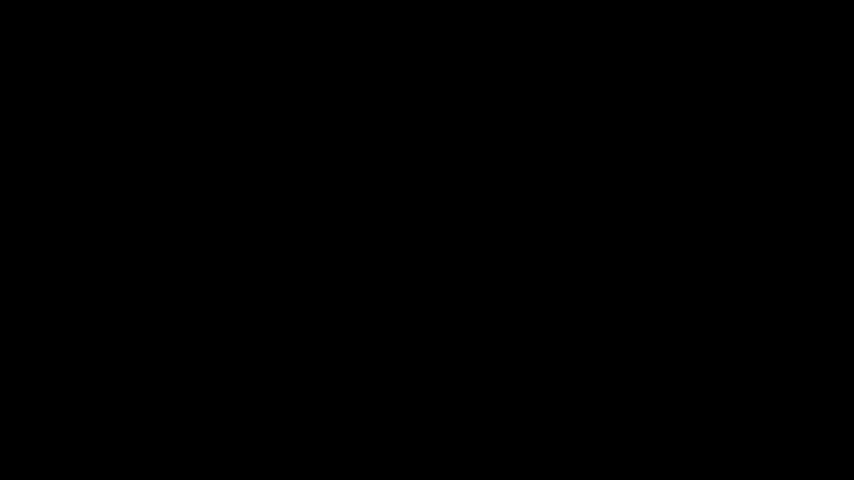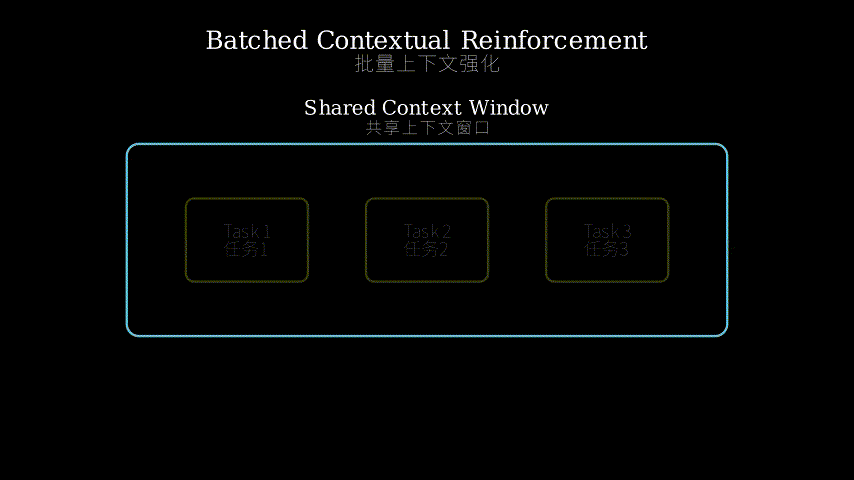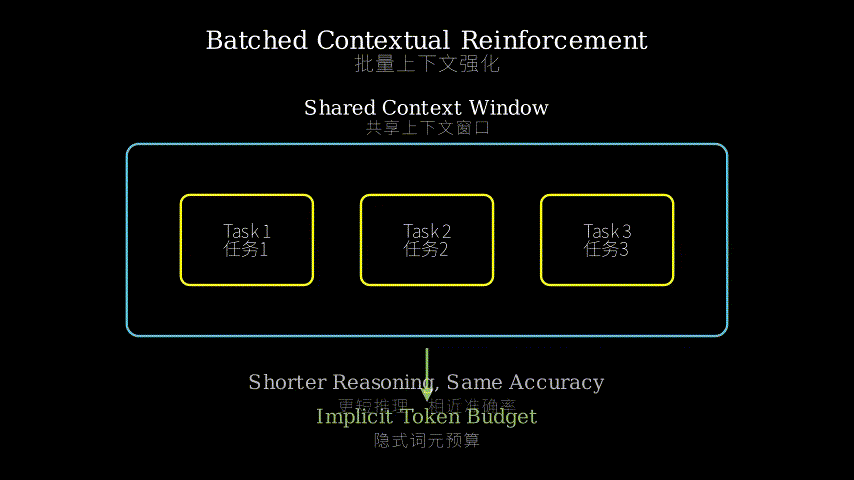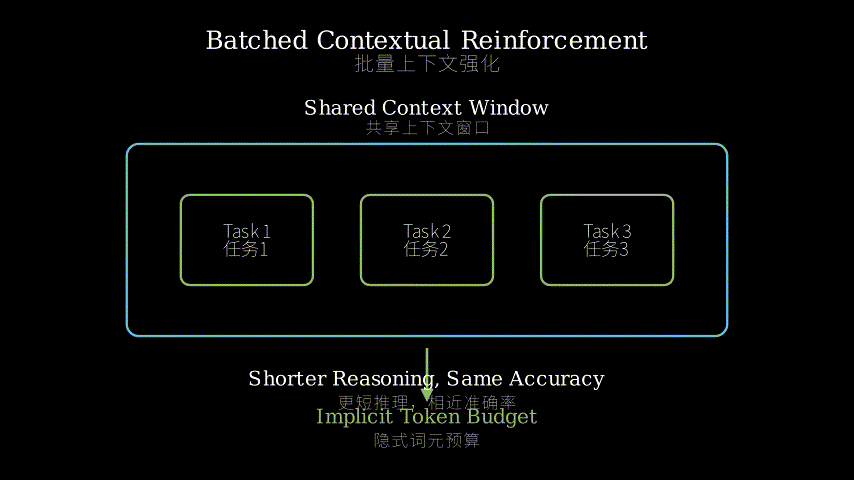
This paper’s answer is yes: instead of telling the model “be shorter,” put multiple problems into one shared context window during training and reward only per-problem correctness. That creates an implicit budget because every extra token spent on one problem eats room available for the others. The claimed novelty is that this simple structural pressure is enough to produce shorter reasoning, preserve accuracy surprisingly well, and avoid the optimization pathologies of direct length penalties.
[Problem]
[CoT is accurate but token heavy]
            |
            v
[Assumption]
[If tasks share one context window then
 extra tokens on one task reduce space for others]
            |
            v
[Method]
[Train on N problems at once
 reward only per problem accuracy
 no explicit length penalty]
            |
            v
[Evidence]
[Token use drops as N rises
 accuracy falls slowly
 single task inference is also shorter
 explicit penalties are less stable]
            |
            v
[Conclusion]
[Implicit structural budget can replace
 explicit token punishment for efficient reasoning]
The Increment
One sentence: Before this paper, efficient reasoning mostly meant explicitly telling models to talk less; after this paper, it looks plausible that you can get shorter reasoning by changing the *task geometry rather than the reward formula.
Core Mechanism
The mechanism is almost annoyingly simple. During training, the model does not receive one problem in one context. It receives N problems packed into the same context window. It is then asked to solve all of them, and the reward is based on whether each individual answer is correct, not on how many tokens were used. There is no explicit brevity reward, no handcrafted compression target, and no auxiliary difficulty predictor.
What changes is the optimization environment. In a standard single-problem setup, the model can afford to wander: verbose self-talk, repeated verification loops, and unnecessary restatement all cost tokens but not necessarily reward. In BCR, those wasted tokens now have an opportunity cost. If the model spends too much room on problem 1, it leaves less room for problems 2 through N. So the context window itself becomes a shared resource. Concision emerges because verbose reasoning is no longer locally harmless; it hurts neighboring tasks.
At inference time, the same structure gives you a new control knob: N, the number of concurrent problems. As N increases, the effective per-problem token budget tightens. The paper’s main empirical claim is a task-scaling law: larger N leads to monotonic token reduction per problem, while accuracy drops more gracefully than baseline methods. More interestingly, even when you go back to ordinary single-problem inference, the trained model often remains shorter and sometimes more accurate. That is the “free lunch” result the authors emphasize.
[Batch of N problems]
[P1] [P2] [P3] ... [PN]
   \   |   /       /
    \  |  /       /
     v v v       v
 [Shared context window]
            |
            v
 [One model rollout over packed tasks]
            |
            v
 [Per task answers]
[A1] [A2] [A3] ... [AN]
            |
            v
 [Reward = accuracy of each task]
            |
            v
 [Gradient pressure]
[Reduce useless tokens because
 every token competes with other tasks]
A good structural metaphor here is a group of students taking an oral exam in one shared time slot.
In the old setup, each student gets a private 10-minute slot. If one student rambles, that’s mostly their own problem. In BCR, several students share the same 10 minutes. The examiner only cares whether each student gives the right answer. Nobody explicitly says “speak briefly,” but the moment one student starts looping, they steal time from everyone else. Over repeated exams, the students learn a new behavior: cut the filler, say the decisive steps, and stop. The important part of the metaphor is that the pressure comes from shared capacity, not from a direct rule about brevity.
Map it back to the method:
- shared exam slot = shared context window
- students = concurrent problems
- right final answer = per-instance accuracy reward
- less rambling = shorter reasoning traces
- choosing how many students share the slot = inference-time control via N
That metaphor is load-bearing because it explains both why concision emerges and why it may be more stable than explicit length penalties. If the teacher instead docked points for every extra word, students might answer in cryptic fragments and miss crucial content. But when the constraint is shared time, they still need to be correct; they just become selective about what to say.
Key Concepts
-
Implicit token budget:
Imagine you have a fixed-size backpack and need to pack lunch for one person versus four people. Nobody tells you “each sandwich must be exactly this small.” But once four people share the same backpack, oversized packing becomes impossible. That is what this paper does with context length. The model is not directly punished for long reasoning; it simply experiences a setup where verbosity has a real cost because space is shared. -
Task-scaling law:
We usually hear about scaling laws in terms of model size, data, or compute. Here the scaling variable is different: how many problems are solved in parallel inside one context. The paper claims a regular pattern: as N goes up, tokens per problem go down in a predictable direction, while accuracy declines more gently than expected. Think of it as a throughput dial. You can trade a bit of quality for a lot of efficiency, and the curve looks better than naive baselines. -
Adversarial gradients from explicit penalties:
Suppose you reward a student for being short, not for being clear. They may learn tricks: skip justification, compress too aggressively, or terminate early. In optimization terms, the reward starts pushing against the reasoning process itself. That is what the authors mean by adversarial gradients. The gradient says “fewer tokens,” while the task still needs enough tokens to stay correct. BCR tries to avoid that conflict by keeping the reward aligned with correctness and letting the structure create the pressure indirectly.
Framework Shift
Before (mainstream approach):        After (this paper):

[One task]                          [Task1] [Task2] [Task3]
    |                                  \      |      /
    v                                   \     |     /
[Model reasons long]                     v    v    v
    |                              [Shared context window]
    v                                       |
[Add penalty or controller]                 v
    |                                [Model allocates reasoning
    v                                 across tasks under one budget]
[Try to recover accuracy]                  |
                                           v
                                     [Shorter per task reasoning
                                      from shared constraint]
From reward-level compression to structure-level resource sharing, the core shift is moving the efficiency pressure out of the objective and into the environment.
Expert Assessment
Problem choice: This is a real gap, not a manufactured one. Token-heavy reasoning is one of the biggest practical annoyances in current LLM deployment, and a lot of prior solutions really do feel like patching around the problem with extra knobs. The paper sits in a meaningful place in the field: after “reasoning works” but before “reasoning is cheap enough.”
Method maturity: The central idea is clever, and in a good way: small conceptual move, large behavioral consequence. It is not brute force. That said, it is also narrow. The whole story depends on tasks that can be packed and rewarded independently inside one context. I would want to know how robust this is beyond math-style benchmarks, where correctness is clean and multiple tasks can be serialized without too much interference. So: elegant insight, but not yet a universal recipe.
Experimental integrity: The headline numbers are interesting: 15.8 percent to 62.6 percent token reduction while maintaining or improving accuracy on five math benchmarks is nontrivial. The comparison to explicit length penalties is also a useful baseline because that is exactly the method class they are arguing against. My mild concern is whether the benchmark set is too concentrated in domains where concise latent solutions already exist and can be safely surfaced. Another concern is packing effects: depending on formatting and ordering, batched contexts may induce behaviors unrelated to “efficiency learning” per se. I would also want stronger ablations on the role of prompt layout, answer separators, and cross-task contamination.
Writing quality: The paper seems strongest when stating the empirical phenomenon and weakest when pinning down the mechanism. “Implicit budget” is intuitive, but the causal account could be tighter. If I could ask for one rewritten section, it would be the analysis section: I would want a more surgical decomposition of *which kinds of tokens disappear. Are they removing repetition, verification loops, hedging, scratch work, or syntax overhead? That would elevate the paper from neat result to more durable scientific contribution.
Verdict: weak accept — The idea is simple, fresh, and practically relevant, with solid enough evidence to matter, but the mechanism and generality still need sharper validation.
Takeaways
A practitioner can steal several concrete things here:
-
Use shared-capacity training to induce efficiency indirectly.
If direct penalties destabilize optimization, try creating a setup where examples compete for a fixed resource. This idea could transfer beyond reasoning length to memory slots, tool calls, retrieval budget, or number of planner steps. -
Treat concurrency as a control knob, not just a systems detail.
Usually batching is for hardware efficiency. This paper reframes batching as a behavioral variable that shapes model policy. That is a useful lens. -
When you want compression, change the game before changing the reward.
Reward hacks often get gamed. Structural constraints are sometimes cleaner because they preserve the original success criterion. -
Measure what kinds of verbosity your model emits.
The paper suggests there is latent high-density reasoning already inside these models. In practice, you might audit outputs for repeated self-checks, restatements, and ritual phrases before reaching for more complicated distillation methods. -
Single-stage training matters operationally.
Even if the gains were only moderate, avoiding a multi-stage compression pipeline is a real engineering win.
论文: 2604.02322
作者: Bangji Yang, Hongbo Ma, Jiajun Fan, Ge Liu
分类: cs.LG, cs.AI, cs.CL
缺口
这篇论文盯的是一个非常现实、而且已经开始变成部署瓶颈的问题:推理模型会做题了,但它们太爱“边想边写”了。
Chain-of-Thought 把准确率拉上去了,也把 token 成本一起拉爆了。
尤其在数学、多步推理、复杂问答里,真正有信息量的步骤可能只占一部分,剩下的是重复确认、格式性铺垫、元认知自言自语。
现有工作大概走了三条路。
第一条是显式长度惩罚:直接奖励短输出,或者惩罚长输出。
问题是,这会把“说短一点”和“答对题”变成拉扯关系。
模型最容易学会的,不一定是更高密度地推理,而可能是少说、早停、跳步,甚至学会投机地绕过惩罚。
作者把这类现象概括为优化不稳定、梯度对抗,严重时会塌。
第二条是难度估计或路由。
先判断这题值不值得长推理,再决定给多少计算预算。
这听上去合理,但系统一下就复杂了:你得先做一个靠谱的“预算分配器”,还得校准它,防止错把难题当简单题。
等于在原问题上又套了一个控制问题。
第三条是多阶段训练或课程式压缩。
先学会推理,再慢慢把推理压短,或者加蒸馏、重写、筛选。
这类方法未必没用,但工程账很重。
阶段一多,变量就多,最后很难说清楚到底是哪一步真起作用。
所以这篇论文填的缺口很明确:
有没有一种单阶段、结构上很简单的方法,不直接监督“要短”,也不引入复杂管线,却能逼出更省 token 的推理?
作者给出的答案是:有。
做法不是改 reward 公式,而是改训练场景。
把 N 道题一起塞进同一个上下文窗口 里做,只按每道题答没答对来奖励。
这样一来,一个题多写一个废 token,就会挤占其他题的空间。
长度控制不是被写进 loss,而是被“共享资源”这个结构自动带出来。
论文的核心主张是:这种隐式预算约束既更稳,也能真的把推理变短,而且准确率掉得比基线温和得多。
[问题]
[CoT 很准 但 token 太贵]
            |
            v
[假设]
[多个任务共享同一上下文时
 一个任务多写就会挤占别的任务]
            |
            v
[方法]
[训练时一次放入 N 道题
 奖励只看各题是否答对
 不显式惩罚长度]
            |
            v
[证据]
[N 增大时 单题 token 单调下降
 准确率下降较缓
 回到单题推理也更短
 显式长度惩罚更不稳定]
            |
            v
[结论]
[共享上下文形成的隐式预算
 可以替代显式长度惩罚来做高效推理]
增量
一句话: 这篇论文之前,大家主要在“奖励函数里压长度”;这篇论文之后,一个更有意思的方向出现了:通过改变任务结构本身,让模型自己学会少说废话。
核心机制
这套方法的妙处在于,它几乎没有花活。
训练时,模型不再面对“一道题对应一个上下文”的标准场景,而是面对 N 道题共用一个上下文窗口 的场景。
模型需要把这些题都做出来。
奖励也很直接:每道题对了就加分,错了就不给分。
这里没有专门的“长度奖励”、没有“压缩老师”、也没有额外的难度预测模块。
真正改变的是优化环境。
在单题训练里,模型的冗长往往是“无害的”。
它多写一点自我确认、多绕一圈验证、把同一句话换三种说法,通常不会立刻吃亏。
可在 BCR 里,这些冗余不再免费。
因为上下文是共享的。
题 1 多占一点,题 2 到题 N 就少一点。
于是模型会逐步学会一个更经济的策略:只保留对正确性最有贡献的步骤,把那些“看起来像推理、其实不太增益”的文字删掉。
更有意思的是,作者把这个结构在推理时也变成了一个新旋钮:N。
你可以把更多题一起推。
N 越大,平均到每道题头上的隐式预算越紧。
论文声称观察到一个“任务缩放律”:随着 N 增加,单题 token 使用单调下降,但准确率下降得比常见基线更缓。
而且即便你最后回到普通的单题推理,这种训练出来的模型也常常会自然写得更短,甚至精度还不掉。
这就是作者说的那个有点挑衅意味的“free lunch”。
[输入 N 道题]
[P1] [P2] [P3] ... [PN]
   \   |   /       /
    \  |  /       /
     v v v       v
    [共享上下文窗口]
            |
            v
     [模型在同一窗口内展开推理]
            |
            v
   [输出各题答案与过程]
[A1] [A2] [A3] ... [AN]
            |
            v
   [奖励只看各题是否正确]
            |
            v
 [训练压力自然指向高密度表达
 因为废 token 会挤占别的题]
如果要打一个真正“承重”的比喻,我会用拼车去机场。
以前是每个人单独打一辆车。
你想绕路买咖啡、想跟司机聊两句、想走风景线,成本主要是你自己承担。
BCR 则像四个人拼一辆车赶飞机。
司机只看结果:大家能不能都准时到。
没人明说“你不许废话,不许绕路”,但只要你一个人临时起意去多拐三个弯,其他人就一起受影响。
久而久之,大家自然会形成一种更紧凑的协同行为:只走必要路线,只做关键停靠。
这个比喻和方法是一一对应的。
共享的车程,就是共享的 context window。
拼车的人,就是同时求解的多道题。
是否准时到机场,就是每题是否答对。
绕路和闲聊,就是冗余 token、重复验证、无意义元认知。
拼车人数,就是 N。
N 增大,路线就得更紧。
关键是:这里的效率不是靠“罚你绕路”得到的,而是靠“大家共用一份预算”逼出来的。
这也解释了为什么它可能比显式长度惩罚更稳:因为目标始终还是“把人送到”,不是“少开公里数”。
关键概念
-
隐式预算:
你可以把它想成一个固定大小的饭盒。
一个人带午饭时,装得松松垮垮也无所谓。
四个人共用这个饭盒时,你自然会去掉包装、减少空隙、只放最有营养的东西。
论文做的就是把 token 空间变成这种共享饭盒。
没人直接规定“每题最多说多少”,但结构本身让模型感受到“废话真的会占地方”。 -
任务缩放律:
我们平时说 scaling law,往往说的是模型变大、数据变多、算力增加。
这篇论文把缩放变量换成了 同时处理的任务数 N。
也就是说,影响行为的不只是模型有多大,还有“一次塞给它几件事”。
如果这个规律稳定存在,那 N 就不只是工程上的 batch size,而会变成一种推理风格控制杆:想要更高吞吐,就增大 N;想要更稳的精度,就减小 N。 -
对抗性长度优化:
为什么显式长度惩罚常常不好使?
因为模型学到的最简单策略,可能不是“更有效地思考”,而是“更快地闭嘴”。
这两件事看起来接近,其实完全不是一回事。
前者是压缩信息密度,后者可能只是砍掉必要步骤。
论文的核心贡献之一,就是提供了一个避免这种正面冲突的替代路径:不去奖惩“短”,只去塑造一个让“短但对”更有利的环境。
框架转变
之前(主流方法):                之后(本文方法):

[一道题]                          [题1] [题2] [题3]
    |                                \    |    /
    v                                 \   |   /
[模型先放开推理]                        v  v  v
    |                             [共享上下文窗口]
    v                                     |
[再额外加长度惩罚                           v
 或预算控制器]                       [模型在共享预算下
    |                                自行分配推理篇幅]
    v                                     |
[努力把精度救回来]                         v
                                     [自然形成更短的
                                      单题推理轨迹]
一句话:从直接处罚冗长,转向让冗长自己变得昂贵,核心转变是把效率压力从目标函数移到了任务结构里。
专家评审
选题眼光: 这是个真问题,不是为了发 paper 硬造的。
现在做 reasoning 的人,几乎都被 token 成本折腾过。
特别是数学和复杂代理场景,模型明明会做,但过程长得离谱。
所以“如何不伤精度地把推理压短”绝对在主航道上。
这篇论文的好处是,它没有在已有套路上继续叠模块,而是换了一个看问题的角度。
方法成熟度: 这更像“巧劲”而不是“蛮力”。
改动很小,但诱导出的行为变化挺大。
这是优点。
但也别过度神化。
这招目前最自然适用的是那类可并列打包、可独立判分的任务,数学题尤其合适。
要是换到开放式写作、工具调用、多轮交互、任务间互相依赖的环境,效果能不能保留,我并不确定。
所以现在更像是一个很有潜力的原则,而不是万能配方。
实验诚意: 从摘要看,作者至少打到了几个该打的点:
一是和显式长度惩罚比,这很关键,因为这是最直接的对照组。
二是既报告 token 降幅,也报告准确率,这比只晒一个“更短了”要诚实。
三是有 1.5B 和 4B 两个量级,不是只挑一个甜 spot。
但我还是会保留一点怀疑:
第一,五个 benchmark 都是数学向的话,领域可能偏窄。
第二,多个任务塞同一窗口,会不会带来额外的格式归纳效应,甚至隐含的“互相提醒”现象?
第三,所谓“free lunch”如果成立,最好看更细的 ablation,确认不是 prompt 模板、题目顺序、答案分隔方式在偷偷贡献。
所以我会说,结果有意思,但还没到完全盖棺定论。
写作功力: 这类论文最容易偷懒的地方就是“现象讲得漂亮,机制讲得太虚”。
从摘要看,作者已经把结果讲明白了,但“为什么会这样”还停留在一个很合理、但不够剖开的叙事层。
如果让我指定重写一节,我会选分析部分。
最值得深入的不是再放几张总表,而是把被删掉的 token 类型拆出来:
到底是重复句少了?
自我验证环节少了?
模板化废话少了?
还是中间 scratchpad 被压缩了?
这部分一旦写透,论文的科学价值会明显上一个台阶。
判决: 弱接收 — 视角新、方法简、结果也确实有吸引力,但机制解释和跨域泛化还需要更扎实的验证。
要点总结
如果你是实践者,这篇论文里能“偷”的东西其实不少,而且不只是照抄 BCR 这么简单。
第一,遇到长度或计算预算问题,先想结构约束,再想 reward hacking。
很多时候直接惩罚“多用一点资源”会把训练带偏。
与其在 loss 里写“别太长”,不如设计一个场景,让多占资源本身就会挤压别的目标。
这个思路可以迁移到工具调用次数、检索条数、规划步数、记忆槽位等问题。
第二,把 batch 从系统参数变成行为参数。
我们平时把 batching 当吞吐优化。
这篇论文提醒你:batch 也可以改变策略分配方式。
这是一种挺值钱的视角切换。
第三,想压缩推理,先审计冗余类型。
如果模型的长输出里,大部分是重复确认、格式套话、机械复述,那你也许不需要更复杂的蒸馏链路。
一个共享预算式训练环境,可能就足够把这些“低价值 token”挤掉。
第四,单阶段方法有很高的工程含金量。
很多论文的改进来自一串复杂流程,实验室里能跑,产品里很难落。
如果 BCR 的效果在更多场景复现,那它最大的价值之一,恰恰是实现和维护成本低。
第五,N 可以被理解成新的服务档位。
如果后续工作证明这个 task-scaling law 稳定存在,那在线推理系统可以把 N 当成吞吐和质量之间的新调节杆。
不是只有采样温度、最大长度、路由器阈值这些老旋钮了。
这会很实用。