Paper: <img alt=“2604.03216” src=“https://e1a4c9d0d2f9f737c5e1.ucr.io/-/preview/https://api.urlbox.io/v1/NTYqWgJv5s0qDIxN/jpeg?url=https%3A%2F%2Farxiv.org%2Fabs%2F2604.03216&full_page=true&width=1024&max_height=2048&quality=80” />
Authors: Sean Wu, Fredrik K. Gustafsson, Edward Phillips, Boyan Gao, Anshul Thakur, David A. Clifton
Categories: cs.CL
The Gap
Existing research on LLM “trustworthiness” focuses heavily on calibration metrics like Expected Calibration Error (ECE). While ECE tells us if a model’s 80% confidence actually corresponds to 80% accuracy on average, it fails in high-stakes decision-making. In the real world, we don’t just care about the average; we care about whether the model’s confidence allows us to safely abstain when it’s likely to be wrong.
Prior metrics treat underconfidence (being right but unsure) and overconfidence (being wrong but certain) with similar weight. This paper addresses the limitation that standard evaluations ignore risk preferences—a doctor and a casual chatter have very different “costs” for a confident error.
[ Problem: Overconfident errors kill trust ]
      |
[ Assumption: Real-world utility depends on knowing when to stop ]
      |
[ Method: BAS (Behavioral Alignment Score) via Utility Modeling ]
      |
[ Evidence: Benchmarking frontier LLMs shows ECE hides fatal flaws ]
      |
[ Conclusion: We need asymmetric penalties for overconfident hallucination ]
The Increment
One sentence: Before this paper, we measured if LLMs knew what they knew; after this paper, we can measure if they know enough to be trusted with a “Stop” button.
Core Mechanism
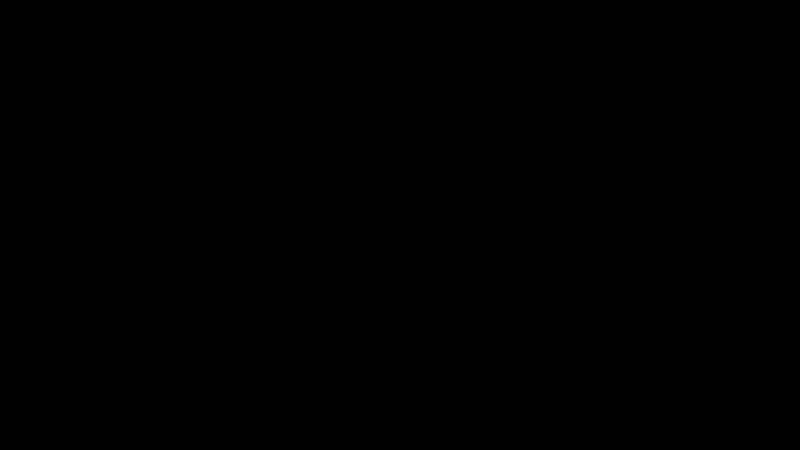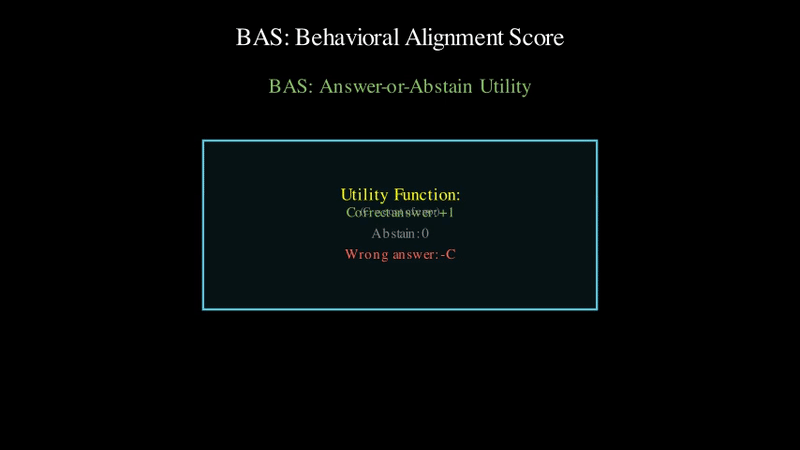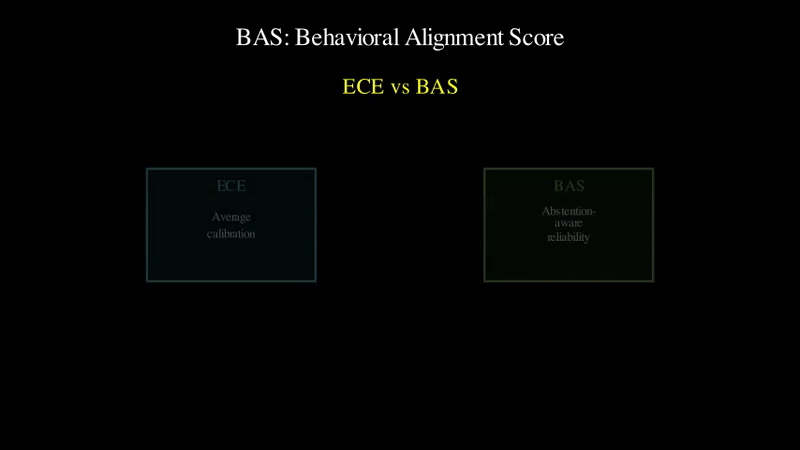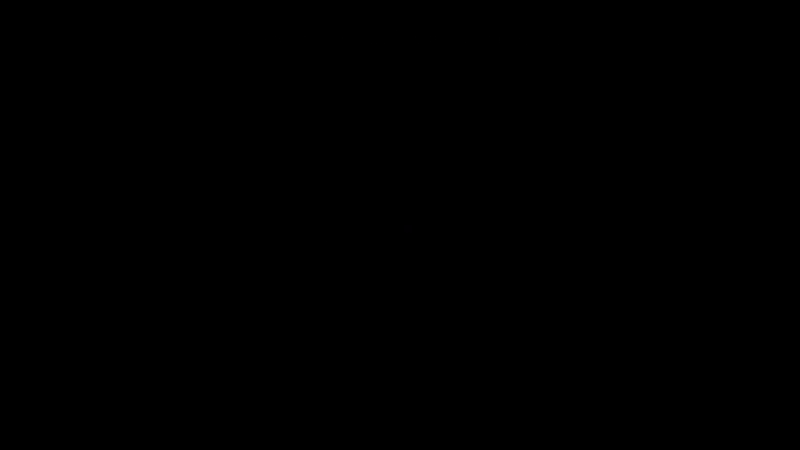
BAS works by defining an explicit “Answer-or-Abstain” utility. If the model answers correctly, it gets a reward (+1). If it abstains, it gets zero (0). If it answers incorrectly, it gets a massive penalty (-C). The score aggregates this utility across every possible risk threshold (every possible value of C).
Instead of a single point-estimate of error, BAS looks at the entire continuum of risk. It measures the “Area Under the Utility Curve,” ensuring that a model is only rewarded if its confidence scores are ordered such that an optimal observer could set a threshold to filter out almost all errors without losing all correct answers.
[ Input: Confidence p, Accuracy y ]
      v
[ Utility: U(p, y, tau) = y if p > tau else 0 ]
      v
[ Penalty: Adds -C*(1-y) if p > tau ]
      v
[ BAS: Integral over all risk preferences tau/C ]
Structural Metaphor: The Professional Indemnity Insurance. Think of the LLM as a freelance consultant. Standard metrics (ECE) are like a performance review: “How often were you right?” BAS is like an insurance premium calculation. If the consultant says “I’m 99% sure” and crashes the project, the insurance payout (penalty) is massive. If they say “I’m not sure, hire someone else,” there’s no progress but no disaster. BAS evaluates the consultant not just on their skill, but on whether their “Self-Assessed Risk” matches the actual danger of the task across different “Insurance Plans” (risk levels).
Key Concepts
- Abstention-Awareness: The ability of a system to recognize its own limits and choose not to provide an output when the risk of error exceeds a threshold.
- Asymmetric Penalty: A scoring logic where the cost of a “False Positive” (confidently wrong) is much higher than the cost of a “False Negative” (unnecessarily silent).
- Decision-Theoretic Metric: A way of measuring performance that accounts for the real-world consequences (utility) of different outcomes, rather than just statistical distance.
Framework Shift
Before (Statistical Calibration):      After (Decision Alignment):

  [ Confidence ] <-> [ Accuracy ]      [ Confidence ] -> [ Risk Filter ]
        |                |                   |                |
     Balance Mean Error                   Minimize Expected Disaster
One sentence: From “Is the probability accurate?” to “Is the probability a reliable trigger for a safety switch?”
Expert Assessment
Problem choice: Highly relevant. As LLMs enter medicine and law, “knowing when to shut up” is more important than “knowing more facts.”
Method maturity: The math is a clever application of existing decision theory (utility curves) to the LLM calibration problem. It’s elegant because it doesn’t require new model training, just a better way to look at the outputs we already have.
Experimental integrity: The benchmark is comprehensive. Comparing models with similar ECE but wildly different BAS effectively “exposes” models that look calibrated on paper but fail in the “tail” (the rare, high-confidence errors).
Writing quality: The theoretical proof section is dense, but the motivation is crystal clear. A better visualization of the “Abstention vs. Accuracy” tradeoff would have helped practitioners.
Verdict: Strong Accept — This is the “grown-up” version of calibration metrics the industry has been waiting for.
Takeaways
Practitioners should stop reporting ECE alone. If you are building a RAG system for a client, calculate the BAS. It will show you exactly where your “Top-K” retrieval might be leading the model into “Confident Hallucination” territories that a simple error rate won’t catch. Use BAS to set your “Abstention Threshold” based on your client’s specific risk tolerance.
论文: BAS: A Decision-Theoretic Approach to Evaluating Large Language Model Confidence 作者: Sean Wu, Fredrik K. Gustafsson, Edward Phillips, Boyan Gao, Anshul Thakur, David A. Clifton 分类: cs.CL
缺口
现有的 LLM “可靠性”研究过度依赖于预期校准误差(ECE)等指标。 ECE 只能告诉我们模型 80% 的置信度在平均意义上是否对应 80% 的准确率。 但在实际决策中,平均数会骗人。 我们真正关心的是,模型的置信度能否作为“安全开关”,在可能出错时让我们果断“弃权”。
此前的方法(如 Log Loss)对称地惩罚置信度不足和过度自信。 然而在现实中,医生的一个“确定的错误”比“不确定的正确”代价要大得多。 这篇论文填补了现有指标无法反映不同“风险偏好”的空白。
[ 问题:过度自信的错误(幻觉)摧毁信任 ]
      |
[ 假设:现实效用取决于模型是否具备“弃权”能力 ]
      |
[ 方法:基于效用模型的 BAS(行为对齐得分) ]
      |
[ 证据:前沿模型 ECE 接近但 BAS 差异巨大 ]
      |
[ 结论:评估必须对“过度自信的错误”进行非对称惩罚 ]
增量
一句话: 这篇论文之前,我们衡量 LLM 是否“自知之明”;这篇论文之后,我们衡量 LLM 是否可靠到可以给它一个“紧急制动开关”。
核心机制
BAS 通过定义一个明确的“回答或弃权”效用函数来工作。 如果模型答对了,得 1 分。 如果它选择弃权(承认不会),得 0 分。 如果它自信地答错了,扣除巨额分数(罚金 C)。 BAS 会计算在所有可能的“风险阈值”(即不同的 C 值)下的累计效用。
BAS 不再盯着单一的误差值,而是观察整个“效用曲线”。 它要求模型的置信度排序必须非常精准:只有当模型能通过设置一个阈值,过滤掉绝大多数错误,同时保留大部分正确答案时,它才能获得高分。
[ 输入:置信度 p, 准确性 y ]
      v
[ 效用:U = 正确(+1) / 弃权(0) / 错误(-C) ]
      v
[ 积分:在不同的风险厌恶程度 C 下进行全量计算 ]
      v
[ BAS:衡量模型在全风险谱系下的可靠性 ]
核喻:专业责任险评估。 把 LLM 想象成一名自由职业顾问。 传统的指标(如 ECE)像是“绩效考核”:你回答的问题里有多少是对的? 而 BAS 像是“保费计算”。 如果顾问说“我有 99% 的把握”却搞砸了,保险公司的赔付(惩罚)是天文数字。 如果他说“这我不专业,请找别人”,虽然没干活,但没造成灾难。 BAS 不仅评估顾问的专业水平,更评估他的“风险自评”是否与实际任务难度匹配。
关键概念
- 弃权意识 (Abstention-Awareness): 系统识别自身局限性的能力。在错误风险超过特定阈值时,主动选择不输出。
- 非对称惩罚 (Asymmetric Penalty): 一种计分逻辑。即“自信地犯错”的代价远高于“不必要的沉默”。
- 决策论指标 (Decision-Theoretic Metric): 这种评估方式不仅看统计上的距离,更看结果在现实世界中的“利害关系”(效用)。
框架转变
之前(统计校准):                  之后(决策对齐):

  [ 置信度 ] <-> [ 准确率 ]          [ 置信度 ] -> [ 风险过滤器 ]
        |            |                     |              |
      平衡平均误差                        最小化预期灾难
一句话:从“概率准不准?”转变为“概率能不能作为安全开关?”
专家评审
选题眼光: 非常敏锐。随着 LLM 进入医疗、法律领域,“知道什么时候该闭嘴”比“多背几个事实”重要得多。
方法成熟度: 数学上是将成熟的决策论(效用曲线)巧妙迁移到 LLM 校准问题上。它的高明之处在于不需要重新训练模型,只是换了一副眼镜来看待已有的输出。
实验诚意: 基准测试非常全面。通过对比 ECE 相似但 BAS 迥异的模型,无情地戳穿了那些“纸面校准良好、实则在关键时刻掉链子”的模型。
写作功力: 理论证明部分比较晦涩,但动机讲解得非常透彻。如果能对“弃权 vs 准确”的权衡做更直观的动态演示会更好。
判决: 强接收 (Strong Accept) — 这是工业界期待已久的、“成年人”版本的可靠性评估指标。
要点总结
实践者应该立即停止单独报告 ECE 指标。 如果你正在为客户构建 RAG 系统,请计算 BAS。 它能告诉你,你的检索增强是否正把模型引入“自信的幻觉”区,而这仅仅看错误率是看不出来的。 利用 BAS,你可以根据客户具体的风险承受能力(比如金融机构对错误的零容忍),设定最科学的“弃权阈值”。