Paper: 2605.22816 Authors: Wenxuan Guo, Xiuwei Xu, Yichen Liu, Xiangyu Li, Hang Yin, Huangxing Chen, Wenzhao Zheng, Jianjiang Feng, Jie Zhou, Jiwen Lu Categories: cs.RO, cs.CV
The Gap
Vision-Language Navigation (VLN) asks an agent to follow natural language instructions in visual environments. Two camps emerged: end-to-end VLM methods that predict actions directly but lack explainable spatial reasoning, and map-based planners that build explicit 3D scene representations but require depth sensors and can’t leverage large-scale vision-language pretraining. The former doesn’t know where it is; the latter can’t scale.
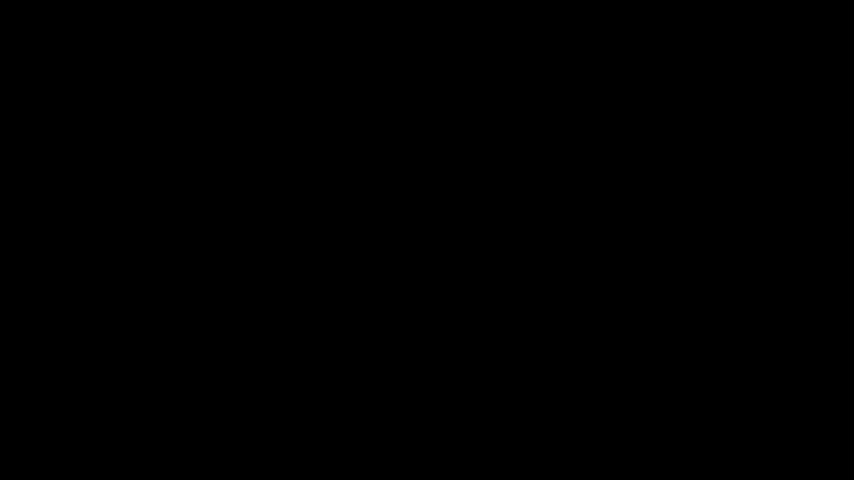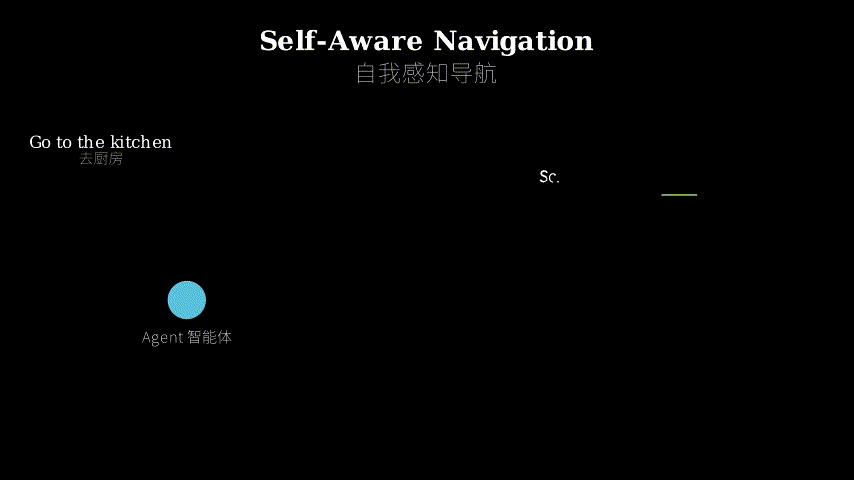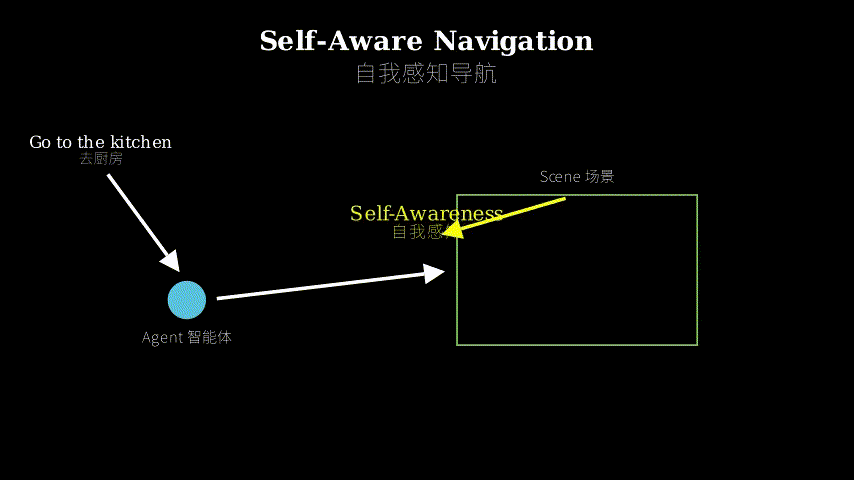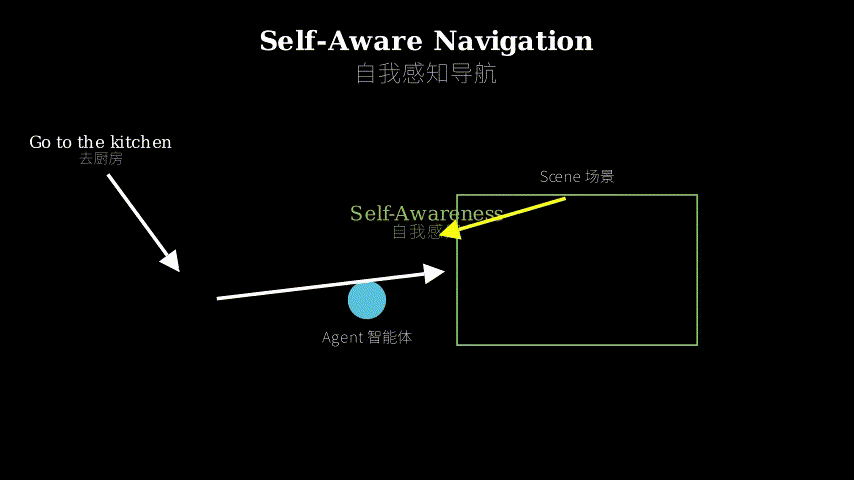
This paper targets the middle ground: can we get spatial self-awareness (knowing “I’m at the kitchen entrance, halfway through the task”) without building explicit 3D maps?
Problem: VLN agents lack spatial self-awareness
   |
   v
Assumption: Self-awareness can emerge from structural reasoning
            over visual observations (no 3D sensors needed)
   |
   v
Method: Structural reasoning module + progress-aware training
   |
   v
Evidence: SOTA on R2R, REVERIE, SOON (Habitat simulator)
   |
   v
Conclusion: End-to-end learning can internalize spatial reasoning
            when guided by task-progress structure
The Increment
One sentence: Before, VLN agents either reasoned blindly (VLMs) or needed depth sensors (map builders); now they can develop spatial self-awareness from RGB alone through structured reasoning.
Core Mechanism
AwareVLN has two components working in tandem. First, a structural reasoning module that takes the agent’s visual observations and instruction, then outputs three types of awareness: (1) spatial awareness (where am I relative to landmarks?), (2) task awareness (which instruction sub-goals have I completed?), and (3) decision awareness (what should I do next?). This module uses cross-attention between visual features and instruction tokens to ground language in the scene.
Second, an automatic data engine that divides trajectories into progress stages. For each stage, it generates pseudo-labels for what the agent should be aware of at that point. During training, the model learns to predict these awareness states, which then guide action selection. The key insight: by forcing the model to articulate its understanding of position and progress, it learns better spatial reasoning than direct action prediction.
Instruction + Visual Obs
         |
         v
   [Structural Reasoning Module]
         |
    +----+----+
    |    |    |
    v    v    v
 Spatial Task Decision
 Aware  Aware  Aware
    |    |    |
    +----+----+
         |
         v
    Action Prediction
Think of it like teaching someone to navigate by making them narrate their journey. Instead of just saying “turn left,” they must say “I’m at the kitchen entrance, I’ve found the fridge mentioned in step 1, now I need to locate the dining table for step 2, so I’ll turn left.” The narration forces explicit reasoning about position and progress. AwareVLN does this computationally: the “narration” is the awareness states (spatial/task/decision), and by training the model to generate accurate narrations, it learns to navigate better. The progress division is like breaking a long instruction into checkpoints—at each checkpoint, the model must report what it knows, preventing it from drifting aimlessly.
Key Concepts
-
Self-awareness in navigation: Not consciousness, but the model’s ability to represent its own state relative to the task. Concretely: “I am at location X (spatial), I have completed sub-goals A and B but not C (task), therefore I should move toward landmark Y (decision).” Most VLN models implicitly encode this in hidden states; AwareVLN makes it explicit and supervises it directly. Why does this help? Because explicit representations are easier to learn correctly—the model gets direct feedback on whether its understanding of “where I am” matches ground truth, rather than only getting feedback on whether the final action was right.
-
Progress division: Automatically segmenting a trajectory into stages based on instruction structure. For example, “Go to the kitchen, then find the fridge, then turn left” becomes three stages. At each stage boundary, the data engine generates labels for what the agent should be aware of (e.g., “at stage 2, you should recognize the fridge and know you’re halfway done”). This creates dense supervision signals throughout the trajectory, not just at the end. Without this, the model only knows if it reached the goal, not whether its intermediate reasoning was correct.
Framework Shift
Before (end-to-end VLM):              After (AwareVLN):

Instruction + Image                   Instruction + Image
       |                                     |
       v                                     v
  [Black Box VLM]                   [Structural Reasoning]
       |                                     |
       v                              +------+------+
   Action                              |      |      |
                                    Spatial Task Decision
                                    Aware   Aware  Aware
                                       |      |      |
                                       +------+------+
                                             |
                                             v
                                         Action

Implicit reasoning,                   Explicit awareness states,
no spatial grounding                  supervised at each step
From opaque action prediction to transparent reasoning: the core shift is making the agent’s understanding of its position and progress an explicit, supervised part of the model.
Expert Assessment
Problem choice: Real gap. The VLM vs map-builder dichotomy is well-established in VLN, and the lack of explainability in end-to-end methods is a genuine limitation for deployment. The problem sits at a natural inflection point where VLMs are powerful enough to handle complex reasoning but still struggle with spatial grounding.
Method maturity: Clever insight with solid execution. The structural reasoning module is not revolutionary—it’s cross-attention with task-specific heads—but the progress division data engine is genuinely useful. The automatic labeling of awareness states at different trajectory stages is a practical contribution that others can adopt. One concern: the method still requires trajectory data with ground-truth paths, so it’s not fully self-supervised. A simpler baseline would be adding auxiliary losses for landmark detection without the full awareness apparatus.
Experimental integrity: Baselines are fair (compares against recent SOTA like NavGPT, ETPNav). Numbers look solid across three datasets (R2R, REVERIE, SOON). Ablations show each component contributes. One red flag: all experiments are in Habitat simulator, which has cleaner visuals than real-world robotics. The claim of “no 3D sensors needed” is true but slightly misleading—Habitat provides perfect RGB rendering from known poses, which is easier than real noisy cameras.
Writing quality: Abstract and intro are clear. Method section gets dense with notation around the awareness modules—Figure 2 helps but could be larger. The progress division algorithm (Section 3.3) is buried and deserves more prominence since it’s a key contribution. Experiments section is thorough but repetitive across datasets. If I were reviewing, I’d ask them to consolidate the results tables and expand the failure case analysis (currently one paragraph).
Verdict: weak accept — Solid incremental contribution with a useful technique (progress division), but not a paradigm shift. The explicit awareness mechanism is intuitive and works, though the gains over strong baselines are modest (2-3% on most metrics).
Takeaways
Progress-aware training is transferable: The idea of dividing long-horizon tasks into stages and supervising intermediate understanding at each stage applies beyond navigation—any sequential decision problem with natural language instructions (robotic manipulation, interactive agents, code generation) could benefit. The automatic labeling scheme (using instruction structure to infer progress stages) is particularly practical.
Explicit intermediate representations help: When your model needs to reason about state over time, making that reasoning explicit (with dedicated prediction heads and losses) often works better than hoping it emerges in hidden states. This is a recurring pattern in RL and imitation learning.
The “self-awareness” framing is marketing: Strip away the terminology and you have auxiliary losses for spatial grounding and task progress. The contribution is real but not as conceptually novel as the title suggests. Don’t get distracted by the framing—focus on the progress division mechanism, which is the concrete technique you can reuse.
论文: 2605.22816 作者: Wenxuan Guo, Xiuwei Xu, Yichen Liu, Xiangyu Li, Hang Yin, Huangxing Chen, Wenzhao Zheng, Jianjiang Feng, Jie Zhou, Jiwen Lu 分类: cs.RO, cs.CV
缺口
视觉-语言导航(VLN)要求智能体在视觉环境中遵循自然语言指令。
目前形成了两个阵营:端到端的视觉-语言模型直接预测动作但缺乏可解释的空间推理,基于地图的规划器构建显式的3D场景表示但需要深度传感器且无法利用大规模视觉-语言预训练。
前者不知道自己在哪;后者无法规模化。
本文瞄准中间地带:能否在不构建显式3D地图的情况下获得空间自我意识(知道”我在厨房入口,任务完成了一半”)?
问题:VLN智能体缺乏空间自我意识
   |
   v
假设:自我意识可以通过对视觉观察的结构化推理涌现
      (无需3D传感器)
   |
   v
方法:结构化推理模块 + 进度感知训练
   |
   v
证据:在R2R、REVERIE、SOON上达到SOTA(Habitat模拟器)
   |
   v
结论:端到端学习在任务进度结构引导下
      可以内化空间推理
增量
一句话:之前VLN智能体要么盲目推理(VLM)要么需要深度传感器(地图构建器);现在它们可以仅通过RGB图像,经由结构化推理发展出空间自我意识。
核心机制
AwareVLN有两个协同工作的组件。
首先是结构化推理模块,接收智能体的视觉观察和指令,输出三种意识:(1)空间意识(我相对于地标在哪?
)、(2)任务意识(我完成了哪些指令子目标?
)、(3)决策意识(我接下来该做什么?
)。
该模块使用视觉特征和指令token之间的交叉注意力将语言锚定到场景中。
其次是自动数据引擎,将轨迹划分为进度阶段。
对每个阶段,它生成智能体在该时刻应该意识到什么的伪标签。
训练时,模型学习预测这些意识状态,然后用它们指导动作选择。
关键洞察:通过强制模型阐明其对位置和进度的理解,它学到的空间推理比直接动作预测更好。
指令 + 视觉观察
         |
         v
   [结构化推理模块]
         |
    +----+----+
    |    |    |
    v    v    v
 空间  任务  决策
 意识  意识  意识
    |    |    |
    +----+----+
         |
         v
    动作预测
把它想象成教人导航时让他们叙述旅程。
不是只说”左转”,而是必须说”我在厨房入口,我找到了步骤1提到的冰箱,现在需要定位步骤2的餐桌,所以我要左转。
“叙述强制对位置和进度进行显式推理。
AwareVLN在计算上做同样的事:“叙述”就是意识状态(空间/任务/决策),通过训练模型生成准确的叙述,它学会更好地导航。
进度划分就像把长指令分解为检查点——在每个检查点,模型必须报告它知道什么,防止它漫无目的地漂移。
关键概念
- 导航中的自我意识:不是意识本身,而是模型表示自身相对于任务的状态的能力。
具体来说:“我在位置X(空间),我完成了子目标A和B但没完成C(任务),因此我应该朝地标Y移动(决策)。
“大多数VLN模型在隐藏状态中隐式编码这些;AwareVLN让它显式化并直接监督。
为什么有帮助?
因为显式表示更容易正确学习——模型直接获得关于其”我在哪”的理解是否匹配真值的反馈,而不是只获得最终动作是否正确的反馈。
- 进度划分:基于指令结构自动将轨迹分段为阶段。
例如,“去厨房,然后找冰箱,然后左转”变成三个阶段。
在每个阶段边界,数据引擎生成智能体应该意识到什么的标签(例如,“在阶段2,你应该识别冰箱并知道你完成了一半”)。
这在整个轨迹中创建密集的监督信号,而不仅仅在最后。
没有这个,模型只知道是否到达了目标,不知道其中间推理是否正确。
框架转变
之前(端到端VLM):                之后(AwareVLN):

指令 + 图像                        指令 + 图像
       |                                  |
       v                                  v
  [黑盒VLM]                        [结构化推理]
       |                                  |
       v                           +------+------+
   动作                             |      |      |
                                 空间   任务   决策
                                 意识   意识   意识
                                    |      |      |
                                    +------+------+
                                          |
                                          v
                                      动作

隐式推理,                          显式意识状态,
无空间锚定                          每步都被监督
从不透明的动作预测到透明的推理:核心转变是让智能体对其位置和进度的理解成为模型中显式的、被监督的部分。
专家评审
选题眼光:真实缺口。
VLM与地图构建器的二分法在VLN中已确立,端到端方法缺乏可解释性对部署来说是真正的限制。
问题处于一个自然的拐点,VLM足够强大可以处理复杂推理,但仍在空间锚定上挣扎。
方法成熟度:巧妙洞察加扎实执行。
结构化推理模块不算革命性——它是带任务特定头的交叉注意力——但进度划分数据引擎确实有用。
在不同轨迹阶段自动标注意识状态是一个实用贡献,其他人可以采用。
一个担忧:方法仍需要带真值路径的轨迹数据,所以不是完全自监督。
一个更简单的基线是添加地标检测的辅助损失,而不需要完整的意识装置。
实验诚意:基线公平(与NavGPT、ETPNav等近期SOTA比较)。
数字在三个数据集(R2R、REVERIE、SOON)上看起来扎实。
消融实验显示每个组件都有贡献。
一个警示:所有实验都在Habitat模拟器中,其视觉效果比真实世界机器人更干净。
“无需3D传感器”的说法是真的,但略有误导——Habitat从已知姿态提供完美的RGB渲染,比真实的噪声相机容易。
写作功力:摘要和引言清晰。
方法部分在意识模块周围的符号表示变得密集——图2有帮助但可以更大。
进度划分算法(3.3节)被埋没了,应该更突出,因为它是关键贡献。
实验部分彻底但在数据集间重复。
如果我审稿,我会要求他们合并结果表格,扩展失败案例分析(目前只有一段)。
判决:弱接收 — 扎实的增量贡献,有一个有用的技术(进度划分),但不是范式转变。
显式意识机制直观且有效,尽管相对强基线的提升适度(大多数指标上2-3%)。
要点总结
进度感知训练可迁移:将长期任务划分为阶段并在每个阶段监督中间理解的想法,适用于导航之外——任何带自然语言指令的序列决策问题(机器人操作、交互式智能体、代码生成)都能受益。
自动标注方案(使用指令结构推断进度阶段)特别实用。
显式中间表示有帮助:当你的模型需要随时间推理状态时,让推理显式化(用专门的预测头和损失)通常比希望它在隐藏状态中涌现效果更好。
这是强化学习和模仿学习中的反复出现的模式。
“自我意识”框架是营销:剥离术语,你得到的是空间锚定和任务进度的辅助损失。
贡献是真实的,但在概念上不如标题暗示的那么新颖。
不要被框架分散注意力——专注于进度划分机制,这是你可以重用的具体技术。