Paper: 2608.12313 Authors: Chuyue Li, Jinpeng Yu, Haozhe Wang, Tian Xueyun, Zhijing Zhang, Bingnan Li, Shuqi Gu, Kan Ren, Jiaming Liu, Ruihua Hua Categories: cs.CL, cs.CV
The Gap
Here’s the setup. We have two mature families of video representation and neither is usable by an agent that wants to learn filmmaking from films.
Family one is continuous latents: VAE latents inside diffusion video models, VideoMAE-style masked reconstruction features, CLIP/ViCLIP/InternVideo embeddings. These are faithful — you can decode a VAE latent back to something close to pixels — but they are opaque. An agent cannot ask “who is in the frame during the reverse shot?” or edit “make the key light colder in shot 14.” There’s no handle to grab.
Family two is text: dense captioning, LLaVA-Video / Qwen-VL style descriptions, “storyboard scripts” that agentic video pipelines (VideoDirectorGPT, Anim-Director, MovieAgent lineage) write by hand-prompting an LLM. These are perfectly editable but badly lossy and, more importantly, unstructured and ungrounded. A paragraph of prose cannot carry a specific actor’s face, a specific voice timbre, or shot-to-shot continuity. And the prompt that produced that paragraph was tuned by a human staring at outputs, which doesn’t scale and isn’t measurable.
So the gap is precise: no representation is simultaneously (a) faithful enough that you can measure information loss by reconstructing the video, and (b) structured enough that an agent can query and edit it. And a second-order gap: even if you designed such a representation by hand, there’s no *learning signal for the encoder, because the encoder is an LLM policy and the whole pipeline is non-differentiable.
AVA-Encoder’s bet: make the latent space a typed knowledge graph with an attached asset layer, close the loop by actually re-rendering the video, and turn the reconstruction gap into English feedback that updates the encoding policy.
   PROBLEM
   [ agents cannot learn from films: no representation that is
     both faithful AND agent-manipulable ]
        |
        v
   ASSUMPTION
   [ 1. a typed KG + linked assets can carry film content ]
   [ 2. reconstruct-and-compare is a valid fidelity proxy ]
   [ 3. natural language can act as a gradient over prompts ]
        |
        v
   METHOD
   [ video -> KG (hierarchy + state nodes, typed edges)
                  + asset layer (img / audio / video)
     KG   -> video (agentic decode)
     diff -> textual gradient
        outer: policy pseudo-training  (data independent)
        inner: KG refinement at test    (data dependent)  ]
        |
        v
   EVIDENCE
   [ +20.7 pp over strongest external baseline           ]
   [ pseudo-trained policy > human-tuned policy,          ]
   [   with 74.3% fewer system-prompt tokens              ]
   [ released: benchmark + film-KG dataset                ]
        |
        v
   CONCLUSION
   [ "agent-native" representations can be *learned*,
     not hand-designed; reconstruction is the yardstick ]
The Increment
One sentence: Before, agentic video pipelines used hand-written prompt scaffolds producing unverifiable prose; after, there’s a closed-loop auto-encoder whose latent is an editable knowledge graph and whose training signal is natural-language critique of the reconstructed video.
Core Mechanism
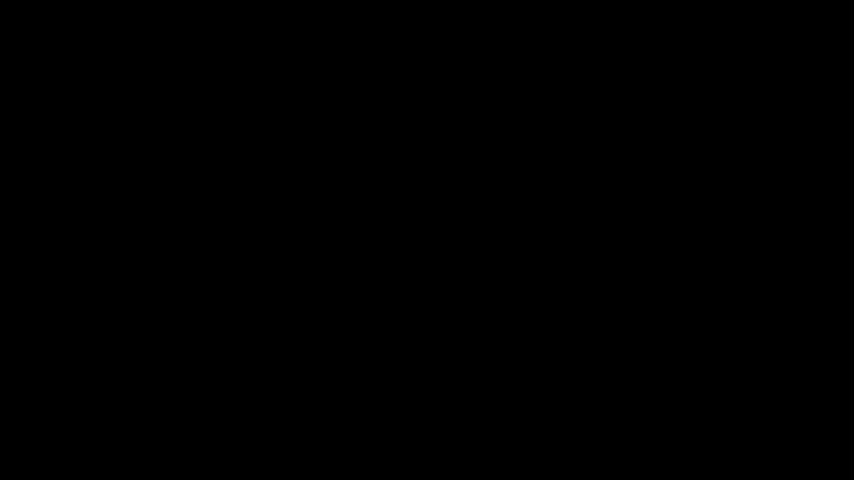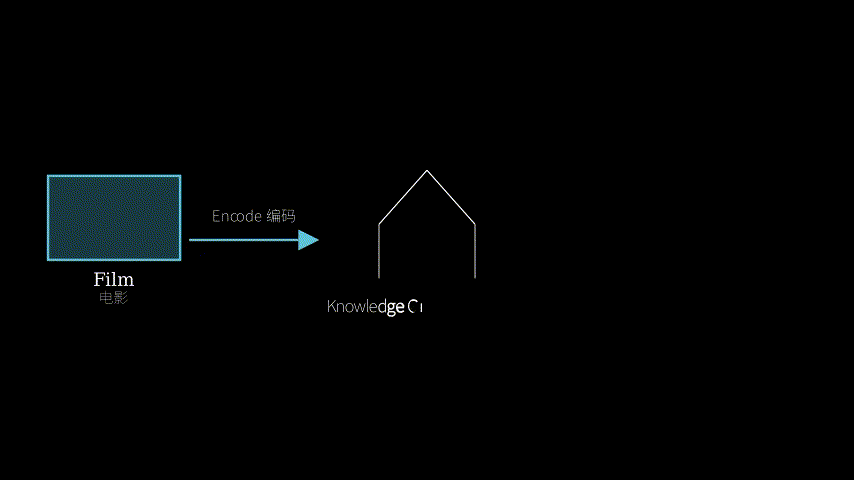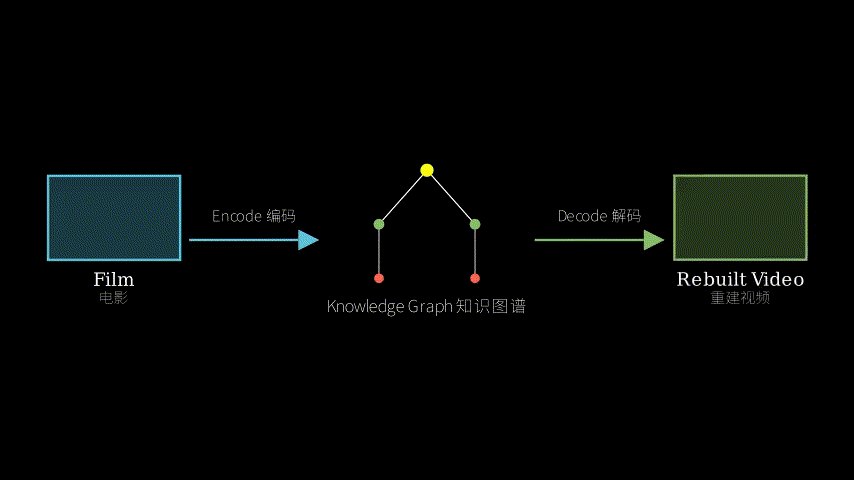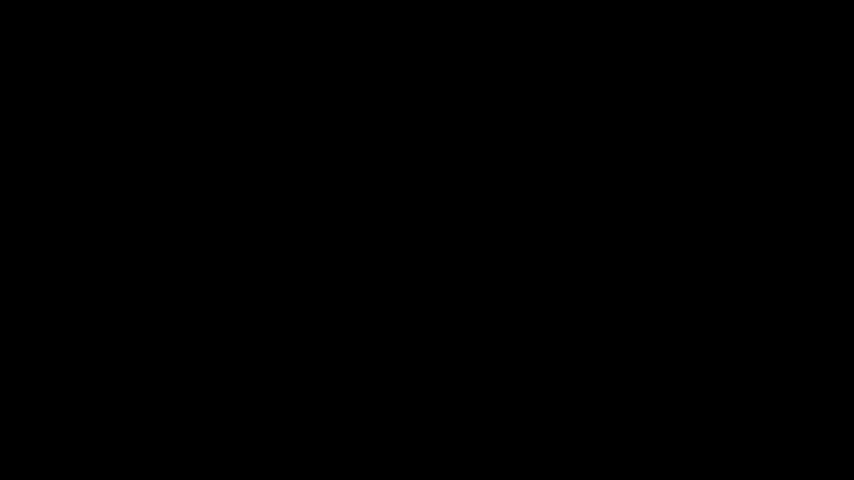
The encoder is an LLM/VLM agent policy that ingests a film and emits a knowledge graph. The graph has three structural ingredients. Hierarchy nodes give the film its skeleton — film, sequence, scene, shot — which matters because film information is genuinely hierarchical (a lighting decision belongs to a scene, a cut belongs between shots). State nodes hang off the hierarchy and hold structured text: who is present, what they want, where the camera is, what the lens is doing, what the mood is. Typed edges wire it together, and the typing is the whole point: shot -> contains -> character, character -> rendered_as -> asset_017, shot_14 -> cuts_to -> shot_15. An agent can traverse typed edges; it cannot traverse a paragraph.
The fourth ingredient is the escape hatch for what text cannot hold. Some content is irreducibly non-textual: a face, a voice, a specific texture of grain. The asset layer stores generated images, audio clips, and video snippets, and typed edges pin them to the nodes they realize. This is what stops the representation from degenerating into a screenplay.
Then the loop closes. A decoder agent reads the KG and reconstructs a video from it. Comparing reconstruction against original yields a gap — and instead of backpropagating a scalar, the framework verbalizes it: “the reverse shot lost the character’s eyeline; the encoder never recorded screen direction.” That sentence is the gradient. It flows to two places. In the outer loop (*Data-Independent Encoding Policy Pseudo-Training) it updates the encoder’s policy — its system prompt, its schema conventions, its checklist of what to always record — so the fix generalizes to films never seen. This is where the 74.3% token reduction comes from: the learned policy is a tighter, better-organized instruction set than a human’s accreted prompt. In the optional inner loop (*Data-Dependent KG Representation Refinement) the gradient instead edits this particular graph at test time, patching the specific missing eyeline.
   original video
        |
        v
  +----------------------------+
  |  ENCODER POLICY (agent)    |<---- outer-loop update (text)
  |  system prompt = "weights"  |          ^
  +----------------------------+           |
        |                                  |
        v                                  |
  KG REPRESENTATION                        |
  .......................................  |
  : [film]                              :  |
  :   |-- [scene] --- [shot] --- [state]:  |
  :   |                 |          |    :  |
  :   |            (typed edges)   |    :  |
  :   v                 v          v    :  |
  : [scene] ....... [shot] ... [state]  :  |
  :......................................  |
        |  rendered_as / voiced_by         |
        v                                  |
  ASSET LAYER  [ img ] [ audio ] [ clip ]  |
        |                                  |
        v                                  |
  +----------------------------+           |
  |  DECODER (agentic render)  |           |
  +----------------------------+           |
        |                                  |
        v                                  |
  reconstructed video                      |
        |                                  |
        v                                  |
  +----------------------------+           |
  |  EVALUATOR: diff -> ENGLISH |----------+
  |  "you dropped screen        |
  |   direction in reverse cuts"|--- inner loop ---> edit THIS KG
  +----------------------------+
The metaphor: a studio’s continuity bible.
Think of a film production department. The script supervisor (encoder policy) watches the movie and writes the *continuity bible: a binder organized by act, scene, and shot (hierarchy nodes), with a page per shot listing characters, blocking, lens, lighting, mood (state nodes), cross-referenced by explicit tabs — “see character sheet C-3,” “cuts to page 214” (typed edges). Prose alone won’t do, so the binder has a prop and casting warehouse attached: headshots, voice samples, reference clips, each tagged with the binder page it belongs to (asset layer).
Now the test: hand the binder to a second crew that has never seen the original film (decoder) and tell them to shoot it. Screen the result next to the original. The director’s dailies notes are the gradient — but notice there are two kinds of note. “Page 214 forgot the eyeline, fix page 214” is a note about *this film (inner loop, test-time KG refinement). “Our binder template has no field for screen direction — add it to the studio’s standard form” is a note about how we take notes at all (outer loop, policy pseudo-training). The second kind is the paper’s real contribution, and it’s why the learned form ends up shorter than the one the veteran supervisor built by accretion: a form redesigned from failure evidence beats a form that grew by adding reminders.
Key Concepts
-
Agentic auto-encoding: A normal auto-encoder squeezes data through a narrow bottleneck and trains by penalizing reconstruction error, with gradients flowing through both halves. Here, both halves are LLM agents and the bottleneck is a document, so nothing is differentiable. But the *logic survives: if the reconstruction is wrong, the encoding must have dropped something, and the drop tells you what to record next time. Concretely — you describe a photo to a friend over the phone, they draw it, you compare drawings. You don’t need calculus to learn “always mention which way people are facing.” That’s the whole trick, applied to films instead of photos.
-
Textual gradient: A gradient is just “which direction should I move to get less error.” A number does that in weight space; a sentence can do it in prompt space. Instead of
dL/dw = 0.03, you get “the encoder consistently ignores audio transitions” and you edit the instruction accordingly. It inherits the shape of gradient descent — repeated small directed edits driven by evaluated error — without the mathematics, and it inherits the pathologies too: it’s noisy, it can oscillate, and there’s no line search. (This descends from TextGrad/DSPy-style prompt optimization; the novelty here is what generates the signal.) -
Data-independent vs data-dependent optimization: The distinction is where the update lands. Data-independent (outer, “pseudo-training”) changes the *encoder, so every future film benefits — this is training, and it’s why they can report a policy-only comparison against a human-tuned prompt. Data-dependent (inner, test-time) changes one graph, so only this film benefits — this is inference-time repair. Analogy: fixing the intake form your clinic uses for all patients, versus correcting one patient’s chart. Papers that conflate these tend to overclaim; keeping them separate is what makes the “controlled policy-only setting” result meaningful.
Framework Shift
Before (mainstream approach):          After (this paper):

 video                                  video
   |                                      |
   v                                      v
 [ pixel latent ]  or  [ prose ]      [ typed KG + asset layer ]
   |                       |             |    ^
   |  faithful             | editable    |    |  english gradient
   |  opaque               | lossy       |    |  from re-render diff
   v                       v             v    |
 agent: no handle    agent: no ground   agent: query / edit / reuse
                                              |
 encoder prompt: hand-tuned by human    encoder POLICY: pseudo-trained
   (unmeasured, grows by accretion)        (measured by reconstruction)

 fidelity: FVD / CLIPScore vibes        fidelity: can a blind crew
   (no closed loop)                       reshoot it? (closed loop)
From “represent the video” to “represent the production instructions and verify them by reshooting,” the core shift is making the encoder an object of optimization rather than a hand-written scaffold, with reconstruction as the only judge.
Expert Assessment
Problem choice: Real gap, well located. Everyone building creative agents has hit the same wall — you can prompt a model into a decent 8-second shot, but there’s no substrate for *learning from a corpus of good films and no way to know whether your intermediate script actually retained the film. Framing that substrate as a latent code and importing auto-encoder discipline is the right instinct, and it sits naturally in the trajectory from prompt-chaining pipelines toward optimized agent programs. The “creative agents need cinematic grade” motivation is more marketing than argument, but the technical gap underneath it stands on its own.
Method maturity: Clever, with a load-bearing engineering component and one soft spot. The genuinely good idea is using reconstruction to supervise the *encoder policy rather than the per-instance representation — that’s the difference between a demo and a method, and the token-reduction result is the most persuasive number in the abstract precisely because it’s a controlled policy-only comparison. The asset layer is honest engineering: they noticed text can’t carry identity and stopped pretending. The soft spot is that the asset layer also quietly weakens the auto-encoder framing. If arbitrary generated images and clips can be stored in the “latent,” the bottleneck is negotiable, and nothing in the abstract tells us how much information lives in text versus cached pixels. A rate-distortion style curve — fidelity as a function of asset budget — would settle whether this is compression or a well-organized cache. Simpler alternatives worth ruling out: a fixed hand-designed schema with a strong VLM filling slots, or plain DSPy/TextGrad prompt optimization against a VLM judge without the graph. The KG’s incremental value over “structured JSON with references” is asserted more than isolated.
Experimental integrity: Cautiously positive with the usual caveats, and I can’t verify the internals from the abstract alone. “+20.7 percentage points over the strongest external baseline” is a big jump, and big jumps on a self-released benchmark usually mean the baselines weren’t built for that benchmark — captioning models and hand-prompted storyboard pipelines aren’t trying to be reconstructable. That’s not cheating, but it makes the number a statement about task novelty more than method superiority. The load-bearing worry is the evaluator: if reconstruction fidelity is scored by a VLM judge, and a textual gradient from that same judge tunes the encoder, you have a closed loop that can learn to please the judge. Human study, held-out judge, or judge-swap ablation is the thing I’d look for first. Also unaddressed in the abstract: does the representation help *downstream? The stated motivation is producing better films; reconstruction fidelity is a proxy, and nobody yet shows an agent editing a KG and getting a better film out.
Writing quality: The abstract is dense with capitalized proper nouns — “Data-Independent Encoding Policy Pseudo-Training,” “Data-Dependent KG Representation Refinement” — that carry less information than the plain phrases they replace, and “pseudo-training” is doing conspicuous hedging work that deserves one honest sentence of definition. The section I’d rewrite is evaluation: state the metric, state who judges, and put the ablations that matter up front (KG vs flat text at matched asset budget; outer loop off; judge swapped). The taxonomy is over-branded relative to how well the measurement is explained.
Verdict: weak accept — the reconstruction-supervised encoder policy is a genuinely transferable idea and the artifact release is substantial, but the headline gain rests on a self-built benchmark with a likely-circular judge, and downstream utility is unproven.
Takeaways
Things you can actually steal:
- Use reconstruction as a supervision signal for non-differentiable pipelines. Any time an agent extracts structure from rich input, you can build a decoder that regenerates the input and use the gap as free, unlabeled, automatic supervision. This works on documents, codebases, UI recordings, medical charts — anywhere “did you keep the important stuff?” is hard to ask directly but “can you rebuild it?” is easy.
- Optimize the policy, not the output. The distinction between data-independent (fix the extractor) and data-dependent (fix this record) updates is the cleanest framing in the paper. Most prompt-tuning work quietly mixes them and then can’t say what it learned. Keep them in separate loops and report them separately.
- Expect learned prompts to be shorter than hand-tuned ones. The 74.3% reduction is the practical headline: human prompts grow by accretion — every failure adds a reminder, nothing is ever removed. An optimizer that rewrites from failure evidence reorganizes instead of appending. If you maintain a long hand-tuned system prompt, this is the argument for regenerating it against a test set.
- Give your text representation an asset escape hatch. Deciding up front which content is irreducibly non-textual and storing it as typed pointers, rather than trying to describe a face in words, is a design pattern that transfers to any “LLM as structured extractor” system.
- Type your edges. The reason the graph beats prose is not expressiveness, it’s traversability: an agent can query and patch
shot_14 -> cuts_to -> shot_15and cannot patch a sentence. If you want an agent to edit your representation, make every relation nameable.
What not to take on faith: the specific gains, until you see who the judge was.
论文: 2608.12313 作者: Chuyue Li, Jinpeng Yu, Haozhe Wang, Tian Xueyun, Zhijing Zhang, Bingnan Li, Shuqi Gu, Kan Ren, Jiaming Liu, Ruihua Hua 分类: cs.CL, cs.CV
缺口
先把局面摆清楚。
现在成熟的视频表示有两大类,而想「从好电影里学会拍电影」的智能体,两类都用不上。
第一类是连续潜变量:扩散视频模型里的 VAE latent、VideoMAE 那套掩码重建特征、CLIP / ViCLIP / InternVideo 的嵌入。
它们够忠实——VAE latent 解回去确实很接近原像素——但完全不透明。
智能体没法问「反打镜头里画面中是谁」,也没法执行「把第 14 号镜头的主光调冷一点」。
没有把手可抓。
第二类是文本:dense caption、LLaVA-Video / Qwen-VL 式的描述、以及各种智能体视频流水线(VideoDirectorGPT、Anim-Director、MovieAgent 一脉)靠人工调 prompt 让 LLM 写出的「故事板脚本」。
这类完全可编辑,但损失严重,更要命的是既无结构也无接地。
一段散文承载不了某个具体演员的脸、某个具体的音色、也承载不了镜头之间的连贯性。
而且产出这段散文的 prompt 是人盯着输出手调出来的——不可扩展,也无法度量。
所以缺口很精确:没有一种表示同时做到 (a) 足够忠实,以至于可以通过「重建视频」来度量信息损失;(b) 足够结构化,以至于智能体能查询和编辑。
还有一个二阶缺口:即便你手工设计出这样一种表示,编码器也没有学习信号——因为编码器是个 LLM 策略,整条链路不可微。
AVA-Encoder 的赌注是:把潜空间做成带素材层的有类型知识图谱,用「真的把视频重渲染回来」闭环,再把重建差距变成英文反馈去更新编码策略。
   问题
   [ 智能体无法从电影中学习:不存在既忠实
     又可被智能体操纵的表示 ]
        |
        v
   假设
   [ 1. 有类型 KG + 素材层 足以承载电影内容 ]
   [ 2. 重建后对比 是有效的忠实度代理指标   ]
   [ 3. 自然语言 可以充当 prompt 空间的梯度 ]
        |
        v
   方法
   [ 视频 -> KG(层级节点 + 状态节点 + 有类型边)
                 + 素材层(图 / 音 / 视频片段)
     KG   -> 视频(智能体式解码)
     差异 -> 文本梯度
        外环:编码策略伪训练(数据无关)
        内环:KG 表示精修(数据相关,测试时) ]
        |
        v
   证据
   [ 比最强外部基线 +20.7 个百分点        ]
   [ 伪训练策略 > 人工精调策略,          ]
   [   且系统 prompt 少 74.3% token       ]
   [ 开源:重建基准 + 电影 KG 数据集      ]
        |
        v
   结论
   [ 「智能体原生」表示可以被*学出来*,
     不必手工设计;重建就是那把尺子 ]
增量
一句话:以前的智能体视频流水线用人写的 prompt 脚手架产出无法验证的散文;以后有了一个闭环自编码器,它的潜表示是可编辑的知识图谱,它的训练信号是对重建视频的自然语言批评。
核心机制
编码器是一个 LLM/VLM 智能体策略,吃进一部电影,吐出一张知识图谱。
图有三种结构成分。
层级节点给电影搭骨架——片、段、场、镜——这很关键,因为电影信息本身就是层级的(一个打光决定属于一场戏,一个剪切点属于两个镜头之间)。
状态节点挂在层级上,装结构化文本:谁在场、他想干什么、机位在哪、镜头在做什么运动、情绪是什么。
有类型边把这些连起来,而「有类型」正是整个要点:shot -> contains -> character、character -> rendered_as -> asset_017、shot_14 -> cuts_to -> shot_15。
智能体能遍历有类型的边,但没法遍历一个段落。
第四种成分是给「文本装不下的东西」留的逃生口。
有些内容天生无法文本化:一张脸、一个嗓音、某种特定质感的颗粒。
素材层存放生成的图像、音频、视频片段,并用有类型边把它们钉在各自实现的节点上。
正是这一层阻止了整个表示退化成一份剧本。
然后闭环合上。
解码智能体读 KG,从它重建出视频。
拿重建和原片对比会得到一个差距——而框架不是回传一个标量,而是把它讲成话:「反打丢了角色视线;编码器从来没记录过画面方向。」
这句话就是梯度。
它流向两个地方。
在外环(数据无关的编码策略伪训练)里,它更新编码器的**策略*——系统 prompt、schema 约定、「必须记录什么」的清单——所以这个修补能泛化到从未见过的电影。
74.3% 的 token 缩减就来自这里:学出来的策略比人类层层累积的 prompt 更紧、组织更好。
在可选的内环(数据相关的测试时 KG 精修)里,梯度改的是**这一张图*,直接补上那条缺失的视线。
   原始视频
        |
        v
  +----------------------------+
  |  编码策略(智能体)        |<---- 外环更新(文本)
  |  系统 prompt = 「权重」    |          ^
  +----------------------------+           |
        |                                  |
        v                                  |
  KG 表示                                  |
  .......................................  |
  : [片]                                :  |
  :   |-- [场] ----- [镜] ----- [状态]  :  |
  :   |                |          |     :  |
  :   |          (有类型边)     |     :  |
  :   v                v          v     :  |
  : [场] .......... [镜] ..... [状态]   :  |
  :......................................  |
        |  rendered_as / voiced_by         |
        v                                  |
  素材层   [ 图 ] [ 音频 ] [ 片段 ]        |
        |                                  |
        v                                  |
  +----------------------------+           |
  |  解码器(智能体式渲染)    |           |
  +----------------------------+           |
        |                                  |
        v                                  |
  重建视频                                 |
        |                                  |
        v                                  |
  +----------------------------+           |
  |  评估器:差异 -> 自然语言   |----------+
  |  「反打里丢了画面方向」     |--- 内环 ---> 改这张 KG
  +----------------------------+
核喻:制片厂的场记圣经(continuity bible)。
想象一个电影制作部门。
场记(编码策略)看完片子,写出那本「连戏圣经」:按幕、场、镜分好标签的活页夹(层级节点),每个镜头一页,列出人物、走位、镜头、光线、情绪(状态节点),并用明确的交叉索引互相指认——「参见角色卡 C-3」「接第 214 页」(有类型边)。
光靠文字不够,所以活页夹后面挂着一个道具与选角仓库:定妆照、声音样本、参考片段,每一份都标注属于哪一页(素材层)。
现在做实验:把活页夹交给一个从没看过原片的第二组剧组(解码器),让他们照着拍。
拍完和原片并排放映。
导演的样片笔记就是梯度——但注意,笔记有两种。
「第 214 页漏了视线,去改第 214 页」是关于这部片子的(内环,测试时 KG 精修)。
「我们这套活页夹模板根本没有『画面方向』这一栏,把它加进制片厂标准表格」是关于我们该怎么做笔记的(外环,策略伪训练)。
第二种才是这篇论文真正的贡献,也解释了为什么学出来的表格比老场记多年累加的那份更短:从失败证据出发重新设计的表格,胜过靠不断添加提醒长出来的表格。
关键概念
-
智能体式自编码(agentic auto-encoding):普通自编码器把数据挤过一个窄瓶颈,用重建误差训练,梯度穿过两端。这里两端都是 LLM 智能体,瓶颈是一份文档,什么都不可微。但**逻辑*活下来了:重建错了,说明编码时漏了东西,而「漏了什么」正好告诉你下次该记什么。举个具体例子——你在电话里描述一张照片,朋友照着画,你俩对比。你不需要微积分就能学到「以后一定要说清人物朝哪边」。整篇论文就是把这个把戏从照片搬到电影。
-
文本梯度(textual gradient):梯度不过是「往哪个方向走误差会变小」。数字能在权重空间里做这件事,句子能在 prompt 空间里做同一件事。你拿到的不是
dL/dw = 0.03,而是「编码器一直忽略声音的转场」,于是你照着改指令。它继承了梯度下降的形状——被误差评估驱动的、反复的小步定向修改——但不带数学;它也继承了病症:噪声大、会震荡、没有线搜索。(这一脉来自 TextGrad / DSPy 式的 prompt 优化;本文的新意在于**信号从哪来*。) -
数据无关 vs 数据相关优化:区别在于更新落到哪里。数据无关(外环,「伪训练」)改的是**编码器*,此后每部片子都受益——这是训练,也正因如此他们才能做「仅策略」对照人工精调 prompt 的实验。数据相关(内环,测试时)改的是一张图,只有这部片受益——这是推理期修补。类比:改的是全诊所通用的问诊表,还是改某一位病人的病历。把这两者混在一起的论文往往会夸大结论;把它们分开,才让那个「受控仅策略设定」的结果有意义。
框架转变
之前(主流方法):                      之后(本文方法):

 视频                                    视频
   |                                       |
   v                                       v
 [ 像素潜变量 ] 或 [ 散文 ]           [ 有类型 KG + 素材层 ]
   |                    |                |    ^
   | 忠实               | 可编辑         |    | 英文梯度
   | 不透明             | 损失大         |    | 来自重渲染差异
   v                    v                v    |
 智能体:抓不住   智能体:无接地      智能体:查询/编辑/复用
                                             |
 编码 prompt:人手调                  编码策略:伪训练出来
   (无度量,靠累加变长)                (由重建来度量)

 忠实度:FVD / CLIPScore 的感觉        忠实度:一个盲拍剧组
   (无闭环)                            能否复拍出来?(闭环)
一句话:从「表示这段视频」到「表示这份拍摄说明书并靠复拍来验证」,核心转变是把编码器本身变成可优化对象,且只认重建这一个裁判。
专家评审
选题眼光:真缺口,位置也找得准。
任何做创作类智能体的人都撞过同一面墙——你能 prompt 出一个不错的 8 秒镜头,但没有任何载体能让你从一批好电影里学,也没有办法知道你那份中间脚本到底留住了多少原片信息。
把这个载体当成潜编码、把自编码器的纪律引进来,是对的直觉,而且它自然落在「prompt 串接流水线 -> 可优化智能体程序」这条轨迹上。
「创作智能体需要电影级质感」这套动机更像市场话术而非论证,但底下那个技术缺口本身站得住。
方法成熟度:有巧劲,工程部分承重,但有一处软肋。
真正好的想法是用重建来监督编码策略而不是单个实例的表示——这是 demo 和方法的分界线,而 token 缩减那个数字之所以最有说服力,恰恰因为它是受控的仅策略对比。
素材层是诚实的工程:他们注意到文本装不下身份信息,就不再假装能装。
软肋在于,素材层同时也悄悄削弱了「自编码器」这个框架。
如果任意生成的图像和片段都能塞进「潜表示」,那瓶颈就是可谈判的,而摘要里没有告诉我们信息有多少住在文本里、多少住在缓存的像素里。
一条率-失真式的曲线——忠实度随素材预算变化——就能判定这到底是压缩还是一个组织良好的缓存。
值得排除的更简单替代:固定手工 schema + 强 VLM 填槽;或者不要图、直接用 DSPy/TextGrad 对着 VLM 裁判做 prompt 优化。
KG 相对于「带引用的结构化 JSON」的增量价值,被断言得多,被隔离验证得少。
实验诚意:谨慎偏正面,而且仅凭摘要我无法核实内部细节。
「比最强外部基线 +20.7 个百分点」是个很大的跳跃,而自建基准上的大跳跃通常意味着基线本来就不是为这个基准造的——captioning 模型和人工 prompt 的故事板流水线并没有在追求「可重建」。
这不算作弊,但让这个数字更像是在陈述任务的新颖性,而不是方法的优越性。
真正承重的担忧是评估器:如果重建忠实度由 VLM 裁判打分,而来自同一个裁判的文本梯度又去调编码器,你就有了一个能学会讨好裁判的闭环。
人工评测、留出裁判、或换裁判的消融,是我第一个要看的东西。
摘要还没回答的另一点:这个表示对下游有用吗?
宣称的动机是拍出更好的片子;重建忠实度只是代理指标,目前还没人展示智能体编辑 KG 之后真的产出了更好的成片。
写作功力:摘要里塞满了首字母大写的专名——「Data-Independent Encoding Policy Pseudo-Training」「Data-Dependent KG Representation Refinement」——它们承载的信息比被替换掉的朴素说法还少;而「伪训练」这个词在明显地做对冲工作,值得用一句老实话把它定义清楚。
我会重写的是评估那一节:说清指标、说清谁来打分,并把真正重要的消融放到前面(同等素材预算下 KG vs 扁平文本;关掉外环;换裁判)。
术语包装的用力程度,明显超过了对度量方式的解释。
判决:弱接收 —— 「用重建监督编码策略」是个真正可迁移的想法,开源的工件也相当扎实,但头条增益建立在自建基准和一个可能循环的裁判上,且下游价值未被验证。
要点总结
真能「偷」走的东西:
- 把重建当作不可微流水线的监督信号。 只要智能体在从富输入中抽取结构,你就能造一个解码器把输入重生成,用差距当作免费、无标注、自动的监督。这招在文档、代码库、UI 录屏、病历上都成立——凡是「你有没有留住关键信息」难以直接问、而「你能不能重建它」很容易问的场合。
- 优化策略,而不是优化输出。 数据无关(修抽取器)与数据相关(修这一条记录)的区分是全文最干净的框架。大多数 prompt 调优工作把两者悄悄混在一起,然后说不清自己到底学到了什么。把它们放在分开的环里,并分开汇报。
- 预期学出来的 prompt 比手调的更短。 74.3% 这个缩减是最实用的头条:人写的 prompt 是靠累加长大的——每次失败加一条提醒,从来没有东西被删掉。而一个从失败证据出发重写的优化器会做重组,而不是追加。如果你在维护一份又长又手调的系统 prompt,这就是「拿测试集把它重新生成一遍」的理由。
- 给你的文本表示留一个素材逃生口。 事先判定哪些内容天生无法文本化,把它们存成有类型的指针,而不是硬用文字描述一张脸——这个设计模式能迁移到任何「LLM 当结构化抽取器」的系统。
- 给边加类型。 图之所以胜过散文,不是表达力,而是可遍历性:智能体能查询和修补
shot_14 -> cuts_to -> shot_15,却没法修补一个句子。如果你想让智能体编辑你的表示,就让每一种关系都可被命名。
不要盲信的部分:具体的数字,直到你看清裁判是谁。