Paper: 2608.06362 Authors: Boning Li, Yu Chen, Longbo Huang Categories: cs.GT, cs.AI, cs.CL, cs.LG, cs.MA
The Gap
Two threads of prior work each solve half of this problem, and nobody had spliced them.
Thread one: variance reduction in imperfect-information games. Poker payoffs are brutally noisy — one cooler hand can swing a hundred hands’ worth of edge. AIVAT (Burch et al., 2018) attacks this by subtracting a conditionally mean-zero correction built from a value function plus “imaginary observations” over the actions and cards that *could have happened. It keeps the estimator unbiased and, in this paper’s runs, cuts variance by a median 54x across 15 LLM agent configurations on 71,439 paired Heads-Up No-Limit Hold’em hands. What AIVAT does not do is tell you when you have seen enough. It hands you a tighter estimate at whatever sample size you happened to choose.
Thread two: anytime-valid inference. Confidence sequences (Howard et al.; Waudby-Smith & Ramdas) give you an interval you may look at after every single observation, with one global coverage promise. They solve the stopping problem but do nothing about the noise itself.
So today’s practitioner is stuck choosing between two bad options. Fix a budget of N hands up front: either the verdict was settled at hand 3,000 and you burned inference credits through hand 100,000, or N was too small and the intervals still overlap. Or peek at an ordinary 95% confidence interval and stop when it looks good — which quietly destroys the 95%, because you cherry-picked the moment.
The subtle obstacle to just gluing the two together: a confidence sequence needs the summands to behave like martingale increments. If your value model is fit on all the data, hand t helps build its own correction, the mean-zero property breaks conditionally, and the anytime-valid guarantee evaporates. That measurability discipline is the paper’s real hinge.
[Problem] two agents, noisy payoffs, unknown number of games needed
    |
    +--> fixed budget N: overpay past the verdict .. or .. stop too early
    +--> peek at an ordinary 95% CI: the stated level is a lie
    |
    v
[Prior art] AIVAT: conditionally mean-zero corrections -> variance / 54
            ...but silent on WHEN to stop
    |
    v
[Assumption] build corrections ONLY from past games
             => corrected payoff x_t is a martingale increment
    |
    v
[Method] AV-AIVAT = AIVAT (variance) + Confidence Sequence (anytime-valid)
    |                                          |
    v                                          v
 AsympCS: asymptotic screening          EB-CS: exact, needs |x_t| <= B
    |                                          |
    v                                          v
[Evidence] median 74x fewer hands       Leduc: B proved structurally
 71,439 HUNL hands / 15 configs         HUNL: only 1.37x (width floor)
    |                                          |
    +---------------------+--------------------+
                          v
[Conclusion] stop the moment evidence suffices; the exact-certification
 lane pays a standing price for needing a boundedness constant
The Increment
One sentence: Before, you picked a hand count and hoped; after, the evaluation itself decides when to halt, with a guarantee that survives continuous peeking — and with an honest accounting of how much of a 54x variance win actually converts into earlier stopping (a lot under asymptotic screening, very little under exact certification).
Core Mechanism
The pipeline is a three-stage conveyor. Stage one plays hand t and records the raw payoff in big blinds. Stage two computes the AIVAT correction using a value model whose parameters were frozen before hand t began — trained online, but strictly on hands 1 through t−1. Subtracting that correction gives a corrected payoff with the same mean as the raw one and roughly 1/54 the variance. Stage three feeds the corrected sequence into a confidence sequence and checks a single stopping rule: is the interval now narrower than ±1 big blind? If yes, stop and report; if no, play another hand.
The “no game scores its own correction” constraint is what makes stage three legal rather than decorative. Because the correction at time t is measurable with respect to the past, its conditional expectation is exactly zero given everything seen so far, so the corrected payoffs form a martingale-increment sequence around the true skill difference. Confidence sequences are built on exactly that structure, which is why optional stopping doesn’t cost you anything here.
Then the paper splits the road, and this is the part worth reading carefully. The Asymptotic CS needs no bound on the data and delivers the headline: raw outcomes need a median 74x as many hands to reach ±1 BB as corrected outcomes. But it is asymptotic — good for screening, not for certifying. The Empirical-Bernstein CS gives exact finite-sample coverage, but its width carries a term proportional to a bound *B on the corrected payoffs, divided by the CS’s betting cap. That term shrinks with t but not with variance. So there is a width floor: once the variance term drops below the range term, further variance reduction buys you almost nothing. The authors prove such a *B structurally for Leduc hold’em; for HUNL no independently justified bound exists, so those EB-CS runs are labeled descriptive, and the stopping-time ratio there is a median 1.37x. The gap between 74x and 1.37x is the paper’s most informative number.
hand t:  hole cards, betting actions, showdown
   |
   v
+-------------------------------+
|  raw payoff  u_t  (big blinds)|   variance: enormous
+-------------------------------+
   |
   |     value model V_(t-1)  . fit ONLY on hands 1..t-1
   |             |
   v             v
+-------------------------------+
| AIVAT correction c_t          |   E[ c_t | past ] = 0  exactly
|  = value baseline             |   (this is why peeking stays legal)
|  + imaginary observations      |
+-------------------------------+
   |
   v
 x_t = u_t - c_t        same mean, ~ variance / 54
   |
   v
+---------------------------------------------+
| Confidence Sequence on x_1 .. x_t           |
|   L_t <= mu <= U_t   for ALL t simultaneously|
|                                             |
|   AsympCS : no bound needed, asymptotic     |
|   EB-CS   : exact, needs |x_t| <= B         |
|             width >= floor( B / bet cap )   |
+---------------------------------------------+
   |
   v
 (U_t - L_t) <= 2 BB ?  --- no ---> play hand t+1
   |
  yes
   v
 STOP . publish (t, x_1..x_t, model checkpoints) for third-party recheck
The metaphor: weighing two suitcases on a certified scale, aboard a rocking boat.
The suitcases are the two agents; the weight difference is the true skill gap. The bathroom scale is your payoff measurement, and the boat’s rocking is variance — one big wave and the display says either agent is 40 pounds heavier.
AIVAT is an accelerometer bolted to the deck: it measures the wave motion and subtracts it from the reading. Crucially, the accelerometer is calibrated only on waves that already passed — if you let it calibrate on this instant, it would happily “explain away” the actual weight difference as wave motion, and your reading would be biased. That is the past-only value model.
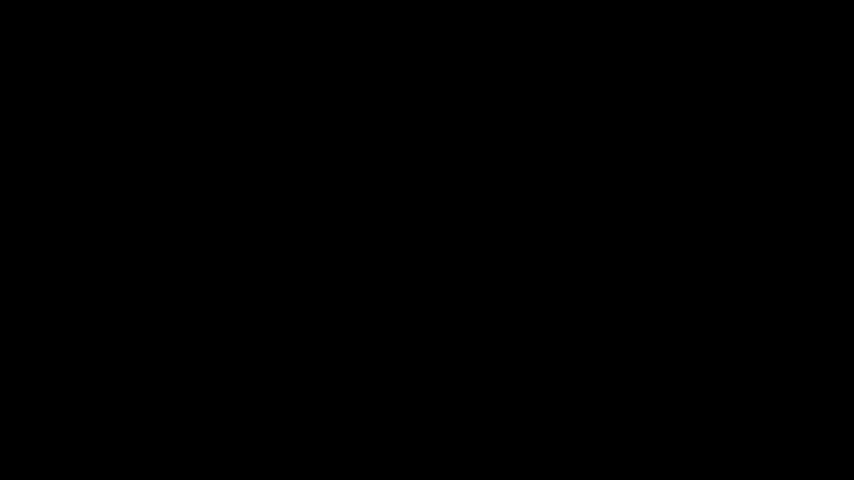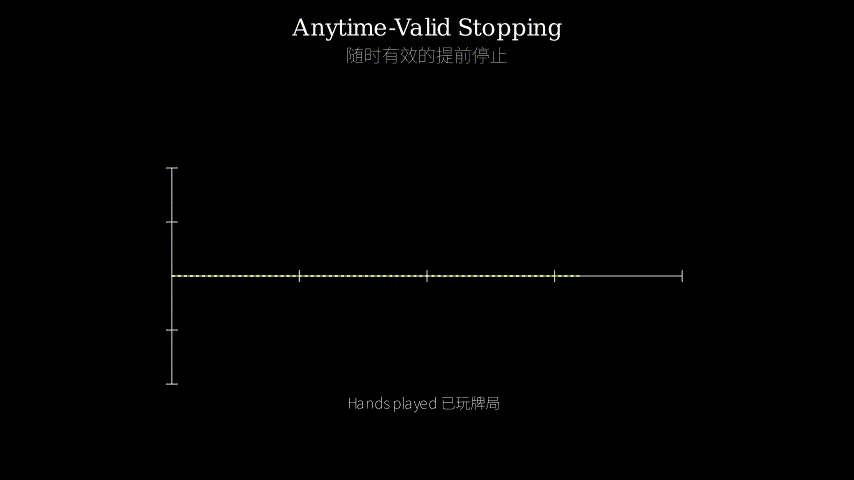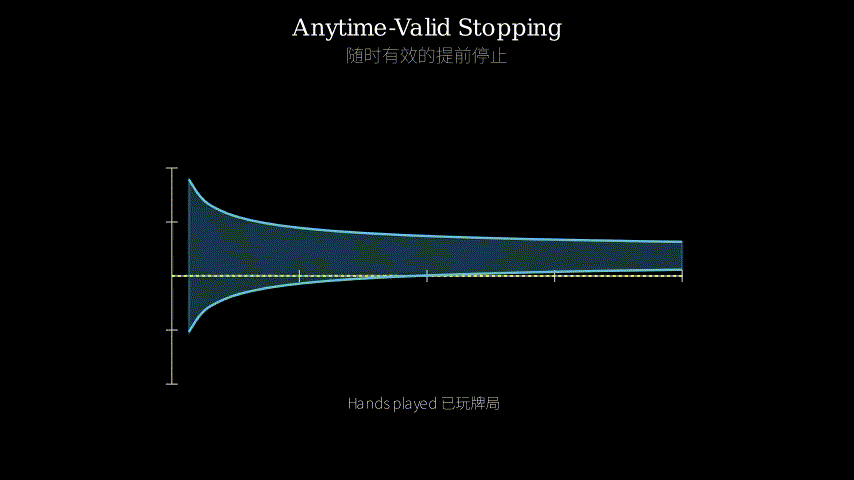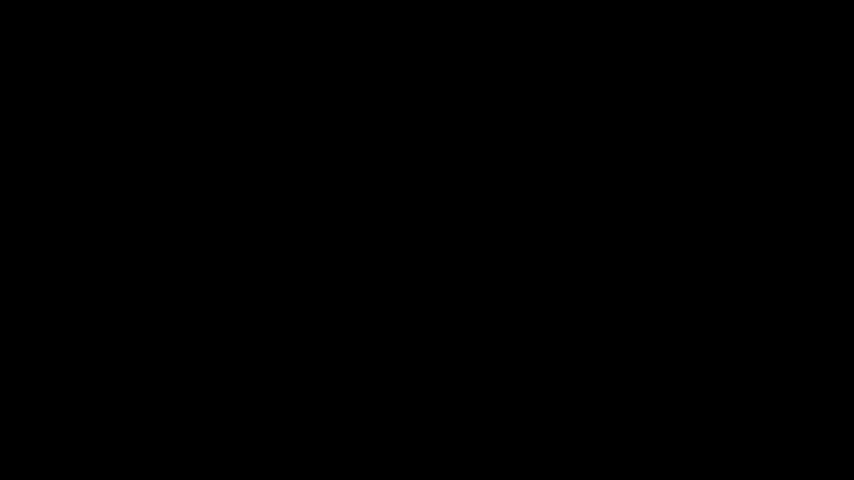
The confidence sequence is a different kind of display. A normal scale certifies its reading only if you take exactly one reading after settling for a fixed time; if you stare at the flickering number and grab the moment it looks tightest, the certification is void. The CS display instead carries a single guarantee that holds at every instant, so you may watch it and stop the second the error bar fits inside ±1 BB.
And the two CS flavors are two classes of scale. AsympCS is the kitchen scale: quick, unbounded, good enough to tell which suitcase is heavier. EB-CS is the legally sealed trade scale used in commerce — but a sealed scale requires a declared maximum load stamped on it, and its smallest readable division is tied to that declared maximum. That division is the width floor. On a glassy calm sea the kitchen scale keeps getting more precise; the sealed scale hits its tick marks and stops improving. Which is exactly why 54x variance reduction becomes 74x on one and 1.37x on the other. The paper’s Leduc proof is the act of legitimately stamping a maximum load on the scale; for HUNL, nobody has stamped it yet.
Key Concepts
-
Why peeking breaks a confidence interval (and what fixes it): An ordinary 95% CI is a promise about *one pre-declared moment: “if you compute me at hand 10,000, I cover the truth 95% of the time.” It says nothing about a person who computes it at hands 100, 200, 300, … and stops at the first one that looks decisive. That person is cherry-picking from a hundred flickering intervals, and their real error rate can be several times the nominal. A confidence sequence changes the quantifier: it is an infinite family of intervals with one joint promise — with probability 95%, no interval in the whole sequence ever misses the truth. Once that holds, stopping whenever you like is free, because your stopping rule can only pick a time from a family that is already all-correct. Concretely: instead of “playing until 10,000 hands then testing,” you get a live-updating bracket you may cash out at hand 2,317 with the same 95% behind it.
-
Conditionally mean-zero corrections (control variates, done carefully): Suppose you want to know if a new coffee blend raised daily sales. Sales swing wildly with weather. If you have a weather-based sales predictor, subtract its prediction from each day’s sales: the average is unchanged as long as the prediction errors average to zero, but the day-to-day swing collapses. AIVAT is this idea specialized to poker — its “weather” is the cards dealt and the actions taken, and it also averages over the hands and actions that *could have occurred (the imaginary observations), which is why it can strip out so much luck. The catch that most people get wrong: the predictor must not have seen today’s sales. Otherwise it absorbs the very signal you are measuring.
-
The width floor: The empirical-Bernstein interval width is roughly (variance term) + (range term), where the range term depends on your assumed bound *B on the data and on how aggressively the underlying betting scheme is allowed to wager. Variance reduction only shrinks the first term. So there is a point past which making your estimator quieter does not make your certificate tighter — you are floor-limited by the boundedness assumption you needed in order to be exact at all. This is a genuinely useful piece of engineering intuition: an exact finite-sample guarantee is not free, and it is priced in units of B.
Framework Shift
Before (mainstream approach):            After (this paper):

  choose N = 100,000 up front              play hand t
        |                                      |
        v                                      v
  play all N hands  ($$$$$)             AIVAT-correct with a PAST-only model
        |                                      |
        v                                      v
  compute ONE CI at the end             read CS interval [L_t, U_t]
        |                                      |
        +--> too wide: wasted run             width <= 2 BB ?
        +--> settled at hand 3k:               |         |
             90% of spend was noise           no        yes
                                               |         |
   ( peeking early == level is void )      loop back    STOP + audit bundle

  guarantee: at time N only              guarantee: at ALL times at once
  cost: fixed, chosen by guesswork       cost: adaptive, set by the evidence

                                         two lanes, kept honest:
                                          AsympCS  -> screening (74x)
                                          EB-CS    -> certification (1.37x,
                                                      floor-limited by B)
From a pre-declared sample size to an evidence-triggered halt, the core shift is that the guarantee moves from a single moment to every moment, which turns variance reduction into a direct saving in games played — up to a floor that exact certification imposes.
Expert Assessment
Problem choice: Real gap, well chosen, and timely. Evaluating LLM agents by self-play is now a line item with actual dollars attached, and imperfect-information games are the worst case for signal-to-noise. Anytime-valid inference has been rediscovered by the ML community over the last five years but has barely touched game-playing agent evaluation, where the payoff variance is precisely the thing that makes fixed budgets wasteful. Sitting AIVAT — a 2018 poker-community tool — next to confidence sequences is an obvious-in-hindsight pairing that nobody had done properly. The honest framing is that this is a well-executed bridge, not a new continent.
Method maturity: Clever in one specific place and standard everywhere else. The one real technical insight is enforcing that the value model is fit only on the past, so the corrected payoffs stay martingale increments and optional stopping remains legal. That trick is well known in adjacent literatures (sequential sample splitting in doubly-robust off-policy evaluation, prediction-powered inference), so the contribution is recognizing that AIVAT’s guarantee is fragile in exactly this way and repairing it, rather than inventing new machinery. The width-floor characterization is the part I’d keep: it converts a vague worry into a quantitative statement about when variance reduction stops paying.
What I think is underexplored: EB-CS may simply be the wrong exact tool here. Betting-based confidence sequences with variance-adaptive wagering, or sub-exponential/sub-gamma mixture boundaries that need tail control rather than a hard bound, could plausibly recover much more than 1.37x without needing a structural B at all. Truncating or Winsorizing corrected payoffs at a data-driven level is another cheap route to a defensible bound. The paper’s own framing — “exact certification is floor-limited” — is really a statement about EB-CS specifically, and I’d want it tested against those alternatives before accepting it as a general law.
Experimental integrity: Better than average, mainly because the authors did not hide the deflating number. Reporting 74x under AsympCS and 1.37x under EB-CS in the same abstract, and explicitly labeling the HUNL EB-CS runs “descriptive” because the bound is not independently justified, is the behavior of people trying to be right rather than impressive. Paired hands and 15 configurations over 71,439 hands is a respectable scale for this kind of study, and medians rather than means is the correct summary for stopping times.
Two things to keep an eye on. First, the title. “74x cheaper” plus “certified anytime-valid stopping” in one line invites the reading that you get 74x and certification; you do not — the 74x comes from the asymptotic procedure, the certified procedure gives 1.37x. That is disclosed in the abstract, so it is spin rather than misrepresentation, but it is spin. Second, 54x variance reduction yielding a 74x stopping-time ratio is roughly what the arithmetic predicts once you account for the running variance estimate and log factors, so the 74x is not an extra win on top of AIVAT — it is AIVAT’s variance win, expressed in the currency of hands. And note that all of this inherits AIVAT’s dependence on value-model quality; a weak online model on unfamiliar agents will not deliver 54x, and I would want the spread across those 15 configurations, not just the median, before budgeting on it.
Writing quality: The abstract is doing too much — it tries to carry the motivation, both CS variants, the Leduc theory, the width floor, and two headline numbers, and the result is dense enough that a casual reader will take away “74x” and nothing else. The section I would most want rewritten is the value-model specification: everything downstream depends on what the online model is, how fast it warms up, and what happens during the early hands when it is nearly uninformative, and that deserves a foregrounded treatment rather than a mention. Second priority: a short worked example turning the width-floor formula into a practitioner’s rule of thumb — “given range bound *B and target precision, here is the smallest sample size any exact certificate can achieve” — would be the single highest-value paragraph in the paper.
Verdict: weak accept — a correct, honestly reported, immediately usable splice of two mature tools, whose main claim to certification only partly delivers and whose exact-inference pessimism may be an artifact of one specific confidence sequence.
Takeaways
Things worth stealing regardless of whether you care about poker:
-
The past-only fitting discipline is the transferable core. Any time you use a learned model to reduce variance in an estimate you intend to monitor continuously — off-policy evaluation, A/B tests with ML-based covariate adjustment, LLM-judge-assisted benchmarks — fit the helper model strictly on data preceding each point. It costs you a little statistical efficiency and buys you the right to peek whenever you want. This is the single most reusable idea here.
-
Price your guarantee in the right currency. The paper’s real lesson is that a 54x variance reduction is worth 74x under an asymptotic bound and 1.37x under an exact one. Before celebrating a variance win, check which term in your interval width it actually attacks. If a range or boundedness term dominates, your noise reduction is invisible.
-
Two lanes, declared explicitly. Running a cheap asymptotic procedure for screening and a strict finite-sample procedure for the final verdict — and saying which is which — is a template worth copying for any expensive evaluation pipeline. Most papers pick one and quietly let readers assume it does both jobs.
-
Ship the audit bundle. Stopping at a data-dependent time is exactly where reviewers get suspicious, so emitting the stopping time, the corrected sequence, and the model checkpoints so a third party can recheck the verdict *at that stopping time is a cheap practice that makes adaptive experiments defensible.
-
A caution to steal too: getting a defensible bound on your corrected values is the hard part, not the algorithm. They could prove it for Leduc, a toy game; they could not for HUNL. If your plan involves exact finite-sample certification of a learned-correction estimator, budget real effort for that bound, or choose an inference tool that does not need one.
论文: 2608.06362 作者: Boning Li, Yu Chen, Longbo Huang 分类: cs.GT, cs.AI, cs.CL, cs.LG, cs.MA
缺口
这个问题此前被两条互不相交的研究线各解决了一半,没人把它们焊起来。
第一条线:不完全信息博弈的方差削减。 扑克的收益噪声极大——一手 cooler 牌能抹掉上百手积累的优势。
AIVAT(Burch 等,2018)的做法是减去一个「条件期望为零」的修正项,这个修正项由价值函数加上「想象观测」(对那些本可能发生的牌与动作取平均)构成。
它保持估计无偏,而在本文的实验里,横跨 15 种 LLM 智能体配置、71,439 手配对的单挑无限注德扑(HUNL),方差中位数下降 54 倍。
但 AIVAT 从不告诉你「够了」。它只是在你随手挑定的样本量上给你一个更紧的估计。
第二条线:任意时刻有效推断。 置信序列(Howard 等;Waudby-Smith & Ramdas)给你一个每来一个观测都可以看一眼的区间,而整条序列只共享一个覆盖率承诺。
它解决了「何时停」,但对噪声本身毫无帮助。
于是今天的实践者只能在两个坏选项里挑。
预先定 N = 10 万手:要么第 3000 手胜负其实已定,你却一路烧推理额度烧到第 10 万手;要么 N 太小,区间还叠在一起分不出高下。
或者盯着普通的 95% 置信区间,看着顺眼就停——这悄悄毁掉了那个 95%,因为你在挑时刻。
真正微妙的障碍在于:置信序列要求求和项具备鞍差(martingale increment)结构。
如果你的价值模型用全部数据拟合,那么第 t 手参与了构造自己的修正项,条件均值为零的性质就断了,任意时刻有效的保证随之蒸发。
这条「可测性纪律」才是全文的枢轴。
[问题] 两个智能体,收益噪声大,需要多少局事先未知
    |
    +--> 固定预算 N:胜负已定还在付钱 .. 或 .. 还没分清就停
    +--> 偷看普通 95% 置信区间:宣称的置信水平是假的
    |
    v
[前人] AIVAT:条件均值为零的修正 -> 方差 / 54
       ...但对「何时停」完全沉默
    |
    v
[假设] 修正项只用过去的对局来构造
       => 修正后收益 x_t 是鞍差序列
    |
    v
[方法] AV-AIVAT = AIVAT(降方差) + 置信序列(任意时刻有效)
    |                                       |
    v                                       v
 AsympCS:渐近,用于筛选            EB-CS:精确,需要 |x_t| <= B
    |                                       |
    v                                       v
[证据] 中位数 74 倍手数节省          Leduc:结构性证出 B
 71,439 手 HUNL / 15 种配置          HUNL:仅 1.37 倍(宽度地板)
    |                                       |
    +--------------------+------------------+
                         v
[结论] 证据一够就停;但「精确认证」这条道
 要为「需要一个有界常数」长期付费
增量
一句话: 以前你拍脑袋定一个手数然后祈祷;现在评测自己决定何时收手,且这个保证经得起连续偷看——同时诚实交代 54 倍方差收益里究竟有多少能兑换成更早停止(渐近筛选下几乎全部,精确认证下微乎其微)。
核心机制
整条流水线是三级传送带。
第一级打完第 t 手,记录以大盲为单位的原始收益。
第二级计算 AIVAT 修正项,用的价值模型参数在第 t 手开打之前就已冻结——在线训练,但严格只看第 1 到 t−1 手。
减掉修正项后得到的修正收益,与原始收益同均值,方差约为 1/54。
第三级把修正后的序列喂进置信序列,只检查一条停止规则:区间是否已窄于 ±1 大盲?是则停并报告,否则再打一手。
「没有一手牌给自己打分」这条约束,是第三级合法而非装饰的原因。
因为 t 时刻的修正项对过去可测,它在已见信息下的条件期望精确为零,于是修正收益构成围绕真实实力差的鞍差序列。
置信序列正是建在这个结构上,所以在这里随意停止不需付任何代价。
接下来论文把路分成两条,这部分值得细读。
渐近置信序列(AsympCS) 不需要对数据设界,给出了那个头条数字:原始收益要达到 ±1 大盲,中位数需要修正后收益的 74 倍手数。
但它是渐近的——适合筛选,不适合认证。
经验伯恩斯坦置信序列(EB-CS) 给出有限样本精确覆盖,但它的宽度里有一项正比于修正收益的界 B、并被下注上限所除。
那一项随 t 缩小,却不随方差缩小。
于是存在一层宽度地板:一旦方差项落到量程项之下,继续降方差几乎买不到任何东西。
作者对 Leduc hold’em 结构性地证出了这样一个 B;对 HUNL 则没有独立成立的界,所以那部分 EB-CS 实验被标注为「描述性」,停止时间比的中位数只有 1.37 倍。
74 倍与 1.37 倍之间的落差,是全文信息量最大的数字。
第 t 手:底牌、下注动作、开牌
   |
   v
+---------------------------------+
| 原始收益  u_t (大盲)           |   方差:极大
+---------------------------------+
   |
   |     价值模型 V_(t-1) . 只用第 1..t-1 手拟合
   |            |
   v            v
+---------------------------------+
| AIVAT 修正项 c_t                |  E[ c_t | 过去 ] = 0 精确成立
|  = 价值基线                      |  (这才是偷看仍然合法的原因)
|  + 想象观测                      |
+---------------------------------+
   |
   v
 x_t = u_t - c_t     同均值,方差约 / 54
   |
   v
+---------------------------------------------+
| 对 x_1 .. x_t 构造置信序列                   |
|   L_t <= mu <= U_t   对所有 t 同时成立        |
|                                             |
|   AsympCS:不需设界,渐近                    |
|   EB-CS  :精确,需要 |x_t| <= B             |
|            宽度 >= 地板( B / 下注上限 )       |
+---------------------------------------------+
   |
   v
 (U_t - L_t) <= 2 大盲 ?  --- 否 ---> 打第 t+1 手
   |
   是
   v
 停止 . 输出 (t, x_1..x_t, 模型快照) 供第三方复核
核喻:在摇晃的船上,用一台检定合格的秤称两只行李箱。
两只行李箱是两个智能体,重量差就是真实实力差。
浴室秤是你的收益测量,船的摇晃就是方差——一个大浪打来,显示屏会说随便哪只箱子重四十斤。
AIVAT 是螺栓固定在甲板上的加速度计:它测出浪的运动,从读数里减掉。
关键在于,这台加速度计只用已经过去的浪来标定——如果让它用「此刻」标定,它会乐呵呵地把真实的重量差也当成浪解释掉,读数就被污染了。
这正是「只用过去数据的价值模型」。
置信序列则是另一种显示屏。
普通秤只在你按规定静置后取唯一一次读数时才算有效;如果你盯着跳动的数字、在它最好看的一瞬间抓下来,检定就作废了。
置信序列的显示屏自带一个在每一个瞬间都成立的承诺,所以你可以一直盯着,误差条一挤进 ±1 大盲就立刻收手。
而两种置信序列,是两类不同的秤。
AsympCS 是厨房秤:快、不需要设量程、足够判断哪只箱子更重。
EB-CS 是贸易结算用的铅封计量秤——但铅封秤必须在铭牌上标明最大称量,而它的最小分度值与那个最大称量绑死。
那个分度值就是宽度地板。
海面越平静,厨房秤越精确;铅封秤却撞上刻度线,从此不再改善。
这就是为什么同样的 54 倍方差削减,在一边变成 74 倍、在另一边只剩 1.37 倍。
论文对 Leduc 的证明,就是合法地在秤上打上最大称量的钢印;对 HUNL,这枚钢印还没人敢打。
关键概念
- 为什么「偷看」会毁掉置信区间,以及怎么补: 普通的 95% 区间是关于某一个预先声明时刻的承诺:「如果你在第 10000 手计算我,我有 95% 的概率盖住真值。」
它对那个在第 100、200、300……手反复计算、并在第一个看起来有结论的时刻停手的人,什么都没承诺。
那个人是在上百个跳动的区间里挑好看的,真实错误率可以是名义值的好几倍。
置信序列改换了量词:它是一个无穷区间族,共享一个联合承诺——以 95% 的概率,整条序列里没有任何一个区间错过真值。
一旦这条成立,想什么时候停都免费,因为你的停止规则只能从一个「已经全对」的族里挑一个时刻。
具体说:不再是「打到 10000 手再检验」,而是一个实时更新的括号,你可以在第 2317 手兑现,背后仍是同一个 95%。
- 条件均值为零的修正项(小心使用的控制变量): 假设你想知道新配方的咖啡有没有提升日销量,而销量随天气剧烈波动。
如果你有一个基于天气的销量预测器,就把每天的预测值从销量里减掉:只要预测误差平均为零,均值不变,但日间波动会塌下去。
AIVAT 就是这个想法在扑克上的特化——它的「天气」是发到的牌和采取的动作,而且它还对那些本可能发生的牌与动作取平均(想象观测),这才是它能剥掉这么多运气成分的原因。
大多数人会踩的坑是:预测器绝不能看过今天的销量,否则它会吸收掉你正要测量的那个信号。
- 宽度地板: 经验伯恩斯坦区间的宽度大致是(方差项)+(量程项),后者取决于你为数据假定的界 B,以及底层下注机制被允许押多狠。
降方差只压缩第一项。
所以存在一个临界点,过了它之后,把估计量弄得更安静,并不会让证书更紧——你被「为了精确而必须引入的有界性假设」卡在地板上了。
这是一条相当实用的工程直觉:有限样本精确保证不是免费的,而且它的价签是以 B 为单位标的。
框架转变
之前(主流方法):                     之后(本文方法):

  事先定下 N = 100,000                   打第 t 手
        |                                    |
        v                                    v
  把 N 手全打完($$$$$)            用「只看过去」的模型做 AIVAT 修正
        |                                    |
        v                                    v
  最后算 一个 置信区间               读置信序列区间 [L_t, U_t]
        |                                    |
        +--> 太宽:整轮白跑              宽度 <= 2 大盲 ?
        +--> 第 3000 手已定胜负:         |          |
             九成花费买的是噪声           否         是
                                          |          |
   (提前偷看 == 置信水平作废)        回到循环   停止 + 审计包

  保证:只在时刻 N 成立               保证:在所有时刻同时成立
  成本:固定,靠猜                    成本:自适应,由证据决定

                                     两条道,明码标价:
                                      AsympCS -> 筛选(74x)
                                      EB-CS   -> 认证(1.37x,
                                                 被 B 卡住地板)
一句话:从「预先声明样本量」到「证据触发停止」,核心转变是保证从一个时刻搬到了所有时刻,于是降方差直接兑换成少打的局数——直到精确认证强加的那层地板为止。
专家评审
选题眼光:真缺口,选得好,也赶上了时候。
用自对局评测 LLM 智能体如今是一笔真金白银的开支,而不完全信息博弈是信噪比最差的场景。
任意时刻有效推断这几年被 ML 圈重新发现,但几乎没进入博弈智能体评测领域——偏偏那里的收益方差正是固定预算最浪费的根源。
把 AIVAT 这个 2018 年的扑克圈工具与置信序列摆在一起,是那种「事后看很明显、但此前没人认真做过」的配对。
诚实的定位是:这是一座修得不错的桥,不是一块新大陆。
方法成熟度:一处巧劲,其余标准件。
真正的技术洞见只有一个:强制价值模型只用过去数据拟合,从而让修正收益保持鞍差结构、让随意停止仍然合法。
这个技巧在邻近文献里并不新鲜(双重稳健离策略评估里的序贯样本切分、prediction-powered inference),所以贡献在于「意识到 AIVAT 的保证恰恰在这一点上脆弱,并把它修好」,而不是发明新机器。
宽度地板的刻画是我会留下的部分:它把一个模糊的担忧变成了「降方差何时停止付费」的定量命题。
我认为被放过去的方向:EB-CS 可能根本就是这里的错误工具。
方差自适应下注型置信序列,或者只需尾部控制而不需硬界的次指数/次伽马混合边界,很可能在完全不需要结构性 B 的前提下拿回远超 1.37 倍的收益。
把修正收益按数据驱动的分位截断(truncation / Winsorization)也是一条廉价的、可辩护的设界路线。
论文自己的说法——「精确认证受地板所限」——其实是关于 EB-CS 这一具体工具的陈述;在被上述替代方案检验之前,我不会把它当成一条普适定律接受。
实验诚意:高于平均水平,主要因为作者没有藏起那个泄气的数字。
在同一段摘要里同时报出 AsympCS 下的 74 倍和 EB-CS 下的 1.37 倍,并且因为界没有独立依据而把 HUNL 的 EB-CS 实验明确标为「描述性」,这是想把事情做对、而不是想做得好看的人的行为。
15 种配置、71,439 手配对牌局,对这类研究是体面的规模;用中位数而非均值总结停止时间也是正确选择。
有两处要留个心。
第一是标题。「74 倍更便宜」和「可认证的任意时刻有效停止」并排出现,会诱使人读成「你既拿到 74 倍又拿到认证」——并非如此:74 倍来自渐近方法,被认证的方法给的是 1.37 倍。
摘要里已披露,所以这是包装而非误导,但它确实是包装。
第二,54 倍方差削减对应 74 倍停止时间比,在把滚动方差估计和对数因子算进去之后,大致就是算术会预测的结果,所以 74 倍不是 AIVAT 之上额外的胜利——它就是 AIVAT 的方差收益,只是换成了「手数」这种货币来表达。
另外,这一切都继承了 AIVAT 对价值模型质量的依赖:在陌生对手上用一个弱在线模型,拿不到 54 倍;在拿它做预算之前,我想看 15 种配置上的离散程度,而不只是中位数。
写作功力:摘要负担过重——它想同时承载动机、两种置信序列、Leduc 理论、宽度地板和两个头条数字,结果密到只有「74 倍」会被随手翻过的读者带走。
我最想重写的一节是价值模型的规格说明:下游的一切都取决于这个在线模型是什么、热启动多快、以及在它几乎没有信息量的最初若干手里会发生什么,这值得放到前台正面处理,而不是一笔带过。
其次是:把宽度地板公式化成一条实践者的经验法则并配个算例——「给定量程界 B 和目标精度,任何精确证书能达到的最小样本量是多少」——那会是全文性价比最高的一段。
判决:弱接收 —— 一次正确、诚实报告、且可以立刻用起来的成熟工具嫁接;但它的「认证」主张只兑现了一半,而它对精确推断的悲观结论可能只是某一种置信序列的产物。
要点总结
不管你关不关心扑克,下面这些值得偷走:
- 「只用过去拟合」这条纪律是最可迁移的核心。 只要你打算用一个学出来的模型去降低某个「你会连续监控」的估计量的方差——离策略评估、带 ML 协变量调整的 A/B 测试、LLM 打分辅助的基准测评——就让辅助模型严格只用每个数据点之前的数据来拟合。
这会损失一点统计效率,换来的是随时偷看的权利。
- 用正确的货币给你的保证定价。 本文真正的教训是:54 倍方差削减在渐近界下值 74 倍,在精确界下只值 1.37 倍。
在为方差胜利庆祝之前,先看它究竟攻击了区间宽度里的哪一项。
如果主导项是量程项或有界性项,你的降噪是隐形的。
- 两条道,明确声明。 用便宜的渐近方法做筛选、用严格的有限样本方法做最终裁决,并且明说哪个是哪个——这个模板值得任何昂贵评测流水线抄走。
多数论文只选一个,然后默默让读者以为它兼任两职。
-
把审计包一起交出去。 在数据决定的时刻停止,恰恰是审稿人最容易起疑的地方;因此输出停止时间、修正后序列与模型快照,让第三方能在那个停止时刻复核结论,是一条让自适应实验站得住脚的廉价做法。
-
也偷走一条警告: 难的不是算法,而是为你的修正值拿到一个能辩护的界。
他们能在 Leduc 这种玩具博弈上证出来,在 HUNL 上证不出来。
如果你的计划涉及对「带学习修正的估计量」做有限样本精确认证,请为这个界预留真实的工作量,或者干脆换一个不需要它的推断工具。