Paper: 2603.08181 Authors: Sidharth Sinha, Anson Bastos, Xuchao Zhang, Akshay Nambi, Chetan Bansal, Saravan Rajmohan Categories: cs.LG
The Gap
LLMs work great on Wikipedia but choke on your company’s legal documents. The standard fix—domain adaptation—is currently a PhD student’s weekend project: manually tune learning rates, pick data augmentation strategies, decide between LoRA ranks, all while burning GPU credits. Existing AutoML tools (FLAML, Optuna) treat this as generic black-box optimization, ignoring decades of accumulated wisdom about what actually works for LLM fine-tuning. The core problem: hyperparameter search spaces are enormous, training runs are expensive, and the knowledge of what configurations transfer across domains lives in scattered papers and engineer folklore, not in any system.
Problem: Manual LLM adaptation = expensive guesswork
   |
   v
Assumption: Domain adaptation knowledge exists but is scattered
   |
   v
Method: Multi-agent debate (planning) + LLM surrogate (optimization)
   |
   v
Evidence: 25% accuracy gain over AutoML baselines on 10 tasks
   |
   v
Conclusion: Codified expertise beats blind search under budget constraints
The Increment
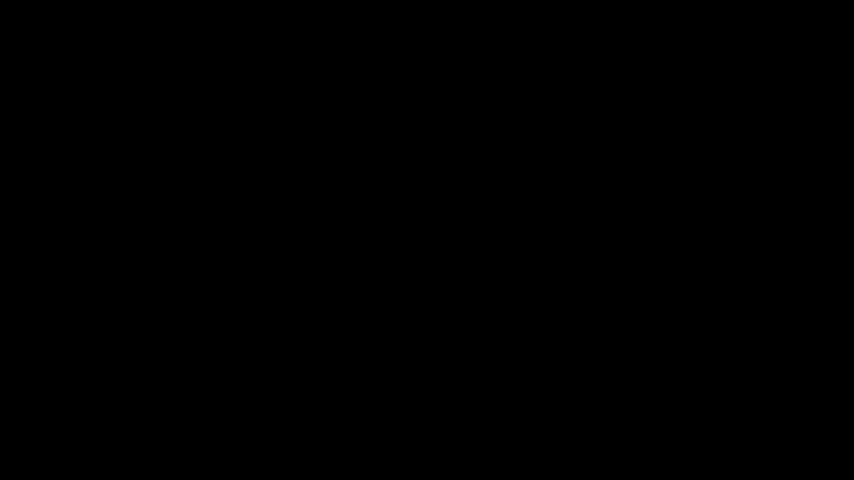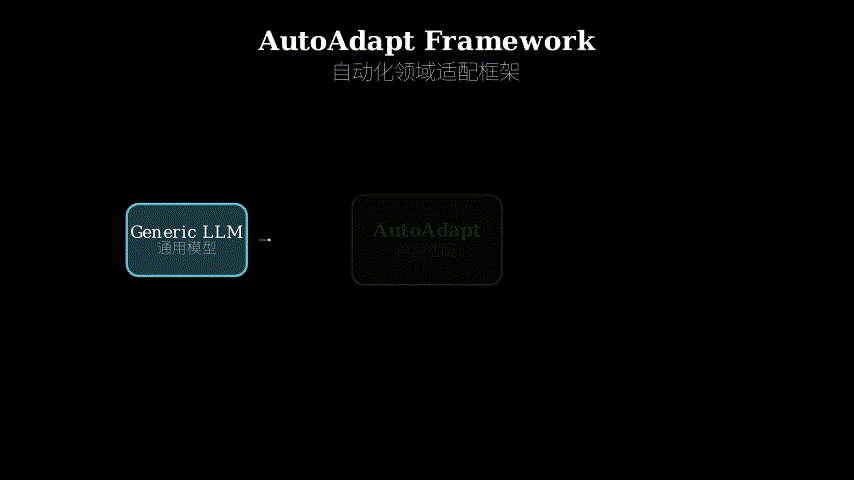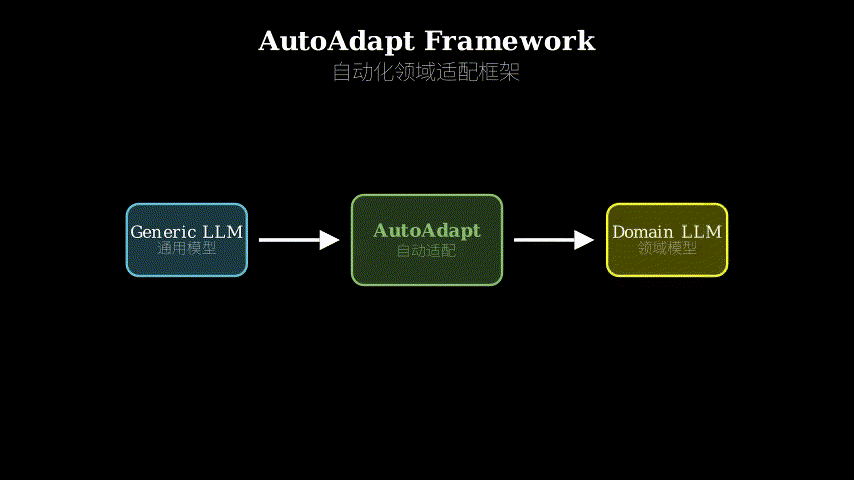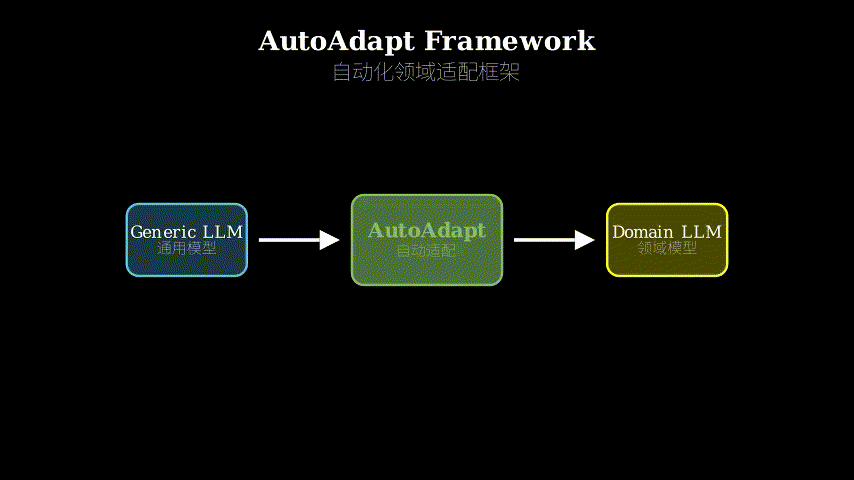
One sentence: Before AutoAdapt, you needed an expert to babysit every domain adaptation run; after, you feed in your task description and data, and the system proposes a sensible adaptation strategy automatically.
Core Mechanism
AutoAdapt has three stages. First, a knowledge base stage scrapes best practices from papers and GitHub repos—things like “use LoRA for parameter-efficient tuning” or “medical domains benefit from continued pretraining.” This gets encoded into a structured KB that the system can query.
Second, a planning stage where two LLM agents debate. The Proposal Agent suggests an adaptation strategy (which techniques to use, rough hyperparameter ranges). The Critic Agent pokes holes in it using data characteristics and KB constraints. They go back and forth until converging on a plan that’s both theoretically sound and data-appropriate. This narrows the search space from thousands of possible configurations to a focused region.
Third, an optimization stage using AutoRefine—an LLM that acts as a surrogate model. Instead of actually training the LLM on every candidate configuration (expensive), AutoRefine predicts performance based on the configuration and past results. It iteratively refines hyperparameters by reasoning about what changes might help, then validates only the most promising candidates with real training runs.
User Input (task + data)
   |
   v
+------------------+
| Knowledge Base   |  <--- Papers, GitHub, best practices
+------------------+
   |
   v
+------------------+
| Multi-Agent      |
| Debate System    |
|                  |
| Proposal Agent   |  <---> Critic Agent
|   (suggests)     |        (challenges)
+------------------+
   |
   v
Narrowed Search Space
   |
   v
+------------------+
| AutoRefine       |
| (LLM Surrogate)  |
|                  |
| Predicts perf    |
| Refines params   |
+------------------+
   |
   v
Final Configuration --> Train LLM --> Adapted Model
Think of AutoAdapt as a consulting firm for your LLM. The Knowledge Base is the firm’s library of case studies and industry reports. The Proposal and Critic agents are two senior consultants who hash out a strategy in a conference room—one’s optimistic, one’s skeptical, and the friction produces a realistic plan. AutoRefine is the junior analyst who runs financial models to test different scenarios without actually executing the full business plan each time. Only when the consultants agree and the models look good do you commit resources to the real implementation.
Key Concepts
-
Multi-Agent Debate for Planning: Instead of having one LLM generate a plan (which might be overconfident or miss edge cases), you have two agents argue. The Proposal Agent is like a startup founder pitching ideas—“let’s use 4-bit quantization and aggressive data augmentation!” The Critic Agent is the VC asking hard questions—“your dataset is only 500 examples, won’t aggressive augmentation overfit?” This adversarial setup surfaces assumptions and forces the system to justify choices against both theory (KB) and data reality. The output isn’t just a configuration, it’s a configuration with a paper trail of why each decision was made.
-
LLM-Based Surrogate (AutoRefine): Traditional hyperparameter optimization treats the model as a black box: try config A, get accuracy X, try config B, get accuracy Y, use Bayesian optimization to guess config C. This is sample-inefficient when each sample costs $50 in GPU time. AutoRefine instead uses an LLM to reason about configurations. You show it past results and ask “if I increase the learning rate from 1e-4 to 5e-4, what happens?” It generates a prediction with reasoning (“higher LR might help escape local minima but risks instability given the small batch size”). You only run real training on configs where the LLM’s reasoning is confident and promising. It’s like having a domain expert in the loop who can extrapolate from limited data.
-
Knowledge Base Curation: The KB isn’t just a dump of papers—it’s structured around decision points. For each adaptation technique (LoRA, prefix tuning, continued pretraining), it stores: when to use it (data regime, domain characteristics), typical hyperparameter ranges, known failure modes, and interaction effects with other techniques. This lets the agents query “what works for low-resource medical NER?” and get actionable constraints, not just citations. The curation process itself is semi-automated: scrape papers for method descriptions, extract hyperparameters from code repos, then have an LLM organize it into a queryable schema.
Framework Shift
Before (mainstream approach):        After (this paper):

Human Expert                         Knowledge Base
    |                                     |
    v                                     v
Manual Config                        Multi-Agent Debate
    |                                     |
    v                                     v
Black-Box Search                     LLM Surrogate (AutoRefine)
(Optuna/FLAML)                           |
    |                                     v
    v                                Predicted Performance
Expensive Training Runs                   |
    |                                     v
    v                                Selective Training
Final Model                          (only promising configs)
                                          |
                                          v
                                     Final Model

Trial-and-error loop                 Plan-then-optimize loop
From blind search over a vast space to informed search over a curated space, the core shift is replacing sample efficiency with reasoning efficiency.
Expert Assessment
Problem choice: This is a real gap. Anyone who’s fine-tuned an LLM for a specific domain knows the pain—there’s no principled way to set hyperparameters, and the cost of exploration is prohibitive. The problem sits at the intersection of AutoML (mature but domain-agnostic) and LLM adaptation (ad-hoc but domain-aware). Timely and practical.
Method maturity: The multi-agent debate is clever—it’s essentially structured prompting with a feedback loop, which sidesteps the brittleness of single-shot generation. AutoRefine is more incremental; LLM-based surrogates have been explored (e.g., in code optimization), but applying them to hyperparameter search is a reasonable extension. The knowledge base curation feels like the weakest link—how do you keep it current as new techniques emerge? The paper doesn’t deeply address KB maintenance or versioning.
Experimental integrity: Baselines are fair (FLAML, Optuna, manual expert tuning). The 25% improvement is averaged across 10 tasks, which is solid breadth. However, the paper doesn’t break down where the gains come from—is it the planning stage, the surrogate, or the KB? Ablations would strengthen the claims. Also, “minimal overhead” is vague—what’s the wall-clock time for the debate and surrogate stages compared to just running more training trials?
Writing quality: The abstract and intro are strong, but the method section tries to cover too much ground without enough depth. The AutoRefine algorithm description is particularly dense—pseudocode would help. The related work section name-drops AutoML tools but doesn’t engage with recent LLM-specific adaptation frameworks (e.g., AdapterHub, PEFT library design choices). Rewriting Section 3.2 (AutoRefine) with a worked example would make the paper much more accessible.
Verdict: Weak accept—the problem is important, the approach is reasonable, and the results are promising, but the paper feels like it’s selling a vision more than a mature system. The KB curation and maintenance story needs work, and the ablations are insufficient to understand what’s actually driving the gains.
Takeaways
The multi-agent debate pattern is immediately stealable. Anytime you’re generating a complex plan or configuration, having two LLMs argue (one propositional, one critical) produces more robust outputs than single-shot generation. You can apply this to infrastructure-as-code generation, API design, or even code review.
The idea of using an LLM as a surrogate for expensive black-box functions is underexplored. If you’re doing any kind of optimization where evaluations are costly (A/B tests, simulation runs, hardware benchmarks), consider whether an LLM can learn to predict outcomes from configuration descriptions. The key is giving it enough structure—not just “predict accuracy” but “reason about why this config might succeed or fail given these constraints.”
The knowledge base approach is less novel but worth noting: if you’re building tools for a specialized domain, don’t assume users will read docs. Encode best practices into a queryable system that can be invoked programmatically. The challenge is keeping it fresh—maybe the real innovation here should be continuous KB updating from community contributions, like a living style guide.
论文: 2603.08181 作者: Sidharth Sinha, Anson Bastos, Xuchao Zhang, Akshay Nambi, Chetan Bansal, Saravan Rajmohan 分类: cs.LG
缺口
大模型在维基百科上表现优异,但在你公司的法律文档上就歇菜了。
标准解决方案——领域适配——目前还是博士生的周末项目:手动调学习率,挑数据增强策略,在LoRA秩之间做选择,同时烧GPU额度。
现有的AutoML工具(FLAML、Optuna)把这当成通用黑盒优化,忽略了几十年积累的关于LLM微调实际有效方法的智慧。
核心问题:超参搜索空间巨大,训练成本高昂,而关于哪些配置能跨领域迁移的知识散落在各种论文和工程师的口口相传中,没有系统化。
问题:手动LLM适配 = 昂贵的瞎猜
   |
   v
假设:领域适配知识存在但分散
   |
   v
方法:多智能体辩论(规划) + LLM代理(优化)
   |
   v
证据:10个任务上比AutoML基线提升25%准确率
   |
   v
结论:在预算约束下,编码的专业知识胜过盲目搜索
增量
一句话: AutoAdapt之前,你需要专家保姆式照看每次领域适配;之后,你输入任务描述和数据,系统自动提出合理的适配策略。
核心机制
AutoAdapt分三个阶段。
首先是知识库阶段,从论文和GitHub仓库抓取最佳实践——比如”用LoRA做参数高效调优”或”医疗领域受益于持续预训练”。
这些被编码成结构化知识库供系统查询。
其次是规划阶段,两个LLM智能体辩论。
提案智能体建议适配策略(用哪些技术,大致的超参范围)。
批评智能体用数据特征和知识库约束挑刺。
它们来回交锋直到收敛到一个既理论可靠又适合数据的方案。
这把搜索空间从数千种可能配置缩小到一个聚焦区域。
第三是优化阶段,使用AutoRefine——一个充当代理模型的LLM。
它不是在每个候选配置上实际训练LLM(昂贵),而是基于配置和过往结果预测性能。
它通过推理什么改变可能有帮助来迭代优化超参,然后只用真实训练验证最有希望的候选。
用户输入(任务+数据)
   |
   v
+------------------+
| 知识库           |  <--- 论文、GitHub、最佳实践
+------------------+
   |
   v
+------------------+
| 多智能体         |
| 辩论系统         |
|                  |
| 提案智能体       |  <---> 批评智能体
|   (建议)         |        (质疑)
+------------------+
   |
   v
缩小的搜索空间
   |
   v
+------------------+
| AutoRefine       |
| (LLM代理)        |
|                  |
| 预测性能         |
| 优化参数         |
+------------------+
   |
   v
最终配置 --> 训练LLM --> 适配后模型
把AutoAdapt想象成你的LLM咨询公司。
知识库是公司的案例研究和行业报告库。
提案和批评智能体是两个在会议室里敲定策略的资深顾问——一个乐观,一个怀疑,摩擦产生现实方案。
AutoRefine是运行财务模型测试不同场景的初级分析师,不用每次都执行完整商业计划。
只有当顾问达成一致且模型看起来不错时,你才投入资源到真实实施。
关键概念
- 用于规划的多智能体辩论: 与其让一个LLM生成计划(可能过度自信或遗漏边界情况),不如让两个智能体争论。
提案智能体像创业者推销想法——“咱们用4位量化和激进数据增强!”批评智能体是问尖锐问题的风投——“你的数据集只有500个样本,激进增强不会过拟合吗?”这种对抗设置暴露假设,迫使系统根据理论(知识库)和数据现实证明每个选择。
输出不只是配置,而是带有每个决策为何做出的纸面记录的配置。
- 基于LLM的代理(AutoRefine): 传统超参优化把模型当黑盒:试配置A,得准确率X,试配置B,得准确率Y,用贝叶斯优化猜配置C。
当每个样本花费50美元GPU时间时,这样本效率低。
AutoRefine改用LLM推理配置。
你展示过往结果并问”如果我把学习率从1e-4提到5e-4,会怎样?”它生成带推理的预测(“更高学习率可能帮助逃离局部最小值,但考虑到小批量大小有不稳定风险”)。
你只在LLM推理自信且有希望的配置上运行真实训练。
这像在循环中有个能从有限数据外推的领域专家。
- 知识库整理: 知识库不只是论文堆砌——它围绕决策点结构化。
对每种适配技术(LoRA、前缀调优、持续预训练),它存储:何时使用(数据规模、领域特征)、典型超参范围、已知失败模式、与其他技术的交互效应。
这让智能体查询”低资源医疗命名实体识别用什么?”并得到可操作约束,不只是引用。
整理过程本身半自动化:从论文抓取方法描述,从代码仓库提取超参,然后让LLM组织成可查询模式。
框架转变
之前(主流方法):                  之后(本文方法):

人类专家                         知识库
    |                                |
    v                                v
手动配置                         多智能体辩论
    |                                |
    v                                v
黑盒搜索                         LLM代理(AutoRefine)
(Optuna/FLAML)                       |
    |                                v
    v                            预测性能
昂贵训练                             |
    |                                v
    v                            选择性训练
最终模型                         (仅有希望的配置)
                                     |
                                     v
                                 最终模型

试错循环                         先规划后优化循环
从在广阔空间盲目搜索到在精选空间知情搜索,核心转变是用推理效率替代样本效率。
专家评审
选题眼光: 这是真缺口。
任何为特定领域微调过LLM的人都知道痛点——没有原则性方法设置超参,探索成本高得吓人。
问题位于AutoML(成熟但领域无关)和LLM适配(临时但领域感知)的交叉点。
及时且实用。
方法成熟度: 多智能体辩论很巧妙——本质上是带反馈循环的结构化提示,绕过了单次生成的脆弱性。
AutoRefine更渐进;基于LLM的代理已被探索(如代码优化),但应用到超参搜索是合理延伸。
知识库整理感觉是最薄弱环节——随着新技术出现如何保持更新?论文没深入讨论知识库维护或版本控制。
实验诚意: 基线公平(FLAML、Optuna、手动专家调优)。
25%提升在10个任务上平均,广度扎实。
但论文没分解增益来自哪里——是规划阶段、代理还是知识库?消融实验会加强论证。
另外,“最小开销”含糊——辩论和代理阶段的实际时间相比直接跑更多训练是多少?
写作功力: 摘要和引言强劲,但方法部分试图覆盖太多而深度不足。
AutoRefine算法描述特别密集——伪代码会有帮助。
相关工作部分点名AutoML工具但没深入讨论近期LLM特定适配框架(如AdapterHub、PEFT库设计选择)。
用实例重写3.2节(AutoRefine)会让论文更易懂。
判决: 弱接收——问题重要,方法合理,结果有希望,但论文感觉更像在推销愿景而非成熟系统。
知识库整理和维护故事需要完善,消融实验不足以理解真正驱动增益的是什么。
要点总结
多智能体辩论模式可以立即偷走。
任何时候生成复杂计划或配置,让两个LLM争论(一个提议,一个批判)比单次生成产生更稳健输出。
你可以应用到基础设施即代码生成、API设计甚至代码审查。
用LLM作为昂贵黑盒函数代理的想法未被充分探索。
如果你在做任何评估成本高的优化(A/B测试、仿真运行、硬件基准),考虑LLM能否从配置描述学习预测结果。
关键是给它足够结构——不只是”预测准确率”而是”推理为何这个配置在这些约束下可能成功或失败”。
知识库方法不太新颖但值得注意:如果你在为专业领域构建工具,别假设用户会读文档。
把最佳实践编码成可编程调用的可查询系统。
挑战是保持新鲜——也许这里真正的创新应该是从社区贡献持续更新知识库,像活的风格指南。