Paper: 2603.12254 Authors: Baifeng Shi, Stephanie Fu, Long Lian, Hanrong Ye, David Eigen, Aaron Reite, Boyi Li, Jan Kautz, Song Han, David M. Chan Categories: cs.CV
The Gap
Video understanding with MLLMs has a dirty secret: the models treat every pixel in every frame as equally important. A 1K-frame 4K-resolution video produces millions of visual tokens, and the ViT and LLM chew through all of them regardless of how much of the video is a static background, a slow pan, or a talking head that hasn’t moved in 30 seconds.
Prior work attacked this in a few ways. Token merging (ToMe, FastV) prunes tokens inside the ViT or LLM after they’ve already been computed — you’ve already paid the cost. Frame sampling heuristics (uniform sampling, motion-based selection) operate at the frame level and throw away entire frames, which is too coarse for high-resolution detail. Spatial attention maps from the LLM have been used to guide which regions matter, but that’s a chicken-and-egg problem: you need to run the expensive model to know what to look at.
The gap is upstream: nobody has built a cheap, trainable module that decides before the ViT runs which patches are worth processing, at multiple spatial scales, across time.
Problem: Long 4K video -> millions of tokens -> ViT/LLM too slow
    |
    v
Assumption: Most spatiotemporal patches are redundant;
            a small subset can reconstruct the video
            within a bounded error
    |
    v
Method: AutoGaze -- lightweight autoregressive patch selector
        trained with next-token prediction + RL
        selects multi-scale patches before ViT sees anything
    |
    v
Evidence: 4x-100x token reduction, up to 19x speedup,
          67.0% VideoMME, +10.1% on new HLVid benchmark
    |
    v
Conclusion: Pre-ViT patch selection is a viable and
            superior alternative to post-hoc pruning
The Increment
One sentence: Before this paper, video MLLMs had no cheap way to decide what to look at before looking — AutoGaze gives them that ability, making 1K-frame 4K-resolution video tractable for the first time.
Core Mechanism
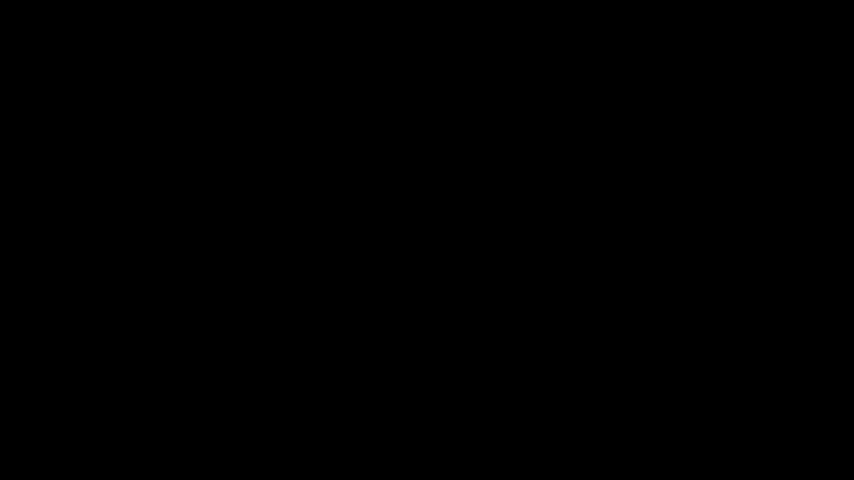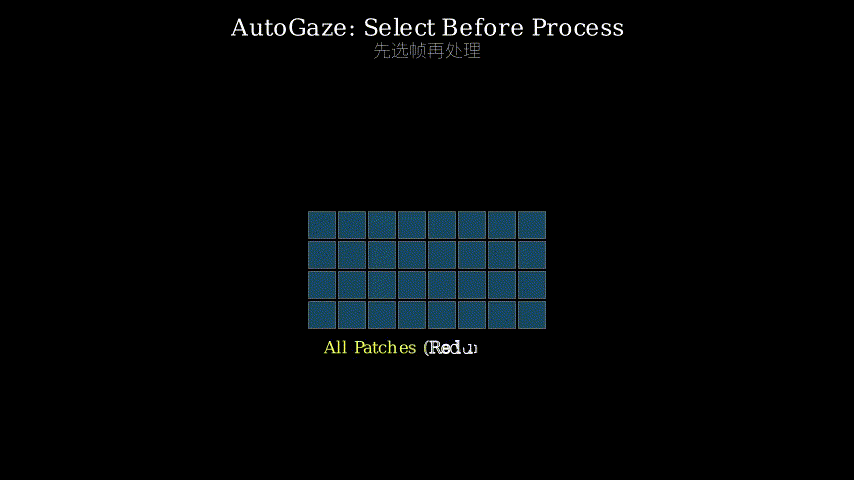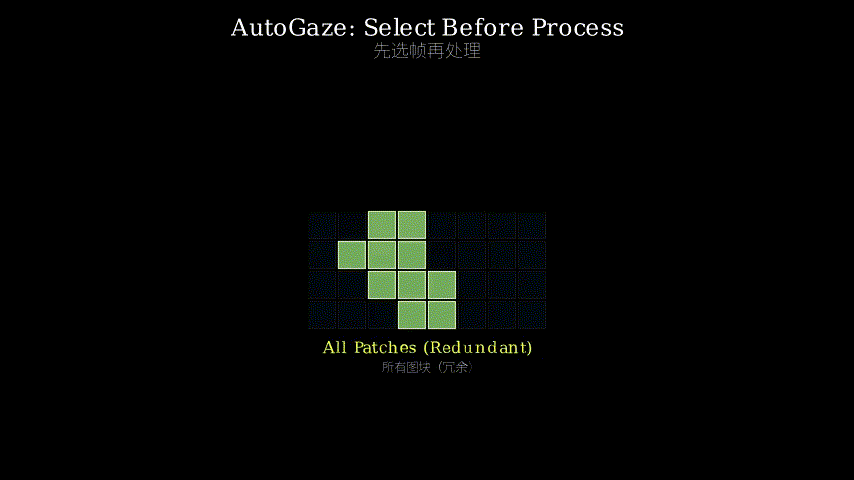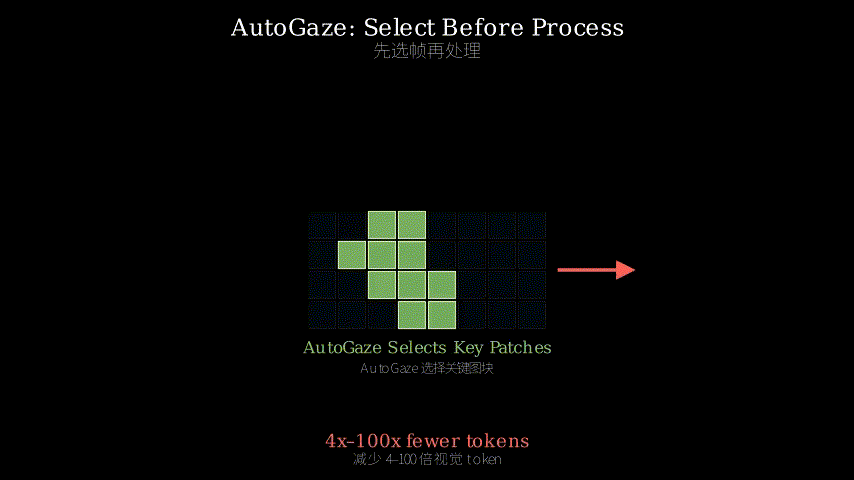
AutoGaze sits entirely upstream of the ViT. It takes raw video frames (or low-resolution thumbnails) and autoregressively outputs a sequence of patch selections — each selection is a (frame index, spatial location, scale) tuple. The model is trained with two objectives: a reconstruction loss that ensures the selected patches can reproduce the original video within a user-specified error threshold, and a reinforcement learning signal that rewards selecting fewer patches while staying under that threshold. The result is a Pareto-optimal selector: it finds the smallest set of patches that preserves the information the downstream task needs.
The multi-scale aspect is important. AutoGaze doesn’t just pick pixels — it picks patches at different zoom levels. A wide shot of a room might be captured at coarse scale, while the text on a whiteboard in the corner gets a fine-scale patch. This mirrors how a human would skim a video: broad strokes first, then zoom in on what matters.
The autoregressive structure means each selection conditions on previous selections. If AutoGaze already grabbed the left half of frame 42, it knows not to redundantly grab the overlapping region. This sequential dependency is what allows it to avoid duplication across both space and time.
Raw Video Frames
      |
      v
  [AutoGaze]  <-- lightweight, runs BEFORE ViT
      |
      | autoregressive loop:
      |   step 1: select patch (frame, location, scale)
      |   step 2: condition next selection on prior ones
      |   step 3: stop when reconstruction error < threshold
      |
      v
  Sparse Patch Set  (4x-100x fewer tokens)
      |
      v
  [ViT Encoder]  <-- now processes only selected patches
      |
      v
  [MLLM / LLM]
      |
      v
  Answer / Caption
Think of AutoGaze as a skilled film editor doing a rough cut before the director watches the footage. The director (ViT + LLM) is expensive — their time costs money. So the editor (AutoGaze) watches everything first at 2x speed, marks the important moments and close-ups, and hands the director a tight assembly cut. The editor doesn’t need to understand the film deeply; they just need to know what’s redundant. The director then watches only the assembly cut and makes the final call. The key insight is that the editor’s job is much cheaper than the director’s, so front-loading the selection work saves the whole production.
Each component maps cleanly: the raw footage is the 4K video, the editor’s rough cut is the sparse patch set, the director is the ViT/LLM, the editor’s judgment criteria are the reconstruction loss + RL reward, and the “stop when good enough” rule is the user-specified error threshold.
Key Concepts
-
Autoregressive patch selection: Instead of scoring all patches independently and picking the top-K (which ignores overlap and redundancy), AutoGaze picks patches one at a time, where each pick depends on what’s already been picked. It’s like packing a suitcase: you don’t decide what to pack by scoring each item in isolation — you pack the first thing, then ask “given what’s already in here, what’s the next most important thing to add?” This sequential dependency is what lets AutoGaze avoid grabbing the same information twice from nearby frames.
-
Reconstruction-bounded selection: The stopping criterion isn’t “pick exactly N patches” — it’s “pick patches until you can reconstruct the video within error threshold T.” This is a much more principled formulation. It means the number of selected patches adapts to the video’s actual complexity: a static talking-head video needs very few patches, while a fast-cut action sequence needs more. The user controls the quality-speed tradeoff by setting T.
-
Pre-ViT vs post-ViT pruning: Most prior token reduction work happens inside or after the ViT — you compute all the patch embeddings first, then throw some away. AutoGaze prunes before the ViT ever runs, which means you never pay the compute cost for the discarded patches. This is the difference between deciding not to cook a dish vs cooking it and then throwing it out.
Framework Shift
Before (mainstream approach):        After (this paper):

All frames                           Raw frames
    |                                    |
    v                                    v
[ViT: process ALL patches]          [AutoGaze: cheap selector]
    |                                    |
    v                                    v
Millions of tokens                  Sparse patch set (small)
    |                                    |
    v                                    v
[Token pruning / merging]           [ViT: process ONLY selected]
(post-hoc, cost already paid)           |
    |                                    v
    v                               Hundreds of tokens
[LLM]                                   |
    |                                    v
    v                               [LLM]
Answer                                  |
                                        v
                                    Answer

Cost: O(all patches)                Cost: O(selected patches)
Bottleneck: ViT compute             Bottleneck: AutoGaze (cheap)
From reactive pruning to proactive selection, the core shift is: stop paying to look at things you were going to ignore anyway.
Expert Assessment
Problem choice: This is a real gap, not a manufactured one. The compute wall for long high-resolution video is a genuine blocker for deployment, and the prior work on post-hoc token pruning has an obvious inefficiency that this paper correctly identifies. The timing is right — 4K video understanding is becoming a practical requirement, not a benchmark curiosity. The introduction of HLVid as a new benchmark is a smart move that also happens to be self-serving, but the benchmark itself addresses a real evaluation gap.
Method maturity: The core idea is clean and well-motivated. Training a lightweight selector with reconstruction loss + RL is not trivial engineering, and the autoregressive formulation is a genuine insight over independent scoring. That said, the RL training adds complexity and potential instability that the paper doesn’t fully interrogate. The ablation on “what if you just used uniform sampling at the same token budget?” would be the most important baseline, and it’s not clear from the abstract whether that’s included. The multi-scale aspect is sensible but also adds hyperparameters.
Experimental integrity: The 67.0% on VideoMME is a strong number, and the 19x speedup claim is specific enough to be checkable. The +10.1% on HLVid is compelling but needs scrutiny since the authors also created HLVid — that’s not disqualifying, but it warrants independent replication. The 4x-100x token reduction range is suspiciously wide; the 100x end likely applies only to very redundant videos, and the average case matters more for practical deployment. I’d want to see the distribution of compression ratios, not just the extremes.
Writing quality: The abstract buries the most interesting technical contribution — the autoregressive formulation and the reconstruction-bounded stopping criterion — in favor of leading with speedup numbers. The methods section (not visible here but predictable) probably undersells the RL training details, which is where the real engineering difficulty lives. If the authors rewrote the methods section to be more transparent about training stability and failure modes of the RL component, the paper would be significantly more useful to practitioners trying to reproduce it.
Verdict: weak accept — strong empirical results and a clean problem framing, but the self-referential benchmark and underspecified RL training details leave enough uncertainty that it needs a careful read before trusting the numbers.
Takeaways
The reconstruction-bounded stopping criterion is directly stealable. Any time you’re doing adaptive computation — deciding how much processing to apply to an input — framing the stopping rule as “stop when you can reconstruct the input within error T” is cleaner than “stop after K steps.” It gives you a principled quality-speed knob and makes the compute budget adaptive to input complexity rather than fixed.
The pre-processor pattern is also worth generalizing: if you have an expensive model and a cheap proxy, train the proxy to filter inputs for the expensive model rather than pruning inside the expensive model. This applies beyond video — document understanding, multi-image reasoning, any setting where the input has spatiotemporal redundancy.
The autoregressive selection with sequential conditioning (each pick depends on prior picks) is a useful inductive bias for any selection problem where items have overlapping information content. It’s a better fit than independent scoring whenever the value of an item depends on what else you’ve already selected.
论文: 2603.12254 作者: Baifeng Shi, Stephanie Fu, Long Lian, Hanrong Ye, David Eigen, Aaron Reite, Boyi Li, Jan Kautz, Song Han, David M. Chan 分类: cs.CV
缺口
视频理解领域的多模态大语言模型(MLLM)有一个公开的秘密:它们对每一帧的每一个像素一视同仁。
一段 1K 帧、4K 分辨率的视频会产生数百万个视觉 token,而 ViT 和 LLM 会把它们全部处理一遍——不管其中有多少是静止背景、缓慢平移,还是三十秒没动过的说话人脸。
此前的工作从几个方向尝试解决这个问题。
Token 合并方法(ToMe、FastV)在 ViT 或 LLM 内部剪枝,但计算代价已经付出去了。 帧采样启发式方法(均匀采样、基于运动的选择)在帧级别操作,粒度太粗,丢失了高分辨率细节。 用 LLM 的注意力图来引导区域选择,则陷入了先有鸡还是先有蛋的困境:你得先跑一遍昂贵的模型,才知道该看哪里。
真正的缺口在上游:没有人构建过一个廉价的、可训练的模块,在 ViT 运行之前,就决定哪些图像块值得处理——还要跨时间、跨多个空间尺度地做这件事。
问题:长视频 4K 帧 -> 数百万 token -> ViT/LLM 太慢
    |
    v
假设:大多数时空图像块是冗余的;
      一个小子集就能在有界误差内重建视频
    |
    v
方法:AutoGaze -- 轻量自回归图像块选择器
      用下一 token 预测 + 强化学习训练
      在 ViT 看到任何东西之前完成选择
    |
    v
证据:token 减少 4x-100x,最高加速 19x,
      VideoMME 67.0%,HLVid 基准提升 10.1%
    |
    v
结论:ViT 前置图像块选择是比事后剪枝
      更优越的可行方案
增量
一句话:在这篇论文之前,视频 MLLM 没有廉价的方式在”看”之前决定”看什么”——AutoGaze 给了它们这种能力,让 1K 帧 4K 分辨率视频的处理第一次变得可行。
核心机制
AutoGaze 完全位于 ViT 的上游。
它接收原始视频帧(或低分辨率缩略图),自回归地输出一系列图像块选择——每个选择是一个(帧索引、空间位置、尺度)三元组。 模型用两个目标训练:重建损失确保所选图像块能在用户指定的误差阈值内重建原始视频;强化学习信号奖励在满足阈值的前提下选择更少的图像块。 结果是一个帕累托最优选择器:找到保留下游任务所需信息的最小图像块集合。
多尺度设计很关键。
AutoGaze 不只是选像素,而是在不同缩放级别选图像块。 房间的全景可以用粗粒度图像块捕获,而角落白板上的文字则需要细粒度图像块。 这模拟了人类浏览视频的方式:先看大轮廓,再聚焦到重要细节。
自回归结构意味着每次选择都以之前的选择为条件。
如果 AutoGaze 已经抓取了第 42 帧的左半部分,它就知道不要再冗余地抓取相邻区域。 这种序列依赖正是它能避免在空间和时间上重复抓取相同信息的原因。
原始视频帧
      |
      v
  [AutoGaze]  <-- 轻量,在 ViT 之前运行
      |
      | 自回归循环:
      |   步骤 1:选择图像块(帧、位置、尺度)
      |   步骤 2:以已选图像块为条件进行下一次选择
      |   步骤 3:当重建误差 < 阈值时停止
      |
      v
  稀疏图像块集合(少 4x-100x)
      |
      v
  [ViT 编码器]  <-- 现在只处理已选图像块
      |
      v
  [MLLM / LLM]
      |
      v
  答案 / 描述
把 AutoGaze 想象成一位熟练的剪辑师,在导演看素材之前先做粗剪。
导演(ViT + LLM)很贵——他们的时间就是钱。 所以剪辑师(AutoGaze)先以 2 倍速把所有素材看一遍,标出重要时刻和特写镜头,然后把一个紧凑的粗剪版本交给导演。 剪辑师不需要深刻理解这部电影,只需要知道什么是冗余的。 导演只看粗剪版本,然后做最终决定。 关键洞察是:剪辑师的工作比导演便宜得多,所以把选择工作前置能节省整个制作流程的成本。
每个组件都有清晰的映射:原始素材是 4K 视频,粗剪版本是稀疏图像块集合,导演是 ViT/LLM,剪辑师的判断标准是重建损失加强化学习奖励,“够好就停”的规则是用户指定的误差阈值。
关键概念
-
自回归图像块选择:不是对所有图像块独立打分然后取前 K 个(这种方式忽略了重叠和冗余),而是一次选一个,每次选择依赖于已经选了什么。就像打包行李:你不会孤立地给每件衣服打分——你先放第一件,然后问”考虑到已经放进去的东西,下一件最重要的是什么?“这种序列依赖让 AutoGaze 能避免从相邻帧中重复抓取相同信息。
-
重建有界选择:停止标准不是”恰好选 N 个图像块”,而是”选图像块直到能在误差阈值 T 内重建视频”。这是更有原则的表述。它意味着所选图像块的数量会适应视频的实际复杂度:静态说话人视频只需要很少的图像块,而快速剪切的动作场景需要更多。用户通过设置 T 来控制质量与速度的权衡。
-
ViT 前剪枝 vs ViT 后剪枝:大多数先前的 token 减少工作发生在 ViT 内部或之后——你先计算所有图像块的嵌入,然后丢弃一些。AutoGaze 在 ViT 运行之前就剪枝,这意味着你永远不需要为被丢弃的图像块付出计算代价。这就像决定不做一道菜,和做完之后再扔掉的区别。
框架转变
之前(主流方法):                    之后(本文方法):

所有帧                               原始帧
    |                                    |
    v                                    v
[ViT:处理所有图像块]              [AutoGaze:廉价选择器]
    |                                    |
    v                                    v
数百万 token                        稀疏图像块集合(很小)
    |                                    |
    v                                    v
[Token 剪枝/合并]                   [ViT:只处理已选图像块]
(事后补救,代价已付)                   |
    |                                    v
    v                               数百个 token
[LLM]                                   |
    |                                    v
    v                               [LLM]
答案                                    |
                                        v
                                    答案

代价:O(所有图像块)                 代价:O(已选图像块)
瓶颈:ViT 计算                      瓶颈:AutoGaze(廉价)
从被动剪枝到主动选择,核心转变是:不再为那些本来就要忽略的内容付出代价。
专家评审
选题眼光:这是真缺口,不是人造的。
长