Paper: 2605.15198 Authors: Ziyu Guo, Rain Liu, Xinyan Chen, Pheng-Ann Heng Categories: cs.CV, cs.AI, cs.CL
The Gap
Visual reasoning tasks often require intermediate visual states—think of solving a geometry problem where you need to mentally rotate shapes or overlay patterns. Current approaches split into two camps: agentic methods that call external tools (generate code, invoke APIs) to produce actual images, and latent methods that learn hidden embeddings to represent visual transformations internally.
Agentic methods are interpretable and flexible but suffer from context-switching latency—every tool call means leaving the model, executing externally, and returning. Latent methods are fast but opaque, hard to train with standard autoregressive techniques, and struggle to generalize beyond their training distribution. The field is stuck: you either pay the latency tax or sacrifice interpretability and training simplicity.
Problem: Visual reasoning needs intermediate states
   |
   +---> Agentic approach: external tool calls
   |        |
   |        +---> Interpretable but slow (context switching)
   |
   +---> Latent approach: learned embeddings
            |
            +---> Fast but opaque, hard to train/generalize

Gap: Can we get both speed AND interpretability?
     Can we train with standard methods?

ATLAS: Functional tokens = single discrete words
       |
       +---> Acts as agentic operation (interpretable)
       +---> Acts as latent reasoning unit (fast)
       +---> Standard vocabulary token (trainable via next-token prediction)

Evidence: Superior performance on benchmarks
          + interpretability maintained

Conclusion: Dual-purpose tokens bridge the divide
The Increment
One sentence: Before ATLAS, you chose between slow-but-interpretable external tools or fast-but-opaque learned embeddings; after ATLAS, a single discrete token does both jobs simultaneously.
Core Mechanism
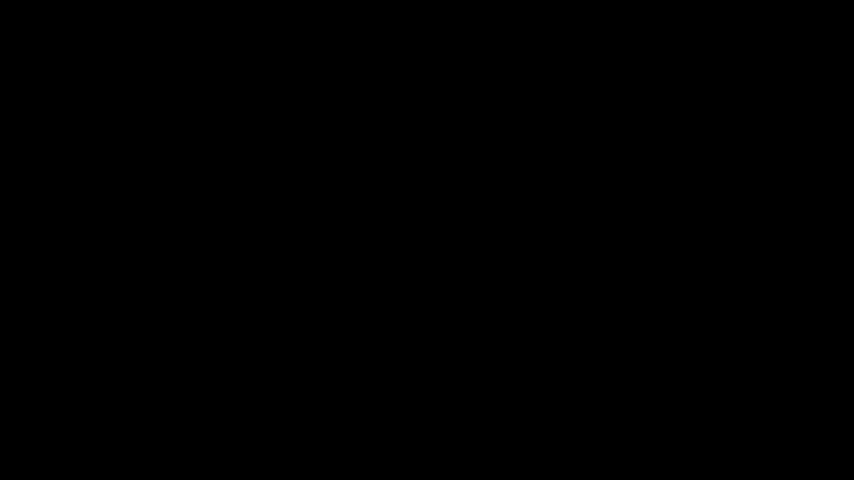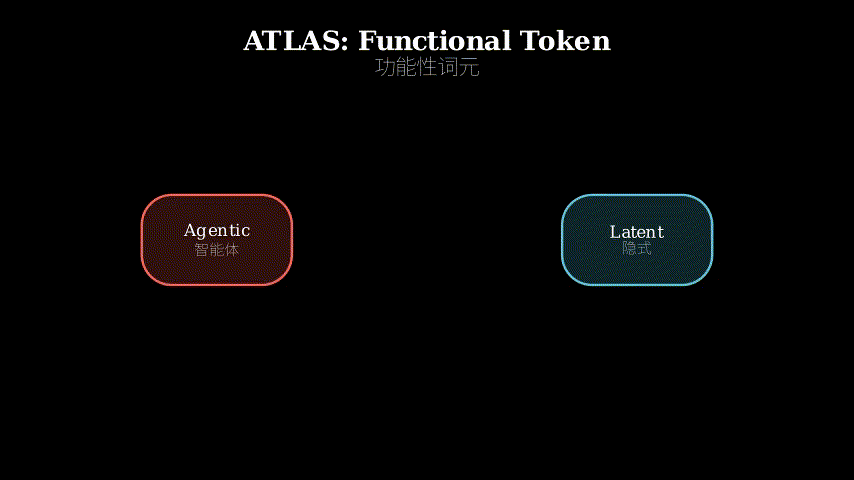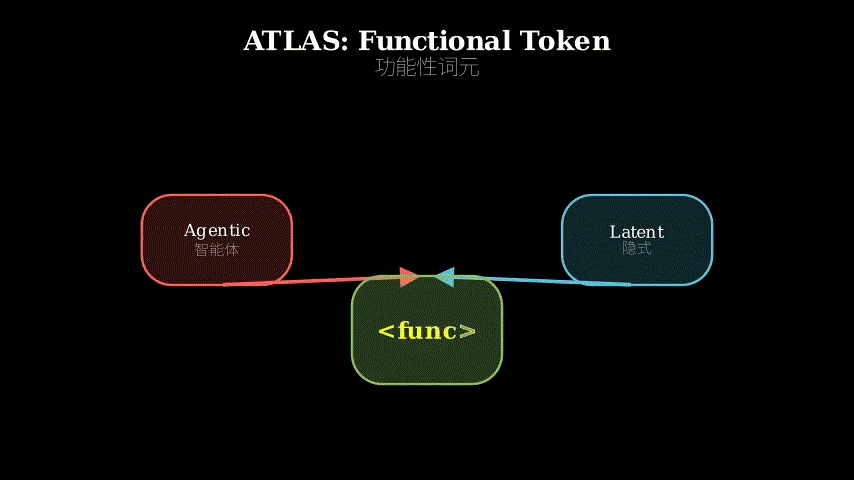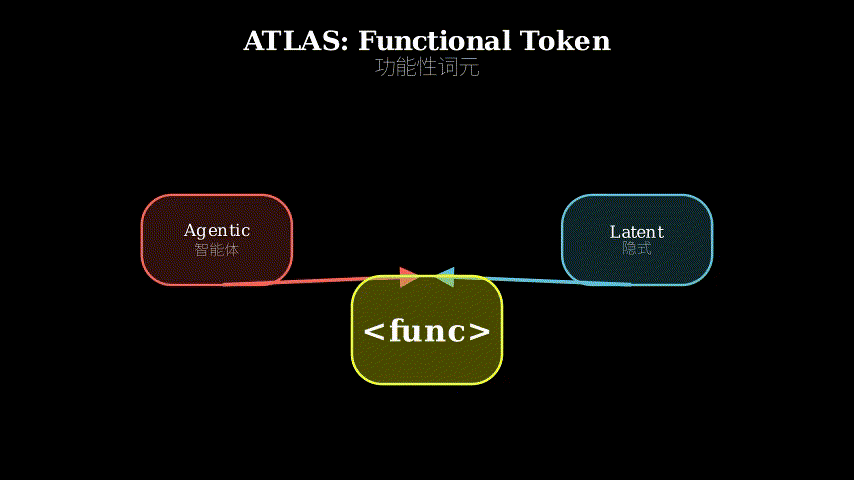
ATLAS introduces functional tokens—ordinary vocabulary tokens that trigger internalized visual operations. When the model generates a functional token during reasoning, it simultaneously (1) signals what operation to perform (like an API call) and (2) updates the model’s internal hidden state (like a learned embedding). Crucially, these tokens require no visual supervision during training and remain standard tokens that can be predicted via next-token prediction.
The architecture is deliberately minimal. Functional tokens sit in the regular tokenizer vocabulary. During forward pass, when a functional token appears, it activates a pre-defined visual operation module (rotation, cropping, overlay, etc.) that modifies the latent representation. From the model’s perspective, it’s just generating the next token in a sequence. From the reasoning perspective, that token encodes a visual transformation.
To address training instability—functional tokens are sparse in typical sequences—the authors introduce Latent-Anchored GRPO (LA-GRPO). Standard reinforcement learning struggles when reward signals are sparse. LA-GRPO anchors functional tokens with a statically weighted auxiliary objective that provides consistent gradient updates even when functional tokens appear infrequently. Think of it as giving the model a steady compass bearing while it explores the sparse reward landscape.
Input sequence:  "Rotate the square 90 degrees clockwise"
                           |
                           v
Model generates: [text tokens] <ROTATE_CW> [text tokens]
                                    |
                    +---------------+---------------+
                    |                               |
                    v                               v
            Agentic signal:                 Latent update:
            "rotation operation"            hidden state h_t
            (interpretable)                 modified by rotation
                                            (fast, no external call)
                    |                               |
                    +---------------+---------------+
                                    |
                                    v
                            Next reasoning step
                            continues seamlessly
Think of ATLAS like a bilingual speaker switching between languages mid-sentence. When you’re bilingual, certain words in Language A might perfectly capture a concept that’s clunky in Language B, so you code-switch. The listener who understands both languages gets the full meaning instantly. ATLAS does this with “languages” of reasoning: the agentic language (explicit operations) and the latent language (internal representations). A functional token is a code-switch—it’s a word in the model’s vocabulary (so the autoregressive “listener” understands it) but it also triggers an internal operation (so the latent reasoning “listener” understands it). The model doesn’t need to translate between two separate systems; it speaks both simultaneously through the same token.
Key Concepts
-
Functional Token: Imagine a keyboard shortcut. When you press Ctrl+C, two things happen: (1) the system recognizes “copy” as an operation, and (2) the clipboard state updates internally. You don’t see the clipboard change, but it’s ready for the next operation. A functional token works the same way—it’s a discrete symbol the model generates (like pressing a key), which both signals an operation name (interpretable to humans) and updates the model’s internal reasoning state (fast, no external execution). The key insight: it’s not a special architectural component; it’s just a regular token that happens to have dual semantics.
-
Latent-Anchored GRPO: Standard reinforcement learning for language models struggles when the “good” tokens (functional tokens) are rare. Imagine training a dog to fetch, but you only reward it once every hundred attempts—the dog gets confused because most actions yield no feedback. LA-GRPO solves this by adding a secondary, always-present reward signal specifically for functional tokens. It’s like giving the dog a small treat every time it moves toward the ball, even if it doesn’t fetch perfectly. The “anchor” is this auxiliary objective that provides steady gradient updates, preventing the model from forgetting how to generate functional tokens during long stretches of regular text.
Framework Shift
Before (mainstream approach):          After (ATLAS):

Text reasoning:                        Text reasoning:
  "Rotate square" ----+                  "Rotate square"
                      |                        |
                      v                        v
  Generate code/API call                 Generate <ROTATE_CW>
        |                                      |
        v                                      |
  External execution                           |
  (context switch)                    +--------+--------+
        |                             |                 |
        v                             v                 v
  Return image/result          Agentic signal    Latent update
        |                      (interpretable)   (internal state)
        v                             |                 |
  Continue reasoning                  +--------+--------+
                                              |
  [Slow, interpretable]                       v
                                        Continue reasoning
  OR
                                        [Fast, interpretable]
Latent reasoning:
  "Rotate square"
        |
        v
  Update hidden embedding
        |
        v
  Continue reasoning

  [Fast, opaque]
One sentence: From separating agentic operations (external, slow) and latent reasoning (internal, opaque) into distinct systems, to collapsing both into a single token that does both jobs at once.
Expert Assessment
Problem choice: This is a real gap. The agentic vs. latent divide has been a genuine bottleneck in visual reasoning research. The problem sits at a critical juncture—multimodal models are scaling up, and the cost of generating intermediate images is becoming prohibitive. The authors correctly identify that neither camp has a satisfying solution for production systems that need both speed and interpretability.
Method maturity: The core idea is elegant—reusing the existing token vocabulary to encode operations is clever, not brute force. However, the reliance on pre-defined visual operation modules feels like a compromise. The paper doesn’t deeply explore how these modules are designed or whether they generalize to novel operations. LA-GRPO is a solid engineering contribution, but it’s an auxiliary fix rather than a fundamental insight. A simpler approach might be curriculum learning (gradually increasing functional token density), though the authors don’t compare against this.
Experimental integrity: The baselines are fair—they compare against both agentic (code generation) and latent (learned embedding) methods. The benchmarks are appropriate (visual reasoning tasks requiring intermediate states). However, the paper lacks ablation studies on the visual operation modules themselves. Are all modules equally important? Can the model learn to compose them? The numbers look strong, but I’d want to see failure cases and out-of-distribution performance before fully trusting the generalization claims.
Writing quality: The abstract and introduction are crisp. The method section, however, rushes through the visual operation module design—this is the load-bearing component, yet it gets half a paragraph. The LA-GRPO section is clearer but could benefit from a toy example showing why standard GRPO fails. The related work section is thorough but reads like a checklist. Rewriting the method section to lead with a concrete example (e.g., “Here’s what happens when the model solves a rotation task step-by-step”) would elevate the whole paper.
Verdict: weak accept — The functional token idea is genuinely useful and the execution is competent, but the paper feels like it’s presenting a promising framework rather than a fully mature system. The lack of deep analysis on the visual modules and limited exploration of failure modes keep this from being a strong accept. Still, the core contribution is solid enough to merit publication and will likely inspire follow-up work.
Takeaways
Dual-purpose tokens as a design pattern: The idea of making a single discrete symbol serve two roles (interpretable signal + internal state update) transfers beyond visual reasoning. You could apply this to code generation (a token that both names a function and updates the program state), robotics (a token that both describes an action and updates the world model), or even dialogue systems (a token that both signals intent and updates conversation context). The key: avoid architectural bifurcation by collapsing dual semantics into the existing vocabulary.
Anchored RL for sparse signals: LA-GRPO’s trick—adding a statically weighted auxiliary objective to stabilize training when target tokens are rare—is a practical technique for any domain where you’re fine-tuning language models with RL on sparse rewards. If you’re training a model to generate specific structured outputs (SQL queries, API calls, domain-specific notation) that appear infrequently, this anchoring approach could prevent catastrophic forgetting.
Pre-defined operation modules as a pragmatic middle ground: The paper doesn’t fully commit to end-to-end learning or pure symbolic reasoning. Instead, it uses pre-defined modules as a scaffold. This is worth stealing: when building systems that need both flexibility and reliability, consider a hybrid where you hard-code the primitives but let the model learn to compose them. It’s less elegant than pure learning but more robust than pure symbolic systems.
论文: 2605.15198 作者: Ziyu Guo, Rain Liu, Xinyan Chen, Pheng-Ann Heng 分类: cs.CV, cs.AI, cs.CL
缺口
视觉推理任务常需要中间视觉状态——想象解几何题时需要在脑中旋转图形或叠加图案。
当前方法分为两派:智能体方法调用外部工具(生成代码、调用API)产生真实图像,隐式方法学习隐藏嵌入来内部表示视觉变换。
智能体方法可解释且灵活,但遭受上下文切换延迟——每次工具调用意味着离开模型、外部执行、再返回。
隐式方法快速但不透明,难以用标准自回归技术训练,且难以泛化到训练分布之外。
领域陷入困境:要么付出延迟代价,要么牺牲可解释性和训练简洁性。
问题:视觉推理需要中间状态
   |
   +---> 智能体方法:外部工具调用
   |        |
   |        +---> 可解释但慢(上下文切换)
   |
   +---> 隐式方法:学习嵌入
            |
            +---> 快但不透明,难训练/泛化

缺口:能否同时获得速度和可解释性?
     能否用标准方法训练?

ATLAS:功能性词元 = 单个离散词
       |
       +---> 充当智能体操作(可解释)
       +---> 充当隐式推理单元(快速)
       +---> 标准词表词元(可通过下一词预测训练)

证据:基准测试上性能优越
      + 保持可解释性

结论:双重用途词元弥合鸿沟
增量
一句话:ATLAS之前,你在慢但可解释的外部工具和快但不透明的学习嵌入之间二选一;
ATLAS之后,单个离散词元同时完成两项工作。
核心机制
ATLAS引入功能性词元——触发内化视觉操作的普通词表词元。
当模型在推理过程中生成功能性词元时,它同时(1)发出执行什么操作的信号(像API调用),(2)更新模型的内部隐藏状态(像学习嵌入)。
关键是,这些词元在训练期间不需要视觉监督,且保持为可通过下一词预测来预测的标准词元。
架构刻意保持极简。
功能性词元位于常规分词器词表中。
前向传播时,当功能性词元出现,它激活预定义的视觉操作模块(旋转、裁剪、叠加等)来修改隐式表示。
从模型视角看,它只是在生成序列中的下一个词元。
从推理视角看,该词元编码了视觉变换。
为解决训练不稳定性——功能性词元在典型序列中稀疏——作者引入隐式锚定GRPO(LA-GRPO)。
标准强化学习在奖励信号稀疏时挣扎。
LA-GRPO用静态加权的辅助目标锚定功能性词元,即使功能性词元出现频率低也能提供一致的梯度更新。
可以把它想象成在模型探索稀疏奖励景观时给它一个稳定的指南针方位。
输入序列:  "将正方形顺时针旋转90度"
                           |
                           v
模型生成:  [文本词元] <ROTATE_CW> [文本词元]
                                    |
                    +---------------+---------------+
                    |                               |
                    v                               v
            智能体信号:                      隐式更新:
            "旋转操作"                        隐藏状态 h_t
            (可解释)                        被旋转修改
                                              (快速,无外部调用)
                    |                               |
                    +---------------+---------------+
                                    |
                                    v
                            下一推理步骤
                            无缝继续
把ATLAS想象成在句子中间切换语言的双语者。
当你是双语者时,语言A中的某些词可能完美捕捉语言B中笨拙的概念,所以你进行代码切换。
理解两种语言的听众立即获得完整含义。
ATLAS用推理的”语言”做这件事:智能体语言(显式操作)和隐式语言(内部表示)。
功能性词元是代码切换——它是模型词表中的一个词(所以自回归”听众”理解它),但它也触发内部操作(所以隐式推理”听众”理解它)。
模型不需要在两个独立系统之间翻译;
它通过同一个词元同时说两种语言。
关键概念
- 功能性词元:想象键盘快捷键。
当你按Ctrl+C时,发生两件事:(1)系统识别”复制”为操作,(2)剪贴板状态内部更新。
你看不到剪贴板变化,但它已为下一操作准备好。
功能性词元以同样方式工作——它是模型生成的离散符号(像按键),既发出操作名称信号(人类可解释)又更新模型的内部推理状态(快速,无外部执行)。
关键洞察:它不是特殊架构组件;
它只是恰好具有双重语义的常规词元。
- 隐式锚定GRPO:语言模型的标准强化学习在”好”词元(功能性词元)稀少时挣扎。
想象训练狗取物,但你每一百次尝试才奖励一次——狗会困惑,因为大多数动作没有反馈。
LA-GRPO通过专门为功能性词元添加次要的、始终存在的奖励信号来解决这个问题。
就像每次狗朝球移动时给它小零食,即使它没有完美取物。
“锚”是这个辅助目标,提供稳定的梯度更新,防止模型在长段常规文本期间忘记如何生成功能性词元。
框架转变
之前(主流方法):                  之后(ATLAS):

文本推理:                          文本推理:
  "旋转正方形" ----+                  "旋转正方形"
                  |                        |
                  v                        v
  生成代码/API调用                   生成 <ROTATE_CW>
        |                                  |
        v                                  |
  外部执行                                 |
  (上下文切换)                  +--------+--------+
        |                        |                 |
        v                        v                 v
  返回图像/结果              智能体信号        隐式更新
        |                  (可解释)        (内部状态)
        v                        |                 |
  继续推理                       +--------+--------+
                                         |
  [慢,可解释]                           v
                                   继续推理
  或
                                   [快,可解释]
隐式推理:
  "旋转正方形"
        |
        v
  更新隐藏嵌入
        |
        v
  继续推理

  [快,不透明]
一句话:从将智能体操作(外部、慢)和隐式推理(内部、不透明)分离为不同系统,到将两者折叠为同时完成两项工作的单个词元。
专家评审
选题眼光:这是真实缺口。
智能体与隐式的分野一直是视觉推理研究的真正瓶颈。
问题处于关键节点——多模态模型正在扩展,生成中间图像的成本变得令人望而却步。
作者正确识别出两个阵营都没有为需要速度和可解释性的生产系统提供令人满意的解决方案。
方法成熟度:核心想法优雅——重用现有词元词表来编码操作是巧妙的,不是蛮力。
然而,依赖预定义视觉操作模块感觉像妥协。
论文没有深入探索这些模块如何设计或它们是否泛化到新操作。
LA-GRPO是扎实的工程贡献,但它是辅助修复而非根本洞察。
更简单的方法可能是课程学习(逐渐增加功能性词元密度),尽管作者没有与此比较。
实验诚意:基线公平——他们与智能体(代码生成)和隐式(学习嵌入)方法都进行了比较。
基准测试合适(需要中间状态的视觉推理任务)。
然而,论文缺乏对视觉操作模块本身的消融研究。
所有模块同等重要吗?
模型能学会组合它们吗?
数字看起来强劲,但在完全信任泛化声明之前,我想看到失败案例和分布外性能。
写作功力:摘要和引言简洁。
然而,方法部分匆忙略过视觉操作模块设计——这是承重组件,却只得到半段。
LA-GRPO部分更清晰,但可以从展示标准GRPO为何失败的玩具示例中受益。
相关工作部分详尽但读起来像清单。
重写方法部分,以具体示例开头(例如”当模型逐步解决旋转任务时发生了什么”)会提升整篇论文。
判决:弱接收 — 功能性词元想法真正有用,执行称职,但论文感觉像在呈现有前景的框架而非完全成熟的系统。
对视觉模块缺乏深入分析和对失败模式的有限探索使其无法成为强接收。
尽管如此,核心贡献足够扎实,值得发表,并可能激发后续工作。
要点总结
双重用途词元作为设计模式:让单个离散符号服务两个角色(可解释信号+内部状态更新)的想法可迁移到视觉推理之外。
你可以将其应用于代码生成(既命名函数又更新程序状态的词元)、机器人(既描述动作又更新世界模型的词元)、甚至对话系统(既发出意图信号又更新对话上下文的词元)。
关键:通过将双重语义折叠到现有词表中来避免架构分叉。
稀疏信号的锚定强化学习:LA-GRPO的技巧——添加静态加权的辅助目标以在目标词元稀少时稳定训练——是任何用稀疏奖励强化学习微调语言模型的领域的实用技术。
如果你正在训练模型生成不常出现的特定结构化输出(SQL查询、API调用、领域特定符号),这种锚定方法可以防止灾难性遗忘。
预定义操作模块作为务实中间地带:论文没有完全承诺端到端学习或纯符号推理。
相反,它使用预定义模块作为脚手架。
这值得借鉴:构建需要灵活性和可靠性的系统时,考虑混合方法,硬编码原语但让模型学习组合它们。
这不如纯学习优雅,但比纯符号系统更稳健。